P.S. Free & New SPLK-1005 dumps are available on Google Drive shared by PrepAwayTest: https://drive.google.com/open?id=1iAOjFLqcP3xE4DTl2TkMweGfiPTHCCW5
The system of SPLK-1005 study materials is very smooth and you don't need to spend a lot of time installing it. We take into account all aspects and save you as much time as possible. After the installation is complete, you can devote all of your time to studying our SPLK-1005 Exam Questions. We use your time as much as possible for learning. This must remove all unnecessary programs. Our SPLK-1005 study materials are so efficient!
| Section | Weight | Objectives |
|---|---|---|
| Splunk Cloud Overview | 5% | - Cloud topology and architecture
|
| User Authentication and Authorization | 5% | - User and role administration
|
| Index Management | 5% | - Index fundamentals
|
| Data Ingestion and Inputs | 20% | - Data onboarding and forwarding
|
| Security and Compliance | 15% | - Cloud security controls
|
| Search and Performance Optimization | 15% | - Search infrastructure management
|
| Monitoring, Troubleshooting, and Support | 15% | - Operational troubleshooting
|
>> Reliable SPLK-1005 Test Cost <<
SPLK-1005 materials trends are not always easy to forecast, but they have predictable pattern for them by ten-year experience who often accurately predict points of knowledge occurring in next SPLK-1005 preparation materials. Our professional experts can give you the latest and the most accurate SPLK-1005 Training Material for that they have beening in this filed for so many years and know every aspect of the change of SPLK-1005 practice questions. You can trust in our SPLK-1005 learning braindump for sure.
NEW QUESTION # 43
What syntax is required in inputs.conf to ingest data from files or directories?
Answer: D
NEW QUESTION # 44
At what point in the indexing pipeline set is SEDCMD applied to data?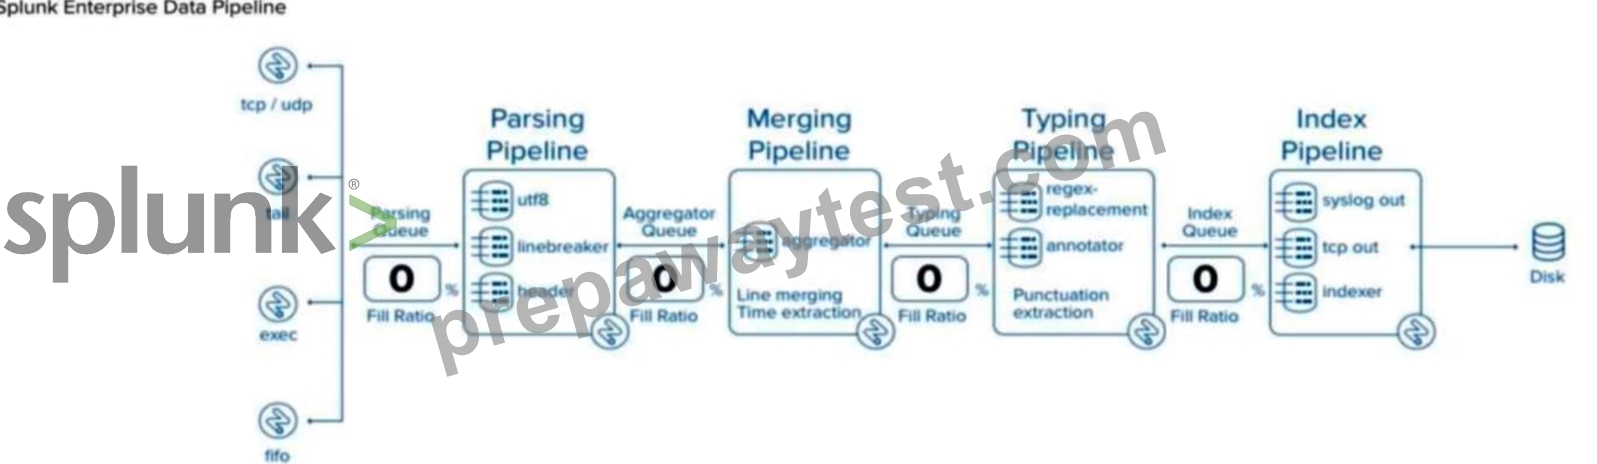
Answer: C
Explanation:
In Splunk, SEDCMD (Stream Editing Commands) is applied during the Typing Pipeline of the data indexing process.
The Typing Pipeline is responsible for various tasks, such as applying regular expressions for field extractions, replacements, and data transformation operations that occur after the initial parsing and aggregation steps.
Here's how the indexing process works in more detail:
Parsing Pipeline: In this stage, Splunk breaks incoming data into events, identifies timestamps, and assigns metadata.
Merging Pipeline: This stage is responsible for merging events and handling time-based operations.
Typing Pipeline: The Typing Pipeline is where SEDCMD operations occur. It applies regular expressions and replacements, which is essential for modifying raw data before indexing. This pipeline is also responsible for field extraction and other similar operations.
Index Pipeline: Finally, the processed data is indexed and stored, where it becomes available for searching.
NEW QUESTION # 45
Which of the following is true when using Intermediate Forwarders?
Answer: C
Explanation:
Intermediate Forwarders are special types of forwarders that sit between Universal Forwarders and indexers to perform additional processing tasks such as routing, filtering, or load balancing data before it reaches the indexers.
* B. All Intermediate Forwarders must be Heavy Forwardersis the correct answer. Heavy Forwarders are the only type of forwarder that can perform the necessary tasks required of an Intermediate Forwarder, such as parsing data, applying transformations, and routing based on specific rules.
Universal Forwarders are lightweight and cannot perform these complex tasks, thus cannot serve as Intermediate Forwarders.
Splunk Documentation References:
* Intermediate Forwarders
NEW QUESTION # 46
Which of the following takes place during the input phase?
Answer: D
Explanation:
During the input phase in Splunk, the system processes incoming data by first setting the character encoding of the data. This step ensures that the data is correctly interpreted by Splunk, allowing it to be parsed and processed properly later in the pipeline. Other options describe actions that occur during later phases, such as parsing and indexing.
NEW QUESTION # 47
When monitoring directories that contain mixed file types, which setting should be omitted from inputs, conf and instead be overridden in propo.conf?
Answer: B
Explanation:
When monitoring directories containing mixed file types, the sourcetype should typically be overridden in props.conf rather than defined in inputs.conf. This is because sourcetype is meant to classify the type of data being ingested, and when dealing with mixed file types, setting a single sourcetype in inputs.conf would not be effective for accurate data classification. Instead, you can use props.conf to define rules that apply different sourcetypes based on the file path, file name patterns, or other criteria. This allows for more granular and accurate assignment of sourcetypes, ensuring the data is properly parsed and indexed according to its type.
Splunk Cloud Reference:For further clarification, refer to Splunk's official documentation on configuring inputs and props, especially the sections discussing monitoring directories and configuring sourcetypes.
Source:
* Splunk Docs: Monitor files and directories
* Splunk Docs: Configure event line breaking and input settings with props.conf
NEW QUESTION # 48
......
With our study materials, you do not need to have a high IQ, you do not need to spend a lot of time to learn, you only need to follow the method SPLK-1005 real questions provide to you, and then you can easily pass the exam. Our study material is like a tutor helping you learn, but unlike a tutor who make you spend too much money and time on learning. As usual, you just need to spend little time can have a good commend of our study materials, then you can attend to your SPLK-1005 Exam and pass it at your first attempt.
SPLK-1005 Valid Test Questions: https://www.prepawaytest.com/Splunk/SPLK-1005-practice-exam-dumps.html
2026 Latest PrepAwayTest SPLK-1005 PDF Dumps and SPLK-1005 Exam Engine Free Share: https://drive.google.com/open?id=1iAOjFLqcP3xE4DTl2TkMweGfiPTHCCW5