この急速に変化する世界では、Microsoft仕事と才能に対する要件は高く、人々が高給の仕事を見つけたい場合は、健康だけでなく作業能力も含むさまざまなスキルを高める必要があります。しかし、AI-200認定を取得すると、あなたの作業能力が証明され、理想的な仕事を見つけることができます。 AI-200試験に簡単に合格できる高品質のAI-200試験資料を提供します。また、AI-200試験の学習と準備にほとんど時間を必要としない多くの時間とエネルギーを節約できます。
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Develop AI solutions using Azure data services | 30% | - Implement vector-enabled databases
|
| Topic 2: Secure, monitor, and optimize AI solutions | 20% | - Implement observability and reliability
|
| Topic 3: Integrate backend services and build event-driven architectures | 25% | - Implement messaging and event systems
|
| Topic 4: Develop containerized AI solutions on Azure | 25% | - Monitor and troubleshoot containerized workloads
|
市場で高い評価を得ている責任ある企業として、スタッフと従業員を厳格な信念を持って訓練し、AI-200学習教材に関する問題を24時間年中無休で支援しました。私たちとの購入活動を終えたとしても、AI-200試験問題に関する思いやりのあるサービスを提供しています。そして、AI-200トレーニングガイドを随時更新します。AI-200スタディガイドを更新したら、お客様に自動送信します。お支払い後1年間、AI-200学習準備の更新をお楽しみいただけます。
質問 # 89
Hotspot Question
You are troubleshooting latency issues by using the requests table in Azure Monitor.
You need to calculate the average request duration grouped by cloud role name and also limit results to the past 30 minutes.
Which code elements should you select? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.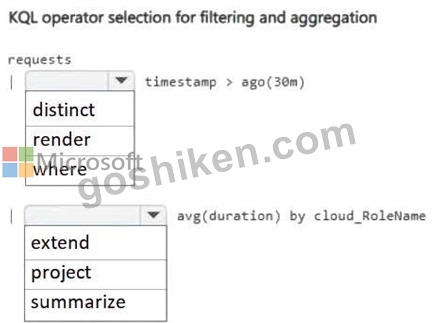
正解:
解説: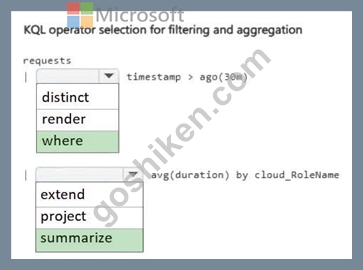
Explanation:
Box 1: where
In Kusto Query Language (KQL), the where operator filters the rows of a table to only include records that satisfy a specific predicate or condition.
Box 2: summarize
summarize is used for aggregations (count, avg, percentiles).
Reference:
https://world.optimizely.com/blogs/K-Khan-/Dates/2025/12/troubleshooting-with-azure-application-insights-using-kql
質問 # 90
You are designing a messaging solution by using Service Bus for AI document processing.
You need to ensure that a published message is delivered to multiple independent consumers.
Each consumer must receive their own copy of the message.
Which two Service Bus entities should you use? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
正解:A、D
解説:
Topics and Subscriptions are the two Azure Service Bus entities that fit this scenario.
Topics: The publisher sends the document processing message to a single topic, which acts as the central distribution hub.
Subscriptions: Each independent consumer creates its own individual subscription under that topic. When a message arrives, a copy is forwarded to every independent subscription so each consumer can process their own copy safely and separately.
Reference:
https://learn.microsoft.com/en-us/azure/service-bus-messaging/service-bus-queues-topics-subscriptions
質問 # 91
Case Study 2 - Proseware Inc.
Background
Proseware Inc. develops AI-powered knowledge management solutions for enterprise customers.
The company is modernizing its platform to support semantic search, intelligent document retrieval, and real-time partner integrations.
The engineering team uses Python and Azure SDKs. The architecture is being redesigned to support containerized microservices, vector search workloads, and serverless backend processing.
Planned Application Architecture
Microservices are containerized by using Docker.
Code for containerized microservices and Azure Function apps is developed locally but stored in a GitHub repository.
Custom images for containerized microservices are stored in Azure Container Registry (ACR).
Base images are stored in Docker Hub. Custom images must be rebuilt automatically whenever their base images are updated.
Azure Cosmos DB for NoSQL stores documents, metadata, and vector embeddings.
Azure Functions generate vector embeddings of Azure Cosmos DB for NoSQL-hosted documents and send messages to Service Bus to trigger search index updates.
Azure Container Apps (ACA) apps host backend API services that provide semantic search across Azure Cosmos DB for NoSQL documents. API services process Service Bus messages and update search indexes.
Azure Kubernetes Service (AKS) processes batch vector embedding regeneration for existing Azure Cosmos DB for NoSQL documents (whenever the embedding model is changed).
An extranet-facing containerized webhook allows business partners to submit documents to be processed by internal AI workflows for semantic search and retrieval.
Monitoring
Telemetry generated by Azure resources is sent to Azure Monitor.
A Log Analytics workspace is used to collect ACA apps logs, AKS container logs, and Azure Functions apps logs.
Monitoring of Azure Functions is currently implemented by using Azure Application Insights SDK instrumentation.
Business Requirements
Embeddings for new or updated Azure Cosmos DB for NoSQL-hosted documents must be automatically generated.
Backend API services must scale automatically during business hours.
Cold start delay of backend APIs must be minimized.
Secrets must be stored outside of container images.
Developers must be able to correlate telemetry across Azure Functions hosts and apps.
All tracing must be implemented by using OpenTelemetry SDK instrumentation.
Development efforts must be minimized.
Technical Requirements
Container images must be built automatically and validated before code updates are merged into the main branch.
Image build automation must run inside the Azure Container Registry, eliminating dependency on local developer machines and external build services.
Dependency of image builds on local developer machines must be eliminated.
Event-driven scaling in ACA must occur based on the number of pending messages in the Azure Service Bus queue.
Azure Cosmos DB for NoSQL RU consumption must be minimized.
Vector similarity search must use embeddings stored in Azure Cosmos DB for NoSQL.
The partner-facing containerized webhook service must run on Azure App Service.
Secrets must NOT be stored in container images, source control, or application configuration directly. They must be accessed securely at runtime.
All secrets must be stored centrally in Azure Key Vault and accessed at runtime through a managed identity.
Azure App Service must supply secrets at runtime without relying on external services.
Resources and workloads must be deployed by using Bicep templates through an automated, version-controlled pipeline. Local and command-line deployments must be eliminated to ensure repeatable, auditable deployments.
Known Issues
RU consumption spikes during vector similarity queries.
You need to deploy Azure Function resources and apps to meet the business and technical requirements. What should you use?
正解:D
解説:
GitHub Actions is the correct tool to use.
Automated Pipeline: It natively automates infrastructure deployment (Bicep) and code compilation through version-controlled workflows.
Eliminates Local Deployments: Workloads are triggered by repository events (like a code merge), removing the need for manual command-line interventions.
Auditability & Repeatability: It keeps a centralized log of every deployment, ensuring a clear audit trail for governance.
Scenario:
Technical Requirements
Resources and workloads must be deployed by using Bicep templates through an automated, version-controlled pipeline. Local and command-line deployments must be eliminated to ensure repeatable, auditable deployments.
Business Requirements
Development efforts must be minimized.
Reference:
https://github.com/marketplace/actions/azure-functions-action
質問 # 92
You are developing an application that uses a Python API to perform similarity queries against Azure Database for PostgreSQL. The application creates a new database connection for every request.
During peak traffic, the application intermittently fails to open new database sessions, logs indicate that the maximum number of connections have been reached.
You need to configure the connection pooling strategy to reduce connection setup overhead and maximize reuse for the high-concurrency workload.
What should you configure? To answer. select the appropriate options in the answer area NOTE: Each correct selection is worth one point.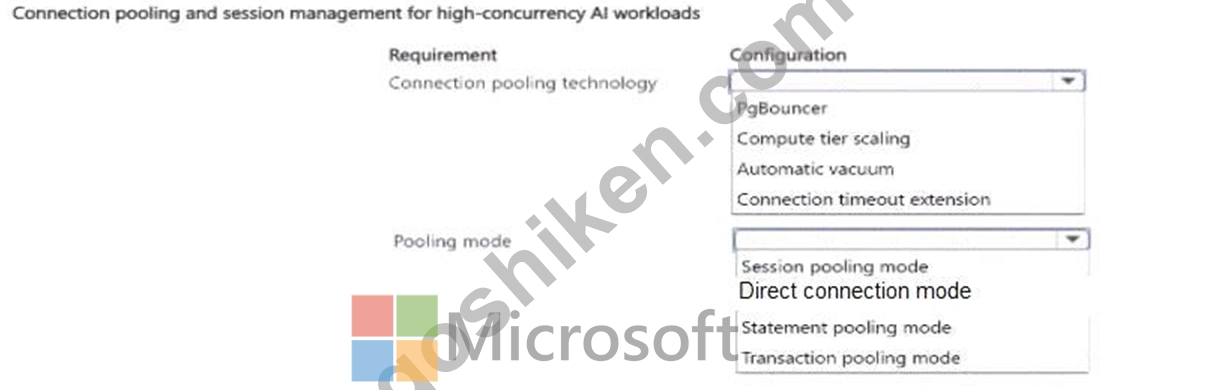
正解:
解説: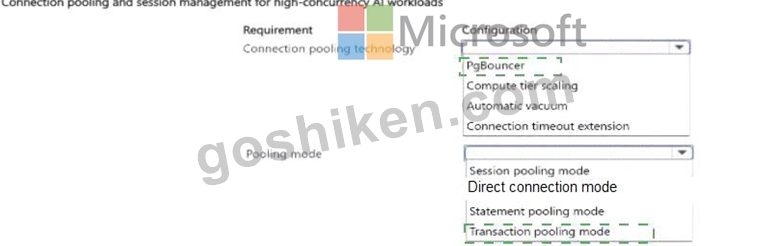
Explanation: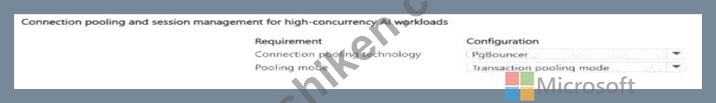
onnection pooling technology: PgBouncer. Pooling mode: Transaction pooling mode.
Detailed Explanation: Azure Database for PostgreSQL Flexible Server supports PgBouncer to reduce connection setup cost and protect the server from excessive client sessions. For a high-concurrency API whose requests do not require a server session to remain pinned between transactions, transaction pooling maximizes reuse by returning the server connection to the pool after each transaction. Session pooling holds a server connection for the lifetime of the client session and therefore provides less multiplexing under the connection-pressure scenario described.
Study Guide Alignment: AI data-management workloads: Cosmos DB, PostgreSQL, caching, vector storage, vector retrieval, consistency, and connection optimization.
Official Microsoft Learn References: AI-200 Study Guide | PgBouncer in Azure Database for PostgreSQL
質問 # 93
You have an Azure subscription named Sub1 that contains a resource group named RG1 and a Service Bus queue named SB1.
You plan to implement an Azure Event Grid push even: subscription that will deliver an event lo SB1 whenever a resource is created, modified, or deleted in RG1. You must minimize the development and configuration efforts.
You need to create an Event Grid topic for your planned implementation
Which type of event topic should you create?
正解:C
質問 # 94
......
AI-200学習資料は、消費者に無料の試用サービスをGoShiken提供します。 AI-200学習資料に興味があり、Microsoft無料でトライアル質問バンクをすぐにダウンロードして体験できます。 トライアルを通じて、AI-200試験ガイドでさまざまな学習経験ができます。私たちの言うことは嘘ではないことがわかり、すぐに製品に恋をすることになります。 あなたの人生の成功の鍵として、AI-200学習教材があなたにもたらす利益は金銭では測定されません。 AI-200試験トレントは、最短時間でDeveloping AI Cloud Solutions on Azure試験に合格するのに役立ちます。
AI-200最新問題: https://www.goshiken.com/Microsoft/AI-200-mondaishu.html