Fast and Effective Preparation with Databricks Databricks-Machine-Learning-Professional Exam Questions

BTW, DOWNLOAD part of TroytecDumps Databricks-Machine-Learning-Professional dumps from Cloud Storage: https://drive.google.com/open?id=1X3Tu3afZrfLQP8vC2RYDoyz-6_hVnWQ0
In order to meet the demand of most of the IT employees, TroytecDumps's IT experts team use their experience and knowledge to study the past few years Databricks certification Databricks-Machine-Learning-Professional exam questions. Finally, TroytecDumps's latest Databricks Databricks-Machine-Learning-Professional simulation test, exercise questions and answers have come out. Our Databricks Databricks-Machine-Learning-Professional simulation test questions have 95% similarity answers with real exam questions and answers, which can help you 100% pass the exam. If you do not pass the exam, TroytecDumps will full refund to you. You can also free online download the part of TroytecDumps's Databricks Certification Databricks-Machine-Learning-Professional Exam practice questions and answers as a try. After your understanding of our reliability, I believe you will quickly add TroytecDumps's products to your cart. TroytecDumps will achieve your dream.
| Topic | Details |
|---|
| Topic 1 | - Create, overwrite, merge, and read Feature Store tables in machine learning workflows
- View Delta table history and load a previous version of a Delta table
|
| Topic 2 | - Identify a use case for HTTP webhooks and where the Webhook URL needs to come
- Identify advantages of using Job clusters over all-purpose clusters
|
| Topic 3 | - Identify that data can arrive out-of-order with structured streaming
- Identify how model serving uses one all-purpose cluster for a model deployment
|
| Topic 4 | - Identify which code block will trigger a shown webhook
- Describe the basic purpose and user interactions with Model Registry
|
| Topic 5 | - Describe model serving deploys and endpoint for every stage
- Identify scenarios in which feature drift and
- or label drift are likely to occur
|
| Topic 6 | - Test whether the updated model performs better on the more recent data
- Identify when retraining and deploying an updated model is a probable solution to drift
|
| Topic 7 | - Describe concept drift and its impact on model efficacy
- Describe summary statistic monitoring as a simple solution for numeric feature drift
|
| Topic 8 | - Describe the advantages of using the pyfunc MLflow flavor
- Manually log parameters, models, and evaluation metrics using MLflow
|
>> Databricks-Machine-Learning-Professional Materials <<
Reliable Databricks-Machine-Learning-Professional Test Objectives & Intereactive Databricks-Machine-Learning-Professional Testing Engine
TroytecDumps is professional platform to establish for compiling Databricks exam materials for candidates, and we aim to help you to pass the examination as well as getting the related certification in a more efficient and easier way. Our answers and questions are compiled elaborately and easy to be mastered. Because our Databricks-Machine-Learning-Professional Test Braindumps are highly efficient and the passing rate is very high you can pass the exam fluently and easily with little time and energy needed.
Databricks Certified Machine Learning Professional Sample Questions (Q86-Q91):
NEW QUESTION # 86
A Data Scientist has created a sales forecasting model, named sales-forecasting. The model is deployed to a model serving endpoint with a schema. They need to invoke this model using Python and would prefer to use a SDK function to make the request. Which method suits these requirements?
- A. Make an API request to the MODEL_VERSION_URI and provide the dataframe_split as the request parameter.
- B. Use the built in ai_query function and provide the endpoints and request parameters.
- C. Import the MLflow Deployments class and use the ai_query method and provide the endpoints and request parameters.
- D. Import the MLflow Deployments class and use the predict method and provide the endpoint and input parameters.
Answer: D
Explanation:
The MLflow Deployments SDK provides a predict method specifically designed to invoke Databricks model serving endpoints from Python. This method abstracts the HTTP request details, allows specifying the endpoint name directly, and cleanly passes input parameters that conform to the model's serving schema, making it the preferred SDK-based approach.
NEW QUESTION # 87
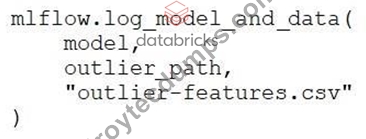
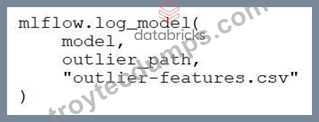
A data scientist wants to log outlier feature data from a CSV file at path outlier_path with an MLflow run for model model. Which code block will accomplish this task inside of an existing MLflow run block?
- A. mlflow.log_artifact(outlier_path, "outlier-features.csv")
- B.
- C.
- D. mlflow.log_data(outlier_path, "outlier-features.csv")
Answer: A
Explanation:
To log external files, such as a CSV containing outlier feature data, MLflow provides the mlflow.log_artifact() function. This function uploads the specified file or directory (outlier_path) as an artifact under the provided artifact path ("outlier-features.csv"). It is the correct way to associate data files with an MLflow run, whereas mlflow.log_model() is reserved for logging model objects, not arbitrary data.
NEW QUESTION # 88
Which is a benefit of logging an input example with an MLflow model?
- A. An example prediction is available to test post-inference pipelines
- B. The environment requirements are packaged with the MLmodel file
- C. An example record is available to test serving applications
- D. The model evaluation metrics are stored with the model
Answer: C
Explanation:
Logging an input example with an MLflow model provides a concrete sample of the data format expected by the model. This helps serving applications and users understand the model's input structure and verify that inference requests are properly formatted when deploying or testing the model in production.
NEW QUESTION # 89
A Machine Learning Engineer has trained a credit scoring model and needs to evaluate fairness metrics across different customer segments while maintaining different levels of granularity for business reporting. They need to compute metrics like precision, recall, and demographic parity at the individual feature level (credit_score_range, income_bracket) as well as intersectional slices (combinations of features). The model outputs are stored in a Delta table with prediction probabilities and actual default labels. The engineer wants to systematically evaluate model performance across these various feature slices and granularities. Which approach will do this?
- A. Use Unity Catalog metric views with dimensions defined for each feature and measures for the fairness metrics.
- B. Implement custom MLflow evaluation functions that iterate through all possible feature combinations.
- C. Create Lakehouse Monitoring with slicing expressions for individual features and intersection conditions.
- D. Build separate Spark DataFrames for each slice and compute metrics using standard DataFrame operations.
Answer: C
Explanation:
Lakehouse Monitoring supports defining slicing expressions on one or more columns, allowing metrics such as precision, recall, and fairness indicators to be computed at both individual feature levels and intersectional combinations. This provides a systematic, scalable, and governed way to evaluate model performance and fairness across multiple granularities directly from Delta tables without custom metric pipelines.
NEW QUESTION # 90
A Data Scientist is training a model to predict whether a customer will purchase a new product.
They are experimenting with many algorithm types (e.g., Linear Regression, Logistic Regression, Decision Trees) and hundreds of hyperparameter combinations. They are using MLflow to track their runs, but managing and distinguishing between runs has become difficult. They need an MLFIow technique that will organize and trace these experiments and that will follow commonly- accepted design patterns. Which technique will fulfill these requirements?
- A. Use AutoML to automatically test a variety of different algorithms and models.
- B. Log runs for each algorithm type to different MLflow Tracking servers to ensure the runs do not get mixed up.
- C. Use MLflows Automatic Logging feature to reduce the number of explicit log statements within each run to increase code readability.
- D. Set each algorithm type as a parent run and use nested runs for different hyperparameter settings within that parent run.
Answer: D
Explanation:
Using parent runs for each algorithm and nested runs for the associated hyperparameter experiments follows a widely accepted MLflow experiment design pattern. This structure makes it easy to organize, compare, and trace large numbers of related runs, improving experiment management and interpretability when exploring many models and hyperparameter configurations.
NEW QUESTION # 91
......
The desktop software Databricks Databricks-Machine-Learning-Professional practice exam format can be used easily used on your Windows system. Customers can use it without the internet. TroytecDumps have made all of the different formats so the students won't face any extra issues and crack Databricks-Machine-Learning-Professional Certification exams for the betterment of their futures.
Reliable Databricks-Machine-Learning-Professional Test Objectives: https://www.troytecdumps.com/Databricks-Machine-Learning-Professional-troytec-exam-dumps.html
- Free Download Databricks Databricks-Machine-Learning-Professional Materials With Interarctive Test Engine - High-quality Reliable Databricks-Machine-Learning-Professional Test Objectives 🤴 Search for ⇛ Databricks-Machine-Learning-Professional ⇚ and download it for free on ➡ www.pdfdumps.com ️⬅️ website 🤯Databricks-Machine-Learning-Professional Valid Test Answers
- Databricks-Machine-Learning-Professional Dumps PDF 💒 Databricks-Machine-Learning-Professional Reliable Test Bootcamp 🛑 Databricks-Machine-Learning-Professional Valid Test Answers ❤ Enter ▷ www.pdfvce.com ◁ and search for ⇛ Databricks-Machine-Learning-Professional ⇚ to download for free 🍫Databricks-Machine-Learning-Professional Dumps PDF
- Databricks-Machine-Learning-Professional Reliable Test Bootcamp 🤔 Databricks-Machine-Learning-Professional Reliable Braindumps Files 🐠 Databricks-Machine-Learning-Professional Customizable Exam Mode ⏩ Go to website ✔ www.verifieddumps.com ️✔️ open and search for ⮆ Databricks-Machine-Learning-Professional ⮄ to download for free 🎢Databricks-Machine-Learning-Professional Latest Test Sample
- 2026 Databricks-Machine-Learning-Professional Materials - Databricks Databricks Certified Machine Learning Professional - High-quality Reliable Databricks-Machine-Learning-Professional Test Objectives 🐀 Search on ▛ www.pdfvce.com ▟ for ⮆ Databricks-Machine-Learning-Professional ⮄ to obtain exam materials for free download 🚋Databricks-Machine-Learning-Professional Updated Dumps
- Believable Databricks-Machine-Learning-Professional Guide Materials: Databricks Certified Machine Learning Professional Present You the Most Popular Exam Dumps - www.prepawaypdf.com ⚒ The page for free download of ( Databricks-Machine-Learning-Professional ) on ▛ www.prepawaypdf.com ▟ will open immediately 🚪Databricks-Machine-Learning-Professional Latest Test Sample
- Formal Databricks-Machine-Learning-Professional Test 🙈 Databricks-Machine-Learning-Professional Reliable Test Bootcamp ⏹ Databricks-Machine-Learning-Professional Valid Torrent 🥫 Enter ▷ www.pdfvce.com ◁ and search for ▛ Databricks-Machine-Learning-Professional ▟ to download for free 🕓Databricks-Machine-Learning-Professional Customizable Exam Mode
- Pass Guaranteed Databricks - Latest Databricks-Machine-Learning-Professional Materials 👭 Search for ▷ Databricks-Machine-Learning-Professional ◁ and download it for free immediately on ▛ www.pdfdumps.com ▟ 🔛Databricks-Machine-Learning-Professional Valid Test Answers
- 2026 Databricks-Machine-Learning-Professional Materials - Databricks Databricks Certified Machine Learning Professional - High-quality Reliable Databricks-Machine-Learning-Professional Test Objectives 🦰 Open ⮆ www.pdfvce.com ⮄ and search for 《 Databricks-Machine-Learning-Professional 》 to download exam materials for free 👗Databricks-Machine-Learning-Professional Valid Exam Experience
- Databricks-Machine-Learning-Professional Certification Exam 💨 Databricks-Machine-Learning-Professional Dumps PDF 🛄 Databricks-Machine-Learning-Professional Latest Test Sample 🦪 Search for ⇛ Databricks-Machine-Learning-Professional ⇚ and easily obtain a free download on ➠ www.examdiscuss.com 🠰 🦩Databricks-Machine-Learning-Professional Updated Dumps
- Databricks-Machine-Learning-Professional Reliable Mock Test 🐊 Databricks-Machine-Learning-Professional Latest Test Sample 🎀 New Databricks-Machine-Learning-Professional Test Answers 🏯 Search for “ Databricks-Machine-Learning-Professional ” on ➤ www.pdfvce.com ⮘ immediately to obtain a free download 🎥Databricks-Machine-Learning-Professional Valid Exam Experience
- Databricks-Machine-Learning-Professional Updated Dumps 🆖 PDF Databricks-Machine-Learning-Professional VCE 😠 Databricks-Machine-Learning-Professional Reliable Braindumps Files ⚗ [ www.prep4sures.top ] is best website to obtain ▶ Databricks-Machine-Learning-Professional ◀ for free download 🛐Databricks-Machine-Learning-Professional Dumps PDF
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, tooter.in, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, ifidir.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, Disposable vapes
What's more, part of that TroytecDumps Databricks-Machine-Learning-Professional dumps now are free: https://drive.google.com/open?id=1X3Tu3afZrfLQP8vC2RYDoyz-6_hVnWQ0