What's more, part of that TorrentExam SPS-C01 dumps now are free: https://drive.google.com/open?id=1GMMult5zmqq9snTyG1fn0cwQ7AdOfoTX
Our TorrentExam provides the latest and the most complete SPS-C01 exam questions and answers aimed at becoming the most reliable dumps provider in IT exam software. With the help of our TorrentExam, nearly all those who have purchased our dumps have successfully passed the difficult SPS-C01 Exam, which gives us great confidence to recommend our reliable products to you. We can assure you that we will fully refund the cost you purchased our dump, if you fail SPS-C01 exam with our dumps. So, just rest assured to prepare for your exam.
| Section | Objectives |
|---|---|
| Topic 1: DataFrame Operations and Data Processing | - Data transformation workflows
|
| Topic 2: Data Engineering with Snowpark | - Pipeline development
|
| Topic 3: Snowpark Fundamentals | - Snowpark architecture and concepts
|
| Topic 4: User Defined Functions and Stored Procedures | - Extending Snowpark with custom logic
|
| Topic 5: Performance Optimization and Best Practices | - Efficient Snowpark execution
|
| Topic 6: Testing, Debugging, and Deployment | - Production readiness
|
Knowledge about a person and is indispensable in recruitment. That is to say, for those who are without good educational background, only by paying efforts to get an acknowledged SPS-C01 certification, can they become popular employees. So for you, the SPS-C01 latest braindumps complied by our company can offer you the best help. With our test-oriented SPS-C01 Test Prep in hand, we guarantee that you can pass the SPS-C01 exam as easy as blowing away the dust, as long as you guarantee 20 to 30 hours practice with our SPS-C01 study materials.
NEW QUESTION # 245
You are tasked with deploying a set of Python UDFs and UDTFs to a Snowflake environment using Snowpark. These functions rely on several external Python packages and need to be versioned and managed effectively. Which of the following strategies provides the MOST robust and scalable solution for managing dependencies and deploying these functions in a reproducible manner?
Answer: B,E
Explanation:
Options B and C provide the most robust and scalable solution. Creating a conda environment specification file (environment.yml) allows for precise control over dependencies and their versions. Both allow other devs to work with the same environment. Uploading the yml allows to include it as a part of snowflake's udfs and udtfs. The difference is whether it can be done directly in snowpark (B) or through the CLI (C). Option A is less manageable as dependencies grow and is prone to manual errors. Option D is not the correct way to handle dependencies for UDFs/UDTFs; the 'imports' parameter is used for data files and other resources, not for installing Python packages.
NEW QUESTION # 246
Consider a scenario where you have a table 'EMPLOYEES' with columns 'employee id', 'department', and 'salary'. You want to delete employees who belong to either the 'HR' or 'Finance' department and have a salary less than 60000. Which of the following Snowpark DataFrame operations correctly implements this deletion?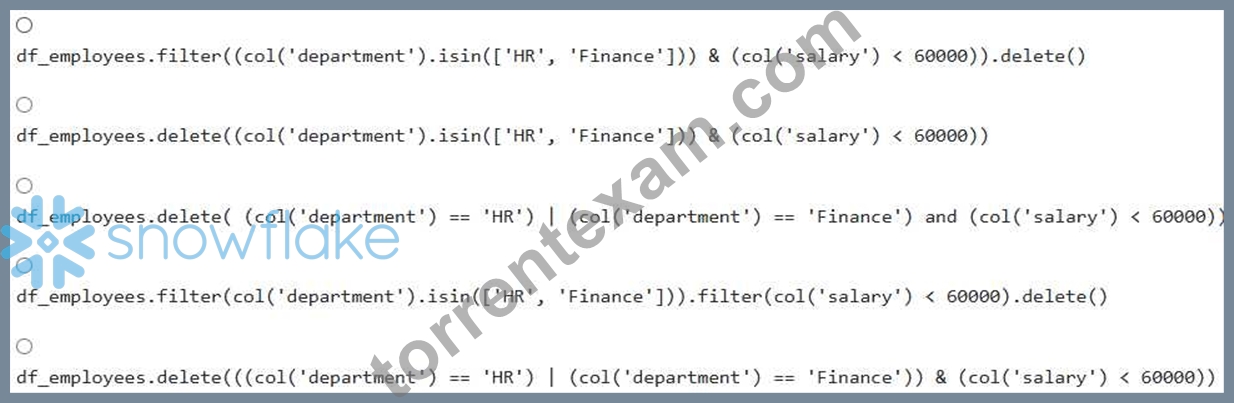
Answer: D
Explanation:
Option E is the correct solution because it uses the 'delete' function with the correct boolean logic: == 'HR') I (col('department') 'Finance')) & (col('salary') < 60000)'. This accurately translates to 'department is HR OR department is Finance AND salary is less than 60000'. Option A has incorrect syntax for 'delete()' usage. Option B is missing parenthesis for correct precedence. Option C has incorrect precedence; the 'and' will bind tighter than the or. Option D filters twice but does not correctly use the .delete' method with filter conditions.
NEW QUESTION # 247
A Snowpark application needs to authenticate to Snowflake using OAuth. The application is running on an Azure Function and uses a client ID, client secret, and refresh token obtained previously. Which of the following connection parameter dictionaries is correctly configured for OAuth authentication?





Answer: A
Explanation:
Option E correctly specifies 'oauth' as the authenticator and uses the access token to establish the connection. Using the access token directly after obtaining it is the common practice for OAuth in Snowpark. Options A, B, C and D are incorrect because for Snowpark, you typically use the access token, not the refresh token, directly in the connection parameters after you've initially exchanged the refresh token for an access token outside of this specific session establishment.
NEW QUESTION # 248
You are tasked with developing a data pipeline using Snowpark that involves reading data from multiple CSV files, performing transformations using Pandas DataFrames, and then loading the transformed data into a Snowflake table. You want to optimize the process by leveraging the capabilities of Snowpark and Pandas effectively. Which of the following approaches is the MOST efficient for creating the Snowpark DataFrame from the pandas dataframe? (Select all that apply.)
Answer: C,D
Explanation:
Option C is the most efficient when the transformations can be effectively done using Snowpark itself, bypassing Pandas entirely and leveraging Snowflake's compute power directly. Option D, while using Pandas for transformation, optimizes data transfer using the optimized 'write_pandas' function. Creating Snowpark DataFrames from Pandas DataFrames and then unioning (Option B) can be less performant due to data transfer overhead. Concatenating Pandas DataFrames and then creating a Snowpark DataFrame (Option A) can be memory-intensive. Option E is incorrect, setting will throw an error if table does not exist.
NEW QUESTION # 249
A data engineer is developing a Snowpark application using Python and needs to connect to Snowflake. They want to avoid hardcoding credentials directly in the script and utilize environment variables for authentication. Which of the following approaches is the MOST secure and RECOMMENDED way to retrieve Snowflake connection parameters (account, user, password, database, schema, warehouse, role) from environment variables and establish a Snowpark session?
Answer: A
Explanation:
Option E, 'Session.builder.getOrCreate(V , is the most concise and recommended approach. It automatically retrieves connection parameters from standard environment variables (e.g., SNOWFLAKE_USER, SNOWFLAKE_PASSWORD, SNOWFLAKE_ACCOUNT). This simplifies the code and reduces the risk of errors. Option A is verbose and prone to errors. Option B introduces unnecessary complexity and parsing. Option C involves the classic Snowflake connector, which is not the recommended way with Snowpark for Python. Option D involves snowCLl profiles and is not using Environment Variables.
NEW QUESTION # 250
......
We are aimed to develop a long-lasting and reliable relationship with our customers who are willing to purchase our SPS-C01 study materials. To enhance the cooperation built on mutual-trust, we will renovate and update our system for free so that our customers can keep on practicing our SPS-C01 Study Materials without any extra fee. Meanwhile, to ensure that our customers have greater chance to pass the SPS-C01 exam, we will make our SPS-C01 test training keeps pace with the digitized world that change with each passing day.
Reliable SPS-C01 Test Prep: https://www.torrentexam.com/SPS-C01-exam-latest-torrent.html
BTW, DOWNLOAD part of TorrentExam SPS-C01 dumps from Cloud Storage: https://drive.google.com/open?id=1GMMult5zmqq9snTyG1fn0cwQ7AdOfoTX