The computer is widely used in all phases of society. If you get a Databricks certification you will have wide development for business, education, medicine and nearly all walks of life. Databricks-Certified-Professional-Data-Engineer test dumps materials play an important role if you are willing to get a certificate. If you can show your computer skills and talents, it will be your outstanding advantage over others. Pass4sureCert Valid Databricks-Certified-Professional-Data-Engineer Test Dumps materials may be your first step to success as an IT worker.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Data Sharing and Federation | 5% | - Cross-workspace and cross-cloud access - Unity Catalog data sharing |
| Topic 2: Ensuring Data Security and Compliance | 10% | - Data encryption and masking - Access control and permissions - Compliance standards implementation |
| Topic 3: Data Ingestion & Acquisition | 7% | - Auto Loader and streaming ingestion - Schema inference and evolution - Connecting to diverse data sources |
| Topic 4: Cost & Performance Optimisation | 13% | - Storage optimization (partitioning, Z-order, indexing) - Cluster configuration and scaling - Query optimization and caching |
| Topic 5: Monitoring and Alerting | 10% | - Pipeline observability and logging - Setting up alerts and notifications - Performance and health monitoring |
| Topic 6: Debugging and Deploying | 10% | - Deployment using bundles, CLI, and APIs - CI/CD and DevOps practices - Troubleshooting pipelines and errors |
| Topic 7: Developing Code for Data Processing using Python and SQL | 22% | - Data transformation and aggregation - Batch and incremental processing logic - Integration with Databricks APIs and tools |
| Topic 8: Data Transformation, Cleansing, and Quality | 10% | - Standardization and normalization - Data validation and quality checks - Handling missing or inconsistent data |
| Topic 9: Data Modelling | 6% | - Delta Lake table design - Schema design and management - Medallion Architecture implementation |
| Topic 10: Data Governance | 7% | - Data lineage and metadata tracking - Unity Catalog management - Policy enforcement |
>> New Databricks-Certified-Professional-Data-Engineer Exam Cram <<
The Databricks Certified Professional Data Engineer Exam (Databricks-Certified-Professional-Data-Engineer) PDF format, desktop practice test software, and web-based practice test software, all three formats of actual exam questions are ready for quick download. You just need to pay the affordable Databricks Databricks-Certified-Professional-Data-Engineer Exam Questions charges and click on the download button. Get them now and start Databricks Certified Professional Data Engineer Exam (Databricks-Certified-Professional-Data-Engineer) exam preparation today.
NEW QUESTION # 75
A nightly job ingests data into a Delta Lake table using the following code: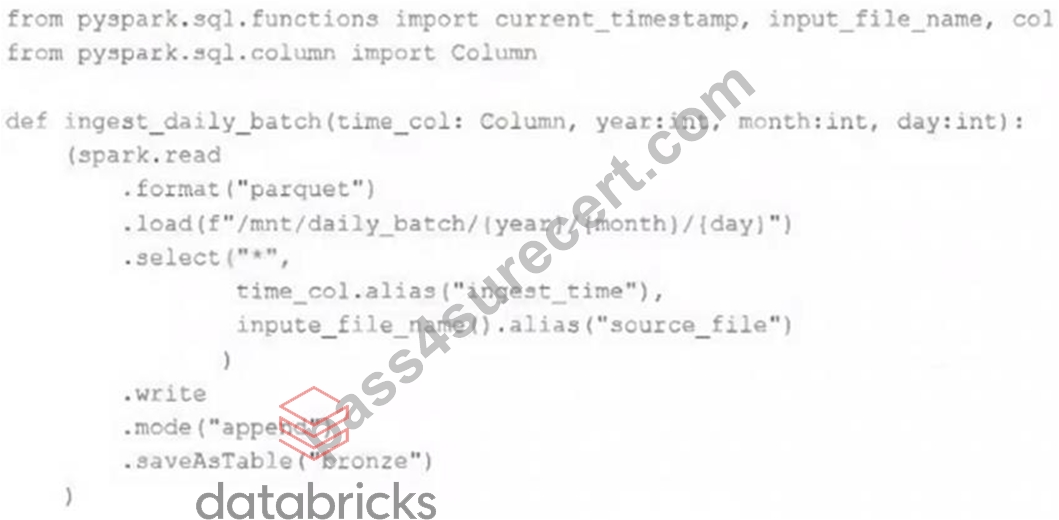
The next step in the pipeline requires a function that returns an object that can be used to manipulate new records that have not yet been processed to the next table in the pipeline.
Which code snippet completes this function definition?
def new_records():
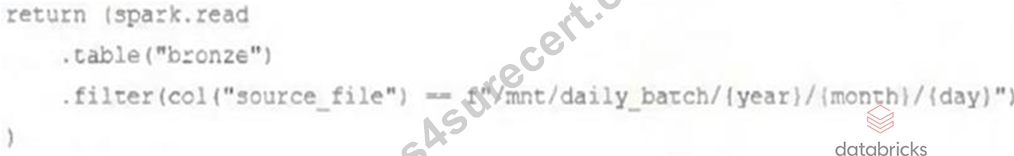
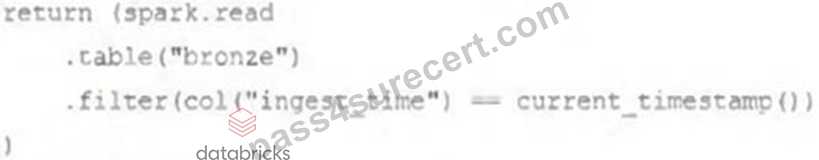
Answer: A
Explanation:
Explanation
This is the correct answer because it completes the function definition that returns an object that can be used to manipulate new records that have not yet been processed to the next table in the pipeline. The object returned by this function is a DataFrame that contains all change events from a Delta Lake table that has enabled change data feed. The readChangeFeed option is set to true to indicate that the DataFrame should read changes from the table, and the table argument specifies the name of the table to read changes from. The DataFrame will have a schema that includes four columns: operation, partition, value, and timestamp. The operation column indicates the type of change event, such as insert, update, or delete. The partition column indicates the partition where the change event occurred. The value column contains the actual data of the change event as a struct type. The timestamp column indicates the time when the change event was committed. Verified References: [Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "Read changes in batch queries" section.
NEW QUESTION # 76
The data architect has mandated that all tables in the Lakehouse should be configured as external Delta Lake tables.
Which approach will ensure that this requirement is met?
Answer: D
Explanation:
This is the correct answer because it ensures that this requirement is met. The requirement is that all tables in the Lakehouse should be configured as external Delta Lake tables. An external table is a table that is stored outside of the default warehouse directory and whose metadata is not managed by Databricks. An external table can be created by using the location keyword to specify the path to an existing directory in a cloud storage system, such as DBFS or S3. By creating external tables, the data engineering team can avoid losing data if they drop or overwrite the table, as well as leverage existing data without moving or copying it.
Verified References: [Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "Create an external table" section.
NEW QUESTION # 77
The data science team has created and logged a production using MLFlow. The model accepts a list of column names and returns a new column of type DOUBLE.
The following code correctly imports the production model, load the customer table containing the customer_id key column into a Dataframe, and defines the feature columns needed for the model.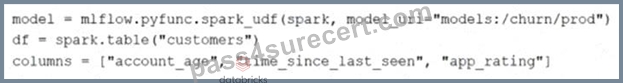
Which code block will output DataFrame with the schema'' customer_id LONG, predictions DOUBLE''?
Answer: D
Explanation:
Given the information that the model is registered with MLflow and assuming predict is the method used to apply the model to a set of columns, we use the model.predict() function to apply the model to the DataFrame df using the specified columns. The model.predict() function is designed to take in a DataFrame and a list of column names as arguments, applying the trained model to these features to produce a predictions column. When working with PySpark, this predictions column needs to be selected alongside the customer_id to create a new DataFrame with the schema customer_id LONG, predictions DOUBLE.
References:
MLflow documentation on using Python function models: https://www.mlflow.org/docs/latest/models.
html#python-function-python
PySpark MLlib documentation on model prediction: https://spark.apache.org/docs/latest/ml-pipeline.
html#pipeline
NEW QUESTION # 78
A Spark job is taking longer than expected. Using the Spark UI, a data engineer notes that the Min, Median, and Max Durations for tasks in a particular stage show the minimum and median time to complete a task as roughly the same, but the max duration for a task to be roughly 100 times as long as the minimum.
Which situation is causing increased duration of the overall job?
Answer: C
Explanation:
This is the correct answer because skew is a common situation that causes increased duration of the overall job. Skew occurs when some partitions have more data than others, resulting in uneven distribution of work among tasks and executors. Skew can be caused by various factors, such as skewed data distribution, improper partitioning strategy, or join operations with skewed keys. Skew can lead to performance issues such as long-running tasks, wasted resources, or even task failures due to memory or disk spills. Verified Reference: [Databricks Certified Data Engineer Professional], under "Performance Tuning" section; Databricks Documentation, under "Skew" section.
NEW QUESTION # 79
The default threshold of VACUUM is 7 days, internal audit team asked to certain tables to maintain at least
365 days as part of compliance requirement, which of the below setting is needed to implement.
Answer: C
Explanation:
Explanation
1.ALTER TABLE table_name SET TBLPROPERTIES ( property_key [ = ] property_val [, ...] ) TBLPROPERTIES allow you to set key-value pairs Table properties and table options (Databricks SQL) | Databricks on AWS
NEW QUESTION # 80
......
In Pass4sureCert's website you can free download study guide, some exercises and answers about Databricks Certification Databricks-Certified-Professional-Data-Engineer Exam as an attempt.
Databricks-Certified-Professional-Data-Engineer Exam Revision Plan: https://www.pass4surecert.com/Databricks/Databricks-Certified-Professional-Data-Engineer-practice-exam-dumps.html