BONUS!!! Download part of PassExamDumps AI-300 dumps for free: https://drive.google.com/open?id=1e8MbnD1-UzYaM44-XzJegG92u9P3WNRV
If you buy the Software or the APP online version of our AI-300 study materials, you will find that the timer can aid you control the time. Once it is time to submit your exercises, the system of the AI-300 preparation exam will automatically finish your operation. After a several time, you will get used to finish your test on time. If you are satisfied with our AI-300 training guide, come to choose and purchase.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Optimize generative AI systems and model performance | 15–20% | - Improve efficiency and cost-effectiveness
|
| Topic 2: Implement machine learning model lifecycle and operations | 25–30% | - Deploy models to production
|
| Topic 3: Design and implement an MLOps infrastructure | 15–20% | - Implement infrastructure as code for Machine Learning
|
| Topic 4: Design and implement a GenAIOps infrastructure | 20–25% | - Set up Microsoft Foundry environment
|
| Topic 5: Implement generative AI quality assurance and observability | 10–15% | - Monitor generative AI systems
|
In order to solve customers’ problem in the shortest time, our Operationalizing Machine Learning and Generative AI Solutions guide torrent provides the twenty four hours online service for all people. Maybe you have some questions about our AI-300 test torrent when you use our products; it is your right to ask us in anytime and anywhere. You just need to send us an email, our online workers are willing to reply you an email to solve your problem in the shortest time. During the process of using our AI-300 study torrent, we can promise you will have the right to enjoy the twenty four hours online service provided by our online workers. At the same time, we warmly welcome that you tell us your suggestion about our AI-300 study torrent, because we believe it will be very useful for us to utilize our AI-300 test torrent.
NEW QUESTION # 78
Drag and Drop Question
You manage an Microsoft Foundry project.
You deploy a large language model from the model catalog.
You need to manually evaluate the model, collect the statistics, and be able to review the results later.
Which four actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.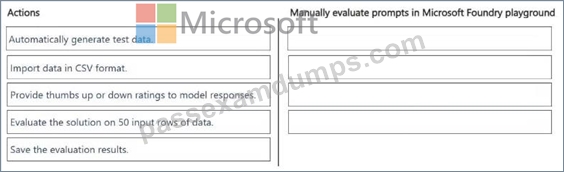
Answer:
Explanation: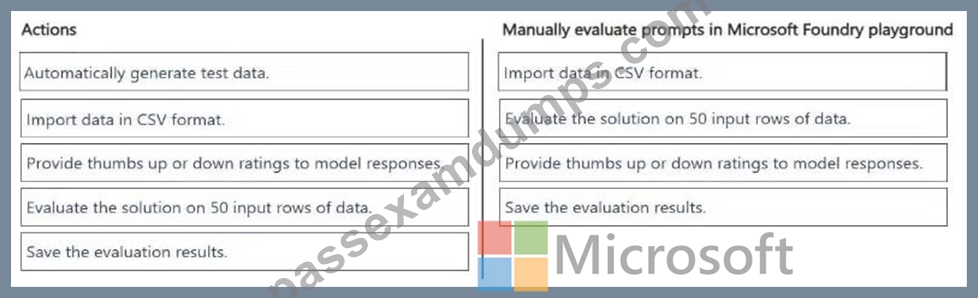
Explanation:
Step 1: Import Data in CSV Format
Supported formats: Azure AI Studio natively accepts .csv and .jsonl files for evaluation datasets.
Requirement: Your file must contain the input columns (e.g., user prompts) that you want to test against the model.
Step 2: Evaluate the Solution on 50 input Rows
Sample size: 50 rows is an excellent size for a manual, qualitative test baseline.
Execution: You will upload this dataset into the Evaluation blade of your project and map your data fields to the model's inputs.
Step 3: Provide thumbs up or down ratings to model responses
Manual UI: The platform features a manual review interface (often called human-in-the-loop evaluation).
Feedback: You can view the model's generated response for each of the 50 rows side-by-side with the input and log your binary (thumbs up/down) or detailed feedback.
Step 4: Save the evaluation results
Persistence: Once completed, the session is saved to your project's run history.
Review: You can return to the dashboard later to view aggregate statistics, check pass/fail rates, and export the annotated data for your records.
Reference:
https://oneuptime.com/blog/post/2026-02-16-how-to-perform-azure-migrate-at-scale-using-csv-import-for-large-datacenter-inventories/view
NEW QUESTION # 79
You have an Azure Machine Learning workspace named Workspace 1 Workspace! has a registered Mlflow model named model 1 with PyFunc flavor You plan to deploy model1 to an online endpoint named endpoint1 without egress connectivity by using Azure Machine learning Python SDK vl You have the following code: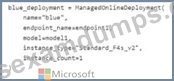
You need to add a parameter to the ManagedOnllneDeployment object to ensure the model deploys successfully Solution: Add the scoring_script parameter.
Does the solution meet the goal?
Answer: B
NEW QUESTION # 80
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear on the review screen.
You manage a Retrieval-Augmented Generation (RAG) application built on Microsoft Foundry.
The application retrieves documents from an indexed knowledge base and generates answers for internal users.
Recent feedback indicates that answers are fluent but sometimes include information that is not supported by the documents that were retrieved.
You need to evaluate whether a proposed change improves RAG answer quality by using supported and measurable techniques.
Solution: Compare embedding vector dimensions used by the retrieval pipeline before and after the change.
Does the solution meet the goal?
Answer: A
Explanation:
Correct:
* Review user feedback comments collected after deployment to determine whether answers appear more accurate.
Relying solely on user feedback comments is not the proper immediate action for evaluating this specific issue but it is still the best choice.
Evaluate whether your proposed change improves the Retrieval-Augmented Generation (RAG) system by reducing hallucinations (unsupported information), you need to measure faithfulness and context relevance using automated, quantifiable metrics.
The proper course of action is to implement an LLM-as-a-Judge framework using an open-source evaluation library like Ragas or TruLens.
Recommended Evaluation Plan
Establish a baseline: Run your current RAG pipeline through a test dataset of 50-100 representative user queries.
Capture the outputs: Save the user query, the exact retrieved document snippets, and the generated response for every test.
Apply the change: Deploy your proposed modification (e.g., altered prompt, different temperature, or re-ranking algorithm).Run the evaluation: Pass the test dataset through the updated pipeline to generate a new set of responses.
Compare the metrics: Use the framework to score both sets of data and mathematically verify if the change reduced unsupported claims.
Incorrect:
* Compare embedding vector dimensions used by the retrieval pipeline before and after the change.
Comparing embedding vector dimensions is not a valid or effective method for measuring RAG answer quality. Vector dimensions (e.g., 1536 or 3072) are static architectural properties of your embedding model. They do not reflect factual accuracy, semantic grounding, or the rate of hallucinations in your text generation.
* Measure token throughput and average response latency before and after applying the proposed change.
Measuring token throughput and latency is not the correct action to solve this specific problem.
Reference:
https://www.getmaxim.ai/articles/how-to-evaluate-your-rag-system/
NEW QUESTION # 81
You create an Azure Machine Learning model to include model files and a scorning script. You must deploy the model. The deployment solution must meet the following requirements:
* Provide near real-time inferencing.
* Enable endpoint and deployment level cost estimates.
* Support logging to Azure Log Analytics.
You need to configure the deployment solution.
What should you configure? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.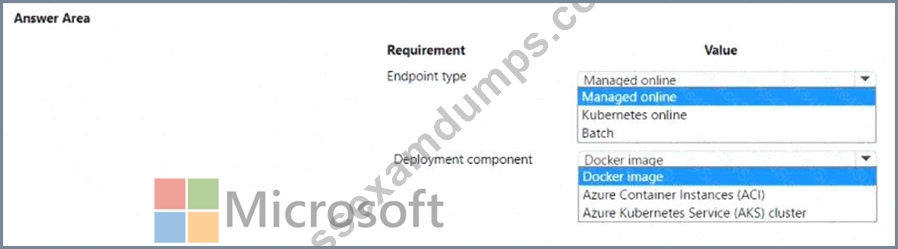
Answer:
Explanation: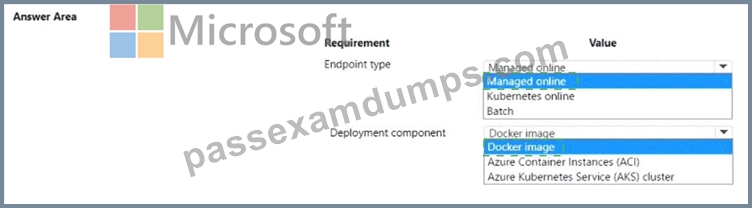
Explanation: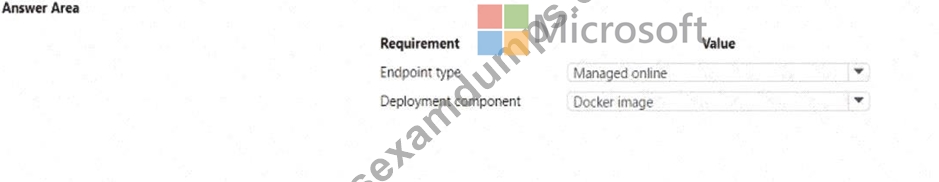
NEW QUESTION # 82
Hotspot Question
You manage an Azure Machine Learning workspace named workspace1 by using the Python SDK v2. You create a General Purpose v2 Azure storage account named mlstorage1. The storage account includes a publicly accessible container named mlcontainer1. The container stores 10 blobs with files in the CSV format.
You must develop Python SDK v2 code to create a data asset referencing all blobs in the container named mlcontainer1.
You need to complete the Python SDK v2 code.
How should you complete the code? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.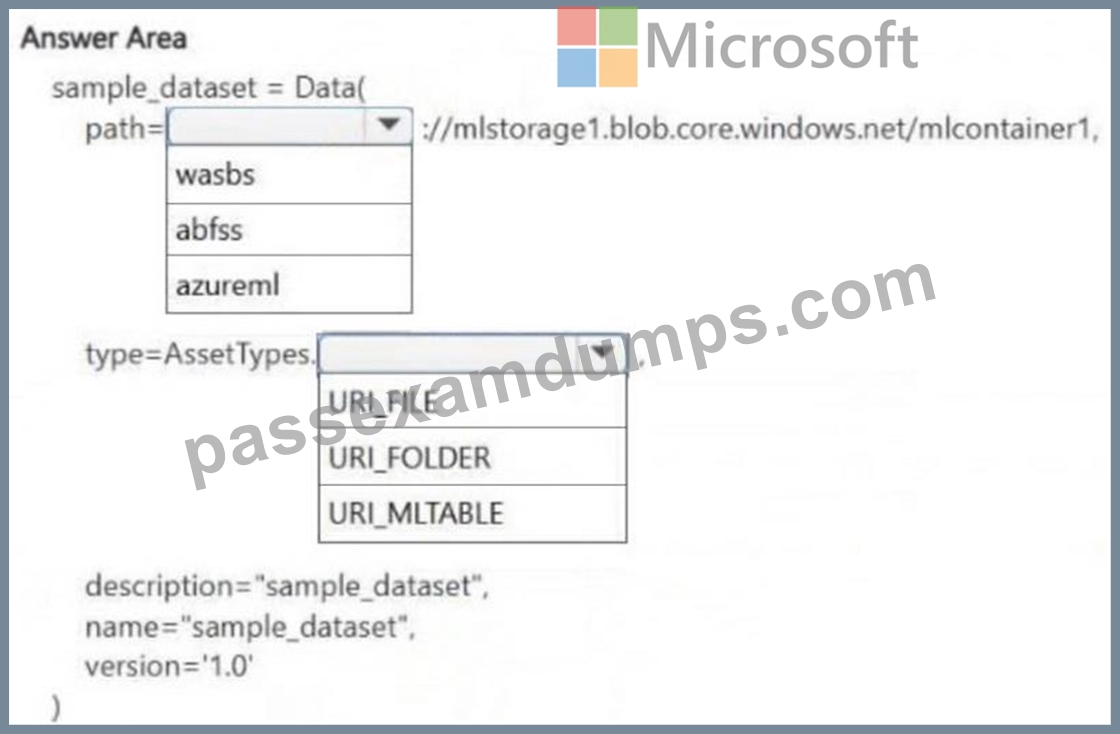
Answer:
Explanation: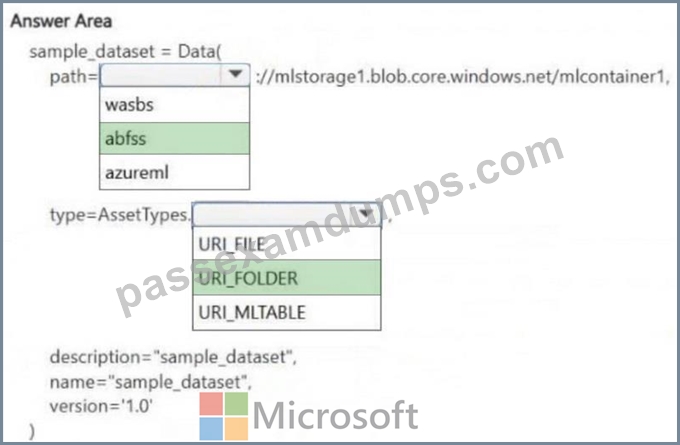
NEW QUESTION # 83
......
Everybody wants success, but not everyone has a strong mind to persevere in study. If you feel unsatisfied with your present status, our AI-300 actual exam can help you out. Our products always boast a pass rate as high as 99%. Using our AI-300 study materials can also save your time in the exam preparation. If you choose our AI-300 Practice Engine, you are going to get the certification easily. Just make your choice and purchase our AI-300 training quiz and start your study now!
Valid AI-300 Study Materials: https://www.passexamdumps.com/AI-300-valid-exam-dumps.html
2026 Latest PassExamDumps AI-300 PDF Dumps and AI-300 Exam Engine Free Share: https://drive.google.com/open?id=1e8MbnD1-UzYaM44-XzJegG92u9P3WNRV