Some candidates may want to get the AI-200 exam braindumps as soonas possible after they buying it, if you also want to get the AI-200 exam braindumps quickly, we can do it for you. You pay for the AI-200 exam dumps, we will send you the downloading link and password to you about five to ten minutes by email. What’s more our AI-200 Exam Braindumps is of high quality, it will help you to pass the exam successfully.
| Section | Weight | Objectives |
|---|---|---|
| Secure, monitor, and optimize AI solutions | 20% | - Implement observability and reliability
|
| Develop containerized AI solutions on Azure | 25% | - Monitor and troubleshoot containerized workloads
|
| Develop AI solutions using Azure data services | 30% | - Design and optimize data access and retrieval
|
| Integrate backend services and build event-driven architectures | 25% | - Build serverless APIs and workflows
|
>> AI-200 New Braindumps Questions <<
ActualtestPDF free update our training materials, which means you will always get the latest AI-200 exam training materials. If AI-200 exam objectives change, The learning materials ActualtestPDF provided will follow the change. ActualtestPDF know the needs of each candidate, we will help you through your AI-200 Exam Certification. We help each candidate to pass the exam with best price and highest quality.
NEW QUESTION # 131
Case Study 1 - Fabrikam Inc.
Background
Fabrikam Inc. is a global retail analytics company that provides AI-driven demand forecasting and product recommendation services to online retailers. The company is modernizing its solution to run entirely on Microsoft Azure.
The platform ingests transaction data, generates embeddings for semantic retrieval, performs vector similarity search, and returns product recommendations through containerized microservices. Developers use Python and Azure SDKs. Operations teams manage container orchestration, scaling, monitoring, and security.
The solution must meet strict performance, scalability, and security requirements.
Current environment
Application architecture
The Recommendation engine is a customer-facing HTTP API running as a containerized Python application. The engine is deployed to Azure Container Apps (ACA).
Embeddings are stored in Azure Database for PostgreSQL by using pgvector.
Semantic retrieval uses metadata filtering combined with vector similarity search.
Azure Managed Redis is used as a caching layer.
Front-end and API workloads are deployed to Azure Container Apps (ACA).
Batch model retraining workloads run in Azure Kubernetes Service (AKS).
Container and CI/CD
Container images are stored in Azure Container Registry (ACR).
CI/CD uses ACR Tasks to build images on commit.
ACA environments support revision management.
AKS workloads are deployed by using Kubernetes manifest files stored in Git.
Monitoring
Logs are collected in Azure Monitor.
Teams inspect container logs and Kubernetes events when troubleshooting.
Developers write KQL queries to analyze latency spikes.
Business requirements
Customer experience: Maintain a seamless, low-latency recommendation experience for end- users, even during unpredictable seasonal traffic spikes.
Operational cost efficiency: Minimize compute expenditures by deallocating resources during periods of inactivity and by preventing runaway scaling costs.
Data integrity and freshness: Ensure that product recommendations always reflect the most current catalog metadata and pricing to prevent customer dissatisfaction.
Security and compliance: Adhere to a Zero Trust security model by eliminating long-lived credentials and centralizing the management of all sensitive secrets.
Global scalability: Support the rapid ingestion of millions of new product embeddings daily without degrading query performance for existing retailers.
Technical requirements
Performance: Semantic search latency must remain under 200 milliseconds at peak load.
Database optimization: Use pgvector for embeddings and implement metadata filtering to reduce compute overhead. Configure compute and memory appropriately for vector workloads to ensure high-dimensional index residency in RAM and efficient mathematical throughput. Vector similarity calculations must be performed only against products that satisfy mandatory metadata constraints.
Database performance: Database connections must support high concurrency with minimal latency through the implementation of connection optimization.
Data load strategy: To ensure maximum ingestion throughput, secondary indexes must be applied only after bulk loading of embeddings is complete.
Caching: Redis cache entries must expire automatically after 10 minutes. Implement a reactive mechanism to invalidate cache entries upon metadata updates.
Identity: Use managed identities for all service-to-service and service-to-database authentication.
Plain-text credentials in configuration files are strictly prohibited.
Secret management: All secrets must be stored centrally. Secrets must be rotated automatically by using a centralized lifecycle policy.
Scaling: Use Kubernetes event-driven autoscaling (KEDA) for event-driven scaling. The Recommendation API must scale based on HTTP traffic, while batch jobs must scale based on queue length and support scale-to-zero.
CI/CD: All images must be stored in Azure Container Registry. Use ACR Tasks to automate image builds triggered by source code commits.
Monitoring: Use KQL to analyze performance telemetry and troubleshoot microservice connectivity failures. Inspect logs and events when troubleshooting AKS and ACA.
You need to improve throughput for concurrent application requests to PostgreSQL. What should you implement?
Answer: A
Explanation:
To improve throughput for highly concurrent application requests in this architecture, you should implement connection pooling.
PostgreSQL follows a process-based architecture where each client connection spawns a separate backend process. This consumes significant memory and CPU overhead during high concurrency. Connection pooling (using tools like PgBouncer or Azure's built-in pooler) allows containerized microservices to reuse a fixed set of database connections. This drastically reduces connection overhead, prevents database exhaustion, and maximizes throughput for short, rapid API queries like vector similarity searches.
Reference:
https://medium.com/@srajanpathak45/a-principal-engineers-guide-to-postgresql-and-modern-alternatives-e8920fd6269a
NEW QUESTION # 132
You are developing a Java application to be deployed in Azure. The application stores sensitive data in Azure Cosmos DB.
You need to configure Always Encrypted to encrypt the sensitive data inside the application.
What should you do first?
Answer: C
Explanation:
To configure Always Encrypted (client-side encryption) for your Java application using Azure Cosmos DB, you must first create a customer-managed key (CMK) and store it in a new Azure Key Vault instance Reference:
https://lennilobel.wordpress.com/2022/08/20/configuring-client-side-encryption-aka-always-encrypted-in-azure-cosmos-db/
NEW QUESTION # 133
You need to implement the semantic retrieval workflow for the recommendation engine to meet the technical and performance requirements of Fabrikam Inc.
Which four actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.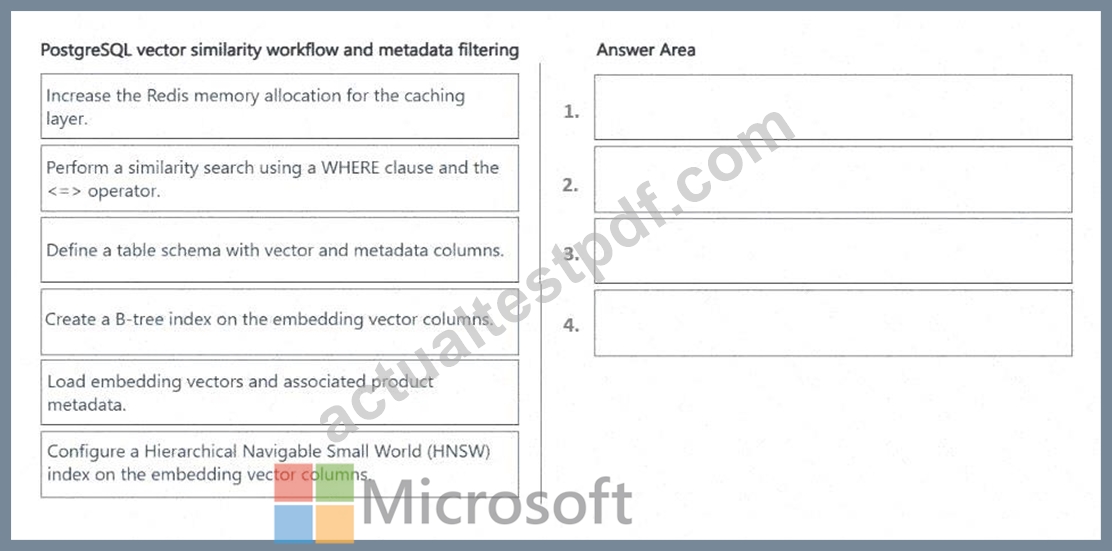
Answer:
Explanation: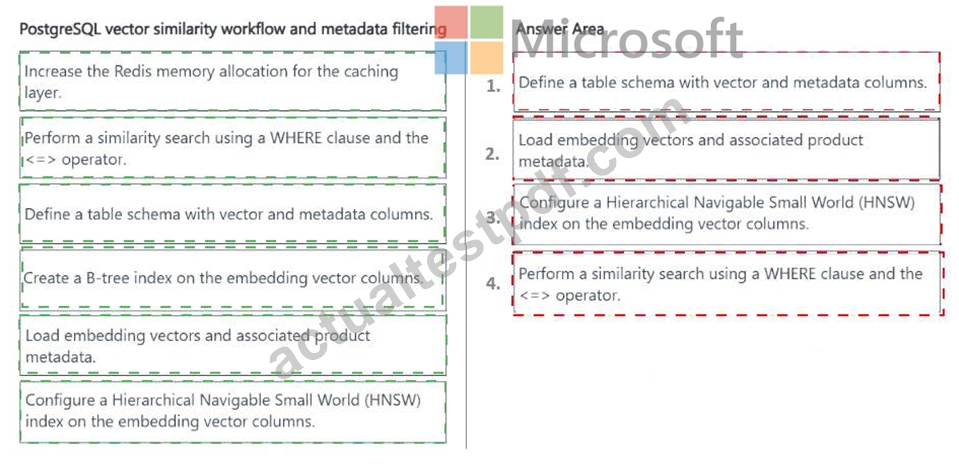
Explanation:
* Define a table schema with vector and metadata columns.
* Load embedding vectors and associated product metadata.
* Configure a Hierarchical Navigable Small World (HNSW) index on the embedding vector columns.
* Perform a similarity search using a WHERE clause and the < = > operator.
The workflow must first establish a PostgreSQL schema containing both the pgvector embedding column and the product metadata required for filtering. The embeddings and their associated metadata are then bulk- loaded. This ordering is important because Microsoft recommends loading data before creating vector indexes ; creating the index afterward provides faster ingestion and a more optimal index layout.
After loading, configure an HNSW index on the embedding column. HNSW is an approximate-nearest- neighbor index supported by pgvector and provides a strong speed/recall tradeoff for low-latency vector retrieval. Microsoft specifically documents HNSW for efficient cosine-distance searches in Azure Database for PostgreSQL.
Finally, execute the retrieval query so that mandatory product metadata constraints are applied through a WHERE clause , while vector similarity is evaluated with the < = > cosine-distance operator . This satisfies Fabrikam ' s requirement to calculate similarity only for eligible products.
A B-tree index is not an ANN vector index, and increasing Redis memory does not implement PostgreSQL semantic retrieval.
Study Guide references: Azure Database for PostgreSQL # pgvector, HNSW indexing, bulk-load optimization, vector similarity operators, metadata-filtered retrieval.
NEW QUESTION # 134
Case Study 2 - Proseware Inc.
Background
Proseware Inc. develops AI-powered knowledge management solutions for enterprise customers.
The company is modernizing its platform to support semantic search, intelligent document retrieval, and real-time partner integrations.
The engineering team uses Python and Azure SDKs. The architecture is being redesigned to support containerized microservices, vector search workloads, and serverless backend processing.
Planned Application Architecture
Microservices are containerized by using Docker.
Code for containerized microservices and Azure Function apps is developed locally but stored in a GitHub repository.
Custom images for containerized microservices are stored in Azure Container Registry (ACR).
Base images are stored in Docker Hub. Custom images must be rebuilt automatically whenever their base images are updated.
Azure Cosmos DB for NoSQL stores documents, metadata, and vector embeddings.
Azure Functions generate vector embeddings of Azure Cosmos DB for NoSQL-hosted documents and send messages to Service Bus to trigger search index updates.
Azure Container Apps (ACA) apps host backend API services that provide semantic search across Azure Cosmos DB for NoSQL documents. API services process Service Bus messages and update search indexes.
Azure Kubernetes Service (AKS) processes batch vector embedding regeneration for existing Azure Cosmos DB for NoSQL documents (whenever the embedding model is changed).
An extranet-facing containerized webhook allows business partners to submit documents to be processed by internal AI workflows for semantic search and retrieval.
Monitoring
Telemetry generated by Azure resources is sent to Azure Monitor.
A Log Analytics workspace is used to collect ACA apps logs, AKS container logs, and Azure Functions apps logs.
Monitoring of Azure Functions is currently implemented by using Azure Application Insights SDK instrumentation.
Business Requirements
Embeddings for new or updated Azure Cosmos DB for NoSQL-hosted documents must be automatically generated.
Backend API services must scale automatically during business hours.
Cold start delay of backend APIs must be minimized.
Secrets must be stored outside of container images.
Developers must be able to correlate telemetry across Azure Functions hosts and apps.
All tracing must be implemented by using OpenTelemetry SDK instrumentation.
Development efforts must be minimized.
Technical Requirements
Container images must be built automatically and validated before code updates are merged into the main branch.
Image build automation must run inside the Azure Container Registry, eliminating dependency on local developer machines and external build services.
Dependency of image builds on local developer machines must be eliminated.
Event-driven scaling in ACA must occur based on the number of pending messages in the Azure Service Bus queue.
Azure Cosmos DB for NoSQL RU consumption must be minimized.
Vector similarity search must use embeddings stored in Azure Cosmos DB for NoSQL.
The partner-facing containerized webhook service must run on Azure App Service.
Secrets must NOT be stored in container images, source control, or application configuration directly. They must be accessed securely at runtime.
All secrets must be stored centrally in Azure Key Vault and accessed at runtime through a managed identity.
Azure App Service must supply secrets at runtime without relying on external services.
Resources and workloads must be deployed by using Bicep templates through an automated, version-controlled pipeline. Local and command-line deployments must be eliminated to ensure repeatable, auditable deployments.
Known Issues
RU consumption spikes during vector similarity queries.
Drag and Drop Question
You need to configure event-driven scaling for the backend API services to meet the technical requirements.
Which settings should you use for each element? To answer, move the appropriate settings to the correct elements. You may use each setting once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.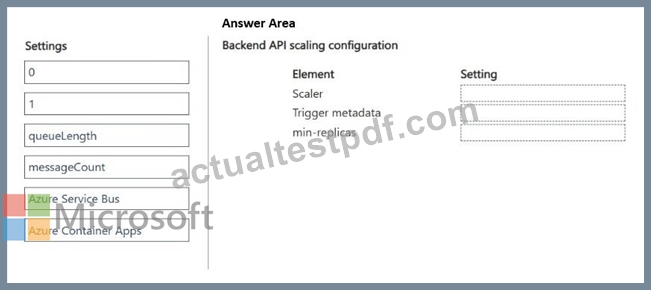
Answer:
Explanation: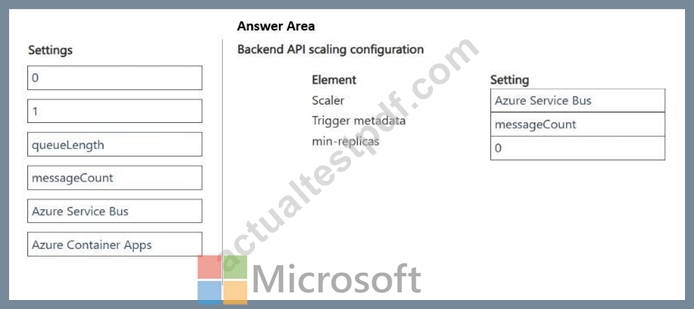
Explanation:
Scenario, technical requirements.
Event-driven scaling in ACA must occur based on the number of pending messages in the Azure Service Bus queue.
Box 1: Azure Service Bus
Scaler TypeType
Set the scale rule type to custom.
KEDA Scaler Name: Set the type inside the custom specification block to azure-service-bus.
Box 2: messageCount
Trigger Metadata Values
The metadata block dictates how KEDA calculates the required replica count.
Configure the following core metadata parameters:
queueName: The explicit string name of your targeted Azure Service Bus
*-> queue.messageCount: The target integer threshold of concurrent pending messages assigned per replica (e.g., 5 or 10). KEDA uses this value to scale out systematically.
activationMessageCount: Set to 1 or 0. This defines the exact metric floor required to transition the container app out of a dormant state.
namespace: The canonical name of your Service Bus namespace
Box 3: 0
Min-Replicas ConfigurationValue
Set --min-replicas to 0.
Setting this value to zero enables full serverless cost efficiency. KEDA actively handles the background polling, allowing your backend API containers to scale down completely and run zero active replicas when the Service Bus queue contains zero pending messages.
Reference:
https://oneuptime.com/blog/post/2026-02-16-how-to-set-up-keda-based-auto-scaling-with-queue-triggers-in-azure-container-apps/view
NEW QUESTION # 135
Hotspot Question
You plan to configure an Event Grid subscription for AI inference events.
The solution must:
- Filter events by payload data.
- Retain undelivered events.
- Limit retry attempts.
You need to configure the Event Grid.
Which configurations should you use? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.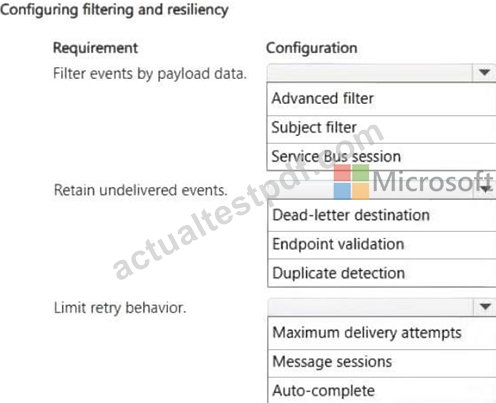
Answer:
Explanation: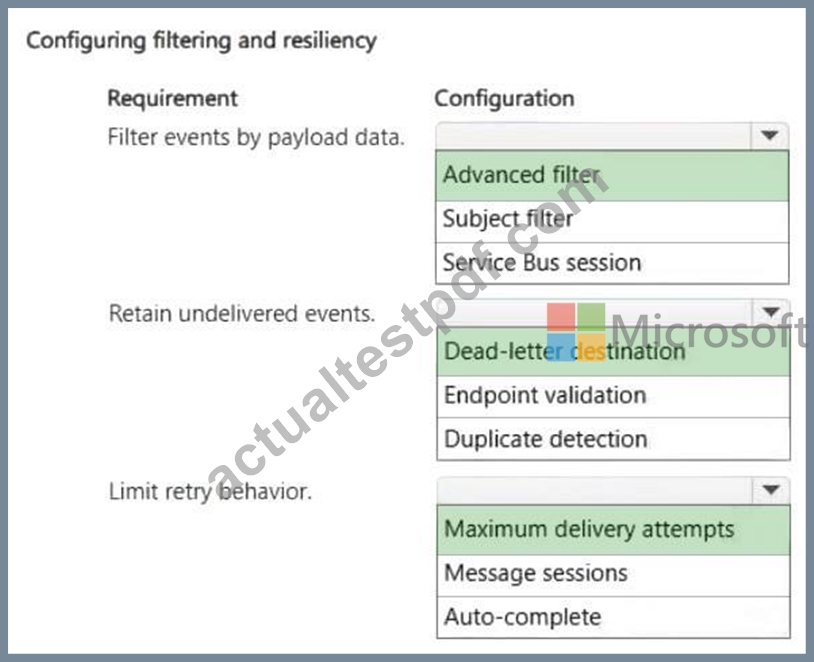
Explanation:
Box 1: Advanced filter
You must use an Advanced filter to filter Azure Event Grid events by payload data.
Payload-level access: Advanced filters allow you to filter on fields within the data object of the event schema, which contains the specific payload of your AI inference event.
Complex operators: It supports advanced comparisons like StringContains, NumberGreaterThan, or BoolEquals against specific JSON payload paths.
Box 2: Dead-letter destination
You should use a dead-letter destination because it is the native Azure mechanism designed to retain undelivered events when delivery attempts fail or are dropped.
Purpose: Captures events that cannot be delivered to your AI inference endpoint due to errors, timeouts, or bad payloads.
Storage Requirement: Requires an Azure Storage account container to securely hold the undelivered message blobs.
Retention Policy: Events stored in the dead-letter container are retained for 14 days by default, giving you time to investigate.
Box 3: Maximum delivery attempts
Maximum delivery attempts is the feature to use to limit retry attempts in an Event Grid subscription.
Use this setting to set a hard cap on how many times Event Grid tries to send an event. You can lower this number from the default value to stop retrying sooner.
Reference:
https://learn.microsoft.com/en-us/azure/data-manager-for-agri/how-to-use-events
https://learn.microsoft.com/en-us/azure/event-grid/subscriber-operations
NEW QUESTION # 136
......
Latest AI-200 exam torrent contains examples and diagrams to illustrate points and necessary notes under difficult points. Remember and practice what AI-200 quiz guides contain will be enough to cope with the exam this time. When dealing with the similar exam in this area, our former customers order the second even the third time with compulsion and confidence. That can be all ascribed to the efficiency of our AI-200 Quiz guides. On our word of honor, these AI-200 test prep will help you who are devoid of efficient practice materials urgently.
Reliable AI-200 Practice Questions: https://www.actualtestpdf.com/Microsoft/AI-200-practice-exam-dumps.html