What's more, part of that GuideTorrent SPS-C01 dumps now are free: https://drive.google.com/open?id=1P-d263QkU8SSQNc4gqY2JTJZp00tCPmz
Our SPS-C01 learning guide is very efficient tool in the world. As is known to us, in our modern world, everyone is looking for to do things faster, better, smarter, so it is no wonder that productivity hacks are incredibly popular. So we must be aware of the importance of the study tool. In order to promote the learning efficiency of our customers, our SPS-C01 Training Materials were designed by a lot of experts from our company. Our SPS-C01 study materials will be very useful for all people to improve their learning efficiency.
| Section | Weight | Objectives |
|---|---|---|
| Snowpark Concepts and Architecture | 25% | - Session management and connection
|
| Performance and Best Practices | 10% | - Optimization techniques
|
| Snowpark API and Development | 30% | - Python API fundamentals
|
| Data Transformations and Operations | 35% | - DataFrame manipulation
|
>> Reliable SPS-C01 Braindumps Ebook <<
We all have same experiences that some excellent people around us further their study and never stop their pace even though they have done great job in their surrounding environment. So it is of great importance to make yourself competitive as much as possible. Facing the SPS-C01 exam this time, your rooted stressful mind of the exam can be eliminated after getting help from our SPS-C01 practice materials. They do not let go even the tenuous points about the SPS-C01 exam as long as they are helpful and related to the exam. And let go those opaque technicalities which are useless and hard to understand, which means whether you are newbie or experienced exam candidate of this area, you can use our SPS-C01 real questions with ease.
NEW QUESTION # 144
Given a Snowpark DataFrame 'employees_df with columns 'employee_id' , 'department' , and 'salary' , and a second Snowpark DataFrame 'departments_df with columns 'department_id' and which of the following Snowpark code snippets correctly performs a join to retrieve employee information along with their department name, filtering for employees with salaries greater than $60,000, and then orders the result by department name?





Answer: A
Explanation:
Explanation:Option E first filters the 'employees_df for salaries greater than $60,000, then joins with 'departments_df using the appropriate join condition (employee.department = department.department_id), and finally orders the result by department name. Using instead of and instead of also acceptable syntax. It's more efficient to filter before joining, so E is better than D, and more importantly E and D work correctly. The other options will throw an error.
NEW QUESTION # 145
You are tasked with optimizing a Snowpark application that uses a Python UDF to perform complex string manipulations on a large dataset. The current implementation uses a scalar UDF. You are considering converting it to a vectorized UDF. What are the key considerations and potential limitations you need to address during the conversion to ensure correctness and optimal performance? Choose all that apply:
Answer: B,C,E
Explanation:
A, B, and C are all crucial considerations. Vectorized UDFs need to handle NULLs, leverage efficient array processing libraries (while respecting package limitations), and maintain type compatibility and consistent array lengths. D is incorrect, as the performance benefit depends on the workload. For very small datasets or simple operations, the overhead of vectorization might outweigh the benefits. E is partially true. Data type compatability is needed, however, you can cast data type to ensure compatibility.
NEW QUESTION # 146
You are building a Snowpark application that uses a Python UDF to perform sentiment analysis on customer reviews. The UDF relies on a large pre-trained machine learning model loaded from a file. During execution, you encounter 'Out of Memory' errors within the UDF. Considering the constraints of the Snowpark execution environment and the need to optimize resource usage, which of the following steps is the MOST effective in addressing this issue and ensuring the application's stability and performance?
Answer: A,B
Explanation:
Lazy loading can reduce initial memory footprint of the UDF. Further, the first time when model is requested, it will be loaded in the UDF and cached for subsequent calls. This avoids reloading the same model again and again. Optimizing the model can reduce the memory footprint of the model to the point it no longer causes out of memory issues. Increasing warehouse size may help but won't address the underlying issue. Breaking down the reviews doesn't solve the memory issue within each batch. Stored procedures do not necessarily have more memory allocated than UDFs.
NEW QUESTION # 147
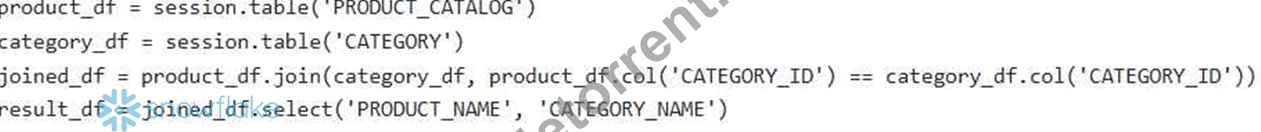
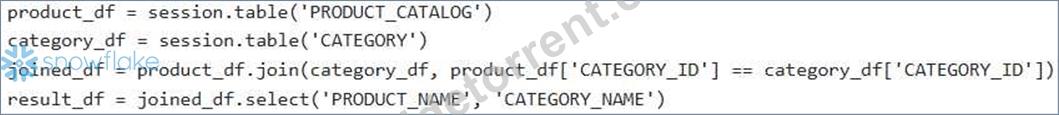
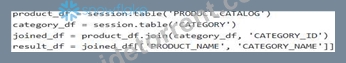
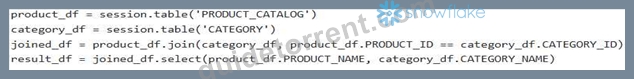
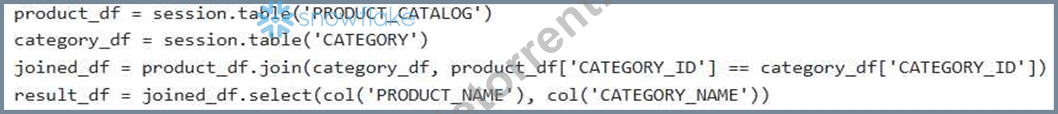
You have a Snowflake table 'PRODUCT CATALOG' with columns 'PRODUCT ID, 'PRODUCT NAME, and 'CATEGORY ID. You also have a table 'CATEGORY' with 'CATEGORY ID' and 'CATEGORY NAME. You need to create a Snowpark DataFrame that joins these two tables and includes only 'PRODUCT NAME and 'CATEGORY NAME. Assume a Snowpark Session object named 'session' is available. Which code snippet demonstrates creating the DataFrame using Snowpark's join functionality and column selection while using the 'table' method?
Answer: E
Explanation:
Option D correctly joins the tables using the 'join' method with a column expression specifying the join condition. It also correctly selects only the desired columns using and option A incorrectly uses 'PRODUCT_ID instead of for the join and needs 'col()' to reference columns. option B selects 'PRODUCT_NAME', 'CATEGORY_NAME' without using 'col(Y which will cause an error since the join brings duplicate column names from product_df and category_df. Option C uses Pythonic '[['PRODUCT_NAME', 'CATEGORY_NAME'I]' which only works on Pandas dataframes. option E attempts to use col() to reference the columns in the join condition which is incorrect as it is a column expression needs to use fully qualified table name for the same named column in two dataframes; moreover selection is missing col().
NEW QUESTION # 148
You are developing a Snowpark Python application that reads data from an external stage (AWS S3) and performs several transformations before loading it into a Snowflake table. During testing, you encounter the following error: net.snowflake.client.jdbc.SnowflakeSQLException: SQL compilation error: User does not have OWNERSHIP privilege on integration object 'YOUR INTEGRATION NAME". You have confirmed that the user has the 'USAGE privilege on the integration. Besides granting ownership, which of the following actions could resolve this issue in the MOST secure and efficient way?
Answer: A
Explanation:
Option B is the MOST secure and efficient. The error indicates that the user lacks necessary privileges to utilize the integration for creating objects (in this case, likely an internal stage used during the transformation process). Granting a custom role with both 'USAGE on the integration and 'CREATE TABLE on the database adheres to the principle of least privilege. Option A grants broad privileges to the user, which is less secure. Option C involves complex integration setup and might not be necessary for a simple data loading scenario. Option D is related to reading data from the external stage, not using the integration for internal operations. Option E bypasses the error without addressing the underlying permission issue.
NEW QUESTION # 149
......
Therefore, you have the option to use Snowflake SPS-C01 PDF questions anywhere and anytime. GuideTorrent Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) dumps are designed according to the Snowflake SPS-C01 certification exam standard and have hundreds of questions similar to the actual Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) exam. Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) web-based practice exam software also works without installation.
Exam SPS-C01 Success: https://www.guidetorrent.com/SPS-C01-pdf-free-download.html
BONUS!!! Download part of GuideTorrent SPS-C01 dumps for free: https://drive.google.com/open?id=1P-d263QkU8SSQNc4gqY2JTJZp00tCPmz