2026 Latest PrepAwayPDF SPS-C01 PDF Dumps and SPS-C01 Exam Engine Free Share: https://drive.google.com/open?id=1D3Qp9rD0YGXsBMWlgR1PSwgcsr6eoWka
At present, many office workers are dedicated to improving themselves. Most of them make use of their spare time to study our SPS-C01 study materials. As you can see, it is important to update your skills in company. After all, the most outstanding worker can get promotion. You also need to plan for your future. Getting the SPS-C01 Study Materials will enhance your ability. Also, various good jobs are waiting for you choose. Your life will become wonderful if you accept our guidance.
| Section | Weight | Objectives |
|---|---|---|
| Data Transformations and Operations | 35% | - DataFrame manipulation
|
| Performance and Best Practices | 10% | - Security and governance
|
| Snowpark API and Development | 30% | - Python API fundamentals
|
| Snowpark Concepts and Architecture | 25% | - Session management and connection
|
>> Reliable SPS-C01 Test Cram <<
After you pay for our SPS-C01 exam material online, you will get the link to download it in only 5 to 10 minutes. You don't have to wait a long time to start your preparation for the SPS-C01 exam. And if we have a new version of your SPS-C01 Study Guide, we will send an E-mail to you. Whenever you have questions about our SPS-C01 learning quiz, you are welcome to contact us via E-mail. We sincerely offer you 24/7 online service.
NEW QUESTION # 342
You're developing a Snowpark Python application to process log files stored in an external stage 's3_logs'. These logs are in plain text, with each line representing a log entry. You need to filter log entries based on a specific keyword and extract timestamps from the matching lines. Which of the following approaches, using and Snowpark DataFrames, will efficiently accomplish this, avoiding unnecessary data transfer to the client?
Answer: B
Explanation:
Option E provides the most efficient solution. By using 'session.read.option('PATTERN', ' you load the data directly into a DataFrame within Snowflake. A UDTF (User-Defined Table Function) is then used to process each partition of the DataFrame, performing the filtering and timestamp extraction in parallel within the Snowflake environment, minimizing data transfer to the client. Option A is highly inefficient as it downloads all files to the client. Option B is less efficient than E because it processes all rows through a single UDF instead of distributed processing using UDTF. It also assumes all log data can be held in a single dataframe which can create memory issues Option C is similar to B and it uses UDF instead of UDTF making it less efficient. Option D introduces external dependencies to the solution.
NEW QUESTION # 343
You have developed a Snowpark application that processes a large volume of customer interaction data'. The application uses a vectorized UDF to classify the sentiment of text-based interactions. Initial tests show the application is performing slowly. Which of the following strategies would be MOST effective for optimizing the performance of sentiment analysis using a vectorized UDF?
Answer: C
Explanation:
Optimizing the vectorized UDF code itself offers the most direct and significant performance gains for sentiment analysis. By streamlining computations, reducing memory allocations, and avoiding unnecessary function calls within the UDF's vectorized function, the processing time for each batch of data can be substantially reduced. Mini-batching (B) is already implicit with vectorization with pandas series/dataframe. Increaseing Number of cores allocated to the virtual warehouse can provide some help but it depends on other factor also. Other oprions may not have impact
NEW QUESTION # 344
You have a Snowpark DataFrame named 'sales df containing sales data for different products. The DataFrame includes columns product_id' (INTEGER), 'sale_date' (DATE), 'quantity' (INTEGER), and 'price' (FLOAT). You need to calculate the total revenue for each product on a monthly basis and store the result in a new DataFrame named Which of the following Snowpark code snippets will correctly achieve this, while maximizing performance and minimizing data shuffling?
Answer: B
Explanation:
Option B is the most efficient because 'date_trunc('MM', ...y truncates the date to the beginning of the month, allowing for proper grouping and aggregation without unnecessary string conversions or data shuffling. The 'date_trunc' function leverages Snowflake's internal date functions for optimal performance. Other options either use string representations of dates or date parts, which can lead to less efficient grouping.
NEW QUESTION # 345
You have a Pandas DataFrame named containing employee information including 'name' , 'department, and You want to create a Snowpark DataFrame named from this Pandas DataFrame and register it as a temporary view named 'TEMP EMPLOYEES. However, you need to ensure that any NULL values in the Pandas DataFrame are handled correctly when creating the Snowpark DataFrame. Which of the following code snippets achieves this, minimizes data transfer and provides best performance considering dataset size is large?





Answer: E
Explanation:
Using 'session.write_pandas' with is most efficient for large datasets. It leverages internal optimization within Snowflake for transferring data from Pandas DataFrames, and creating the temporary view directly avoids intermediate steps. Options A, C, and D create Snowpark DataFrames in memory first before potentially creating a temporary view, which is less optimized. Option B creates a permanent table not a temp view.
NEW QUESTION # 346
You have a Snowpark DataFrame 'df sales' containing sales data with columns like 'order id', 'product id', 'quantity', and 'sale_price' You want to persist this data into a Snowflake table named "SALES DATA'. You also want to create a dynamic table on top of this base table for faster analytics. You need to choose the appropriate persistence strategy and consider the implications of using a dynamic table. Which of the following options represents the BEST approach?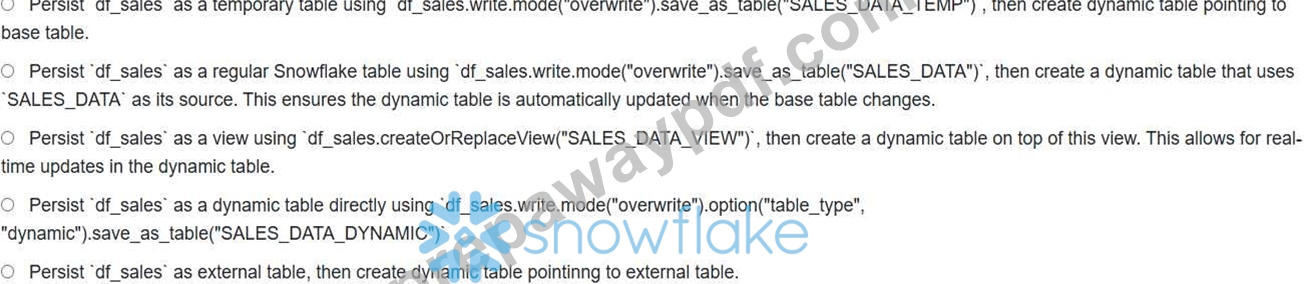
Answer: D
Explanation:
Option B is the best approach because it combines the advantages of persistence with the benefits of dynamic tables. Regular Table Persistence: Persisting as a regular table using DATA") ensures the data is stored durably in Snowflake. This serves as the foundation for the dynamic table. Dynamic Table Creation: Creating a dynamic table that uses 'SALES DATA' as its source provides a materialized view that automatically updates when the base table changes. This allows for faster analytics as the data is pre-computed and optimized for querying. Avoidance of Temporary Tables: Option A uses a temporary table, which is not suitable for long-term storage or scenarios where the data needs to persist beyond the session. Views vs. Dynamic Tables: Option C uses a view, which is not materialized. While views provide real-time access to the data, they can be slower for complex queries compared to dynamic tables. Option D isn't correct as 'table_type' is not a valid option for in Snowpark. Option E isnt valid scenario
NEW QUESTION # 347
......
It can be said that all the content of the SPS-C01 study materials are from the experts in the field of masterpieces, and these are understandable and easy to remember, so users do not have to spend a lot of time to remember and learn. It takes only a little practice on a daily basis to get the desired results. Especially in the face of some difficult problems, the user does not need to worry too much, just learn the SPS-C01 Study Materials provide questions and answers, you can simply pass the exam. This is a wise choice, and in the near future, after using our SPS-C01 training materials, you will realize your dream of a promotion and a raise, because your pay is worth the rewards.
SPS-C01 Exam Course: https://www.prepawaypdf.com/Snowflake/SPS-C01-practice-exam-dumps.html
P.S. Free & New SPS-C01 dumps are available on Google Drive shared by PrepAwayPDF: https://drive.google.com/open?id=1D3Qp9rD0YGXsBMWlgR1PSwgcsr6eoWka