Someone always asks: Why do we need so many certifications? One thing has to admit, more and more certifications you own, it may bring you more opportunities to obtain better job, earn more salary. This is the reason that we need to recognize the importance of getting the test DP-750 certifications. More qualified certification for our future employment has the effect to be reckoned with, only to have enough qualification certifications to prove their ability, can we win over rivals in the social competition. Therefore, the DP-750 Guide Torrent can help users pass the qualifying examinations that they are required to participate in faster and more efficiently.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Configure and manage Azure Databricks environments | 15-20% | - Security and authentication setup
|
| Topic 2: Deploy and manage data pipelines and workloads | 30-35% | - Operational reliability
|
| Topic 3: Prepare and process data | 30-35% | - Data transformation and modeling
|
| Topic 4: Secure and govern data using Unity Catalog | 15-20% | - Access control and policies
|
It is a truth well-known to all around the world that no pains and no gains. There is another proverb that the more you plough the more you gain. When you pass the DP-750 exam which is well recognized wherever you are in any field, then acquire the DP-750 certificate, the door of your new career will be open for you and your future is bright and hopeful. Our DP-750 guide torrent will be your best assistant to help you gain your DP-750 certificate.
NEW QUESTION # 13
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a Delta table named Orders.
You load the Orders table into an Apache Spark DataFrame named df.
You need to create a DataFrame that excludes rows where the order amount is null.
Solution: You run the following expression.
df.filter(df.order_amount.isNotNull())
Does this meet the goal?
Answer: B
Explanation:
The correct answer is A - Yes.
df.filter(df.order_amount.isNotNull()) is the correct PySpark pattern for excluding null rows. The isNotNull() method is a Column method that returns True for every row where order_amount has a value and False for rows where it is null. Spark's filter keeps only the rows where the condition evaluates to True, producing a DataFrame with all null order_amount rows removed.
This works correctly because isNotNull() is explicitly null-aware - unlike the != None comparison in Q52, it doesn't rely on Python equality semantics. Under the hood it maps to the SQL expression order_amount IS NOT NULL, which is unambiguous in both SQL and Spark.
Both df.filter(df.order_amount.isNotNull()) and df.dropna(subset=['order_amount']) produce identical results.
The choice between them is stylistic - isNotNull() reads more explicitly as a filter condition, while dropna is more compact when handling multiple columns.
Reference: https://learn.microsoft.com/en-us/azure/databricks/pyspark/basics
NEW QUESTION # 14
You have an Azure Databricks workspace that contains a Git folder and uses Azure Repos as the Git provider.
From the main branch, you create a branch named Branch1. You commit changes to Branch1.
You need to incorporate the changes from Branch1 into main The solution must preserve the commit history in the repository. Which command should you run?
Answer: D
Explanation:
The correct answer is A - merge.
A Git merge combines the histories of two branches by creating a merge commit that joins them. Every individual commit from Branch1 remains visible in the repository log - the full development history is preserved. This is the requirement: 'the solution must preserve the commit history in the repository.' Option C (rebase) moves Branch1's commits on top of main by replaying them as new commits with new hashes. The end result looks like a linear history, but the original commit hashes are rewritten - the prior history is not preserved in its original form. For a shared repository, rebase rewrites public history, which is considered problematic.
Option B (pull) fetches remote changes and merges or rebases them into the current branch - it's used to sync with a remote, not to incorporate a feature branch. Option D (push) sends local commits to the remote but doesn't incorporate any branch into another.
Reference: https://learn.microsoft.com/en-us/azure/databricks/repos/git-operations-with-repos
NEW QUESTION # 15
You have an Azure Databricks workspace that is enabled for Unity Catalog You have an Apache Spark Structured Streaming job that writes data to a Delta table.
After the cluster restarts, the streaming job reprocesses previously ingested data You need to prevent the streaming job from reprocessing the data after the cluster restarts.
What should you do?
Answer: D
Explanation:
The correct answer is B - configure a checkpoint location.
A checkpoint is the Structured Streaming mechanism for fault tolerance. Databricks writes the committed offset (i.e., how far through the source stream the job has successfully read and processed) to a durable path in ADLS Gen2 or DBFS after each micro-batch. When the cluster restarts, the engine reads that offset and resumes from the next unprocessed record - nothing is reprocessed, nothing is skipped.
Option A (increase trigger interval) affects how frequently micro-batches run but does nothing to record progress between runs. Option C (watermark) handles late-arriving events in event-time windows but doesn't control source offset tracking. Option D (enable CDF on the target table) tracks changes made to a Delta table for downstream consumers - it has no bearing on the streaming job's own fault tolerance or offset management.
Checkpointing is a required configuration for any production streaming job. Without it, every cluster restart triggers a full replay from the source.
Reference: https://learn.microsoft.com/en-us/azure/databricks/structured-streaming/query-recovery
NEW QUESTION # 16
You have an Azure Databricks workspace that contains multiple all-purpose clusters. You discover that some clusters remain idle for long periods after users finish their work. You need to reduce compute costs without affecting active workloads. What should you do?
Answer: C
Explanation:
The correct answer is D - configure automatic termination.
The problem is specific: clusters sit idle after users finish working but nobody manually shuts them down.
Automatic termination solves this directly - once a cluster has been idle for the configured period (no running commands, no attached notebooks with active execution), it shuts itself down. You eliminate the idle cost without any manual intervention and without affecting any workload that is actually running.
Option A (convert to job clusters) would force users off interactive all-purpose clusters, disrupting their development workflow. Option B (spot instances) reduces the hourly rate while a cluster is running but does nothing about the idle-time problem - a cheaper idle cluster is still waste. Option C (enable autoscaling) reduces the number of workers during light load but keeps the cluster alive at the minimum node count. It saves some cost but doesn't fully eliminate idle spend the way auto-termination does.
Reference: https://learn.microsoft.com/en-us/azure/databricks/compute/configure#auto-termination
NEW QUESTION # 17
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You need to create an external volume named Volume1 in an existing schema. Volume1 must expose files from an Azure Storage container. The solution must meet the following requirements:
* Ensure that authentication does NOT require storing credentials in Databricks
* Ensure that users can access the files, but NOT modify the files.
* Follow the principle of least privilege
Which type of authentication should you configure, and which permission should you grant to the users? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.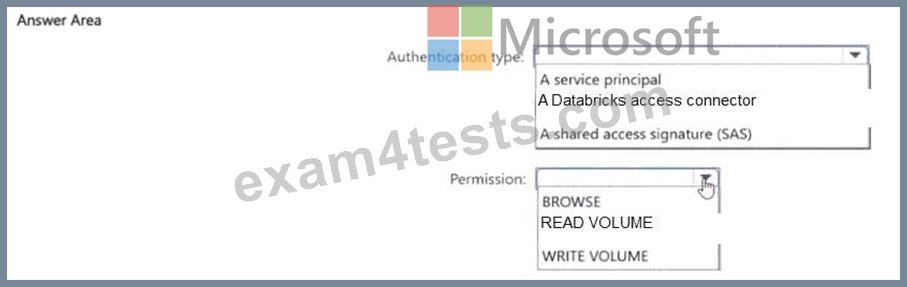
Answer:
Explanation: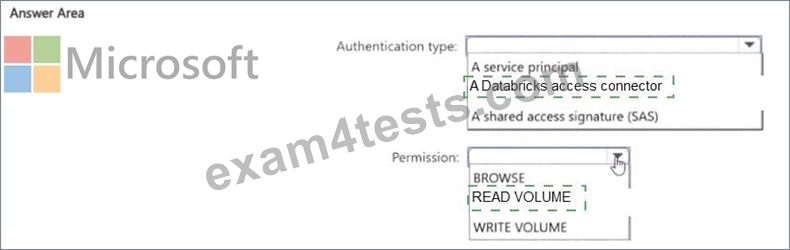
Explanation:
For authentication, a Managed Identity (via a Databricks Access Connector) is the right choice. The Access Connector wraps an Azure-managed identity so Databricks can authenticate to Azure Storage without any credentials being stored in the workspace. The cloud security team controls the identity through Azure RBAC
- there are no secrets to rotate or leak inside Databricks.
For the permission, READ FILES on the volume is exactly right. It allows users to read and list files through the volume path while blocking writes, deletes, and modifications. This is the minimum necessary access, honouring the principle of least privilege.
WRITE FILES would allow modifications, contradicting 'users can access but NOT modify.' ALL PRIVILEGES grants far more than needed. Service principals with stored client secrets would mean credentials inside Databricks, violating the 'does not require storing credentials' requirement.
Reference: https://learn.microsoft.com/en-us/azure/databricks/connect/unity-catalog/volumes
NEW QUESTION # 18
......
You can imagine that you just need to pay a little money for our DP-750 exam prep, what you acquire is priceless. So it equals that you have made a worthwhile investment. Firstly, you will learn many useful knowledge and skills from our DP-750 Exam Guide, which is a valuable asset in your life. After all, no one can steal your knowledge. In addition, you can get the valuable DP-750 certificate.
Free DP-750 Learning Cram: https://www.exam4tests.com/DP-750-valid-braindumps.html