
2026 Latest DumpsMaterials MLA-C01 PDF Dumps and MLA-C01 Exam Engine Free Share: https://drive.google.com/open?id=1Nef1c3ISAqffKqPi901tHzTuzt0YvKRp
Why we can produce the best MLA-C01 exam prep and can get so much praise in the international market. On the one hand, the software version can simulate the real MLA-C01 examination for you and you can download our study materials on more than one computer with the software version of our study materials. On the other hand, you can finish practicing all the contents in our MLA-C01 practice materials within 20 to 30 hours. So what are you waiting for? Just rush to buy our MLA-C01 exam questions!
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
As the saying goes, an inch of time is an inch of gold; time is money. If time be of all things the most precious, wasting of time must be the greatest prodigality. We believe that you will not want to waste your time, and you must want to pass your MLA-C01 Exam in a short time, so it is necessary for you to choose our AWS Certified Machine Learning Engineer - Associate prep torrent as your study tool. If you use our products, you will just need to spend 20-30 hours to take your exam.
NEW QUESTION # 140
A hospital wants to predict patient outcomes for the coming year An ML engineer must improve several existing ML models that currently perform poorly.
Select the correct regularization method from the following list to improve each model Select each regularization method one time, more than one time, or not at all. (Select THREE.)
* L1 regularization
* L2 regularization
* Early stopping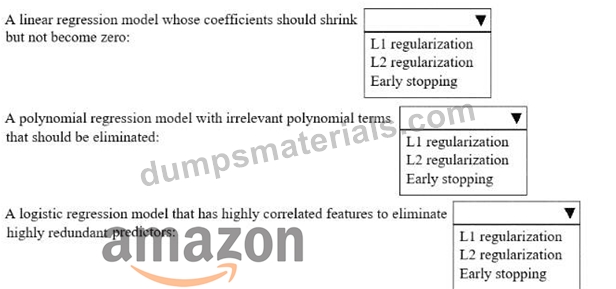
Answer:
Explanation: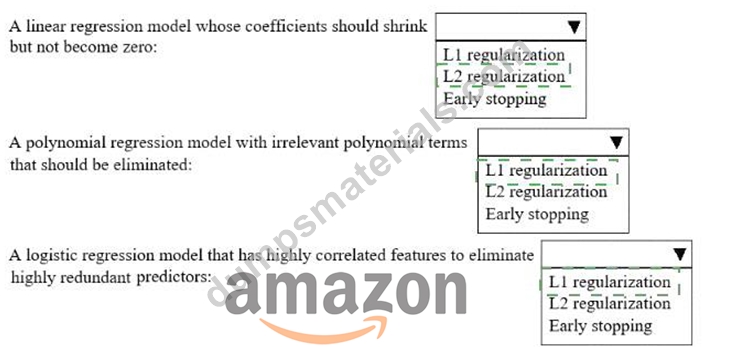
Explanation:
Linear regression model whose coefficients should shrink but not become zero answer: L2 regularization AWS says L2 produces smaller overall weight values and is the right fit when coefficients should be reduced without being forced to zero.
Polynomial regression model with irrelevant polynomial terms that should be eliminated answer: L1 regularization AWS says L1 reduces the number of features used by pushing small weights to zero , which matches elimination of irrelevant terms.
Logistic regression model that has highly correlated features to eliminate highly redundant predictors L1 regularization This is the nuanced one. AWS says L2 stabilizes weights when there is high correlation between features , but because the question explicitly says eliminate highly redundant predictors , L1 is the better match since it creates sparsity and removes predictors by zeroing coefficients.
NEW QUESTION # 141
An ML engineer is working on an ML model to predict the prices of similarly sized homes. The model will base predictions on several features The ML engineer will use the following feature engineering techniques to estimate the prices of the homes:
* Feature splitting
* Logarithmic transformation
* One-hot encoding
* Standardized distribution
Select the correct feature engineering techniques for the following list of features. Each feature engineering technique should be selected one time or not at all (Select three.)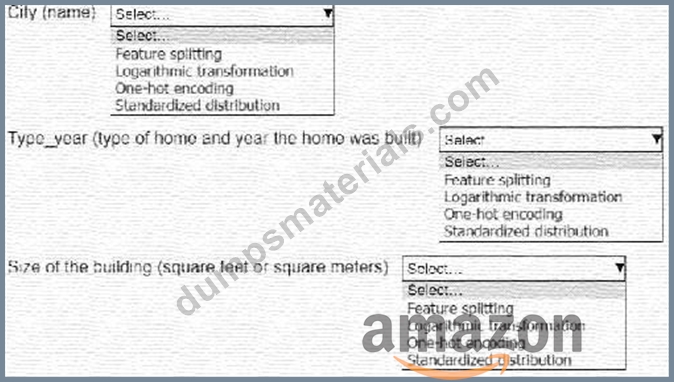
Answer:
Explanation: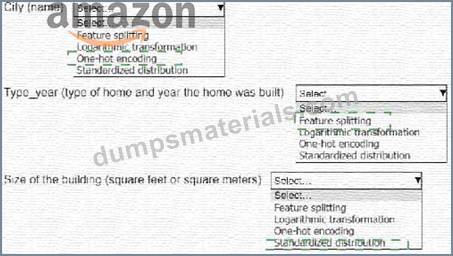
Explanation:
* City (name): One-hot encoding
* Type_year (type of home and year the home was built): Feature splitting
* Size of the building (square feet or square meters): Standardized distribution
* City (name): One-hot encoding
* Why? The "City" is a categorical feature (non-numeric), so one-hot encoding is used to transform it into a numeric format. This encoding creates binary columns for each unique category (e.g., cities like "New York" or "Los Angeles"), which the model can interpret.
* Type_year (type of home and year the home was built): Feature splitting
* Why? "Type_year" combines two pieces of information into one column, which could confuse the model. Feature splitting separates this column into two distinct features: "Type of home" and
"Year built," enabling the model to process each feature independently.
* Size of the building (square feet or square meters): Standardized distribution
* Why? Size is a continuous numerical variable, and standardization (scaling the feature to have a mean of 0 and a standard deviation of 1) ensures that the model treats it fairly compared to other features, avoiding bias from differences in feature scale.
By applying these feature engineering techniques, the ML engineer can ensure that the input data is correctly formatted and optimized for the model to make accurate predictions.
NEW QUESTION # 142
A company runs an Amazon SageMaker domain in a public subnet of a newly created VPC. The network is configured properly, and ML engineers can access the SageMaker domain.
Recently, the company discovered suspicious traffic to the domain from a specific IP address. The company needs to block traffic from the specific IP address.
Which update to the network configuration will meet this requirement?
Answer: A
Explanation:
Network ACLs (Access Control Lists) operate at the subnet level and allow for rules to explicitly deny traffic from specific IP addresses. By creating an inbound rule in the network ACL to deny traffic from the suspicious IP address, the company can block traffic to the Amazon SageMaker domain from that IP. This approach works because network ACLs are evaluated before traffic reaches the security groups, making them effective for blocking traffic at the subnet level.
NEW QUESTION # 143
An airline company deploys ML models to one dozen Amazon SageMaker Al inference endpoints. The inference endpoints must be able to handle different types of workloads in a cost-effective way.
Select the correct inference option from the following list to handle each type of workload. Select each inference option one time. (Select FOUR.)
* Asynchronous inference
* Batch inference
* Real-time inference
* Serverless inference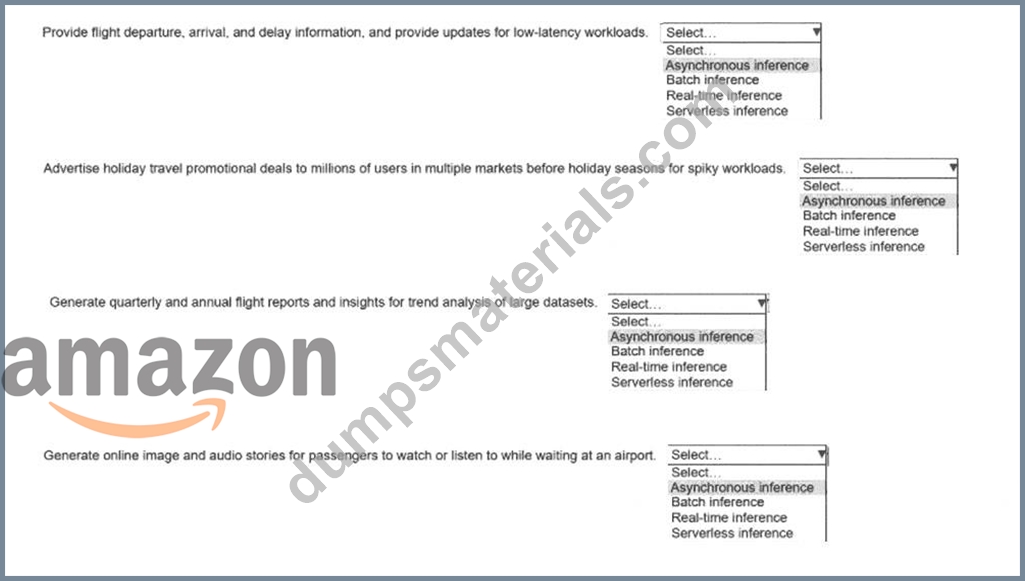
Answer:
Explanation: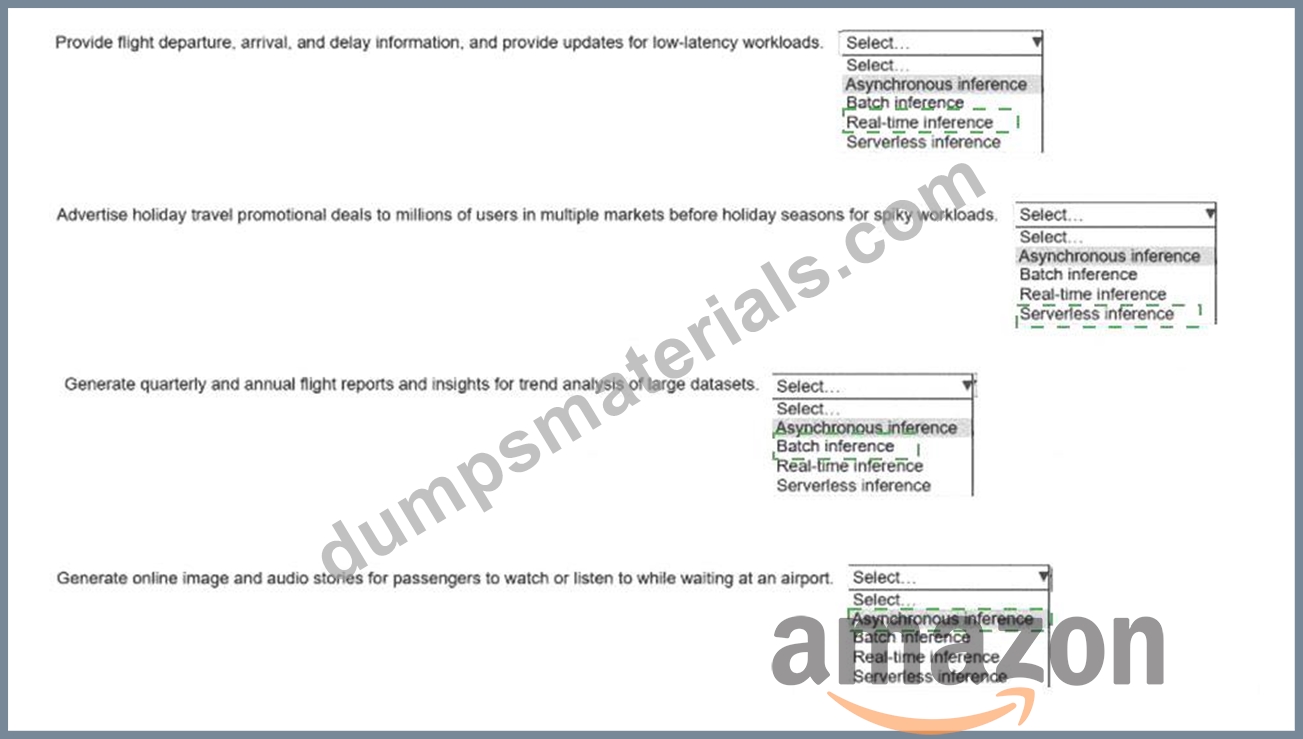
* Provide flight departure, arrival, and delay information, and provide updates for low-latency workloads# Real-time inference
* Advertise holiday travel promotional deals to millions of users in multiple markets before holiday seasons for spiky workloads# Serverless inference
* Generate quarterly and annual flight reports and insights for trend analysis of large datasets# Batch inference
* Generate online image and audio stories for passengers to watch or listen to while waiting at an airport# Asynchronous inference
* The correct mapping depends on latency requirement, traffic pattern, payload size, processing duration, and whether the workload needs a persistent endpoint.
* Real-time inference is the right choice for flight departure, arrival, and delay updates because this is an online user-facing workload that requires low latency. AWS states that SageMaker real-time inference is ideal for online inference workloads with low-latency or high-throughput requirements and uses a persistent fully managed endpoint. That fits flight status information because passengers and airline systems expect immediate responses.
* Serverless inference is the best choice for holiday promotional deals because this traffic is spiky, seasonal, and unpredictable. AWS describes SageMaker Serverless Inference as suitable for intermittent or unpredictable traffic patterns. It is cost-effective because SageMaker manages the infrastructure and scales down when there are no requests, so the company does not pay for idle endpoint capacity.
* Batch inference is correct for quarterly and annual flight reports because this workload analyzes large datasets offline and does not need an always-running endpoint. AWS says SageMaker batch transform is used to get inferences from large datasets and when a persistent endpoint is not required. Reports and trend analysis are scheduled, non-real-time analytics workloads, so batch inference is the most cost- effective option.
* Asynchronous inference is the right choice for generating online image and audio stories. These requests can have larger payloads and longer processing times than normal low-latency API calls. AWS states that SageMaker Asynchronous Inference queues incoming requests and is ideal for large payloads, long processing times, and near-real-time latency requirements. Image and audio generation can take seconds or minutes, so asynchronous inference is more appropriate than real-time inference.
NEW QUESTION # 144
An ML engineer is training a simple neural network model. The ML engineer tracks the performance of the model over time on a validation dataset. The model's performance improves substantially at first and then degrades after a specific number of epochs.
Which solutions will mitigate this problem? (Choose two.)
Answer: D,E
Explanation:
Early stopping halts training once the performance on the validation dataset stops improving. This prevents the model from overfitting, which is likely the cause of performance degradation after a certain number of epochs.
Dropout is a regularization technique that randomly deactivates neurons during training, reducing overfitting by forcing the model to generalize better. Increasing dropout can help mitigate the problem of performance degradation due to overfitting.
NEW QUESTION # 145
......
DumpsMaterials follows its motto to facilitate its consumer by providing them the material to qualify for the Amazon MLA-C01 certification exam with excellence. Therefore, it materializes its mission by giving them free of cost Amazon MLA-C01 demo of the dumps. This practical step taken by the DumpsMaterials will enable its users to assess the quality of the Amazon MLA-C01 dumps.
Valid MLA-C01 Test Sample: https://www.dumpsmaterials.com/MLA-C01-real-torrent.html
DOWNLOAD the newest DumpsMaterials MLA-C01 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1Nef1c3ISAqffKqPi901tHzTuzt0YvKRp