NCP-AIO Frenquent Update | NCP-AIO Exam Topic

DOWNLOAD the newest PremiumVCEDump NCP-AIO PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1HU1_8G4tbLMp_MaBI9Igr1DW-Pw_HvL7
If you are still in colleges, it is a good chance to learn the knowledge of the NCP-AIO study engine because you have much time. At present, many office workers are keen on learning our NCP-AIO guide materials even if they are busy with their work. So you should never give up yourself as long as there has chances. In short, what you have learned on our NCP-AIO study engine will benefit your career development.
| Topic | Details |
|---|
| Topic 1 | - Troubleshooting and Optimization: NVIThis section of the exam measures the skills of AI infrastructure engineers and focuses on diagnosing and resolving technical issues that arise in advanced AI systems. Topics include troubleshooting Docker, the Fabric Manager service for NVIDIA NVlink and NVSwitch systems, Base Command Manager, and Magnum IO components. Candidates must also demonstrate the ability to identify and solve storage performance issues, ensuring optimized performance across AI workloads.
|
| Topic 2 | - Installation and Deployment: This section of the exam measures the skills of system administrators and addresses core practices for installing and deploying infrastructure. Candidates are tested on installing and configuring Base Command Manager, initializing Kubernetes on NVIDIA hosts, and deploying containers from NVIDIA NGC as well as cloud VMI containers. The section also covers understanding storage requirements in AI data centers and deploying DOCA services on DPU Arm processors, ensuring robust setup of AI-driven environments.
|
| Topic 3 | - Administration: This section of the exam measures the skills of system administrators and covers essential tasks in managing AI workloads within data centers. Candidates are expected to understand fleet command, Slurm cluster management, and overall data center architecture specific to AI environments. It also includes knowledge of Base Command Manager (BCM), cluster provisioning, Run.ai administration, and configuration of Multi-Instance GPU (MIG) for both AI and high-performance computing applications.
|
| Topic 4 | - Workload Management: This section of the exam measures the skills of AI infrastructure engineers and focuses on managing workloads effectively in AI environments. It evaluates the ability to administer Kubernetes clusters, maintain workload efficiency, and apply system management tools to troubleshoot operational issues. Emphasis is placed on ensuring that workloads run smoothly across different environments in alignment with NVIDIA technologies.
|
>> NCP-AIO Frenquent Update <<
NCP-AIO Exam Topic | NCP-AIO Valid Dumps Book
Our NCP-AIO test questions can help you have a good preparation for exam effectively. Also you don't need to worry about if our NCP-AIO study materials are out of validity. We provide one year free updates for every buyer, after purchasing you can download our latest version of NCP-AIO Training Questions always within one year. And if you have any question on our NCP-AIO learning guide, you can contact with our service at any time, we will help you pass the NCP-AIO exam with our high quality of NCP-AIO exam questions and good service.
NVIDIA AI Operations Sample Questions (Q36-Q41):
NEW QUESTION # 36
Which of the following storage technologies provides the best support for handling a large number of small files, common in AI datasets (e.g., image datasets)?
- A. Parallel file system (e.g., BeeGFS) designed for high IOPS and low latency.
- B. Traditional block storage (e.g., SAN) with a large block size.
- C. Object storage (e.g., AWS S3) with optimized metadata management.
- D. Network Attached Storage (NAS) using NFS.
- E. Tape storage
Answer: A,C
Explanation:
Object storage systems, especially those optimized for metadata management, are well-suited for storing and accessing large numbers of small files. Parallel file systems are also designed for high IOPS and low latency, making them efficient for handling numerous small file operations. Traditional block storage with a large block size can lead to wasted space. NAS over NFS can become a bottleneck. Tape is unsuitable for frequently accessing data.
NEW QUESTION # 37
Consider the following Kubernetes pod definition:
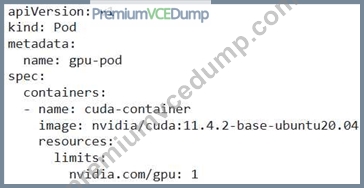
What does the 'nvidia.com/gpu: 1' setting achieve?
- A. It limits the container's GPU memory usage to IGB.
- B. It allocates one full GPU to the container.
- C. It ensures that the pod is scheduled on a node with at least one NVIDIA GPU.
- D. It reserves one virtual GPU (vGPU) instance for the container.
- E. It allows the container to access NVIDIA drivers and libraries.
Answer: B,C,E
Explanation:
The 'nvidia.com/gpu: 1 ' resource request ensures the pod is scheduled on a node with a GPU. It effectively allocates one full GPU to the container (unless using vGPU). It also implicitly provides access to NVIDIA drivers and libraries through the device plugin mechanism. It doesn't directly limit memory usage or reserve vGPU instances; those require additional configurations.
NEW QUESTION # 38
Your team is developing a multi-tenant AI platform on Kubernetes using NVIDIA GPUs provisioned through BCM. Each tenant needs guaranteed access to a fraction of the GPU resources. Which of the following Kubernetes features, in combination with NVIDIA's tools, would be BEST suited for achieving GPU resource isolation and fair sharing among tenants?
- A. Node Affinity combined with Taints and Tolerations to dedicate specific nodes to certain tenants
- B. Resource Quotas and Limit Ranges combined with the NVIDIA Device Plugin's fractional GPU allocation feature (MIG).
- C. Horizontal Pod Autoscaling (HPA) combined with the NVIDIA GPU metrics adapter to automatically scale tenant workloads based on GPU utilization.
- D. Pod Priority and Preemption combined with Resource Quotas to prioritize critical tenant workloads during resource contention.
- E. Network Policies combined with Kubernetes Namespaces to isolate tenant workloads and prevent cross-tenant communication.
Answer: B
Explanation:
Resource Quotas and Limit Ranges enforce resource usage limits on a per-namespace (tenant) basis. The NVIDIA Device Plugin's Multi-lnstance GPU (MIG) feature allows you to partition a single physical GPU into multiple smaller virtual GPUs, enabling fine-grained allocation of GPU resources to tenants. Using them in combination allows for both restriction and isolation on the GPU itself. While network policies and pod priority are useful for overall security and resource management, they don't directly address GPU isolation. HPA is about scaling, not isolation. Node Affinity with Taints/Tolerations helps with node dedication, but alone does not provide GPU isolation within a node.
NEW QUESTION # 39
While monitoring your storage system during a large training job, you notice consistently high disk I/O wait times ('iowait'). What does this metric indicate, and what actions can you take to mitigate it?
- A. High 'iowait' means the system is swapping memory to disk. Add more RAM or reduce memory usage.
- B. High 'iowait' is normal during large training jobs and does not require any action.
- C. High 'iowait' means the CPU is waiting for I/O operations to complete. Increase CPU cores.
- D. High 'iowait' indicates network congestion. Optimize network configuration.
- E. High 'iowait' means the CPU is waiting for I/O operations to complete. Investigate storage performance bottlenecks such as disk saturation, network latency (if using networked storage), or inefficient data access patterns.
Answer: E
Explanation:
'iowait' directly reflects the time the CPU spends idle, waiting for disk I/O operations. The solutions are targetted to identify whether the bottleneck is disk saturation, network latency or inefficient data access patterns.
NEW QUESTION # 40
You are deploying a cloud VMI container and need to choose between different container runtimes (e.g., Docker, containerd, CRI-O).
Which factor is MOST crucial to consider when selecting a container runtime for a GPU-accelerated workload?
- A. The runtime's performance overhead on CPU-bound tasks.
- B. The runtime's compatibility with the NVIDIA Container Toolkit and its ability to expose GPUs to the container.
- C. The ease of use and familiarity with the runtime.
- D. The runtime's security features and isolation capabilities.
- E. The size of the container runtime image.
Answer: B
Explanation:
For GPU-accelerated workloads, the critical factor is the container runtime's integration with the NVIDIA Container Toolkit and its ability to properly expose the GPUs to the container. Without this, the application will not be able to leverage the GPU.
NEW QUESTION # 41
......
Compared with products from other companies, our NCP-AIO practice materials are responsible in every aspect. After your purchase of our NCP-AIO exam braindumps, the after sales services are considerate as well. We have considerate after sales services with genial staff. They are willing to solve the problems of our NCP-AIO training guide 24/7 all the time. If you have any question that you don't understand, just contat us and we will give you the most professional advice immediately.
NCP-AIO Exam Topic: https://www.premiumvcedump.com/NVIDIA/valid-NCP-AIO-premium-vce-exam-dumps.html
- How www.verifieddumps.com will Help You in Passing the NCP-AIO? 💄 Immediately open ⮆ www.verifieddumps.com ⮄ and search for ➥ NCP-AIO 🡄 to obtain a free download ⌛NCP-AIO New Dumps
- Quiz NVIDIA - Perfect NCP-AIO - NVIDIA AI Operations Frenquent Update 😈 Search for ➽ NCP-AIO 🢪 and download it for free immediately on ▷ www.pdfvce.com ◁ ⤵NCP-AIO Latest Test Simulations
- Exam Dumps NCP-AIO Collection 👆 NCP-AIO Latest Exam Forum 🍨 Latest NCP-AIO Test Report 🥾 Easily obtain ⮆ NCP-AIO ⮄ for free download through ✔ www.testkingpass.com ️✔️ 🚒NCP-AIO New Dumps
- Dumps NCP-AIO Download 🧡 NCP-AIO Guaranteed Success ⏫ NCP-AIO Latest Test Simulations 🍬 Copy URL ⮆ www.pdfvce.com ⮄ open and search for ⮆ NCP-AIO ⮄ to download for free ♻Training NCP-AIO Online
- NCP-AIO Latest Test Simulations 🦝 NCP-AIO Answers Real Questions 🌳 Exam Dumps NCP-AIO Collection 🍅 Search for 【 NCP-AIO 】 and easily obtain a free download on 「 www.prepawaypdf.com 」 🦨NCP-AIO Authentic Exam Hub
- Secure 100% Exam Results with NVIDIA NCP-AIO Practice Questions [2026] 👋 Search for 「 NCP-AIO 」 and obtain a free download on 【 www.pdfvce.com 】 🌖NCP-AIO Latest Exam Forum
- 2026 NCP-AIO Frenquent Update | High-quality NCP-AIO: NVIDIA AI Operations 100% Pass 🦑 Simply search for 【 NCP-AIO 】 for free download on ⮆ www.practicevce.com ⮄ 🔊NCP-AIO Latest Exam Camp
- Authoritative 100% Free NCP-AIO – 100% Free Frenquent Update | NCP-AIO Exam Topic 🏘 The page for free download of ✔ NCP-AIO ️✔️ on 「 www.pdfvce.com 」 will open immediately 🍵NCP-AIO Authentic Exam Hub
- NCP-AIO Frenquent Update - 100% Pass Quiz 2026 First-grade NCP-AIO: NVIDIA AI Operations Exam Topic ✔ Search for ⇛ NCP-AIO ⇚ and obtain a free download on “ www.practicevce.com ” 🔹NCP-AIO Latest Exam Online
- Latest NCP-AIO Exam Torrent - NCP-AIO Test Prep - NCP-AIO Quiz Guides 🙇 Immediately open ✔ www.pdfvce.com ️✔️ and search for ✔ NCP-AIO ️✔️ to obtain a free download 🥛Training NCP-AIO Online
- Topic: Real NVIDIA NCP-AIO Exam Practice Questions 🍒 Open website { www.pdfdumps.com } and search for { NCP-AIO } for free download 😥NCP-AIO Passing Score Feedback
- www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
2026 Latest PremiumVCEDump NCP-AIO PDF Dumps and NCP-AIO Exam Engine Free Share: https://drive.google.com/open?id=1HU1_8G4tbLMp_MaBI9Igr1DW-Pw_HvL7