ちなみに、Jpshiken KCNAの一部をクラウドストレージからダウンロードできます:https://drive.google.com/open?id=1vgMgFPl_1qXrqGePq9s197Z7YHZVr-mw
Jpshikenは専門的で、たくさんの受験生のために、君だけのために存在するのです。それは正確的な試験の内容を保証しますし、良いサービスで、安い価格で営業します。Jpshikenがあれば、Linux FoundationのKCNA試験に合格するのは心配しません。Jpshikenは君が最も早い時間でLinux FoundationのKCNA試験に合格するのを助けます。私たちは君がITエリートになるのに頑張ります。
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Container Orchestration | 22% | - Networking & Storage
|
| Topic 2: Cloud Native Observability | 8% | - Monitoring & Metrics
|
| Topic 3: Kubernetes Fundamentals | 46% | - Kubernetes Core Concepts
|
| Topic 4: Cloud Native Application Delivery | 8% | - Deployment Strategies
|
| Topic 5: Cloud Native Architecture | 16% | - Cloud Native Principles
|
我々のLinux FoundationのKCNAソフトを利用してお客様の高通過率及び我々の技術の高いチームで、我々は自信を持って我々Jpshikenは専門的なのだと言えます。アフターサービスは会社を評価する重要な基準です。これをよくできるために、我々は全日24時間のサービスを提供します。Linux FoundationのKCNAソフトを購入してから一年間の無料更新サービスも提供します。試験に失敗したら、全額で返金する承諾があります。だから、Linux FoundationのKCNA試験に合格したいあなたは安心で弊社の商品を選べばいいんです。
質問 # 191
A new Pod is created. Then, the Pod is assigned to a Node. Which Kubernetes component was re-sponsible for determining which Node to assign the Pod to?
正解:D
解説:
https://kubernetes.io/docs/reference/command-line-tools-reference/kube-scheduler/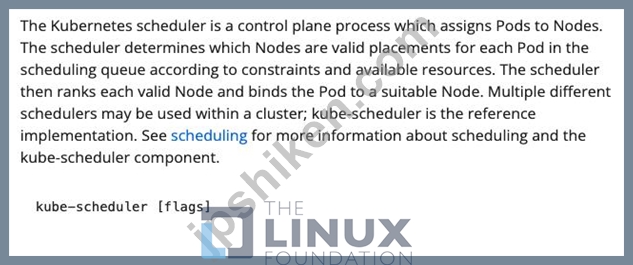
質問 # 192
To visualize data from Prometheus you can use expression browser or console templates. What is the other data visualization tool commonly used together with Prometheus?
正解:C
解説:
The most common visualization tool used with Prometheus is Grafana, so A is correct. Prometheus includes a built-in expression browser that can graph query results, but Grafana provides a much richer dashboarding experience: reusable dashboards, variables, templating, annotations, alerting integrations, and multi-data-source support.
In Kubernetes observability stacks, Prometheus scrapes and stores time-series metrics (cluster and application metrics). Grafana queries Prometheus using PromQL and renders the results into dashboards for SREs and developers. This pairing is widespread because it cleanly separates concerns: Prometheus is the metrics store and query engine; Grafana is the UI and dashboard layer.
Option B (Graphite) is a separate metrics system with its own storage/query model; while Grafana can visualize Graphite too, the question asks what is commonly used together with Prometheus, which is Grafana. Option D (GraphQL) is an API query language, not a metrics visualization tool. Option C ("Nirvana") is not a standard Prometheus visualization tool in common Kubernetes stacks.
In practice, this combo enables operational outcomes: dashboards for error rates and latency (often derived from histograms), capacity monitoring (node CPU/memory), workload behavior (Pod restarts, HPA scaling), and SLO reporting. Grafana dashboards often serve as the shared language during incidents: teams correlate alerts with time-series patterns and quickly identify when regressions began.
Therefore, the verified correct tool commonly used with Prometheus for visualization is Grafana (A).
質問 # 193
Which Kubernetes Service type exposes a service only within the cluster?
正解:B
解説:
In Kubernetes, a Service provides a stable network endpoint for a set of Pods and abstracts away their dynamic nature. Kubernetes offers several Service types, each designed for different exposure requirements.
Among these, ClusterIP is the Service type that exposes an application only within the cluster, making it the correct answer.
When a Service is created with the ClusterIP type, Kubernetes assigns it a virtual IP address that is reachable exclusively from within the cluster's network. This IP is used by other Pods and internal components to communicate with the Service through cluster DNS or environment variables. External traffic from outside the cluster cannot directly access a ClusterIP Service, which makes it ideal for internal APIs, backend services, and microservices that should not be publicly exposed.
Option B (NodePort) is incorrect because NodePort exposes the Service on a static port on each node's IP address, allowing access from outside the cluster. Option C (LoadBalancer) is incorrect because it provisions an external load balancer-typically through a cloud provider-to expose the Service publicly. Option D (ExternalName) is incorrect because it does not create a proxy or internal endpoint at all; instead, it maps the Service name to an external DNS name outside the cluster.
ClusterIP is also the default Service type in Kubernetes. If no type is explicitly specified in a Service manifest, Kubernetes automatically assigns it as ClusterIP. This default behavior reflects the principle of least exposure, encouraging internal-only access unless external access is explicitly required.
From a cloud native architecture perspective, ClusterIP Services are fundamental to building secure, scalable microservices systems. They enable internal service-to-service communication while reducing the attack surface by preventing unintended external access.
According to Kubernetes documentation, ClusterIP Services are intended for internal communication within the cluster and are not reachable from outside the cluster network. Therefore, ClusterIP is the correct and fully verified answer, making option A the right choice.
質問 # 194
You are managing a large Kubernetes cluster with multiple namespaces. You want to control access to resources within different namespaces. Which of the following mechanisms can be used to achieve fine-grained access control?
正解:A、C
解説:
Both Role-Based Access Control (RBAC) and Pod Security Policies (PSP) are used for managing access to resources within Kubernetes. RBAC provides fine-grained permissions based on roles and users, while PSPs define security constraints for Pods, limiting their capabilities and access to resources.
質問 # 195
Which control plane component is responsible for updating the node Ready condition if a node becomes unreachable?
正解:D
解説:
The correct answer is B: the node controller. In Kubernetes, node health is monitored and reflected through Node conditions such as Ready. The Node Controller (a controller that runs as part of the control plane, within the controller-manager) is responsible for monitoring node heartbeats and updating node status when a node becomes unreachable or unhealthy.
Nodes periodically report status (including kubelet heartbeats) to the API server. The Node Controller watches these updates. If it detects that a node has stopped reporting within expected time windows, it marks the node condition Ready as Unknown (or otherwise updates conditions) to indicate the control plane can't confirm node health. This status change then influences higher-level behaviors such as Pod eviction and rescheduling: after grace periods and eviction timeouts, Pods on an unhealthy node may be evicted so the workload can be recreated on healthy nodes (assuming a controller manages replicas).
Option A (kube-proxy) is a node component for Service traffic routing and does not manage node health conditions. Option C (kubectl) is a CLI client; it does not participate in control plane health monitoring. Option D (kube-apiserver) stores and serves Node status, but it doesn't decide when a node is unreachable; it persists what controllers and kubelets report. The "decision logic" for updating the Ready condition in response to missing heartbeats is the Node Controller's job.
So, the component that updates the Node Ready condition when a node becomes unreachable is the node controller, which is option B.
質問 # 196
......
我々はあなたが我々のKCNA問題集を通して試験に合格できるのを保証しています。もし不幸であなたが試験に失敗しましたら、あなたの成績書のスキャンをもらって、我々は全額であなたにKCNA問題集の金額を返金して、あなたの失敗するための経済損失を減少します。
KCNA資格トレーニング: https://www.jpshiken.com/KCNA_shiken.html
さらに、Jpshiken KCNAダンプの一部が現在無料で提供されています:https://drive.google.com/open?id=1vgMgFPl_1qXrqGePq9s197Z7YHZVr-mw