In order to facilitate the user's offline reading, the MCIA-Level-1 study braindumps can better use the time of debris to learn, especially to develop PDF mode for users. In this mode, users can know the MCIA-Level-1 prep guide inside the learning materials to download and print, easy to take notes on the paper, and weak link of their memory, at the same time, every user can be downloaded unlimited number of learning, greatly improve the efficiency of the users with our MCIA-Level-1 Exam Questions. Or you will forget the so-called good, although all kinds of digital device convenient now we read online, but many of us are used by written way to deepen their memory patterns. Our MCIA-Level-1 prep guide can be very good to meet user demand in this respect, allow the user to read and write in a good environment continuously consolidate what they learned.
| Section | Objectives |
|---|---|
| Designing applications with Anypoint connectors | |
| Handling events and messages | |
| Architecting resilient and performant integration solutions | |
| Designing and documenting enterprise integration architecture | |
| Selecting integration styles | |
| Implementing DevOps practices | |
| Configuring and provisioning Anypoint Platform | |
| Designing networks for Anypoint connectors | |
| Operating and monitoring integration solutions | |
| Handling integration implementation lifecycles |
>> MCIA-Level-1 Interactive Questions <<
Success in the MCIA-Level-1 certification exam is essential to advance your career. The MuleSoft Certified Integration Architect - Level 1 (MCIA-Level-1) certification can set you apart from the competition and give you the edge you need to grow in your career. However, preparing for the MCIA-Level-1 test can be challenging, mainly if you have limited time. Here's where TestkingPDF comes in with actual MCIA-Level-1 Questions. We at TestkingPDF are well aware of the importance of the MuleSoft MCIA-Level-1 certification in order to stand out in today's competitive job environment.
NEW QUESTION # 149
Refer to the exhibit.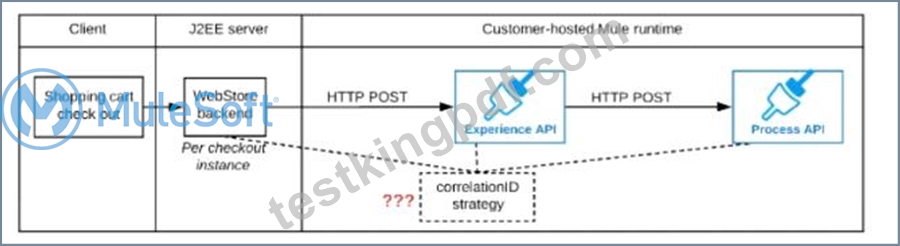
A shopping cart checkout process consists of a web store backend sending a sequence of API invocations to an Experience API, which in turn invokes a Process API. All API invocations are over HTTPS POST. The Java web store backend executes in a Java EE application server, while all API implementations are Mule applications executing in a customer -hosted Mule runtime.
End-to-end correlation of all HTTP requests and responses belonging to each individual checkout Instance is required. This is to be done through a common correlation ID, so that all log entries written by the web store backend, Experience API implementation, and Process API implementation include the same correlation ID for all requests and responses belonging to the same checkout instance.
What is the most efficient way (using the least amount of custom coding or configuration) for the web store backend and the implementations of the Experience API and Process API to participate in end-to-end correlation of the API invocations for each checkout instance?
A)
The web store backend, being a Java EE application, automatically makes use of the thread-local correlation ID generated by the Java EE application server and automatically transmits that to the Experience API using HTTP-standard headers No special code or configuration is included in the web store backend, Experience API, and Process API implementations to generate and manage the correlation ID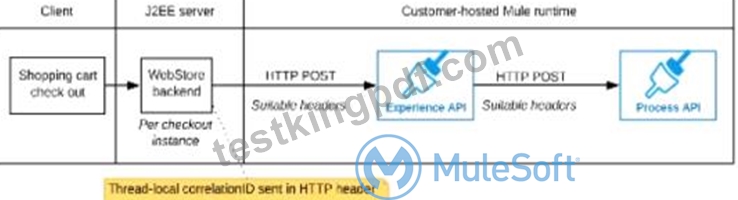
B)
The web store backend generates a new correlation ID value at the start of checkout and sets it on the X-CORRELATlON-lt HTTP request header In each API invocation belonging to that checkout No special code or configuration is included in the Experience API and Process API implementations to generate and manage the correlation ID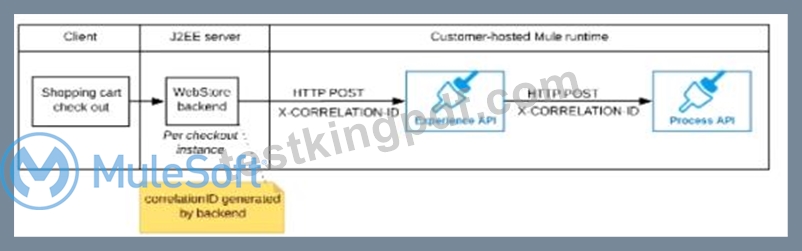
C)
The Experience API implementation generates a correlation ID for each incoming HTTP request and passes it to the web store backend in the HTTP response, which includes it in all subsequent API invocations to the Experience API.
The Experience API implementation must be coded to also propagate the correlation ID to the Process API in a suitable HTTP request header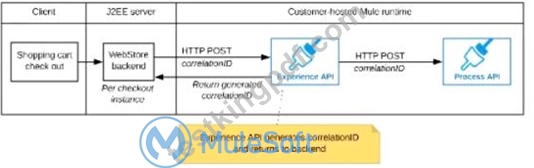
D)
The web store backend sends a correlation ID value in the HTTP request body In the way required by the Experience API The Experience API and Process API implementations must be coded to receive the custom correlation ID In the HTTP requests and propagate It in suitable HTTP request headers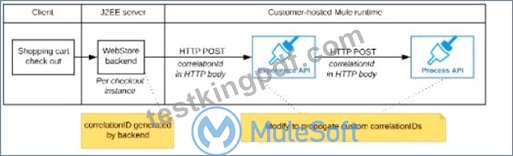
Answer: A
Explanation:
Correct answer is "The web store backend generates a new correlation ID value at the start of checkout and sets it on the X-CORRELATION-ID HTTP request header in each API invocation belonging to that checkout No special code or configuration is included in the Experience API and Process API implementations to generate and manage the correlation ID" : By design, Correlation Ids cannot be changed within a flow in Mule 4 applications and can be set only at source. This ID is part of the Event Context and is generated as soon as the message is received by the application. When a HTTP Request is received, the request is inspected for "X-Correlation-Id" header. If "X-Correlation-Id" header is present, HTTP connector uses this as the Correlation Id. If "X-Correlation-Id" header is NOT present, a Correlation Id is randomly generated. For Incoming HTTP Requests: In order to set a custom Correlation Id, the client invoking the HTTP request must set "X-Correlation-Id" header. This will ensure that the Mule Flow uses this Correlation Id. For Outgoing HTTP Requests: You can also propagate the existing Correlation Id to downstream APIs. By default, all outgoing HTTP Requests send "X-Correlation-Id" header. However, you can choose to set a different value to "X-Correlation-Id" header or set "Send Correlation Id" to NEVER.
Mulesoft Reference: https://help.mulesoft.com/s/article/How-to-Set-Custom-Correlation-Id-for-Flows-with-HTTP-Endpoint-in-Mule-4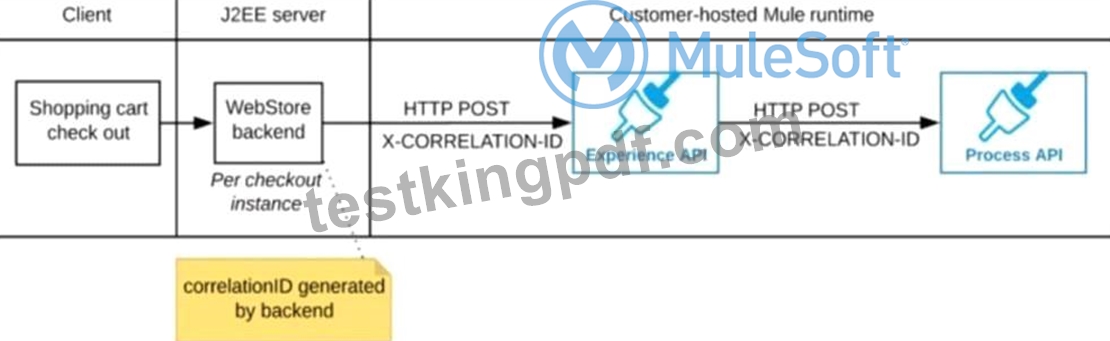
NEW QUESTION # 150
According to MuteSoft, which principle is common to both Service Oriented Architecture (SOA) and API-led connectivity approaches?
Answer: D
NEW QUESTION # 151
Mule application A receives a request Anypoint MQ message REQU with a payload containing a variable-length list of request objects. Application A uses the For Each scope to split the list into individual objects and sends each object as a message to an Anypoint MQ queue.
Service S listens on that queue, processes each message independently of all other messages, and sends a response message to a response queue.
Application A listens on that response queue and must in turn create and publish a response Anypoint MQ message RESP with a payload containing the list of responses sent by service S in the same order as the request objects originally sent in REQU.
Assume successful response messages are returned by service S for all request messages.
What is required so that application A can ensure that the length and order of the list of objects in RESP and REQU match, while at the same time maximizing message throughput?
Answer: D
NEW QUESTION # 152
Which role is primarily responsible for building API implementation as part of a typical MuleSoft integration project?
Answer: A
NEW QUESTION # 153
What aspects of a CI/CD pipeline for Mule applications can be automated using MuleSoft-provided Maven plugins?
Answer: A
Explanation:
Correct answer is "Compile, package, unit test, validate unit test coverage, deploy" : Anypoint Platform supports continuous integration and continuous delivery using industry standard tools Mule Maven Plugin The Mule Maven plugin can automate building, packaging and deployment of Mule applications from source projects Using the Mule Maven plugin, you can automate your Mule application deployment to CloudHub, to Anypoint Runtime Fabric, or on-premises, using any of the following deployment strategies * CloudHub deployment * Runtime Fabric deployment * Runtime Manager REST API deployment * Runtime Manager agent deployment MUnit Maven Plugin The MUnit Maven plugin can automate test execution, and ties in with the Mule Maven plugin. It provides a full suite of integration and unit test capabilities, and is fully integrated with Maven and Surefire for integration with your continuous deployment environment. Since MUnit 2.x, the coverage report goal is integrated with the maven reporting section. Coverage Reports are generated during Maven's site lifecycle, during the coverage-report goal. One of the features of MUnit Coverage is to fail the build if a certain coverage level is not reached. MUnit is not used for integration testing Also publishing to Anypoint Exchange or to create associated API instances in API Manager is not a part of CICD pipeline which can ne achieved using mulesoft provided maven plugin Architecture mentioned in the question can be diagrammatically put as below. Persistent Object Store is the correct answer .
* Mule Object Stores: An object store is a facility for storing objects in or across Mule applications. Mule uses object stores to persist data for eventual retrieval.
Mule provides two types of object stores:
1) In-memory store - stores objects in local Mule runtime memory. Objects are lost on shutdown of the Mule runtime. So we cant use in memory store in our scenario as we want to share watermark within all cloudhub workers
2) Persistent store - Mule persists data when an object store is explicitly configured to be persistent. Hence this watermark will be available even any of the worker goes down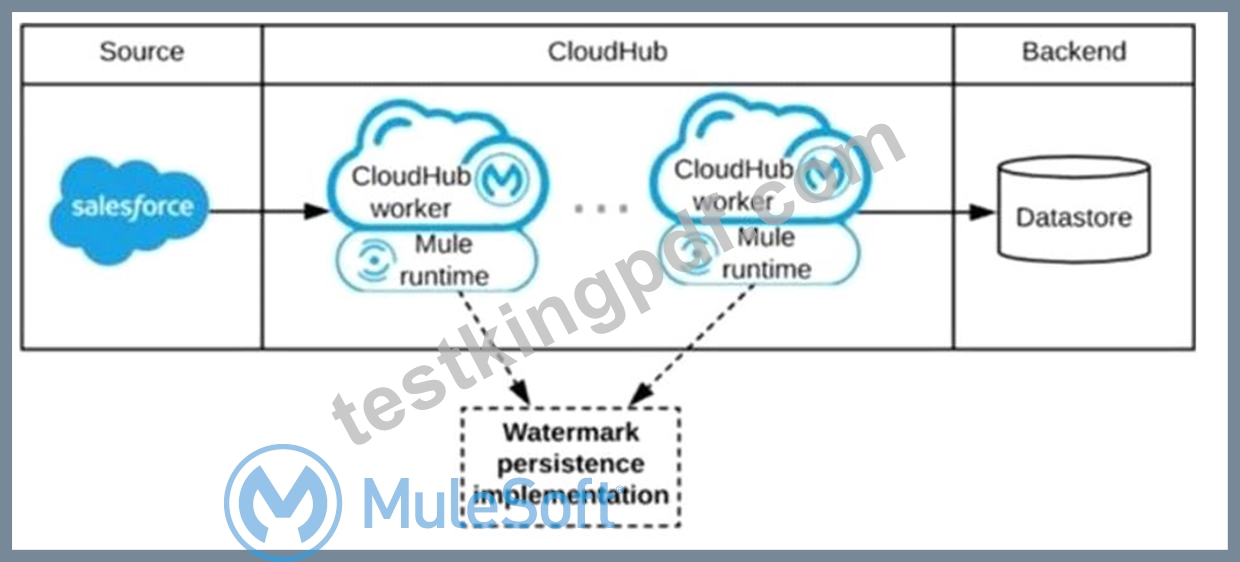
NEW QUESTION # 154
......
Due to professional acumen of expert’s, our MCIA-Level-1 guide quiz has achieved the highest level in proficiency’s perspective. For your particular inclination, we have various versions of our MCIA-Level-1 exam braindumps for you to choose:the PDF, the Software version and the APP online. Now take a look of their features and you can get realized of our MCIA-Level-1 Training Materials better. And as long as you purchase our MCIA-Level-1 study engine, you can enjoy free updates for one year long.
MCIA-Level-1 Valid Exam Forum: https://www.testkingpdf.com/MCIA-Level-1-testking-pdf-torrent.html