さらに、MogiExam CKADダンプの一部が現在無料で提供されています:https://drive.google.com/open?id=1IOoiGNaVlgNUseOGCt9XwcQlQ1BAYhEq
長年のマーケティングを通じて、当社のCKAD最新の認定ガイドは多くのお客様のサポートを獲得しています。最も明白なデータは、当社の製品が毎年徐々に増加していることであり、当社の製品開発のおかげでこのような大きな成功を達成するための大きな努力です。まず、資料の更新を研究する上で非常に良い仕事をしました。さらに、CKADの実際のCKAD学習ガイド教材の品質は、教師によって厳密に管理されています。だから、私たちは正しい選択だと信じています。CKAD学習教材について質問がある場合は、ご相談ください。
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Application Observability and Maintenance | 15% | - Understand API deprecation policies - Use built-in CLI tools to monitor Kubernetes applications - Implement probes and health checks - Debugging in Kubernetes - Utilize container logs |
| Topic 2: Services and Networking | 20% | - Demonstrate basic understanding of NetworkPolicies - Use Ingress rules to expose applications - Provide and troubleshoot access to applications via services |
| Topic 3: Application Environment, Configuration and Security | 25% | - SecurityContexts - Discover and use resources that extend Kubernetes (CRD, Operators) - Understand authentication, authorization and admission control - ConfigMaps and Secrets - ServiceAccounts - Understanding and defining resource requirements, limits and quotas |
| Topic 4: Application Design and Build | 20% | - Define, build and modify container images - Utilize persistent and ephemeral volumes - Understand multi-container Pod design patterns (e.g., sidecar, init and others) - Choose and use the right workload resource (Deployment, DaemonSet, CronJob, etc.) |
| Topic 5: Application Deployment | 20% | - Use the Helm package manager to deploy existing packages - Use Kubernetes primitives to implement common deployment strategies (e.g., blue/green or canary) - Kustomize - Understand Deployments and how to perform rolling updates |
IT業界の一员として、君はまだIT認証試験を悩んでいますか?認証試験はITの専門知識を主なテストとして別に初めてIT関連のLinux Foundation認証試験に参加する受験生にとってはとても難しいとみされます。良い対応性の訓練が必要で、MogiExam のCKAD問題集をお勧めます。
質問 # 129
You have a Deployment named 'my-app-deployment' that runs 3 replicas of an application container. The application container requires access to a ConfigMap named 'my-app-config' . You want to configure your Deployment to use Kustomize to automatically update the ConfigMap's data within the containers whenever the ConfigMap is updated. You also need to configure a rolling update strategy for the Deployment that allows for a maximum of one pod to be unavailable during the update process.
正解:
解説:
See the solution below with Step by Step Explanation.
Explanation:
Solution (Step by Step) :
1. Create a ConfigMap with the necessary data: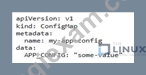
Apply tne ConfigMap using 'kubectl apply -f my-app-config.yaml' 2. Create a Kustomization file for your Deployment: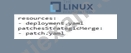
This file defines the resources that Kustomize will manage and the patch file to apply 3. Create a patch file to reference the ConfigMap: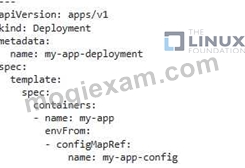
This patch adds a 'envFrom' section to the container, referencing the 'my-app-config' ConfigMap. 4. Create your Deployment YAML file: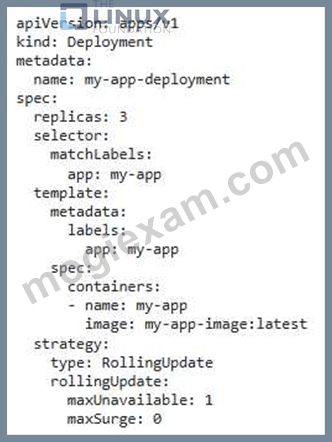
5. Apply the Kustomize configuration: - Navigate to the directory containing your Kustomization file. - Run the command 'kustomize build' to build the Kustomize resources. - Apply the built resources using 'kubectl apply -f kustomization_yaml' 6. Update the ConfigMap: Modify the data within the 'my-app-config' ContigMap. You can either edit the YAML file directly or use 'kubectl patch' to update specific values. 7. Verify the update: - Observe the logs of your 'my-apps containers to confirm that the environment variable has been updated with the new ConfigMap data. - Use 'kubectl get pods -l app=my-app' to monitor the rolling update process. You should see one pod at a time being updated with the new ConfigMap data. Note: The rolling update strategy ensures that only one pod is unavailable at a time during the update process, minimizing downtime. Kustomize ensures that the ConfigMap changes are automatically applied to the Deployment, keeping your application up-to-date.]
質問 # 130
You are working on a Kubernetes application that requires ephemeral storage. The application data needs to be stored within the pod's container and should be deleted when the pod is deleted. How can you achieve this using ephemeral storage in Kubernetes?
正解:
解説:
See the solution below with Step by Step Explanation.
Explanation:
Solution (Step by Step) :
1. Create a Deployment with an EmptyDir Volume:
- Define an 'EmptyDirs volume in tne Deployment YAML.
- Specify the volume mount path Within the container.
- Example: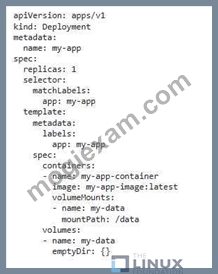
2. Create the Deployment: - Apply the Deployment YAML using 'kubectl apply -f my-app-deployment-yamr 3. Verify the Deployment - Check the status of the Deployment using ' kubectl get deployments my-app' - Verify that the Pod is running and using the EmptyDir volume. 4. Test Ephemeral Storage Behavior: - Write data to the Aldata' directory within the container - Delete the pod. - Create a new pod from the same Deployment. - The data written to tne "data' directory will no longer be present in the new pod, as the volume is ephemeral and is deleted when the pod is deleted.
質問 # 131
You nave a multi-container pod tnat uses a database container and an application container. The database container is responsible for storing sensitive datm You need to ensure that the database container only runs on nodes that have a specific label, like 'sensitive-data=true', for added security. How would you implement this constraint using Pod Affinity and node selectors?
正解:
解説:
See the solution below with Step by Step Explanation.
Explanation:
Solution (Step by Step) :
1. Define Node Labels:
- First, you need to label your nodes appropriately. I-Jse ' kubectl label nodes sensitive-data=true' for nodes that should host the database container
2. Create Pod Affinity Rules:
- In your pod definition, add a 'nodeselector' to enforce the requirement.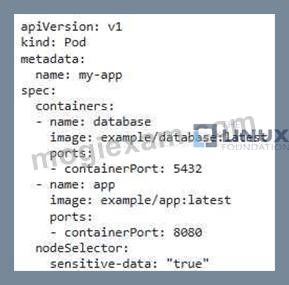
3. Apply the Pod Definition: - Apply the updated pod definition using 'kubectl apply -f my-app-yaml' 4. Verification: - Check the pod status using 'kubectl get pods my-app'. Ensure the pod is scheduled on a node with the 'sensitive-data-true label. 5. Further Security: - You can additionally use 'podAffinity' to ensure that the database container and the application container run on different nodes. This adds an extra layer of security in case one node is compromised.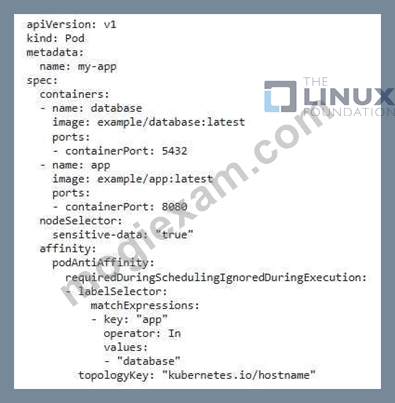
- In this example, 'podAntiAtfinitys Witn 'requiredDuringScnedulinglgnoredDunngExecution' ensures tnat tne database container and tne application container are not scheduled on the same node, thus preventing potential data breaches. ,
質問 # 132
You are building a data processing pipeline that involves multiple steps. Each step is implemented as a separate container image. The pipeline snould run only once, and it should nandle errors gracefully by retrying failed steps. How can you design this pipeline using Kubernetes Jobs, and how would you handle error handling and retries?
正解:
解説:
See the solution below with Step by Step Explanation.
Explanation:
Solution (Step by Step) :
1. Define a Pipeline with Multiple Jobs:
- Create a Job for each stage in your data processing pipeline.
- Each Job should have a dedicated container image specific to its processing step.
2. Implement Error Handling:
- Retry Mechanism Use the 'backoffLimit' and 'retries' settings within each Job's 'spec-template-spec-containers' to specify the number of retries and the delay between retries for each step.
- Error Logging: Ensure each Job logs errors to a centralized location (e.g., a persistent volume) for debugging and analysis. You can use a sidecar container to collect and process logs.
3. Chain Jobs:
- Use a Kubernetes 'Job' to chain the individual steps, ensuring that each step runs successfully before moving to the next.
- For example, use a script within the first Job's container to trigger the next Job once it completes.
4. Example Code (Simplified):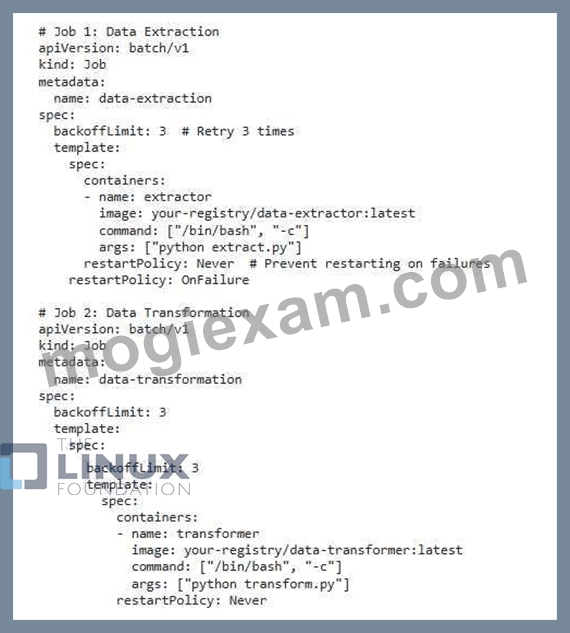
5. Execute the Pipeline: - Run the first Job ('data-extraction'). - If it fails, it will retry up to 'backoffLimit' times. - Once successful, it can trigger the second Job ('data-transformation') using a script in its container or by creating a dependent Job. 6. Monitoring and Logging: - Use Kubernetes dashboards to monitor the progress of each Job. - Check logs for error messages and debug failures. - Implement a centralized logging solution to collect logs from all Jobs. Note: For more complex pipelines, you can consider using tools like Argo Workflows or Tekton Pipelines for more advanced orchestration and error handling capabilities.,
質問 # 133
You have a Deployment named 'wordpress-deployment' that runs 3 replicas of a WordPress container. You want to implement a blue- green deployment strategy for this deployment This strategy should involve creating a new replica set with the updated image, and then gradually shitting traffic to the new replica set. After the traffic has been shifted, the old replica set should be deleted. This process should be fully automated whenever a new image is pushed to the Docker Hub repository 'example/wordpress:latest'
正解:
解説:
See the solution below with Step by Step Explanation.
Explanation:
Solution (Step by Step) :
1. Create a Kubernetes Secret for Docker Hub Credentials:
- You'll need a Secret to securely store your Docker Hub credentials for pulling images. Create a Secret with the following YAML: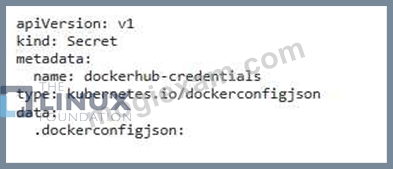
- Replace with the base64 encoded content of your Docker Hub credentials file. This file is typically named '~/.docker/config.json' and contains your Docker Hub username and password. You can create this file or update it manually. To encode the file, use a command like 'base64 ~/.docker/config .jsons 2. Create a ConfigMap for Deployment Configuratiom - Create a ConfigMap to hold the image name and any other deployment-specific configuration: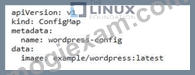
3. Define a Deployment with a Blue-Green Strategy: - Create a Deployment named swordpress-deployment that incorporates the blue-green deployment strategy. This Deployment will have a 'strategy' section with a 'type' of 'Recreate' (for initial deployment) and a 'blueGreenDeploymentStrategy' section: 4. Create a Service.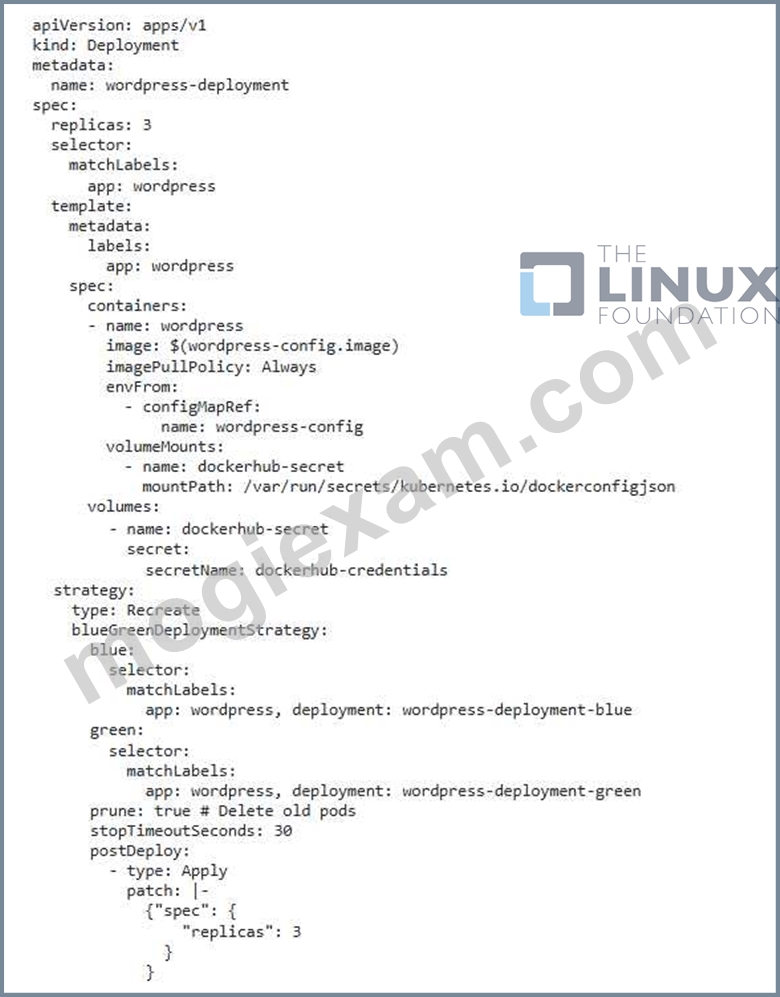
- Create a Kubernetes Service that exposes your WordPress application. This service will automatically route traffic to the active replica set.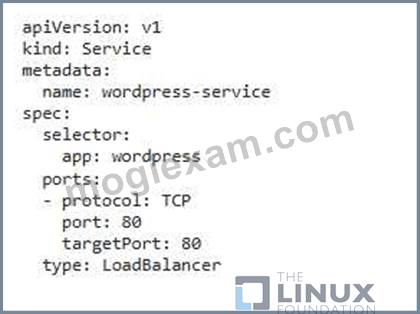
5. Automate the Blue-Green Deployment - Use a 'DeploymentConfig' resource to configure the automatic deployment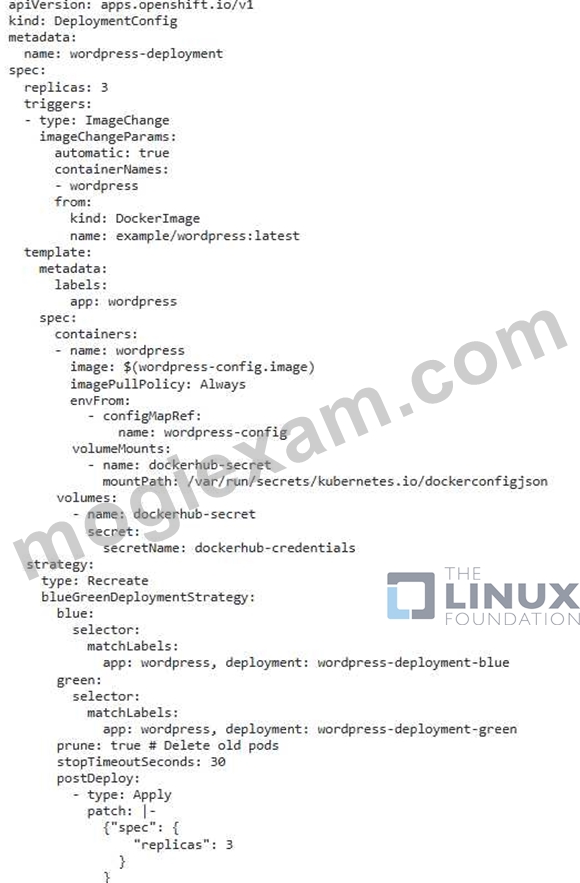
6. Apply the resources: - Apply all the YAML files using 'kubectl apply -f' to create the necessary resources. 7. Trigger the Blue-Green Deployment - Push a new image to the Docker Hub repository 'example/wordpress:latest' The 'Deploymentconfig' will automatically trigger the blue-green deployment: -A new replica set with the updated image will be created, and traffic will be shifted to the new replica set gradually - Once the traffic has been shifted, the old replica set will be deleted. Note: This implementation assumes that you are using OpenShift. If you are using a different Kubernetes distribution, the configuration may need to be adjusted SligntlY. ,
質問 # 134
......
多くの受験生がLinux FoundationのCKAD認定試験に良い成績を取らせるために、MogiExamはより良い結果までずっと努力しています。長年の努力を通じて、MogiExamのLinux FoundationのCKAD認定試験の合格率が100パーセントになっていました。もしMogiExamのLinux FoundationのCKAD問題集を購入したら、学習教材はどんな問題があれば、或いは試験に不合格になる場合は、全額返金することを保証いたします。
CKAD対策学習: https://www.mogiexam.com/CKAD-exam.html
2026年MogiExamの最新CKAD PDFダンプおよびCKAD試験エンジンの無料共有:https://drive.google.com/open?id=1IOoiGNaVlgNUseOGCt9XwcQlQ1BAYhEq