Laden Sie die neuesten It-Pruefung Databricks-Certified-Data-Engineer-Associate PDF-Versionen von Prüfungsfragen kostenlos von Google Drive herunter: https://drive.google.com/open?id=1JZpCh1NOTy1S9QPiahfQCmi3Q9k23w13
Die Schulungsunterlagen für die Vorbereitung der Databricks Databricks-Certified-Data-Engineer-Associate Zertifizierungsprüfung beinhalten die Simulationsprüfungen sowie die jetzigen Prüfungsfragen und Antworten zur Databricks Databricks-Certified-Data-Engineer-Associate Zertifizierungsprüfung. Im Internet haben Sie vielleicht auch einige ähnliche Ausbildungswebsites gesehen. Nach dem Vergleich würden Sie aber finden, dass die Schulungsunterlagen zur Databricks Databricks-Certified-Data-Engineer-Associate Zertifizierungsprüfung von It-Pruefung eher zielgerichtet sind. Sie sind nicht nur von guter Qualität, sondern auch die umfassendeste.
| Section | Weight | Objectives |
|---|---|---|
| Spark SQL and DataFrames | 15-20% | - Handle null values and data quality - Write and execute Spark SQL queries - Join and union DataFrames - Aggregate and group data |
| Apache Spark Data Processing Fundamentals | 20-25% | - Work with structured data types (arrays, maps, structs) - Use Spark SQL for data processing - Create and use Spark DataFrames - Apply transformations and actions on DataFrames |
| Data Pipeline Architecture | 15-20% | - Understand ELT vs ETL patterns - Monitor and optimize pipeline performance - Design data pipelines for batch and streaming - Implement incremental data processing |
| Lakehouse Platform Concepts | 10-15% | - Understand the Lakehouse architecture and its benefits - Describe key Databricks Lakehouse platform components - Explain data governance and security concepts |
| Python for Data Engineering | 10-15% | - Work with Spark APIs in Python - Implement user-defined functions (UDFs) - Use PySpark for data processing |
| Delta Lake Fundamentals | 20-25% | - Write to and read from Delta tables - Understand ACID transactions and time travel - Explain Delta Lake features and benefits - Create and manage Delta tables |
>> Databricks-Certified-Data-Engineer-Associate Zertifizierungsfragen <<
IT-Industrie entwickelt sich sehr schnell und die Angestellten in dieser Branche werden mehr gefordert. Wenn Sie nicht ausscheiden möchten, ist das Bestehen der Databricks Databricks-Certified-Data-Engineer-Associate Prüfung notwendig. Vielleicht haben Sie Angst davor, dass Sie die in der Databricks Databricks-Certified-Data-Engineer-Associate durchfallen, auch wenn Sie viel Zeit und Geld aufwenden. Dann lassen wir It-Pruefung Ihnen helfen! Zahllose Benutzer der Databricks Databricks-Certified-Data-Engineer-Associate Prüfungssoftware geben wir die Konfidenz, Ihnen zu garantieren, dass mit Hilfe unserer Produkte werden Ihr Bestehen der Databricks Databricks-Certified-Data-Engineer-Associate gesichert sein!
84. Frage
A data engineer needs to create a table in Databricks using data from a CSV file at location /path/to/csv.
They run the following command:
Which of the following lines of code fills in the above blank to successfully complete the task?
Antwort: C
Begründung:
A data lakehouse is a new paradigm that can be used to simplify and unify siloed data architectures that are specialized for specific use cases. A data lakehouse combines the best of both data lakes and data warehouses, providing a single platform that supports diverse data types, open standards, low-cost storage, high-performance queries, ACID transactions, schema enforcement, and governance. A data lakehouse enables data engineers to build reliable and scalable data pipelines that can serve various downstream applications and users, such as data science, machine learning, analytics, and reporting. A data lakehouse leverages the power of Delta Lake, a storage layer that brings reliability and performance to data lakes. Reference: What is a data lakehouse?, Delta Lake, Lakehouse: A New Generation of Open Platforms that Unify Data Warehousing and Advanced Analytics
85. Frage
A data engineer wants to create a new table containing the names of customers that live in France.
They have written the following command:
A senior data engineer mentions that it is organization policy to include a table property indicating that the new table includes personally identifiable information (PII).
Which of the following lines of code fills in the above blank to successfully complete the task?
Antwort: D
Begründung:
Explanation
Ref:https://www.databricks.com/discover/pages/data-quality-management
CREATE TABLE my_table (id INT COMMENT 'Unique Identification Number', name STRING COMMENT 'PII', age INT COMMENT 'PII') TBLPROPERTIES ('contains_pii'=True) COMMENT 'Contains PII';
86. Frage
A data engineer is decommissioning a sandbox schema in Unity Catalog. Some tables are ephemeral staging outputs that can be safely removed entirely, but a few tables point at shared cloud storage used by downstream jobs outside Databricks. The engineer must avoid deleting any shared files when cleaning up catalog objects.
How does Unity Catalog behave when dropping Managed vs External tables?
Antwort: C
Begründung:
In Unity Catalog, managed tables and external tables have different lifecycle behavior. When you drop a managed table , Databricks removes the table metadata and also schedules deletion of the underlying managed data files according to the managed-table retention behavior. By contrast, when you drop an external table , Unity Catalog removes only the table metadata and does not delete the underlying files in cloud storage. This distinction exists specifically so that external data can remain available to systems outside Databricks. In the scenario described, ephemeral staging outputs that should disappear completely are best represented by managed tables, while tables backed by shared cloud storage should be external tables so that dropping them does not remove files used by downstream jobs. Therefore, option C is the correct answer.
Options A, B, and D contradict documented Unity Catalog behavior because external table files are not automatically deleted, while managed table data is lifecycle-managed by Databricks.
=========
87. Frage
A data engineer runs a statement every day to copy the previous day's sales into the table transactions. Each day's sales are in their own file in the location "/transactions/raw".
Today, the data engineer runs the following command to complete this task: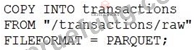
After running the command today, the data engineer notices that the number of records in table transactions has not changed.
Which of the following describes why the statement might not have copied any new records into the table?
Antwort: C
Begründung:
Explanation
https://docs.databricks.com/en/ingestion/copy-into/index.html The COPY INTO SQL command lets you load data from a file location into a Delta table. This is a re-triable and idempotent operation; files in the source location that have already been loaded are skipped. if there are no new records, the only consistent choice is C no new files were loaded because already loaded files were skipped.
88. Frage
A Delta Live Table pipeline includes two datasets defined using STREAMING LIVE TABLE. Three datasets are defined against Delta Lake table sources using LIVE TABLE.
The table is configured to run in Development mode using the Continuous Pipeline Mode.
Assuming previously unprocessed data exists and all definitions are valid, what is the expected outcome after clicking Start to update the pipeline?
Antwort: B
Begründung:
Explanation
You can optimize pipeline execution by switching between development and production modes. Use the Delta Live Tables Environment Toggle Icon buttons in the Pipelines UI to switch between these two modes. By default, pipelines run in development mode.
When you run your pipeline in development mode, the Delta Live Tables system does the following:
Reuses a cluster to avoid the overhead of restarts. By default, clusters run for two hours when development mode is enabled. You can change this with the pipelines.clusterShutdown.delay setting in the Configure your compute settings.
Disables pipeline retries so you can immediately detect and fix errors.
In production mode, the Delta Live Tables system does the following:
Restarts the cluster for specific recoverable errors, including memory leaks and stale credentials.
Retries execution in the event of specific errors, for example, a failure to start a cluster.
https://docs.databricks.com/en/delta-live-tables/updates.html#optimize-execution
89. Frage
......
Liebe Kandidaten, haben Sie schon mal gedacht, sich an der Kurse für die Databricks Databricks-Certified-Data-Engineer-Associate Zertifizierungsprüfung beteiligen? Eigentlich können Sie Maßnahmen treffen, die Prüfung nur einmal zu bestehen. Die Schulungsunterlagen von It-Pruefung ist eine gute Wahl. Das virtuelle Internet-Training und die Kurse enthalten viele Databricks Databricks-Certified-Data-Engineer-Associate Prüfungensaufgaben, die Ihnen zum erfolgreichen Bestehen der Prüfung verhelfen.
Databricks-Certified-Data-Engineer-Associate Testfagen: https://www.it-pruefung.com/Databricks-Certified-Data-Engineer-Associate.html
P.S. Kostenlose 2026 Databricks Databricks-Certified-Data-Engineer-Associate Prüfungsfragen sind auf Google Drive freigegeben von It-Pruefung verfügbar: https://drive.google.com/open?id=1JZpCh1NOTy1S9QPiahfQCmi3Q9k23w13