Nowadays certificates are more and more important for our job-hunters because they can prove that you are skillful to do the jobs in the certain areas and you boost excellent working abilities. Passing the test of AB-100 certification can help you find a better job and get a higher salary. With this target, we will provide the best AB-100 Exam Torrent to the client and help the client pass the exam easily if you buy our product.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
Solutions is one of the top platforms that has been helping Agentic AI Business Solutions Architect exam candidates for many years. Over this long time period countless candidates have passed their dream Agentic AI Business Solutions Architect (AB-100) certification exam. They all got help from Exams. Solutions AB-100 Practice Questions and easily passed their exam. The Microsoft AB-100 exam questions are designed by experience and qualified AB-100 certification expert.
NEW QUESTION # 11
Hotspot Question
You are designing a testing solution for Microsoft Copilot Studio agents.
You need to validate prompt engineering best practices to ensure that the agents generate accurate and contextually relevant responses.
Which prompt validation techniques and metrics should you include in the solution? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.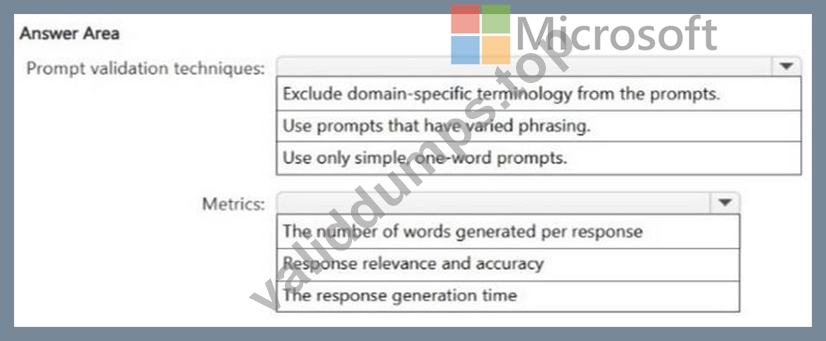
Answer:
Explanation: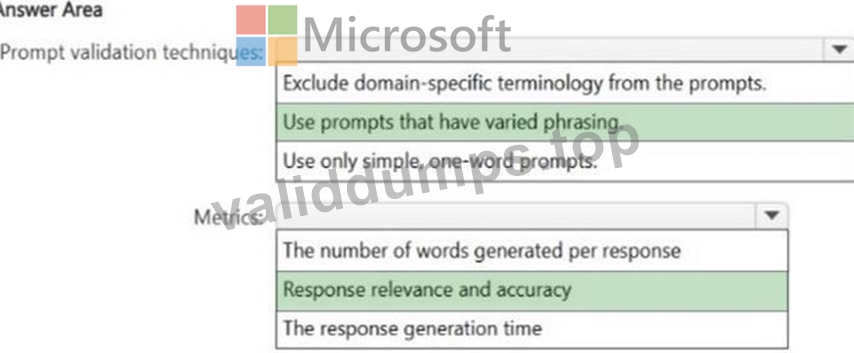
NEW QUESTION # 12
Note: This section contains one or more sets of questions with the same scenario and problem. Each question presents a unique solution to the problem. You must determine whether the solution meets the stated goals. More than one solution in the set might solve the problem. It is also possible that none of the solutions in the set solve the problem.
After you answer a question in this section, you will NOT be able to return. As a result, these questions do not appear on the Review Screen.
A company has a team that analyzes its customers by using a manual process.
You are designing an AI-based agent to automate and improve the process.
You need to recommend on which platform to build the agent. The solution must meet the following requirements:
- Use generative AI to answer common questions.
- Provide analytics to review AI performance.
- Identify customer demographics.
- Minimize custom development.
Solution: You recommend Microsoft Security Copilot.
Does this meet the goal?
Answer: A
Explanation:
Correct:
* You recommend Microsoft Copilot Studio.
Copilot Studio is specifically designed to create customizable AI agents that automate business workflows with minimal coding.
Generative AI Answers: It uses "Generative Answers" to scan your specific data (websites, files, or SharePoint) to answer customer-related questions instantly.
Analytics Dashboard: It includes built-in analytics to track resolution rates, customer satisfaction (CSAT), and overall AI performance.
Customer Demographics: You can configure the agent to extract specific entities (like age, location, or industry) from conversations to build demographic profiles.' Low-Code/No-Code: It minimizes custom development by providing a visual interface to build logic, rather than writing raw code.
Incorrect:
* You recommend GitHub Copilot.
* You recommend Microsoft Security Copilot.
Reference:
https://www.phdata.io/blog/agentic-ais-and-introduction-to-copilot/
NEW QUESTION # 13
A company has a Microsoft Foundry project that uses a single agent and a single prompt to complete a series of tasks.
The agent encounters the following issues:
It frequently produces incomplete results.
It struggles with domain-specific reasoning.
Agent response times are remarkably slow.
You need to recommend a solution to improve the overall performance and accuracy of the agent.
What should you include in the recommendation? To answer, drag the appropriate actions to the correct requirements. Each action may be used once, more than once, or not at all.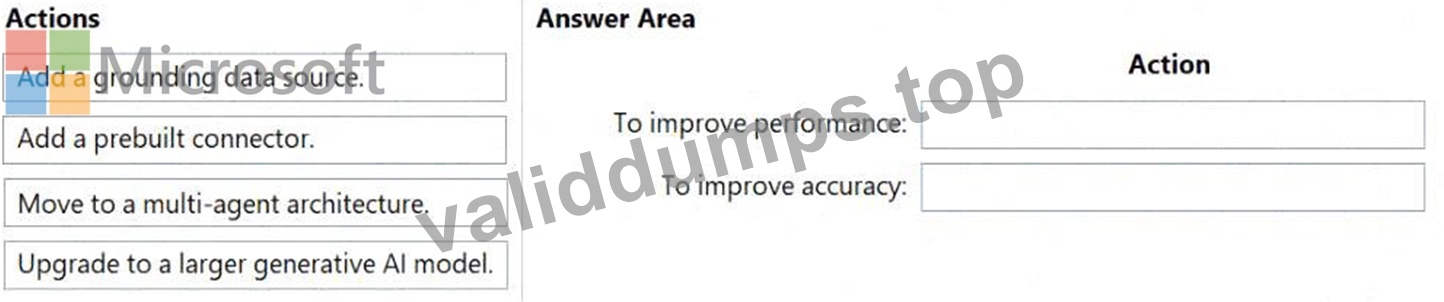
Answer:
Explanation: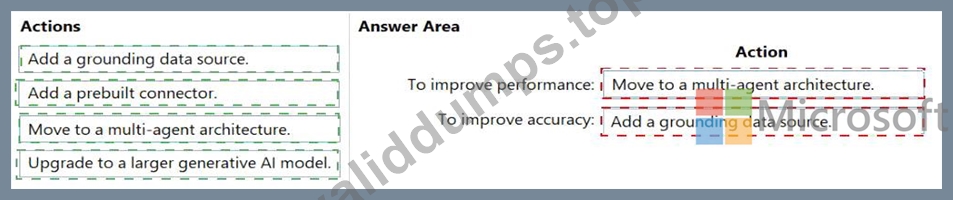
Explanation:
To improve performance # Move to a multi-agent architecture
To improve accuracy # Add a grounding data source
The current design uses a single agent and a single prompt to complete a series of tasks. That is often a bottleneck. When one agent is responsible for everything, it has to manage multiple steps, multiple reasoning modes, and multiple task transitions in one flow. This commonly leads to:
slower response times
task overload
incomplete outputs
reduced efficiency as complexity grows
Moving to a multi-agent architecture helps performance because tasks can be separated by function. For example:
one agent can handle task planning
another can retrieve domain knowledge
another can perform structured reasoning
another can prepare the final response
From an agentic AI systems perspective, decomposition improves throughput and execution quality. Instead of one overloaded agent trying to do everything, specialized agents handle narrower responsibilities. That often reduces latency in practical enterprise designs and improves the reliability of task completion.
This also addresses the symptom of incomplete results, because a multi-agent architecture can break a large workflow into smaller, controlled substeps.
Why "Add a grounding data source" improves accuracy
The agent struggles with domain-specific reasoning. That strongly suggests it lacks sufficient domain context during inference.
The best way to improve accuracy in this case is to add a grounding data source.
Grounding means giving the model access to trusted, relevant business knowledge at runtime, such as:
internal documentation
product specifications
policy manuals
knowledge bases
industry-specific reference data
This improves domain-specific reasoning because the model no longer relies only on general pretrained knowledge. Instead, it can anchor its responses in authoritative content.
From an AI business solutions standpoint, grounding is one of the most important mechanisms for improving:
factual relevance
domain accuracy
consistency
trustworthiness
explainability in enterprise contexts
When a model is inaccurate because it lacks business context, grounding is usually a better first fix than simply scaling model size.
Why the other actions are not the best fit
Add a prebuilt connector
A prebuilt connector helps with integration to systems and services, but it does not directly solve slow reasoning, incomplete output, or weak domain-specific reasoning unless the issue is specifically missing access to an external system. That is not the main problem described here.
Upgrade to a larger generative AI model
A larger model may sometimes improve reasoning quality, but it usually comes with higher cost and often slower response times, which works against the stated performance issue. It is not the best recommendation when the current agent is already slow.
Also, when domain-specific reasoning is the problem, grounding is usually more efficient and more controllable than simply choosing a larger model.
Expert reasoning shortcut
Use this exam logic:
Slow and overloaded single agent handling many tasks # move to multi-agent architecture Weak domain-specific reasoning # add grounding data source Need system integration # prebuilt connector Need raw generative capability increase, but can accept more cost/latency # larger model
NEW QUESTION # 14
You are designing a testing solution for Microsoft Copilot Studio agents.
You need to validate prompt engineering best practices to ensure that the agents generate accurate and contextually relevant responses. Which prompt validation techniques and metrics should you include in the solution? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.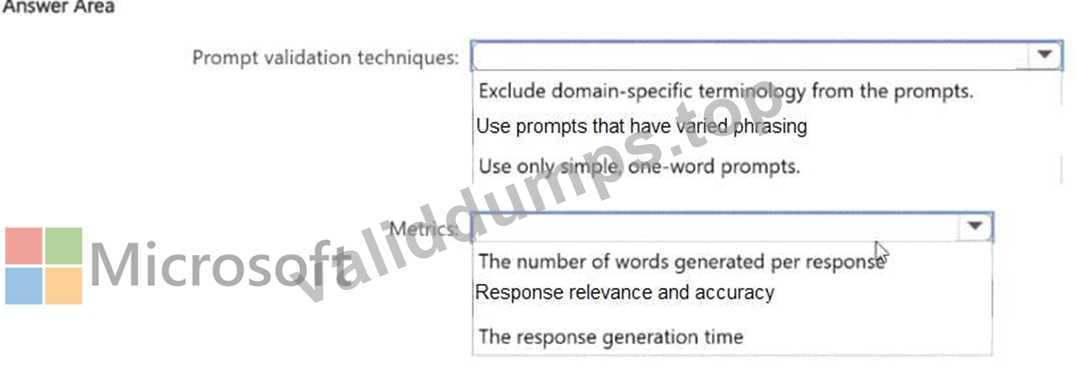
Answer:
Explanation: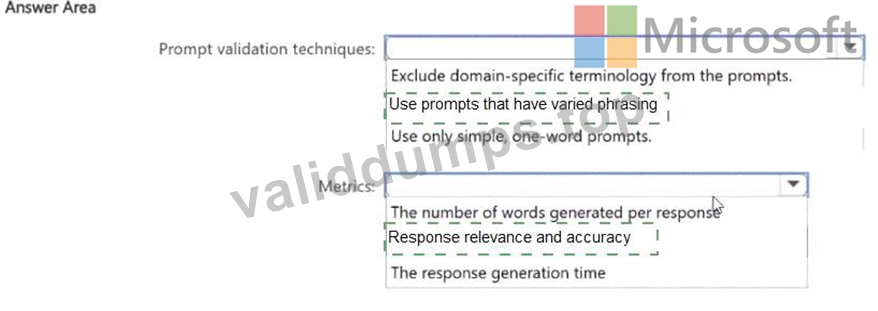
Explanation: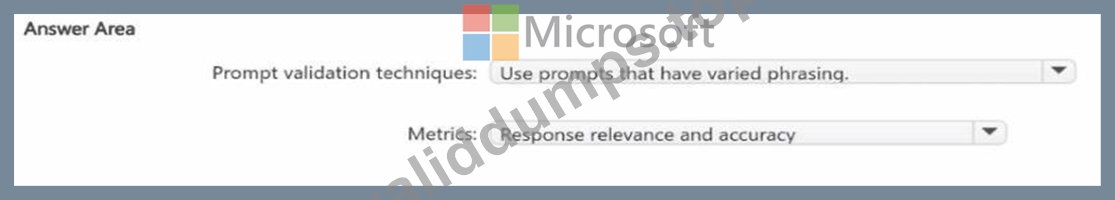
To validate prompt engineering f or Microsoft Copilot Studio agents , the goal is to confirm that the agent responds correctly even when users ask the same thing in different ways, and to measure whether the responses are actually useful and correct.
For the prompt validation technique , the correct choice is Use prompts that have varied phrasing . This is a core best practice because real users do not ask questions in one fixed form. They may use different wording, sentence structure, synonyms, or levels of detail. Testing with varied phra sing checks whether the prompt design is robust and whether the agent can still produce the right response across natural language variation.
For the metric , the correct choice is Response relevance and accuracy . Since the requirement is to ensure responses are accurate and contextually relevant , this is the most appropriate measure. It directly evaluates whether the output answers the user's need correctly and in the right context.
Why the other options are not correct:
* Exclude domain-specific term inology from the prompts is not a best practice in business AI solutions.
In many enterprise scenarios, domain-specific terms are essential for accuracy.
* Use only simple, one-word prompts does not reflect real-world usage and would weaken testing coverage.
* The number of words generated per response does not tell you whether the response is correct or contextually appropriate.
* The response generation time is a performance metric, not the best metric for validating prompt quality.
NEW QUESTION # 15
A company has a Microsoft Foundry generative Al model.
You need to evaluate the model ' s output to measure the overall quality and coherence of generated responses. The evaluation must use GPT-4o as a judge and return a numeric score for each output.
Which type of metric should you use?
Answer: A
Explanation:
The requirement says the evaluation must:
measure overall quality and coherence of generated responses
use GPT-4o as a judge
return a numeric score for each output
That maps directly to AI quality (AI assisted).
Why D is correct:
AI-assisted quality metrics use a strong model such as GPT-4o to evaluate generated outputs against qualitative dimensions like coherence, relevance, completeness, and overall response quality, and then assign scores.
Why the other options are not correct:
A). Groundedness checks whether the answer is supported by the source/context, not overall quality and coherence.
B). AI quality (NLP) usually refers to traditional NLP-style metrics rather than judge-model scoring with GPT-
4o.
C). risk and safety evaluates harmfulness, toxicity, jailbreak risk, or policy concerns, not overall response quality.
NEW QUESTION # 16
......
Our company has employed a lot of leading experts in the field to compile the AB-100 Exam Materials, in order to give candidate a chance to pass the AB-100 exam. So many candidates see our ValidDumps web page occasionally, and they are attracted by our high quality and valid dumps. They bought it without any hesitation. However, they passed the exam successfully. It turned out that their choice was extremely correct.
AB-100 Reliable Dumps Ebook: https://www.validdumps.top/AB-100-exam-torrent.html