Databricks Certified-Data-Engineer-Professional Databricks Certified Data Engineer Professional Questions - With 25% Discount Offer [2026]

In the process of using Certified-Data-Engineer-Professional study question if the clients encounter the difficulties, the obstacles and the doubts they could contact our online customer service staff in the whole day. Our service team will update the Certified-Data-Engineer-Professional certification file periodically and provide one-year free update. Have known these advantages you may be curious to further understand the detailed information about our Certified-Data-Engineer-Professional training braindump and we list the detailed characteristics and functions of our Certified-Data-Engineer-Professional exam questions on the web for you to know.
| Section | Objectives |
|---|
| Topic 1: Data Governance | - Govern enterprise data
- 1. Demonstrate understanding of the Unity Catalog permission inheritance model
- 2. Create and add descriptions and metadata to enterprise data to improve discoverability
|
| Topic 2: Debugging and Deploying | - Deploying CI/CD
- 1. Build and deploy Databricks resources using Databricks Asset Bundles
- 2. Configure and integrate Git-based CI/CD workflows using Databricks Git folders for notebook and code deployment
- Debugging and Troubleshooting
- 1. Analyze errors and remediate failed job runs using job repairs and parameter overrides
- 2. Use Lakeflow Declarative Pipelines event logs and Spark UI to debug Lakeflow Declarative Pipelines and Spark pipelines
- 3. Identify diagnostic information using Spark UI, cluster logs, system tables, and query profiles to troubleshoot errors
|
| Topic 3: Monitoring and Alerting | - Alerting
- 1. Use SQL Alerts to monitor data quality
- 2. Use the Workflows UI and Jobs API to configure notifications for job status and performance issues
- Monitoring
- 1. Use Databricks REST APIs and Databricks CLI to monitor jobs and pipelines
- 2. Use system tables for observability of resource utilization, cost, auditing, and workloads
- 3. Use Lakeflow Declarative Pipelines event logs to monitor pipelines
- 4. Use Query Profile and Spark UI to monitor workloads
|
| Topic 4: Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Create an append-only data pipeline capable of handling both batch and streaming data using Delta
- 2. Ingest formats including Delta Lake, Parquet, ORC, AVRO, JSON, CSV, XML, text, and binary data from sources such as message buses and cloud storage
|
| Topic 5: Cost & Performance Optimization | - Optimize cost and performance
- 1. Understand how and why Unity Catalog managed tables reduce operational overhead and maintenance burden
- 2. Understand Databricks query optimization techniques for large datasets, including data skipping and file pruning
- 3. Use query profiling to identify bottlenecks such as inefficient joins and data shuffling
- 4. Understand Delta optimization techniques such as deletion vectors and liquid clustering
- 5. Apply Change Data Feed to address streaming table limitations and improve latency
|
| Topic 6: Data Transformation, Cleansing, and Quality | - Transform and validate data
- 1. Write efficient Spark SQL and PySpark code for advanced transformations including window functions, joins, and aggregations
- 2. Develop a quarantining process for bad data with Lakeflow Declarative Pipelines or Auto Loader in classic jobs
|
| Topic 7: Developing Code for Data Processing using Python and SQL | - Building and Testing an ETL Pipeline with Lakeflow Declarative Pipelines, SQL, and Apache Spark
- 1. Develop unit and integration tests using assertDataFrameEqual, assertSchemaEqual, DataFrame.transform, testing frameworks, and debugging tools
- 2. Create pipeline components using control flow operators such as if/else and foreach
- 3. Compare Spark Structured Streaming and Lakeflow Declarative Pipelines to determine the optimal approach for scalable ETL pipelines
- 4. Choose appropriate configurations for environments, dependencies, high-memory notebook tasks, and retry behavior
- 5. Use APPLY CHANGES APIs to simplify CDC in Lakeflow Declarative Pipelines
- 6. Explain the advantages and disadvantages of streaming tables compared to materialized views
- 7. Build and manage reliable, production-ready batch and streaming data pipelines using Lakeflow Declarative Pipelines and Auto Loader
- 8. Create and automate ETL workloads using Jobs through the UI, APIs, or CLI
- Using Python and Tools for Development
- 1. Manage and troubleshoot external third-party library installations and dependencies, including PyPI packages, local wheels, and source archives
- 2. Design and implement a scalable Python project structure optimized for Databricks Asset Bundles, enabling modular development, deployment automation, and CI/CD integration
- 3. Develop User-Defined Functions using Pandas/Python UDF
|
| Topic 8: Data Sharing and Federation | - Share and federate data
- 1. Configure Lakehouse Federation with appropriate governance across supported source systems
- 2. Demonstrate secure Delta Sharing between Databricks deployments using Databricks-to-Databricks sharing or with external platforms using the open sharing protocol
- 3. Use Delta Sharing to share live data from the Lakehouse with any computing platform
|
| Topic 9: Ensuring Data Security and Compliance | - Ensuring Compliance
- 1. Implement compliant batch and streaming pipelines that detect and mask PII
- 2. Develop data purging solutions that comply with data retention policies
- Applying Data Security Mechanisms
- 1. Use row filters and column masks to protect sensitive table data
- 2. Apply anonymization and pseudonymization methods including hashing, tokenization, suppression, and generalization
- 3. Use ACLs to secure workspace objects and enforce the principle of least privilege
|
| Topic 10: Data Modeling | - Design and optimize data models
- 1. Identify the benefits of liquid clustering over partitioning and Z-Ordering
- 2. Simplify data layout decisions and optimize query performance using liquid clustering
- 3. Design dimensional models for analytical workloads with efficient querying and aggregation
- 4. Design and implement scalable data models using Delta Lake to manage large datasets
|
>> Certified-Data-Engineer-Professional New Dumps Ebook <<
Latest Certified-Data-Engineer-Professional Test Notes | Certified-Data-Engineer-Professional Test Questions Pdf
If candidates want to obtain certifications candidates should notice studying methods. If you do not want to purchase our Databricks Certified-Data-Engineer-Professional new exam bootcamp materials and just want to study yourself, willpower is the most important. Passing so many exams is really not easy. Reasonable studying methods and relative work experience make you half the work with double the results. Certified-Data-Engineer-Professional New Exam Bootcamp materials will be a shortcut for you.
Databricks Certified Data Engineer Professional Sample Questions (Q118-Q123):
NEW QUESTION # 118
All records from an Apache Kafka producer are being ingested into a single Delta Lake table with the following schema:
key BINARY, value BINARY, topic STRING, partition LONG, offset LONG, timestamp LONG There are 5 unique topics being ingested. Only the "registration" topic contains Personal Identifiable Information (PII). The company wishes to restrict access to PII. The company also wishes to only retain records containing PII in this table for 14 days after initial ingestion.
However, for non-PII information, it would like to retain these records indefinitely.
Which of the following solutions meets the requirements?
- A. Data should be partitioned by the registration field, allowing ACLs and delete statements to be set for the PII directory.
- B. Data should be partitioned by the topic field, allowing ACLs and delete statements to leverage partition boundaries.
- C. Separate object storage containers should be specified based on the partition field, allowing isolation at the storage level.
- D. All data should be deleted biweekly; Delta Lake's time travel functionality should be leveraged to maintain a history of non-PII information.
- E. Because the value field is stored as binary data, this information is not considered PII and no special precautions should be taken.
Answer: B
Explanation:
By default partitionning by a column will create a separate folder for each subset data linked to the partition.
NEW QUESTION # 119
A job runs four independent tasks (X, Y, Z, W) in parallel to process regional sales data. The Data Engineering team recently updated its cluster policy to ban cost-prohibitive instance types. Task Y now fails due to the newly enforced cluster policy restricting the use of a specific instance type.
A data engineer needs to resolve the failure quickly without disrupting the other tasks. How should the data engineer resolve the failure of tasks?
- A. Delete the failed run, disable the cluster policy, and re-execute all tasks.
- B. Manually create a new cluster for Task Y, update the job configuration, and trigger a full re-run.
- C. Edit the global cluster policy to allow the restricted instance type, then re-run the entire job.
- D. Use "Repair run", override the cluster configuration for Task Y to use a permitted instance type, and let Databricks re-run only Task Y.
Answer: D
Explanation:
Repair run allows re-running only the failed task without affecting successfully completed tasks.
Overriding the cluster configuration for the specific task resolves the policy violation quickly while keeping the rest of the job intact and minimizing disruption.
NEW QUESTION # 120
A data engineering team is setting up deployment automation. To deploy workspace assets remotely using the Databricks CLI command, they must configure it with proper authentication.
Which authentication approach will provide the highest level of security?
- A. Use a service principal ID and its OAuth client secret.
- B. Use a shared user account and its OAuth client secret.
- C. Use a service principal with OAuth token federation.
- D. Use a service principal and its Personal Access Token.
Answer: C
Explanation:
The most secure and enterprise-recommended authentication method for Databricks automation is OAuth token federation with service principals.
This configuration allows service principals (non-human identities) to authenticate using temporary OAuth access tokens from a trusted identity provider (such as Azure AD or AWS IAM federation). These tokens are short-lived and scoped, significantly reducing credential exposure risks.
By contrast, static client secrets (B) or PATs (C) are long-lived and require periodic manual rotation, increasing security vulnerability. Shared user accounts (D) violate least-privilege and auditability principles. Therefore, A provides the strongest, most compliant authentication model for automated CLI and CI/CD workflows.
NEW QUESTION # 121
While reviewing a query's execution in the Databricks Query Profiler, a data engineer observes that the Top Operators panel shows a Sort operator with high Time Spent and Memory Peak metrics. The Spark UI also reports frequent data spilling. How should the data engineer address this issue?
- A. Switch to a broadcast join to reduce memory usage.
- B. Convert the sort operation to a filter operation.
- C. Increase the number of shuffle partitions to better distribute data.
- D. Repartition the DataFrame to a single partition before sorting.
Answer: C
Explanation:
Increasing the number of shuffle partitions distributes the data across more tasks, reducing per- task memory pressure during the sort operation. This helps mitigate spilling by lowering memory peak usage per task and improves overall sort performance in large-scale distributed queries.
NEW QUESTION # 122
A task orchestrator has been configured to run two hourly tasks. First, an outside system writes Parquet data to a directory mounted at /mnt/raw_orders/. After this data is written, a Databricks job containing the following code is executed:
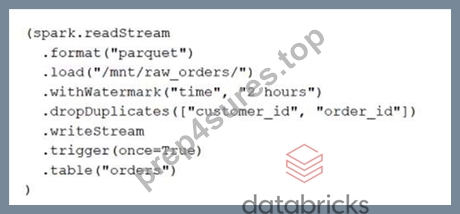
Assume that the fields customer_id and order_id serve as a composite key to uniquely identify each order, and that the time field indicates when the record was queued in the source system.
If the upstream system is known to occasionally enqueue duplicate entries for a single order hours apart, which statement is correct?
- A. Duplicate records arriving more than 2 hours apart will be dropped, but duplicates that arrive in the same batch may both be written to the orders table.
- B. Duplicate records enqueued more than 2 hours apart may be retained and the orders table may contain duplicate records with the same customer_id and order_id.
- C. All records will be held in the state store for 2 hours before being deduplicated and committed to the orders table.
- D. The orders table will not contain duplicates, but records arriving more than 2 hours late will be ignored and missing from the table.
- E. The orders table will contain only the most recent 2 hours of records and no duplicates will be present.
Answer: B
NEW QUESTION # 123
......
You can access the premium PDF file of Databricks Certified Data Engineer Professional Certified-Data-Engineer-Professional dumps right after making the payment. It will contain all the latest Certified-Data-Engineer-Professional exam dumps questions based on the official Certified-Data-Engineer-Professional exam study guide. These are the most relevant Databricks Certified-Data-Engineer-Professional questions that will appear in the actual Databricks Certified Data Engineer Professional exam. Thus you won't waste your time preparing with outdated Certified-Data-Engineer-Professional Dumps. You can go through Databricks Certified-Data-Engineer-Professional dumps questions using this PDF file anytime, anywhere even on your smartphone.
Latest Certified-Data-Engineer-Professional Test Notes: https://www.prep4sures.top/Certified-Data-Engineer-Professional-exam-dumps-torrent.html
- Last Certified-Data-Engineer-Professional Exam Dumps: Databricks Certified Data Engineer Professional help you pass Certified-Data-Engineer-Professional exam surely - www.dumpsquestion.com 🧱 Search for ▶ Certified-Data-Engineer-Professional ◀ on ➤ www.dumpsquestion.com ⮘ immediately to obtain a free download 🔘Certified-Data-Engineer-Professional Latest Materials
- Web-based Certified-Data-Engineer-Professional Practice Test With Dumps 😆 Search for ⏩ Certified-Data-Engineer-Professional ⏪ on ☀ www.pdfvce.com ️☀️ immediately to obtain a free download 🐎Certified-Data-Engineer-Professional Latest Materials
- Certified-Data-Engineer-Professional Study Dumps 🦹 Certified-Data-Engineer-Professional Test Sample Online 💟 Certified-Data-Engineer-Professional Reliable Test Pattern 🙅 Easily obtain ▛ Certified-Data-Engineer-Professional ▟ for free download through 《 www.testkingpass.com 》 🍵Certified-Data-Engineer-Professional Valid Test Labs
- 2026 Authoritative 100% Free Certified-Data-Engineer-Professional – 100% Free New Dumps Ebook | Latest Databricks Certified Data Engineer Professional Test Notes 🔖 Search on ( www.pdfvce.com ) for ➠ Certified-Data-Engineer-Professional 🠰 to obtain exam materials for free download 🙁Certified-Data-Engineer-Professional Test Sample Online
- Certified-Data-Engineer-Professional Materials 📳 Certified-Data-Engineer-Professional Valid Test Labs 🧴 Certified-Data-Engineer-Professional Latest Version 🚗 Download ⮆ Certified-Data-Engineer-Professional ⮄ for free by simply entering ▶ www.troytecdumps.com ◀ website 🏃Certified-Data-Engineer-Professional Latest Version
- 2026 Authoritative 100% Free Certified-Data-Engineer-Professional – 100% Free New Dumps Ebook | Latest Databricks Certified Data Engineer Professional Test Notes 🥗 Search for { Certified-Data-Engineer-Professional } and easily obtain a free download on ➡ www.pdfvce.com ️⬅️ 🙄Certified-Data-Engineer-Professional Reliable Test Price
- Databricks Certified-Data-Engineer-Professional New Dumps Ebook: Databricks Certified Data Engineer Professional - www.pdfdumps.com Helps you Prepare Easily 🌶 Search for ▷ Certified-Data-Engineer-Professional ◁ and download exam materials for free through ▶ www.pdfdumps.com ◀ 🙋Certified-Data-Engineer-Professional Materials
- User Friendly Pdfvce Certified-Data-Engineer-Professional Exam Practice Test Software 🧢 ➽ www.pdfvce.com 🢪 is best website to obtain ( Certified-Data-Engineer-Professional ) for free download ⏩Certified-Data-Engineer-Professional Test Sample Online
- Certified-Data-Engineer-Professional Valid Test Labs 🧚 Certified-Data-Engineer-Professional Test Sample Online 📌 Certified-Data-Engineer-Professional Valid Test Labs ⌚ Enter ▛ www.practicevce.com ▟ and search for “ Certified-Data-Engineer-Professional ” to download for free 🍐Certified-Data-Engineer-Professional Test Vce Free
- Certified-Data-Engineer-Professional Test Sample Online 🍀 Certified-Data-Engineer-Professional Study Dumps 📽 Certified-Data-Engineer-Professional Reliable Test Price 🚟 Easily obtain ➤ Certified-Data-Engineer-Professional ⮘ for free download through ▶ www.pdfvce.com ◀ ⬅️Certified-Data-Engineer-Professional Test Sample Online
- Certified-Data-Engineer-Professional Test Sample Online ☯ Certified-Data-Engineer-Professional Reliable Test Price 🌳 Certified-Data-Engineer-Professional Study Dumps 🛹 Search for ➽ Certified-Data-Engineer-Professional 🢪 and download it for free immediately on ⮆ www.testkingpass.com ⮄ 🎭Certified-Data-Engineer-Professional Materials
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, learn.csisafety.com.au, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes