Databricks-Certified-Data-Engineer-Professional Valid Exam Review - Valid Databricks-Certified-Data-Engineer-Professional Test Pdf

In order to help you more ActualVCE the Databricks Databricks-Certified-Data-Engineer-Professional exam eliminate tension of the candidates on the Internet. Databricks-Certified-Data-Engineer-Professional study materials including the official Databricks Databricks-Certified-Data-Engineer-Professional certification training courses, Databricks Databricks-Certified-Data-Engineer-Professional self-paced training guide, Databricks-Certified-Data-Engineer-Professional exam ActualVCE and practice, Databricks-Certified-Data-Engineer-Professional Online Exam Databricks-Certified-Data-Engineer-Professional study guide. Databricks-Certified-Data-Engineer-Professional simulation training package designed by ActualVCE can help you effortlessly pass the exam. Do not spend too much time and money, as long as you have ActualVCE learning materials you will easily pass the exam.
| Section | Objectives |
|---|
| Data Ingestion and Processing | - Batch and streaming ingestion with Auto Loader
- ETL pipeline design patterns
- Structured Streaming fundamentals
|
| Production Pipelines and Orchestration | - Job scheduling and monitoring
- Databricks Workflows
- Error handling and recovery strategies
|
| Delta Lake and Data Management | - Delta Lake transactions and ACID properties
- Time travel and versioning
- Schema evolution and enforcement
|
| Data Modeling and Transformation | - Performance optimization techniques
- Spark SQL transformations
- Dimensional modeling concepts
|
| Databricks Lakehouse Platform Architecture | - Workspace and cluster architecture
- Data governance concepts (Unity Catalog basics)
- Medallion architecture (Bronze, Silver, Gold)
|
>> Databricks-Certified-Data-Engineer-Professional Valid Exam Review <<
Valid Databricks-Certified-Data-Engineer-Professional Test Pdf, Valid Braindumps Databricks-Certified-Data-Engineer-Professional Questions
In such society where all people take the time so precious, choosing ActualVCE to help you pass the Databricks Certification Databricks-Certified-Data-Engineer-Professional Exam is cost-effective. If you choose ActualVCE, we promise that we will try our best to help you pass the exam and also provide you with one year free update service. If you fail the exam, we will give you a full refund.
Databricks Certified Data Engineer Professional Exam Sample Questions (Q53-Q58):
NEW QUESTION # 53
An upstream source writes Parquet data as hourly batches to directories named with the current date. A nightly batch job runs the following code to ingest all data from the previous day as indicated by the date variable:
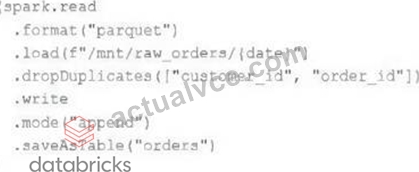
Assume that the fields customer_id and order_id serve as a composite key to uniquely identify each order.
If the upstream system is known to occasionally produce duplicate entries for a single order hours apart, which statement is correct?
- A. Each write to the orders table will only contain unique records, and only those records without duplicates in the target table will be written.
- B. Each write to the orders table will only contain unique records, but newly written records may have duplicates already present in the target table.
- C. Each write to the orders table will run deduplication over the union of new and existing records, ensuring no duplicate records are present.
- D. Each write to the orders table will only contain unique records; if existing records with the same key are present in the target table, these records will be overwritten.
- E. Each write to the orders table will only contain unique records; if existing records with the same key are present in the target table, the operation will tail.
Answer: B
Explanation:
This is the correct answer because the code uses the dropDuplicates method to remove any duplicate records within each batch of data before writing to the orders table. However, this method does not check for duplicates across different batches or in the target table, so it is possible that newly written records may have duplicates already present in the target table. To avoid this, a better approach would be to use Delta Lake and perform an upsert operation using mergeInto.
NEW QUESTION # 54
A data engineer inherits a Delta table with historical partitions by country that are badly skewed.
Queries often filter by high-cardinality customer_id and vary across dimensions over time. The engineer wants a strategy that avoids a disruptive full rewrite, reduces sensitivity to skewed partitions, and sustains strong query performance as access patterns evolve. Which two actions should the data engineer take? (Choose two.)
- A. Keep existing partitions and rely on bin-packing OPTIMIZE only; ZORDER and clustering are unnecessary for multi-dimensional filters.
- B. Depend solely on optimized writes; Databricks will automatically replace partitioning with clustering over time.
- C. Switch from static partitioning to liquid clustering and select initial clustering keys that reflect common filters such as customer_id.
- D. Periodically run OPTIMIZE table_name.
- E. Disable data skipping statistics to avoid maintenance overhead; rely on adaptive query execution instead.
Answer: C,D
Explanation:
Liquid Clustering replaces traditional partitioning and ZORDER optimization by automatically organizing data according to clustering keys. It supports evolving clustering strategies without requiring a full table rewrite. To maintain cluster balance and improve performance, the OPTIMIZE command should be run periodically. OPTIMIZE groups data files by clustering keys and helps reduce small file overhead.
NEW QUESTION # 55
A data engineer is optimizing a managed Delta table that suffers from data skew and frequently changing query filter columns. The engineer wants to avoid costly data rewrites when query patterns evolve. The table size is under 1 TB. How should the data engineer meet this requirement?
- A. Use Hive-style partitioning, as it provides efficient data skipping and is easy to change partition columns at any time.
- B. Combine partitioning and Z-ordering to maximize flexibility and minimize maintenance as query patterns change.
- C. Enable liquid clustering, as it efficiently handles data skew, allows clustering keys to be changed without rewriting existing data, and adapts to evolving query patterns.
- D. Apply Z-ordering, since it allows flexible reorganization of data layout without rewriting existing files and adapts easily to new filter columns.
Answer: C
Explanation:
Liquid clustering is designed for managed tables under 1TB with evolving query patterns. It efficiently addresses data skew, continuously optimizes data layout, and allows clustering keys to be changed without requiring full data rewrites, making it well suited for frequently changing filter columns while minimizing maintenance overhead.
NEW QUESTION # 56
A senior data engineer is planning large-scale data workflows. The current task is to identify the considerations that form a foundation for creating scalable data models that are essential for effective management of large datasets. The data engineering team has identified the core capabilities as part of a scalable data model to build a modern data platform and provided their reasoning for considering Delta Lake for review. The senior data engineer is responsible for identifying the recommendations that are not valid. Which key features can be ignored while evaluating Delta Lake?
- A. Delta Lake provides limited support for monitoring and troubleshooting data pipelines, so relevant partner tools have to be identified and set up for enhanced operational efficiency.
- B. Delta Lake's capability to process data in both batch and streaming modes seamlessly, providing flexibility in data ingestion and processing.
- C. Delta Lake optimizes metadata handling, efficiently managing billions of files and facilitating scalability to petabyte-scale datasets.
- D. Delta Lake works with various data formats (e.g., Parquet, JSON, CSV) and integrates well with Spark and Databricks tools.
Answer: A
Explanation:
Delta Lake includes built-in capabilities for monitoring, auditing, and troubleshooting through transaction logs, history, and tight integration with the Databricks platform. Therefore, limited support for monitoring and troubleshooting is not a valid concern when evaluating Delta Lake and can be ignored.
NEW QUESTION # 57
A data engineer is troubleshooting a slow-running Delta Lake query on Databricks SQL involves complex joins and large datasets. They need to identify whether the root cause is related to poor data skipping, inefficient join strategies, or excessive data shuffling. Which approach should identify the specific bottlenecks using native Databricks tools?
- A. Use the LIMIT clause to run a subset of the query and compare execution times with the full dataset.
- B. Check the query's execution time in the Jobs UI and correlate it with cluster resource utilization metrics.
- C. Enable the EXPLAIN command to review the parsed logical plan and manually estimate shuffle sizes.
- D. Analyze the Top Operators panel in the Query Profile to identify high-cost operations like BroadcastNestedLoopJoin
Answer: D
Explanation:
The Query Profile's Top Operators panel surfaces the most expensive operators in the query execution, making it possible to directly identify bottlenecks such as inefficient join strategies, poor data skipping, or excessive shuffling. This native visualization highlights where time and resources are spent, enabling precise root-cause analysis for slow-running queries.
NEW QUESTION # 58
......
Our Databricks Certified Data Engineer Professional Exam study question has high quality. So there is all effective and central practice for you to prepare for your test. With our professional ability, we can accord to the necessary testing points to edit Databricks-Certified-Data-Engineer-Professional exam questions. With many years work experience, we have fast reaction speed to market change and need. In this way, we have the Latest Databricks-Certified-Data-Engineer-Professional Test Guide. You don’t worry about that how to keep up with the market trend, just follow us. In addition to the industry trends, the Databricks-Certified-Data-Engineer-Professional test guide is written by lots of past materials’ rigorous analyses.
Valid Databricks-Certified-Data-Engineer-Professional Test Pdf: https://www.actualvce.com/Databricks/Databricks-Certified-Data-Engineer-Professional-valid-vce-dumps.html
- 100% Pass 2026 Useful Databricks Databricks-Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional Exam Valid Exam Review ✏ Immediately open 「 www.verifieddumps.com 」 and search for ▛ Databricks-Certified-Data-Engineer-Professional ▟ to obtain a free download 🍺Authorized Databricks-Certified-Data-Engineer-Professional Exam Dumps
- 100% Pass Quiz Perfect Databricks - Databricks-Certified-Data-Engineer-Professional Valid Exam Review 👊 Search for 「 Databricks-Certified-Data-Engineer-Professional 」 on ➥ www.pdfvce.com 🡄 immediately to obtain a free download 🐒Databricks-Certified-Data-Engineer-Professional New Dumps Free
- Databricks-Certified-Data-Engineer-Professional Valid Exam Review - Realistic Valid Databricks Certified Data Engineer Professional Exam Test Pdf Pass Guaranteed Quiz 🍎 Enter ▷ www.vceengine.com ◁ and search for ✔ Databricks-Certified-Data-Engineer-Professional ️✔️ to download for free 🛑Authorized Databricks-Certified-Data-Engineer-Professional Test Dumps
- Reliable Test Databricks-Certified-Data-Engineer-Professional Test 📫 Databricks-Certified-Data-Engineer-Professional Demo Test 👮 Databricks-Certified-Data-Engineer-Professional Demo Test 🕸 Immediately open ➽ www.pdfvce.com 🢪 and search for ➤ Databricks-Certified-Data-Engineer-Professional ⮘ to obtain a free download 🧘Authorized Databricks-Certified-Data-Engineer-Professional Exam Dumps
- Databricks-Certified-Data-Engineer-Professional PDF Dumps Files 🚝 Databricks-Certified-Data-Engineer-Professional Exam Preview 🤺 Exam Databricks-Certified-Data-Engineer-Professional PDF 🔖 Simply search for ⏩ Databricks-Certified-Data-Engineer-Professional ⏪ for free download on ▶ www.dumpsmaterials.com ◀ 🤖Online Databricks-Certified-Data-Engineer-Professional Test
- Databricks-Certified-Data-Engineer-Professional Valid Exam Review - Free PDF Quiz Databricks-Certified-Data-Engineer-Professional - First-grade Valid Databricks Certified Data Engineer Professional Exam Test Pdf 🎊 Search for “ Databricks-Certified-Data-Engineer-Professional ” and download it for free immediately on ⮆ www.pdfvce.com ⮄ 🔨Online Databricks-Certified-Data-Engineer-Professional Test
- 100% Pass 2026 Useful Databricks Databricks-Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional Exam Valid Exam Review 🚻 Copy URL ( www.practicevce.com ) open and search for 《 Databricks-Certified-Data-Engineer-Professional 》 to download for free 🎇Databricks-Certified-Data-Engineer-Professional Exam Preview
- Databricks-Certified-Data-Engineer-Professional Test Pdf 🅿 Databricks-Certified-Data-Engineer-Professional Exam Preview 👉 Preparation Databricks-Certified-Data-Engineer-Professional Store 🐩 Open ✔ www.pdfvce.com ️✔️ enter ➤ Databricks-Certified-Data-Engineer-Professional ⮘ and obtain a free download 🦳Databricks-Certified-Data-Engineer-Professional Authorized Exam Dumps
- Databricks-Certified-Data-Engineer-Professional Authorized Exam Dumps 🦼 Valid Study Databricks-Certified-Data-Engineer-Professional Questions 📧 Databricks-Certified-Data-Engineer-Professional Test Result 🛒 Open ✔ www.exam4labs.com ️✔️ enter ➽ Databricks-Certified-Data-Engineer-Professional 🢪 and obtain a free download 🧹Databricks-Certified-Data-Engineer-Professional Test Result
- Databricks-Certified-Data-Engineer-Professional Demo Test 🍢 Dumps Databricks-Certified-Data-Engineer-Professional Vce 🍗 Databricks-Certified-Data-Engineer-Professional Demo Test ☀ Download ☀ Databricks-Certified-Data-Engineer-Professional ️☀️ for free by simply entering [ www.pdfvce.com ] website 🏣Databricks-Certified-Data-Engineer-Professional Demo Test
- Databricks Databricks-Certified-Data-Engineer-Professional Practice Test - Overcome Your Mistakes And Build Confidence 😘 Search for [ Databricks-Certified-Data-Engineer-Professional ] and download exam materials for free through ⏩ www.prepawayete.com ⏪ ⚖Valid Test Databricks-Certified-Data-Engineer-Professional Braindumps
- www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, justpaste.me, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes