Exam Databricks-Certified-Professional-Data-Engineer Braindumps & Databricks-Certified-Professional-Data-Engineer New Real Exam

BONUS!!! Download part of VCEDumps Databricks-Certified-Professional-Data-Engineer dumps for free: https://drive.google.com/open?id=16DIecqyY06lEJTEeqazXPzysvtNm-ZNA
Let me be clear here a core value problem of VCEDumps. All Databricks exams are very important. In this era of rapid development of information technology, VCEDumps just one of the questions providers. Why do most people to choose VCEDumps ? Because the VCEDumps exam information will be able to help you pass the test. It provides the information which is up to date. With VCEDumps Databricks Databricks-Certified-Professional-Data-Engineer Test Questions, you will become full of confidence and not have to worry about the exam. However, it lets you get certified effortlessly.
| Section | Weight | Objectives |
|---|
| Data Transformation, Cleansing, and Quality | 10% | - Handling missing or inconsistent data
- Standardization and normalization
- Data validation and quality checks
|
| Data Governance | 7% | - Unity Catalog management
- Data lineage and metadata tracking
- Policy enforcement
|
| Data Ingestion & Acquisition | 7% | - Schema inference and evolution
- Auto Loader and streaming ingestion
- Connecting to diverse data sources
|
| Cost & Performance Optimisation | 13% | - Storage optimization (partitioning, Z-order, indexing)
- Cluster configuration and scaling
- Query optimization and caching
|
| Data Modelling | 6% | - Schema design and management
- Delta Lake table design
- Medallion Architecture implementation
|
| Developing Code for Data Processing using Python and SQL | 22% | - Batch and incremental processing logic
- Data transformation and aggregation
- Integration with Databricks APIs and tools
|
| Data Sharing and Federation | 5% | - Cross-workspace and cross-cloud access
- Unity Catalog data sharing
|
| Debugging and Deploying | 10% | - CI/CD and DevOps practices
- Troubleshooting pipelines and errors
- Deployment using bundles, CLI, and APIs
|
| Monitoring and Alerting | 10% | - Performance and health monitoring
- Pipeline observability and logging
- Setting up alerts and notifications
|
| Ensuring Data Security and Compliance | 10% | - Access control and permissions
- Data encryption and masking
- Compliance standards implementation
|
>> Exam Databricks-Certified-Professional-Data-Engineer Braindumps <<
Pass Guaranteed 2026 Databricks Perfect Databricks-Certified-Professional-Data-Engineer: Exam Databricks Certified Professional Data Engineer Exam Braindumps
Moreover, you do not need an active internet connection to utilize VCEDumps desktop Databricks Certified Professional Data Engineer Exam practice exam software. It works without the internet after software installation on Windows computers. The VCEDumps web-based Databricks Databricks-Certified-Professional-Data-Engineer Practice Test requires an active internet and it is compatible with all operating systems.
Databricks Certified Professional Data Engineer Exam Sample Questions (Q88-Q93):
NEW QUESTION # 88
Which configuration parameter directly affects the size of a spark-partition upon ingestion of data into Spark?
- A. spark.sql.files.maxPartitionBytes
- B. spark.sql.adaptive.advisoryPartitionSizeInBytes
- C. spark.sql.adaptive.coalescePartitions.minPartitionNum
- D. spark.sql.autoBroadcastJoinThreshold
- E. spark.sql.files.openCostInBytes
Answer: A
Explanation:
This is the correct answer because spark.sql.files.maxPartitionBytes is a configuration parameter that directly affects the size of a spark-partition upon ingestion of data into Spark. This parameter configures the maximum number of bytes to pack into a single partition when reading files from file-based sources such as Parquet, JSON and ORC. The default value is 128 MB, which means each partition will be roughly 128 MB in size, unless there are too many small files or only one large file. Verified Reference: [Databricks Certified Data Engineer Professional], under "Spark Configuration" section; Databricks Documentation, under "Available Properties - spark.sql.files.maxPartitionBytes" section.
NEW QUESTION # 89
What statement is true regarding the retention of job run history?
- A. It is retained for 30 days, during which time you can deliver job run logs to DBFS or S3
- B. It is retained for 60 days, after which logs are archived
- C. It is retained for 90 days or until the run-id is re-used through custom run configuration
- D. t is retained for 60 days, during which you can export notebook run results to HTML
- E. It is retained until you export or delete job run logs
Answer: D
NEW QUESTION # 90
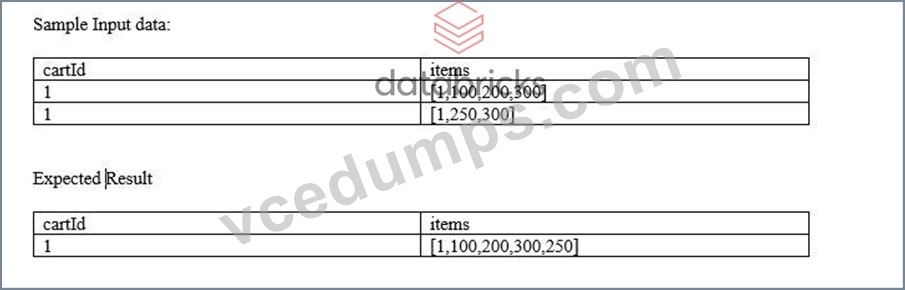
Below sample input data contains two columns, one cartId also known as session id, and the second column is called items, every time a customer makes a change to the cart this is stored as an array in the table, the Marketing team asked you to create a unique list of item's that were ever added to the cart by each customer, fill in blanks by choosing the appropriate array function so the query produces below expected result as shown below.
Schema: cartId INT, items Array<INT>
Sample Data
1.SELECT cartId, ___ (___(items)) as items
2.FROM carts GROUP BY cartId
Expected result:
cartId items
1 [1,100,200,300,250]
- A. FLATTEN, COLLECT_UNION
- B. ARRAY_DISTINCT, ARRAY_UNION
- C. ARRAY_UNION, ARRAY_DISTINT
- D. ARRAY_UNION, FLATTEN
- E. ARRAY_UNION, COLLECT_SET
Answer: E
Explanation:
Explanation
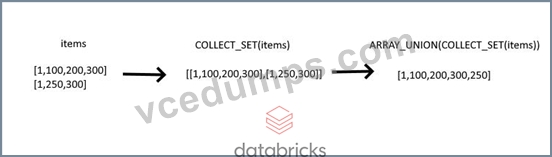
COLLECT SET is a kind of aggregate function that combines a column value from all rows into a unique list ARRAY_UNION combines and removes any duplicates, Graphical user interface, application Description automatically generated with medium confidence
NEW QUESTION # 91
The following code has been migrated to a Databricks notebook from a legacy workload:
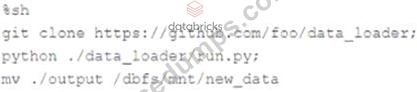
The code executes successfully and provides the logically correct results, however, it takes over 20 minutes to extract and load around 1 GB of data.
Which statement is a possible explanation for this behavior?
- A. %sh executes shell code on the driver node. The code does not take advantage of the worker nodes or Databricks optimized Spark.
- B. Instead of cloning, the code should use %sh pip install so that the Python code can get executed in parallel across all nodes in a cluster.
- C. %sh does not distribute file moving operations; the final line of code should be updated to use %fs instead.
- D. %sh triggers a cluster restart to collect and install Git. Most of the latency is related to cluster startup time.
- E. Python will always execute slower than Scala on Databricks. The run.py script should be refactored to Scala.
Answer: A
Explanation:
https://www.databricks.com/blog/2020/08/31/introducing-the-databricks-web-terminal.html The code is using %sh to execute shell code on the driver node. This means that the code is not taking advantage of the worker nodes or Databricks optimized Spark. This is why the code is taking longer to execute. A better approach would be to use Databricks libraries and APIs to read and write data from Git and DBFS, and to leverage the parallelism and performance of Spark. For example, you can use the Databricks Connect feature to run your Python code on a remote Databricks cluster, or you can use the Spark Git Connector to read data from Git repositories as Spark DataFrames.
NEW QUESTION # 92
A nightly job ingests data into a Delta Lake table using the following code:
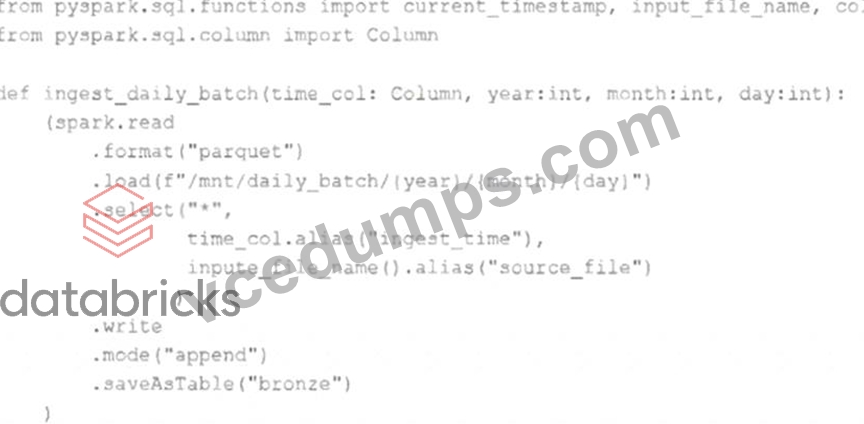
The next step in the pipeline requires a function that returns an object that can be used to manipulate new records that have not yet been processed to the next table in the pipeline.
Which code snippet completes this function definition?
def new_records():
- A. return spark.readStream.load("bronze")
- B. return spark.readStream.table("bronze")
- C.
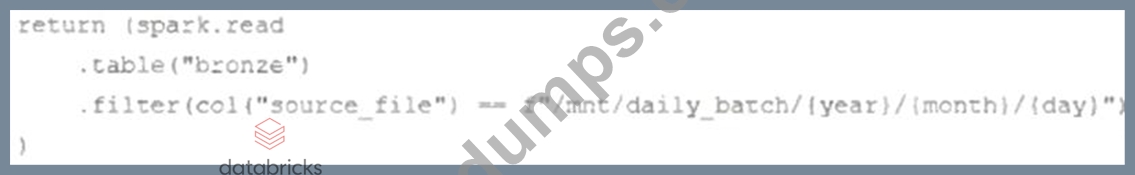
- D. return spark.read.option("readChangeFeed", "true").table ("bronze")
- E.
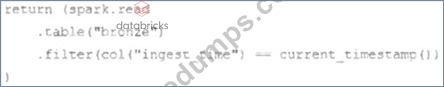
Answer: C
Explanation:
https://docs.databricks.com/en/delta/delta-change-data-feed.html
NEW QUESTION # 93
......
You can use this Databricks-Certified-Professional-Data-Engineer simulation software without an internet connection after installation. Tracking and reporting features of our Databricks Databricks-Certified-Professional-Data-Engineer practice exam software makes it easier for you to identify and overcome mistakes. Customization feature of this format allows you to change time limits and questions numbers of mock exams.
Databricks-Certified-Professional-Data-Engineer New Real Exam: https://www.vcedumps.com/Databricks-Certified-Professional-Data-Engineer-examcollection.html
- Databricks-Certified-Professional-Data-Engineer Reliable Practice Questions 🏇 Valid Databricks-Certified-Professional-Data-Engineer Exam Test 🍪 Valid Braindumps Databricks-Certified-Professional-Data-Engineer Files 🛴 Download [ Databricks-Certified-Professional-Data-Engineer ] for free by simply searching on ✔ www.examcollectionpass.com ️✔️ 🤢Databricks-Certified-Professional-Data-Engineer Valid Braindumps
- Databricks-Certified-Professional-Data-Engineer Vce File 🐎 Trustworthy Databricks-Certified-Professional-Data-Engineer Pdf ☢ Databricks-Certified-Professional-Data-Engineer Exam Objectives Pdf ➰ Search for 「 Databricks-Certified-Professional-Data-Engineer 」 and easily obtain a free download on ▛ www.pdfvce.com ▟ ⛺New Databricks-Certified-Professional-Data-Engineer Exam Practice
- 100% Pass 2026 Exam Databricks-Certified-Professional-Data-Engineer Braindumps - Realistic Databricks Certified Professional Data Engineer Exam New Real Exam 🚝 Search for ✔ Databricks-Certified-Professional-Data-Engineer ️✔️ on ⇛ www.pdfdumps.com ⇚ immediately to obtain a free download 🚴Databricks-Certified-Professional-Data-Engineer Exam Objectives Pdf
- The Best Exam Databricks-Certified-Professional-Data-Engineer Braindumps | Professional Databricks-Certified-Professional-Data-Engineer New Real Exam: Databricks Certified Professional Data Engineer Exam ⛰ Search on ➤ www.pdfvce.com ⮘ for ▛ Databricks-Certified-Professional-Data-Engineer ▟ to obtain exam materials for free download 🎨Databricks-Certified-Professional-Data-Engineer Test Result
- Pass-Sure Exam Databricks-Certified-Professional-Data-Engineer Braindumps offer you accurate New Real Exam | Databricks Certified Professional Data Engineer Exam 🎾 Simply search for ☀ Databricks-Certified-Professional-Data-Engineer ️☀️ for free download on ▷ www.dumpsmaterials.com ◁ ⏫Latest Databricks-Certified-Professional-Data-Engineer Braindumps Questions
- Why Do You Need to Trust Databricks Databricks-Certified-Professional-Data-Engineer Exam Questions? 📓 Search for ➠ Databricks-Certified-Professional-Data-Engineer 🠰 and easily obtain a free download on ⇛ www.pdfvce.com ⇚ 🔟Databricks-Certified-Professional-Data-Engineer Testking Exam Questions
- Databricks-Certified-Professional-Data-Engineer Practice Engine 🙁 Valid Databricks-Certified-Professional-Data-Engineer Exam Test 🔊 Databricks-Certified-Professional-Data-Engineer Valid Braindumps ⚜ Open website ▛ www.practicevce.com ▟ and search for ▷ Databricks-Certified-Professional-Data-Engineer ◁ for free download 💎Interactive Databricks-Certified-Professional-Data-Engineer Questions
- Databricks-Certified-Professional-Data-Engineer Valid Mock Test 💱 Valid Databricks-Certified-Professional-Data-Engineer Exam Test 🔏 Databricks-Certified-Professional-Data-Engineer PDF Dumps Files 🧝 ➽ www.pdfvce.com 🢪 is best website to obtain ⮆ Databricks-Certified-Professional-Data-Engineer ⮄ for free download 🕊Databricks-Certified-Professional-Data-Engineer Latest Braindumps
- Why Do You Need to Trust Databricks Databricks-Certified-Professional-Data-Engineer Exam Questions? 🔮 Easily obtain free download of ⏩ Databricks-Certified-Professional-Data-Engineer ⏪ by searching on ➠ www.practicevce.com 🠰 🎫Trustworthy Databricks-Certified-Professional-Data-Engineer Pdf
- Prep in an Amazing Way with Valid Databricks Databricks-Certified-Professional-Data-Engineer Dumps 🛌 Search for 《 Databricks-Certified-Professional-Data-Engineer 》 and download exam materials for free through 「 www.pdfvce.com 」 🤥Databricks-Certified-Professional-Data-Engineer Latest Braindumps
- Databricks-Certified-Professional-Data-Engineer Test Result 🛴 Databricks-Certified-Professional-Data-Engineer Reliable Practice Questions 🐝 Trustworthy Databricks-Certified-Professional-Data-Engineer Pdf 😀 Enter ( www.pass4test.com ) and search for ▛ Databricks-Certified-Professional-Data-Engineer ▟ to download for free 💗Valid Databricks-Certified-Professional-Data-Engineer Exam Test
- www.stes.tyc.edu.tw, blogfreely.net, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, Disposable vapes
BTW, DOWNLOAD part of VCEDumps Databricks-Certified-Professional-Data-Engineer dumps from Cloud Storage: https://drive.google.com/open?id=16DIecqyY06lEJTEeqazXPzysvtNm-ZNA