DOWNLOAD the newest Getcertkey DP-100 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1YCmbg0MOiPGK61zy1W9d2V-nLaMCTY5t
Rely on Getcertkey’s easy DP-100 Questions Answers that can give you first time success with 100% money back guarantee! Thousands of professional have already been benefited with the marvelous DP-100 and have obtained their dream certification. There is no complication involved; the exam questions and answers are simple and rewarding for every candidate. Getcertkey’s experts have employed their best efforts in creating the questions and answers; hence they are packed with the relevant and the most updated information you are looking for.
Microsoft DP-100 (Designing and Implementing a Data Science Solution on Azure) Certification Exam is a highly sought-after certification exam for data scientists and professionals looking to validate their skills in designing and implementing data science solutions on the Azure cloud platform. DP-100 Exam measures a candidate's ability to design and implement solutions that use Azure services to support data scientists in building, training, and deploying machine learning models.
If you buy our DP-100 practice engine, you can get rewords more than you can imagine. On the one hand, you can elevate your working skills after finishing learning our DP-100 study materials. On the other hand, you will have the chance to pass the exam and obtain the DP-100certificate, which can aid your daily work and get promotion. All in all, learning never stops! It is up to your decision now. Do not regret for you past and look to the future.
To nail DP-100, you will need to scrutinize the below-mentioned areas:
The first domain gives considerable attention to skills related to the Azure ML workspace. So, the test-takers have a chance to learn about workspace settings, the management of workspace using Azure ML, and registering in addition to maintaining the datastores.
The last segment is all about deployment and consumption models. Topics like evaluating compute options, creating production compute targets, batch inferencing pipeline creation, and running this pipeline efficiently are well covered within such a scope.
Using automated ML for the optimal model creation, hyperdrive to tune hyperparameters, model management, and knowing the crucial model explainers to interpret models are some of the key topics explained in this portion.
This objective imparts updated understanding about the concepts like creating models by using Azure ML Designer, custom code modules in Designer, defining a pipeline data flow, and an experiment running by using Azure Machine Learning SDK.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
NEW QUESTION # 245
You manage an Azure Machine Learning workspace named workspace1 and a Data Science Virtual Machine (DSVM) named DSMV1.
You must an experiment in DSMV1 by using a Jupiter notebook and Python SDK v2 code. You must store metrics and artifacts in workspace 1 You start by creating Python SCK v2 code to import ail required packages.
You need to implement the Python SOK v2 code to store metrics and article in workspace1.
Which three actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them the correctly order.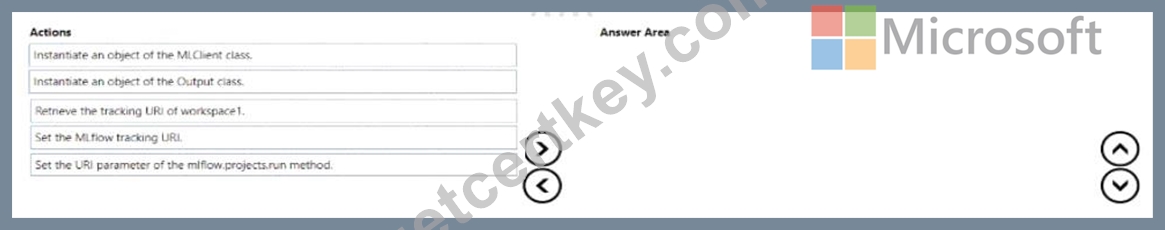
Answer:
Explanation: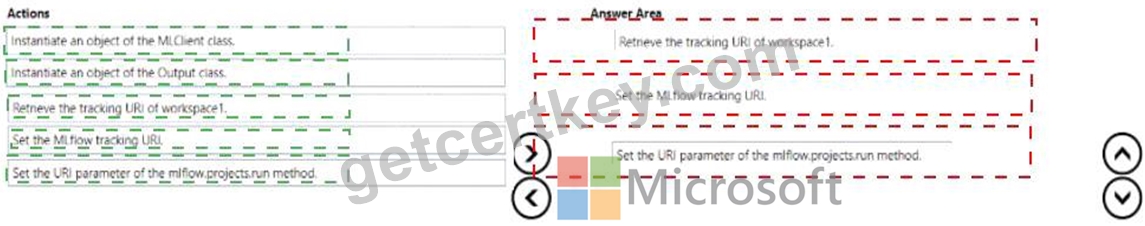
Explanation: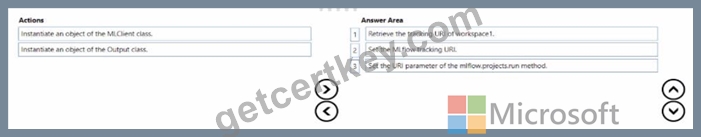
NEW QUESTION # 246
You create an Azure Machine Learning workspace. You use the Azure Machine Learning Python SDK v2 to create a compute cluster.
The compute cluster must run a training script. Costs associated with running the training script must be minimized.
You need to complete the Python script to create the compute cluster.
How should you complete the script? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.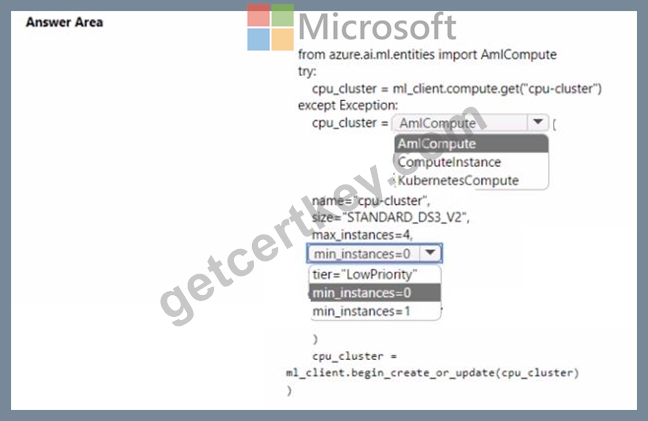
Answer:
Explanation: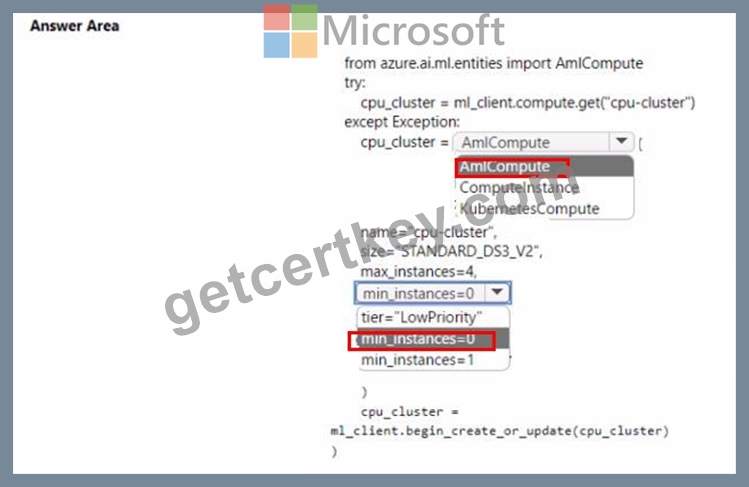
NEW QUESTION # 247
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You train a classification model by using a logistic regression algorithm.
You must be able to explain the model's predictions by calculating the importance of each feature, both as an overall global relative importance value and as a measure of local importance for a specific set of predictions.
You need to create an explainer that you can use to retrieve the required global and local feature importance values.
Solution: Create a MimicExplainer.
Does the solution meet the goal?
Answer: B
Explanation:
Instead use Permutation Feature Importance Explainer (PFI).
Note 1: Mimic explainer is based on the idea of training global surrogate models to mimic blackbox models. A global surrogate model is an intrinsically interpretable model that is trained to approximate the predictions of any black box model as accurately as possible. Data scientists can interpret the surrogate model to draw conclusions about the black box model.
Note 2: Permutation Feature Importance Explainer (PFI): Permutation Feature Importance is a technique used to explain classification and regression models. At a high level, the way it works is by randomly shuffling data one feature at a time for the entire dataset and calculating how much the performance metric of interest changes. The larger the change, the more important that feature is. PFI can explain the overall behavior of any underlying model but does not explain individual predictions.
Reference:
https://docs.microsoft.com/en-us/azure/machine-learning/how-to-machine-learning-interpretability
NEW QUESTION # 248
You manage an Azure Machine Learning workspace named workspace1 by using the Python SDK v2.
You must register datastores in workspace1 for Azure Blob and Azure Data Lake Gen2 storage to meet the following requirements:
* Data scientists accessing the datastore must have the same level of access.
* Access must be restricted to specified containers or folders.
You need to configure a security access method used to register the Azure Blob and Azure Data lake Gen? storage in workspace1. Which security access method should you configure? To answer, select the appropriate options in the answers area.
NOTE: Each correct selection is worth one point.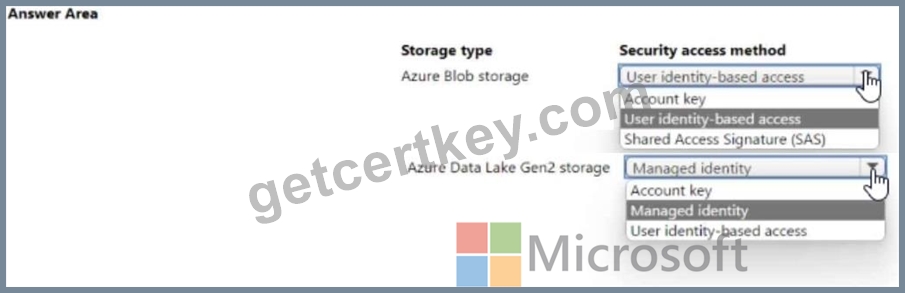
Answer:
Explanation: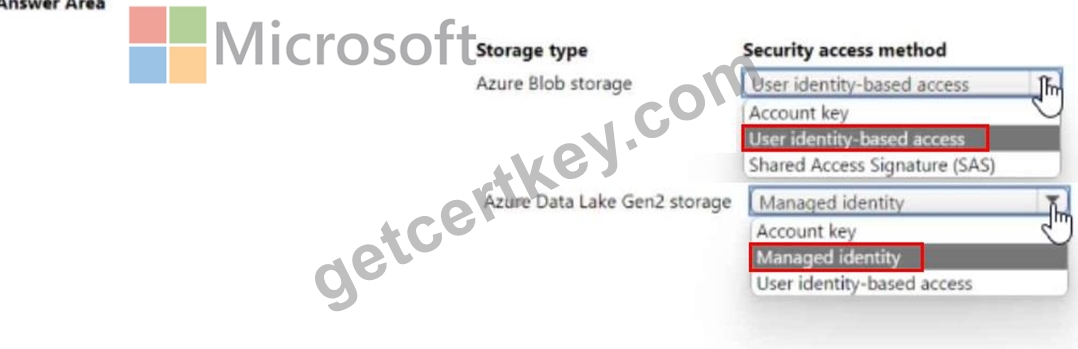
NEW QUESTION # 249
You create a machine learning model by using the Azure Machine Learning designer. You publish the model as a real-time service on an Azure Kubernetes Service (AKS) inference compute cluster. You make no change to the deployed endpoint configuration.
You need to provide application developers with the information they need to consume the endpoint.
Which two values should you provide to application developers? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
Answer: B,C
Explanation:
Deploying an Azure Machine Learning model as a web service creates a REST API endpoint. You can send data to this endpoint and receive the prediction returned by the model.
You create a web service when you deploy a model to your local environment, Azure Container Instances, Azure Kubernetes Service, or field-programmable gate arrays (FPGA). You retrieve the URI used to access the web service by using the Azure Machine Learning SDK. If authentication is enabled, you can also use the SDK to get the authentication keys or tokens.
Example:
# URL for the web service
scoring_uri = '<your web service URI>'
# If the service is authenticated, set the key or token
key = '<your key or token>'
Reference:
https://docs.microsoft.com/en-us/azure/machine-learning/how-to-consume-web-service
NEW QUESTION # 250
......
DP-100 Exam Discount: https://www.getcertkey.com/DP-100_braindumps.html
BTW, DOWNLOAD part of Getcertkey DP-100 dumps from Cloud Storage: https://drive.google.com/open?id=1YCmbg0MOiPGK61zy1W9d2V-nLaMCTY5t