If you're still learning from the traditional old ways and silently waiting for the test to come, you should be awake and ready to take the Databricks-Certified-Data-Engineer-Professional exam in a different way. Study our Databricks-Certified-Data-Engineer-Professional training materials to write "test data" is the most suitable for your choice, after recent years show that the effect of our Databricks-Certified-Data-Engineer-Professional Guide Torrent has become a secret weapon of the examinee through qualification examination, a lot of the users of our Databricks-Certified-Data-Engineer-Professional guide torrent can get unexpected results in the Databricks-Certified-Data-Engineer-Professional examination.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Data Sharing and Federation | 5% | - Implement Lakehouse Federation - Use Delta Sharing for secure data sharing - Manage cross-platform data access |
| Topic 2: Monitoring and Alerting | 10% | - Monitor pipeline performance and health - Set up alerts and notifications - Track data lineage and metrics |
| Topic 3: Ensuring Data Security and Compliance | 10% | - Ensure data privacy and compliance - Implement access control and permissions - Secure data at rest and in transit |
| Topic 4: Cost & Performance Optimisation | 13% | - Improve query and pipeline performance - Apply cost management best practices - Optimize compute and storage resources |
| Topic 5: Data Governance | 7% | - Use Unity Catalog for governance - Manage data assets and metadata - Enforce data policies and standards |
| Topic 6: Debugging and Deploying | 10% | - Troubleshoot and debug pipelines - Deploy using Asset Bundles, CLI, and APIs - Implement CI/CD and DevOps practices |
| Topic 7: Developing Code for Data Processing using Python and SQL | 22% | - Write efficient and maintainable code - Implement complex data processing logic - Use Databricks-specific libraries and APIs |
| Topic 8: Data Modelling | 6% | - Implement dimensional and relational models - Optimize table design and partitioning - Design Medallion Architecture |
| Topic 9: Data Ingestion & Acquisition | 7% | - Handle incremental and batch data loads - Ingest data from diverse sources - Use Auto Loader and structured streaming |
| Topic 10: Data Transformation, Cleansing, and Quality | 10% | - Enforce data quality standards - Implement schema evolution and management - Apply data cleansing and validation rules |
>> Test Databricks-Certified-Data-Engineer-Professional Questions Pdf <<
Our Databricks-Certified-Data-Engineer-Professional exam questions are compiled by experts and approved by the professionals with years of experiences. They are revised and updated according to the change of the syllabus and the latest development situation in the theory and practice. The language is easy to be understood which makes any learners have no obstacles and our Databricks-Certified-Data-Engineer-Professional Guide Torrent is suitable for anyone. The content is easy to be mastered and has simplified the important information. Our Databricks-Certified-Data-Engineer-Professional test torrents convey more important information with less questions and answers and thus make the learning relaxing and efficient.
NEW QUESTION # 66
A data architect has designed a system in which two Structured Streaming jobs will concurrently write to a single bronze Delta table. Each job is subscribing to a different topic from an Apache Kafka source, but they will write data with the same schema. To keep the directory structure simple, a data engineer has decided to nest a checkpoint directory to be shared by both streams.
The proposed directory structure is displayed below: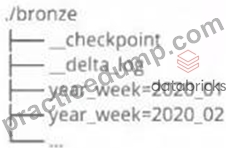
Which statement describes whether this checkpoint directory structure is valid for the given scenario and why?
Answer: D
Explanation:
This is the correct answer because checkpointing is a critical feature of Structured Streaming that provides fault tolerance and recovery in case of failures. Checkpointing stores the current state and progress of a streaming query in a reliable storage system, such as DBFS or S3. Each streaming query must have its own checkpoint directory that is unique and exclusive to that query. If two streaming queries share the same checkpoint directory, they will interfere with each other and cause unexpected errors or data loss.
NEW QUESTION # 67
Two of the most common data locations on Databricks are the DBFS root storage and external object storage mounted with dbutils.fs.mount().
Which of the following statements is correct?
Answer: B
Explanation:
DBFS is a file system protocol that allows users to interact with files stored in object storage using syntax and guarantees similar to Unix file systems. DBFS is not a physical file system, but a layer over the object storage that provides a unified view of data across different data sources. By default, the DBFS root is accessible to all users in the workspace, and the access to mounted data sources depends on the permissions of the storage account or container. Mounted storage volumes do not need to have full public read and write permissions, but they do require a valid connection string or access key to be provided when mounting. Both the DBFS root and mounted storage can be accessed when using %sh in a Databricks notebook, as long as the cluster has FUSE enabled. The DBFS root does not store files in ephemeral block volumes attached to the driver, but in the object storage associated with the workspace. Mounted directories will persist saved data to external storage between sessions, unless they are unmounted or deleted.
NEW QUESTION # 68
A data engineer is designing an append-only pipeline that needs to handle both batch and streaming data in Delta Lake. The team wants to ensure that the streaming component can efficiently track which data has already been processed. Which configuration should be set to enable this?
Answer: C
Explanation:
When working with Delta Lake streaming ingestion, checkpointing is critical for maintaining fault tolerance and ensuring exactly-once data processing semantics.
The checkpointLocation parameter defines the directory where Spark Structured Streaming stores progress information, offsets, and metadata. This allows the engine to resume processing from the last committed offset without reprocessing previously ingested data.
Without checkpointing, each stream restart would reprocess all data, leading to duplicates.
Parameters like partitionBy or schema options (mergeSchema / overwriteSchema) affect table structure, not data lineage tracking. Therefore, the correct and required configuration for efficient streaming state management is checkpointLocation.
NEW QUESTION # 69
The data engineering team has configured a Databricks SQL query and alert to monitor the values in a Delta Lake table. The recent_sensor_recordings table contains an identifying sensor_id alongside the timestamp and temperature for the most recent 5 minutes of recordings.
The below query is used to create the alert: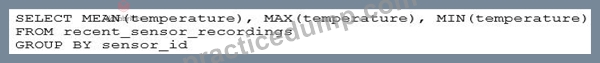
The query is set to refresh each minute and always completes in less than 10 seconds. The alert is set to trigger when mean (temperature) > 120. Notifications are triggered to be sent at most every 1 minute.
If this alert raises notifications for 3 consecutive minutes and then stops, which statement must be true?
Answer: C
Explanation:
This is the correct answer because the query is using a GROUP BY clause on the sensor_id column, which means it will calculate the mean temperature for each sensor separately. The alert will trigger when the mean temperature for any sensor is greater than 120, which means at least one sensor had an average temperature above 120 for three consecutive minutes. The alert will stop when the mean temperature for all sensors drops below 120.
NEW QUESTION # 70
A user wants to use DLT expectations to validate that a derived table report contains all records from the source, included in the table validation_copy.
The user attempts and fails to accomplish this by adding an expectation to the report table definition.
Which approach would allow using DLT expectations to validate all expected records are present in this table?
Answer: D
Explanation:
To validate that all records from the source are included in the derived table, creating a view that performs a left outer join between the validation_copy table and the report table is effective. The view can highlight any discrepancies, such as null values in the report table's key columns, indicating missing records. This view can then be referenced in DLT (Delta Live Tables) expectations for the report table to ensure data integrity. This approach allows for a comprehensive comparison between the source and the derived table.
NEW QUESTION # 71
......
The Databricks-Certified-Data-Engineer-Professional test torrent also offer a variety of learning modes for users to choose from, which can be used for multiple clients of computers and mobile phones to study online, as well as to print and print data for offline consolidation. Therefore, for your convenience, more choices are provided for you, we are pleased to suggest you to choose our Databricks-Certified-Data-Engineer-Professional Exam Question for your exam. So with our Databricks-Certified-Data-Engineer-Professional guide torrents, you are able to pass the exam more easily in the most efficient and productive way and learn how to study with dedication and enthusiasm, which can be a valuable asset in your whole life. It must be your best tool to pass your exam and achieve your target.
New Databricks-Certified-Data-Engineer-Professional Braindumps Free: https://www.practicedump.com/Databricks-Certified-Data-Engineer-Professional_actualtests.html