In order to show you how efficient our CCAR-P exam dump is, we allow you to download a demo version for free! You will have a chance to peak into the program and then make your final purchase decision. We are absolutely sure that once you see what’s inside, you will buy it immediately without any hesitation! CCAR-P Exam Dump also provide customer service, in case you have any inquiry or question, our professional Customer Support will be available for you 24/7. 365 days a Year.
| Section | Weight | Objectives |
|---|---|---|
| Governance, Safety & Risk Management | 14% | - Security and risk management - Ethical AI considerations - AI safety and guardrails - Human-in-the-loop validation - Regulatory and compliance requirements |
| Stakeholder Communication & Lifecycle Management | 14% | - Stakeholder management - Architecture documentation - Communicating architectural decisions - Discovery and requirements gathering - Solution lifecycle management - Service-level agreements |
| Developer Productivity & Operational Enablement | 7% | - Claude tooling configuration for teams - Debugging and operational issue resolution - AI-assisted developer workflows - Developer enablement |
| Solution Design & Architecture | 17% | - Translating business problems into Claude-based AI solutions - Decomposition techniques for complex problem solving - Alignment with business value, cost, performance, and SLAs - Architectural patterns
- Multi-agent systems and orchestration |
| Integration | 19% | - Authentication and authorization analysis - Enterprise system integration - Claude integration mechanisms
|
| Claude Models, Prompting & Context Engineering | 13% | - System prompts and prompt templates - Context window optimization - Claude model selection and trade-offs - Prompt reuse and context engineering strategies - Guardrails |
| Evaluation, Testing & Optimization | 16% | - Evaluation framework design - System issue diagnosis - Evaluation metrics and datasets - Cost and performance optimization - A/B testing - Production monitoring and optimization |
Our CCAR-P exam dumps strive for providing you a comfortable study platform and continuously explore more functions to meet every customer’s requirements. We may foresee the prosperous talent market with more and more workers attempting to reach a high level through the Anthropic certification. To deliver on the commitments of our CCAR-P test prep that we have made for the majority of candidates, we prioritize the research and development of our CCAR-P Test Braindumps, establishing action plans with clear goals of helping them get the Anthropic certification. You can totally rely on our products for your future learning path. Full details on our CCAR-P test braindumps are available as follows.
NEW QUESTION # 102
You are evaluating retrieval-strategy claims used by a peer team.
For each claim, select yes if the statement is generally accurate. Otherwise, select no.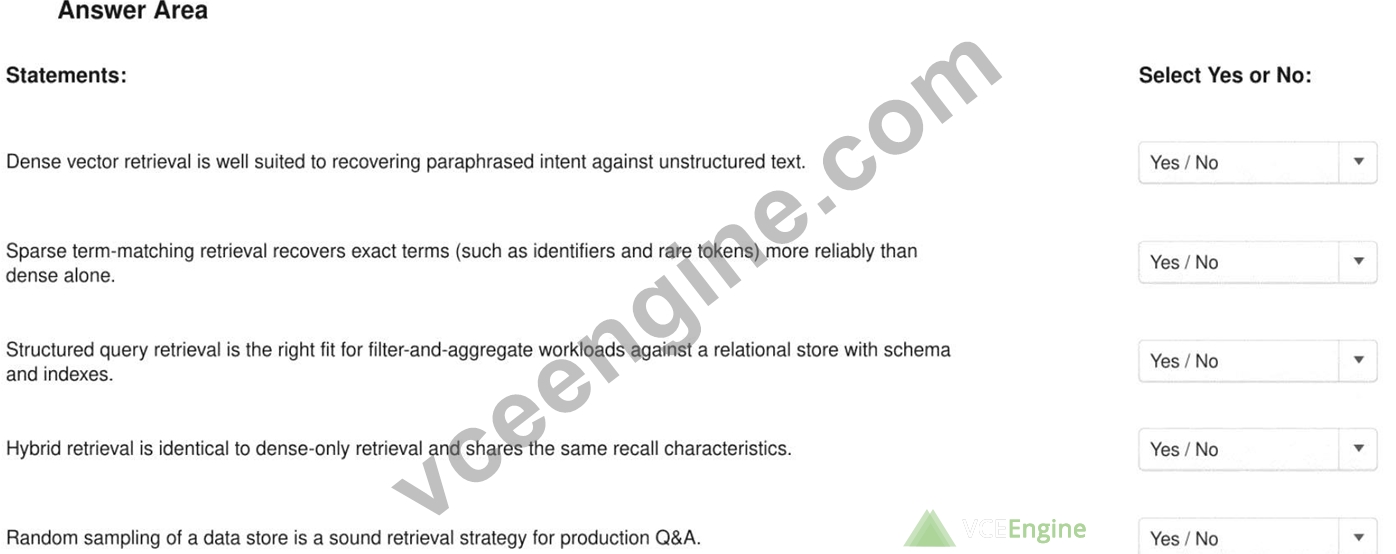
Answer:
Explanation: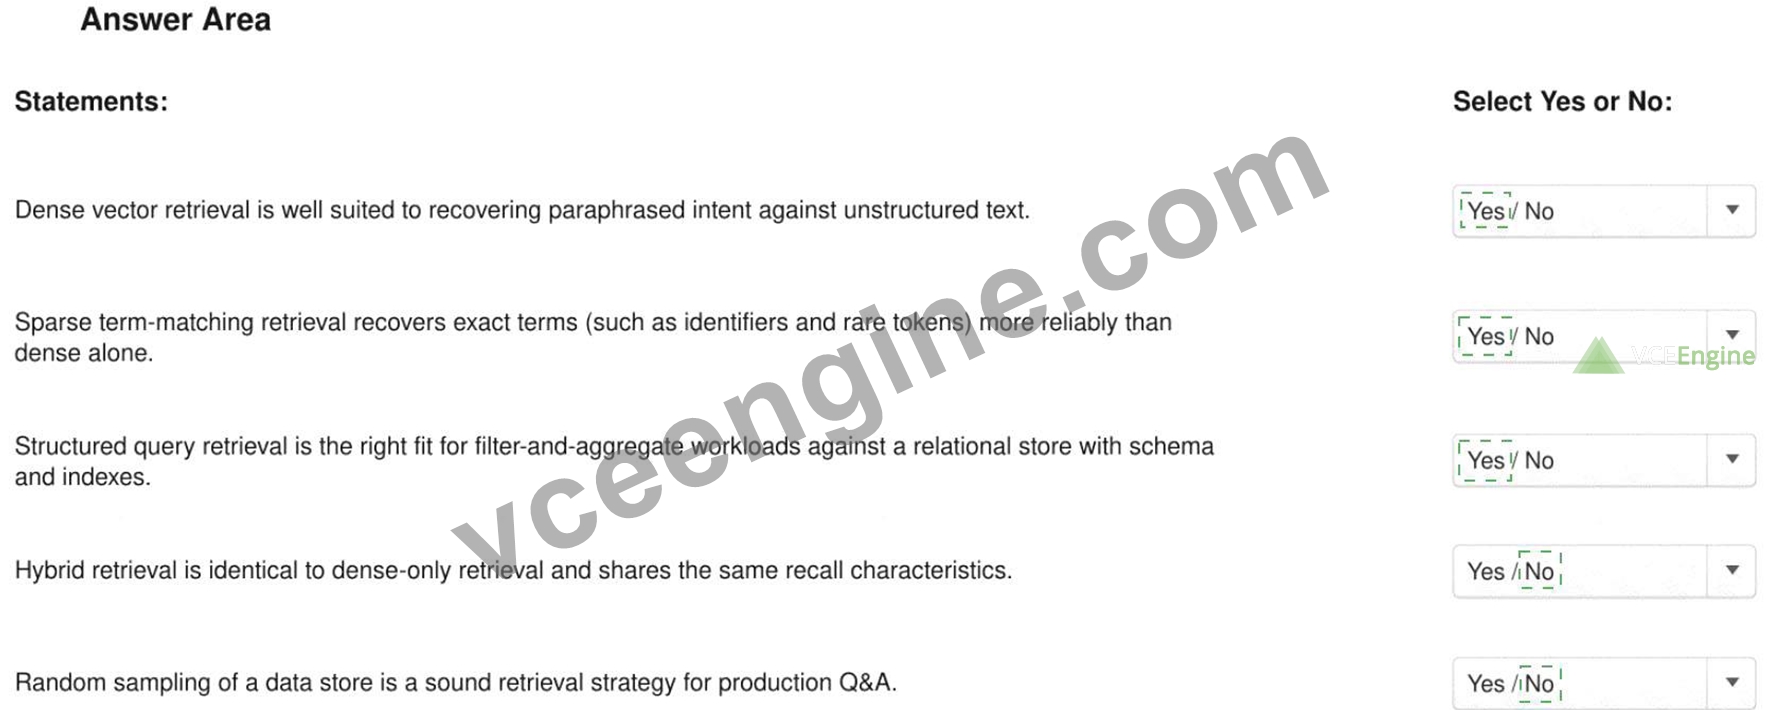
Explanation:
Yes, Yes, Yes, No, No
Dense vector retrieval represents semantic similarity, making it suitable for matching paraphrases and conceptually related language even when the query and source do not share identical words. Sparse lexical retrieval, including BM25-style matching, retains strong sensitivity to exact tokens and is therefore valuable for identifiers, product codes, technical names, and uncommon terminology.
Structured query retrieval is appropriate when the required operation depends on explicit fields, predicates, joins, counts, grouping, or aggregation over a relational schema. In that situation, generating or invoking a constrained database query is more precise than approximating the operation through semantic similarity.
Hybrid retrieval is not identical to dense retrieval. It combines semantic and lexical candidate sets, typically followed by rank fusion or reranking. Anthropic's contextual-retrieval guidance explains that semantic search captures meaning and paraphrases, while BM25 captures exact terminology; combining them improves coverage. Contextual Retrieval , Contextual Retrieval Cookbook Random sampling is not a relevance strategy. It provides no systematic relationship between the query and selected evidence, producing unstable coverage and preventable hallucination risk. Production Q & A requires deterministic or evaluated relevance mechanisms, access filters, suitable indexes, and measurable retrieval metrics such as recall at k .
Study Guide references/topics: Dense retrieval; sparse retrieval; structured queries; hybrid search; rank fusion; retrieval evaluation; production RAG design.
NEW QUESTION # 103
A Claude architect is leading the discovery phase for a new AI-powered customer service solution.
Which two activities are characteristic of structured discovery and requirement gathering for a Claude-based deployment? (Select two.)
Answer: B,C
Explanation:
Structured discovery begins by eliciting constraints from the people who own the business outcome, operate the process, manage risk, and will use or support the deployed system. Stakeholder workshops in Option A identify measurable expectations concerning accuracy, latency, throughput, cost, privacy, compliance, escalation, and acceptable failure behavior before the solution is scoped.
Option D converts those expectations into production gates. Success criteria must be explicit enough to evaluate empirically, while failure thresholds must determine when the design requires remediation, human review, or rejection. Anthropic's evaluation guidance states that successful LLM applications begin with defined success criteria and evaluations that measure performance against them. It characterizes strong criteria as specific, measurable, achievable, and relevant. Define Success Criteria and Build Evaluations Option B prematurely selects a model before the workload profile is known. Option C can supplement discovery, but reaction-driven prototyping cannot replace documented requirements and acceptance criteria.
Option E postpones essential constraints until architectural commitments may already have been made.
The discovery output should create traceability from stakeholder objectives to requirements, evaluation metrics, architecture decisions, and deployment gates.
Study Guide references/topics: Structured discovery; stakeholder workshops; nonfunctional requirements; success criteria; failure thresholds; production readiness gates.
NEW QUESTION # 104
A Claude architect observes that after a recent model-version upgrade, grounded responses began including claims not supported by the retrieved source documents.
Which mitigation is most directly targeted at this failure mode?
Answer: C
Explanation:
The observed failure is a groundedness defect: the response contains claims that cannot be traced to retrieved evidence. Option A directly constrains generation to the supplied sources, requires visible attribution, and verifies that each material claim has supporting text. Unsupported claims should be removed, qualified, or replaced with an explicit statement that the available sources are insufficient. Regression evaluation in Option B may detect the failure but does not itself prevent unsupported claims. OAuth addresses identity and authorization, while input classifiers address malicious or unsafe retrieved content; neither verifies factual support. Anthropic recommends citations, supporting quotations, and post-generation claim verification to reduce hallucinations in document-grounded applications. Reducing hallucinations
NEW QUESTION # 105
You are comparing patterns for a batch document-classification job that follows fixed steps: extract metadata, classify, summarize, and persist.
Which pattern is the best fit and why?
Answer: B
Explanation:
A workflow is appropriate when processing stages and transitions are known in advance. Metadata extraction, classification, summarization, and persistence can be represented as deterministic nodes with explicit schemas, validation rules, retry policies, and failure handling. This provides predictable execution, cost, observability, and testability without paying for repeated model-driven planning. Anthropic's Building Effective AI Agents distinguishes workflows, where predefined code paths control execution, from agents, where the model dynamically determines its process. Option A reaches the correct pattern for an incorrect reason: workflows and agents can both invoke tools. Options B and C introduce unnecessary autonomy and make unsupported claims about consistency or universal accuracy.
Study Guide references/topics: Workflow versus agentic patterns; deterministic orchestration; batch processing; structured outputs; predictable cost; error handling.
NEW QUESTION # 106
You are diagnosing a Claude Code session whose subagent uses 50,000 tokens of context before the engineer types a single message.
Which root cause is most likely?
Answer: C
Explanation:
Claude Code constructs the model context before the first user message. That initial context can include the system prompt, project instructions, subagent configuration, MCP server instructions, and tool definitions expressed as JSON schemas. When numerous MCP servers expose many tools and Tool Search is disabled, those schemas must be loaded upfront. A large collection of verbose tool descriptions and parameter schemas can therefore consume tens of thousands of tokens before the engineer enters any text.
Tool Search is specifically designed to prevent this form of context inflation. With Tool Search enabled, Claude initially receives only server instructions and compact tool-identification information; full tool schemas are deferred until a relevant tool is discovered and required. Anthropic consequently describes Tool Search as the mechanism for keeping MCP context consumption low as integrations scale.
Keyboard layouts, font rendering, and display scaling operate outside the language-model context and cannot generate API input tokens. Likewise, model behavior does not silently reserve 50,000 tokens for personal preferences. The diagnostic action is to inspect configured MCP servers and tool counts, determine whether Tool Search has been disabled, and remove or defer unnecessary definitions.
Study Guide references/topics: [MCP Tool Search and context scaling](https://docs.anthropic.com/en/docs
/claude-code/mcp); MCP server configuration; subagent context budgeting; tool-schema optimization.
NEW QUESTION # 107
......
We are amenable to offer help by introducing our CCAR-P real exam materials and they can help you pass the Claude Certified Architect - Professional practice exam efficiently. All knowledge is based on the real exam by the help of experts. By compiling the most important points of questions into our CCAR-P guide prep our experts also amplify some difficult and important points. There is no doubt they are clear-cut and easy to understand to fulfill your any confusion about the exam. Our Claude Certified Architect - Professional exam question is applicable to all kinds of exam candidates who eager to pass the exam. Last but not the least, they help our company develop brand image as well as help a great deal of exam candidates pass the exam with passing rate over 98 percent of our CCAR-P Real Exam materials.
CCAR-P Test Engine: https://www.vceengine.com/CCAR-P-vce-test-engine.html