In addition to the Snowflake SPS-C01 PDF dumps, we also offer Snowflake Certified SnowPro Specialty - Snowpark practice exam software. You will find the same ambiance and atmosphere when you attempt the real Snowflake Certified SnowPro Specialty - Snowpark exam. It will make you practice nicely and productively as you will experience better handling of the Snowflake SPS-C01 Questions when you take the actual Snowflake SPS-C01 exam to grab the Snowflake SPS-C01 certification.
| Section | Objectives |
|---|---|
| Testing, Debugging, and Deployment | - Production readiness
|
| DataFrame Operations and Data Processing | - Data transformation workflows
|
| Performance Optimization and Best Practices | - Efficient Snowpark execution
|
| User Defined Functions and Stored Procedures | - Extending Snowpark with custom logic
|
| Snowpark Fundamentals | - Snowpark architecture and concepts
|
| Data Engineering with Snowpark | - Pipeline development
|
Passing the SPS-C01 exam requires the ability to manage time effectively. In addition to the Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) exam study materials, practice is essential to prepare for and pass the Snowflake SPS-C01 exam on the first try. It is critical to do self-assessment and learn time management skills. Because the SPS-C01 test has a restricted time constraint, time management must be exercised to get success. Only with enough practice one can answer real Snowflake SPS-C01 exam questions in a given amount of time.
NEW QUESTION # 69
You are developing a Snowpark application to ingest a large dataset into Snowflake. You have a DataFrame with a schema that matches the target table 'TARGET TABLE. Due to network constraints, you need to optimize the insertion process to minimize the number of API calls. Which of the following approaches would provide the MOST efficient way to insert the data?
Answer: B
Explanation:
The most efficient approach is option C: 'data_df.insert_into('TARGET_TABLE')'. This method leverages Snowpark's optimized data transfer mechanisms and performs bulk insertion using the underlying Snowflake engine which minimizes api calls and faster to insert the data. Option A is highly inefficient due to the overhead of constructing and executing individual SQL statements. Option B introduces Pandas, which is slower. Option D involves additional staging steps. Option E is manual chunking which is also slower.
NEW QUESTION # 70
You are using Snowpark Python to transform a large DataFrame containing customer transaction data'. You need to persist the resulting DataFrame as a new Snowflake table named 'CUSTOMER TRANSACTIONS AGGREGATED', replacing the existing table if it exists. You want to explicitly define the schema of the new table to ensure data types are correctly enforced. Which of the following code snippets achieves this most efficiently and correctly?





Answer: E
Explanation:
Option A is the simplest and most direct way to achieve the desired outcome using the method with the 'overwrite' mode. While defining the schema is important, Snowflake infers the schema from the DataFrame if not explicitly provided. If schema inference isn't working, it should be investigated as a separate issue. Option B requires an intermediary view, which is less efficient. Options C and D are not valid Snowpark options. While you can specify file format related options (e.g. CSV options when writing to cloud storage), 'table_type' isn't one of them. Option E introduces the concept of schema definition, which, while important in general, is unnecessary if Snowflake can infer the correct schema. The question asks for the most efficient and correct answer, which is A.
NEW QUESTION # 71
You are developing a Snowpark Python application that reads data from an external stage (AWS S3) and performs several transformations before loading it into a Snowflake table. During testing, you encounter the following error: net.snowflake.client.jdbc.SnowflakeSQLException: SQL compilation error: User does not have OWNERSHIP privilege on integration object 'YOUR INTEGRATION NAME". You have confirmed that the user has the 'USAGE privilege on the integration. Besides granting ownership, which of the following actions could resolve this issue in the MOST secure and efficient way?
Answer: B
Explanation:
Option B is the MOST secure and efficient. The error indicates that the user lacks necessary privileges to utilize the integration for creating objects (in this case, likely an internal stage used during the transformation process). Granting a custom role with both 'USAGE on the integration and 'CREATE TABLE on the database adheres to the principle of least privilege. Option A grants broad privileges to the user, which is less secure. Option C involves complex integration setup and might not be necessary for a simple data loading scenario. Option D is related to reading data from the external stage, not using the integration for internal operations. Option E bypasses the error without addressing the underlying permission issue.
NEW QUESTION # 72
You are developing a Snowpark application that needs to connect to Snowflake using account identifiers. Your organization's Snowflake account is configured with federated authentication (Okta). Which of the following methods is the most secure and recommended way to establish a Snowpark session in this scenario, avoiding hardcoding credentials in your application and leveraging existing authentication mechanisms?
Answer: D
Explanation:
Using OAuth with an external identity provider like Okta is the most secure and recommended method for federated authentication. It avoids storing credentials directly in the application and leverages the organization's existing authentication mechanisms. Options A, B, and D are less secure due to the risk of exposing credentials. Option E does not address the federated authenication requirment.
NEW QUESTION # 73
Consider the following Snowpark code snippet that aims to calculate the rank of each employee based on their salary within their respective department. What are potential issues with this code, and how can you improve it? (Select all that apply.)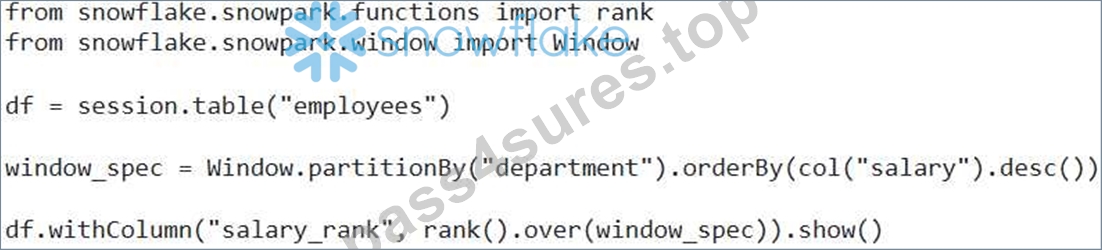
Answer: A,B,C
Explanation:
Options B, D, and E are correct. B: The 'orderBy' clause needs the 'col' function call in D: Null values in the salary column can lead to unexpected ranking results, and should be addressed beforehand. E: Applying window functions on very large DataFrames can be resource-intensive, so filtering data beforehand can improve performance. Option A is incorrect because there are indeed issues with the code. Option C: 'rank()' function does not produce dense ranks. function is used for contiguous ranks.
NEW QUESTION # 74
......
The hit rate for SPS-C01 exam guide is as high as 99%. Obviously such positive pass rate will establish you confidence as well as strengthen your will to pass your SPS-C01 exam. No other vendors can challenge our data in this market. At the same time, by studying with our SPS-C01 practice materials, you avoid wasting your precious time on randomly looking for the key point information. We provide a smooth road for you to success.
Valid SPS-C01 Exam Camp Pdf: https://www.pass4sures.top/Snowflake-Certification/SPS-C01-testking-braindumps.html