BONUS!!! 免費下載PDFExamDumps DEA-C02考試題庫的完整版:https://drive.google.com/open?id=1lDxhFLMulBEPlji9uLA9OLr-e1MAkH_6
用一下PDFExamDumps的DEA-C02考古題怎麼樣?這個考古題可以說是與DEA-C02考試相關的所有參考資料中最優秀的資料。為什麼呢?有以下四個理由。第一,PDFExamDumps的考古題是IT專家們運用他們多年的經驗研究出來的資料,可以準確地劃出考試出題的範圍。第二,PDFExamDumps的考古題包含了可能出現在實際考試中的所有試題。第三,PDFExamDumps的考古題保證考生一次就通過考試,如果考生考試失敗則全額退款。第四,PDFExamDumps的考古題分為PDF版和軟體版兩個版本。利用這兩個版本的考古題,考生可以更輕鬆地準備考試。
| Section | Objectives |
|---|---|
| Topic 1: Data Transformation and Processing | - SQL-based transformations in Snowflake - Streams and Tasks for ELT pipelines - Handling semi-structured data (JSON, Avro, Parquet) |
| Topic 2: Performance and Optimization | - Clustering and partition strategies - Query optimization techniques - Warehouse sizing and scaling |
| Topic 3: Data Engineering Fundamentals | - Data pipelines concepts and patterns - Snowflake architecture for data engineering |
| Topic 4: Data Ingestion and Integration | - Batch and streaming ingestion approaches - Snowpipe usage and automation - Staging data and loading mechanisms |
| Topic 5: Security and Data Governance | - Secure data sharing - Role-based access control (RBAC) - Data masking and encryption |
如何才能快速的通過 DEA-C02 考試呢?下麵給你推薦 PDFExamDumps 考古題,我們的 Snowflake 的 DEA-C02 考試培訓資料是以PDF和軟體格式提供,它包含 DEA-C02 考試的試題及答案,而剛剛上線的 Snowflake DEA-C02 題庫是考生需要重點把握和瞭解的。也只有在看書和看資料的基礎上認真地做 Snowflake DEA-C02 真題,才能使複習達到事半功倍的效果。
問題 #140
You are responsible for monitoring the performance of a Snowflake data pipeline that loads data from S3 into a Snowflake table named 'SALES DATA. You notice that the COPY INTO command consistently takes longer than expected. You want to implement telemetry to proactively identify the root cause of the performance degradation. Which of the following methods, used together, provide the MOST comprehensive telemetry data for troubleshooting the COPY INTO performance?
答案:B,E
解題說明:
To comprehensively troubleshoot COPY INTO performance, you need data on the copy operation itself (COPY HISTORY), overall account and data validation. The COPY_HISTORY view provides details about each COPY INTO execution, including the file size, load time, and any errors encountered. Query profiling offers detailed insight into the internal operations of the COPY INTO command, revealing bottlenecks. Monitoring S3 for throttling ensures that the data source isn't limiting performance. Using helps correlate storage growth with load times. LOAD_HISTORY doesn't exist, 'VALIDATE function is for data validation not performance. While warehouse CPU utilization is useful, it doesn't provide the specific details needed to diagnose COPY INTO issues. External network monitoring is also less relevant than checking for S3 throttling and analyzing Snowflake's internal telemetry data.
問題 #141
You are tasked with creating a UDTF in Snowflake to perform a complex data transformation that requires external libraries (e.g., for advanced string manipulation or data analysis). The transformation involves cleaning and standardizing addresses from a table containing millions of customer records. Which language and approach would be most appropriate and efficient for this scenario?
答案:A
解題說明:
Python UDTFs with Anaconda packages offer the best balance of flexibility, performance, and ease of use for complex data transformations requiring external libraries. Snowflake's integration with Anaconda allows for the seamless use of popular data science and engineering libraries, making Python UDTFs ideal for tasks like address standardization. Java can be useful, but the overhead of JAR management and potentially less efficient integration with Snowflake's execution engine can be a disadvantage. SQL and JavaScript offer limited expressiveness for complex tasks requiring external libraries. While Scala is powerful, it can present a steeper learning curve and may not be as widely adopted as Python within the Snowflake ecosystem for UDTFs.
問題 #142
You have a Snowpark Python application that performs complex calculations on a large dataset stored in Snowflake. The application is currently running slowly. After profiling, you've identified that the UDFs you're using are the bottleneck. These UDFs perform custom data transformations using a third-party Python library which has a significant initialization overhead. Which of the following strategies would be MOST effective to optimize performance, minimizing both runtime and resource consumption?
答案:E
解題說明:
Option C is the most effective. 'pandas_udf with 'vectorized=True' allows processing data in batches using pandas DataFrames, significantly reducing the overhead of invoking the UDF for each row. Pre-initializing the library within the UDF's closure avoids repeated initialization. Increasing warehouse size (A) might help but is not as targeted. UDF caching (B) only helps if the inputs are identical and doesn't address the initialization overhead. Rewriting in SQL (D) might not be feasible if the third-party library is essential. Converting to Java (E) could help, but optimizing the Python code first is generally a better starting point.
問題 #143
You have a table named 'ORDERS' with a column 'ORDER DETAILS' that contains JSON data'. You want to extract a specific nested value ('customer id') from this JSON data using a SQL UDE The JSON structure varies, and sometimes the 'customer id' field might be missing. You need to create a UDF that handles missing fields gracefully and returns NULL if 'customer id' is not found. Also, You are looking for a performant solution that is highly scalable. Which of the following SQL UDF definitions is most appropriate?





答案:A
解題說明:
Option B is the most appropriate because it uses 'NVL' to explicitly handle the case where is NULL, returning NULL in such cases. This prevents errors and ensures graceful handling of missing data. Option A would result in an error if the key doesn't exist in the JSON. Option C is more verbose but also handles NULLs, but NVL provides a more concise solution and it doesnt handle invalid JSON structures. Option D uses 'PARSE JSON' on a 'VARCHAR input, which is less efficient than using 'VARIANT' directly. Option E: TRY_PARSE_JSON returns NULL, and cant get to customer_id. This question tests understanding of JSON handling, NULL handling, and performance considerations when working with semi-structured data in Snowflake UDFs. It also requires knowledge on the appropriate data type to define UDF arguments and expected return type.
問題 #144
A data engineer is working with a Snowpark DataFrame 'sales df containing sales data with columns 'product id', 'sale_date', and 'sale amount'. The engineer needs to calculate the cumulative sales amount for each product over time. Which of the following code snippets using window functions correctly calculates the cumulative sales amount, ordered by 'sale date'?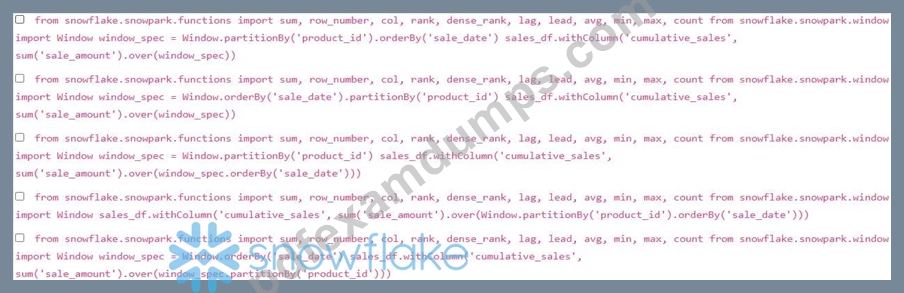
答案:C,E
解題說明:
Options A and D are correct. They both correctly define a window specification partitioned by 'product_id' and ordered by 'sale_date' . Both options then calculate the cumulative sum of 'sale_amount over this window. Option A defines the window and applies it to the dataframe whereas Option D applies it to the dataframe in one step. Options B and E are incorrect because the order of partitionBy and orderBy is incorrect when setting the window specification. Option C is incorrect as it does not apply a window function after the orderBy.
問題 #145
......
一直想要提升自身的你,有沒有參加DEA-C02認證考試的計畫呢?如果你想參加這個考試,你準備怎麼準備考試呢?也許你已經找到了適合自己的參考資料了。那麼,什麼資料有讓你選擇的價值呢?你選擇的是不是PDFExamDumps的DEA-C02考古題?如果是的話,那麼你就不用再擔心不能通過考試了。
DEA-C02最新試題: https://www.pdfexamdumps.com/DEA-C02_valid-braindumps.html
P.S. PDFExamDumps在Google Drive上分享了免費的2026 Snowflake DEA-C02考試題庫:https://drive.google.com/open?id=1lDxhFLMulBEPlji9uLA9OLr-e1MAkH_6