Confronting a tie-up during your review of the exam? Feeling anxious and confused to choose the perfect AB-620 Latest Dumps to pass it smoothly? We understand your situation of susceptibility about the exam, and our AB-620 test guide can offer timely help on your issues right here right now. Without tawdry points of knowledge to remember, our experts systematize all knowledge for your reference. You can download our free demos and get to know synoptic outline before buying.
| Section | Weight | Objectives |
|---|---|---|
| Build and extend agents in Copilot Studio | 40–45% | - Develop agent flows and logic
|
| Test, deploy, and manage agents | 20–25% | - Deploy and manage agent lifecycle
|
| Plan and configure agent solutions | 30–35% | - Plan an agent solution
|
If you start to prapare for the AB-620 exam from books, then you will find that the content is too broad for you to cope with the exam questions. So, we just pick out the most important knowledge to learn. Through large numbers of practices, you will soon master the core knowledge of the AB-620 Exam. It is important to review the questions you always choose mistakenly. You should concentrate on finishing all exercises once you are determined to pass the AB-620 exam. And you will pass for sure as long as you study with our AB-620 study guide carefully.
NEW QUESTION # 89
Hotspot Question
You run multiple evaluation tests for an agent in Copilot Studio before expanding user access.
The tests provide the following results:
- Each evaluation case is reported as meeting or missing the expected
response.
- Some evaluation cases fail repeatedly across several runs.
- Each run displays the expected response and the response generated by the agent.
You need to provide a conclusion based on the evaluation results.
Which conclusions should you make? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.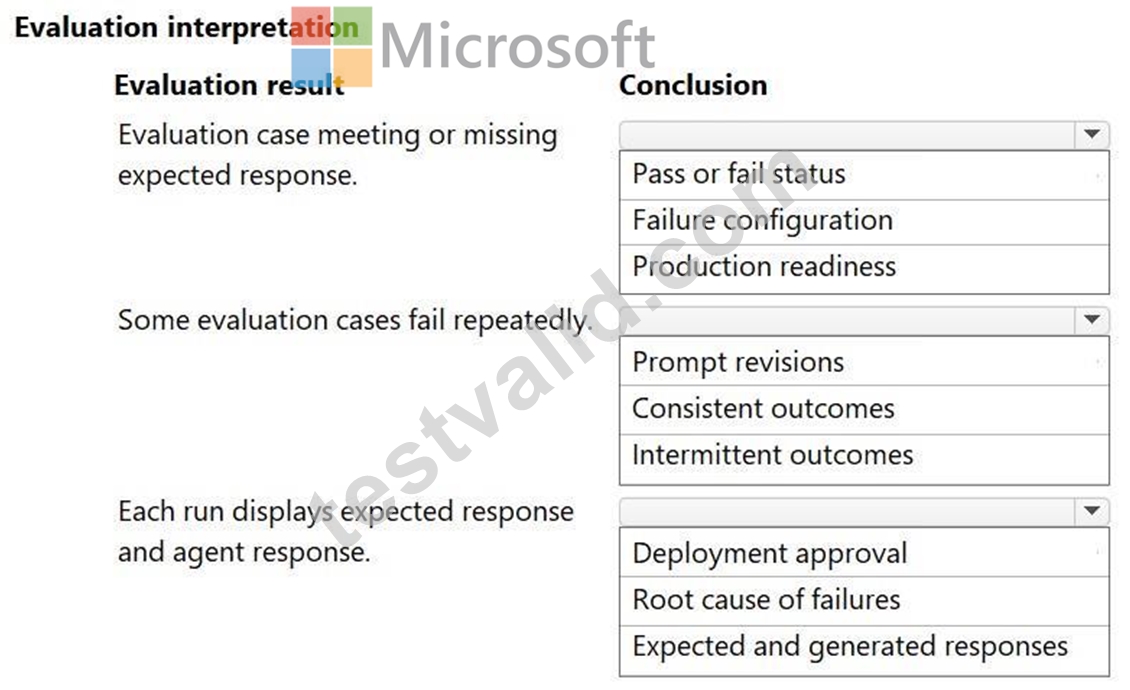
Answer:
Explanation: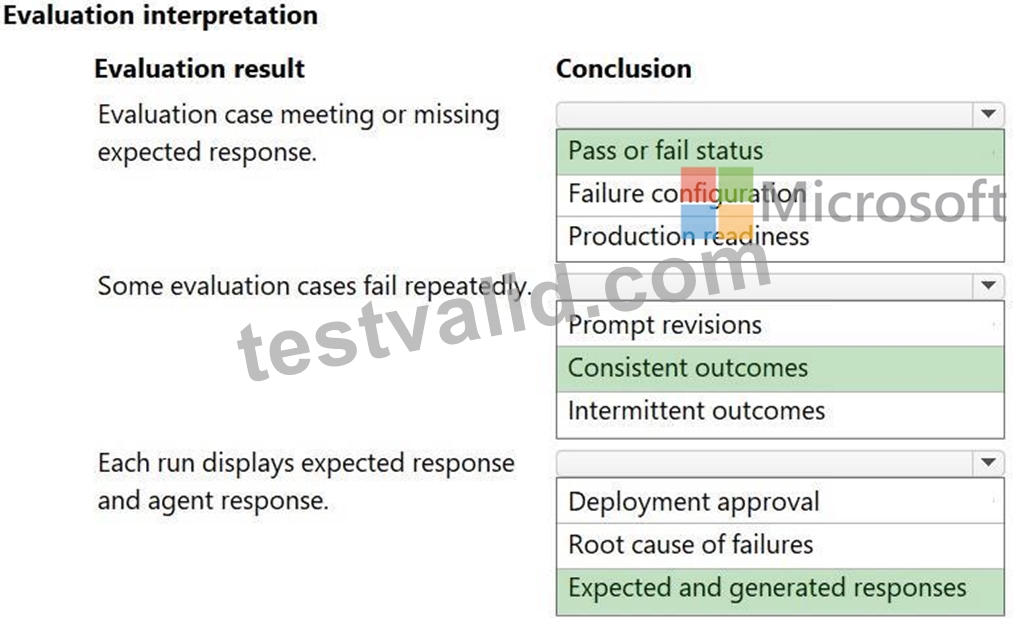
Explanation:
Box 1: Pass or fail status
Based on the testing criteria in Microsoft Copilot Studio, the outcome described directly measures the Pass or fail status of your tests.
Pass or fail status: This is the primary conclusion. Microsoft Copilot Studio Agent Evaluation uses structured methods (such as Exact Match, Similarity, or Compare Meaning) to objectively check if your agent met or missed the expected responses in your test set.
Box 2: Consistent outcomes
The conclusion to make from this is Consistent outcomes.
When evaluation test cases fail repeatedly across several runs, it indicates a stable, reproducible issue with the agent's behavior rather than random variability. Because the agent produces the same failure under the same test conditions, you have consistent outcomes.
Box 3: Expected and generated response
From the multiple evaluation tests in Microsoft Copilot Studio, the primary conclusion you can make is regarding the expected and generated responses.
This specific test output allows you to directly assess the alignment between what the AI was anticipated to say (the expected response) and what it actually produced (the generated response). By contrasting these, you can analyze semantic similarity, intent, and overall quality.
Reference:
https://www.microsoft.com/en-us/microsoft-copilot/blog/copilot-studio/how-to-evaluate-ai-agents/
NEW QUESTION # 90
A team uses environment variables to separate configuration from an agent so that the same solution can be moved between environments.
The team requires the following scenarios to be addressed:
An administrator updates a sensitive configuration value and needs the change to take effect at runtime without republishing the agent.
A builder needs to confirm a configuration value but must not be able to modify it from Copilot Studio.
An administrator updates a non-secret configuration value and needs the updated value to be used by the published agent at runtime.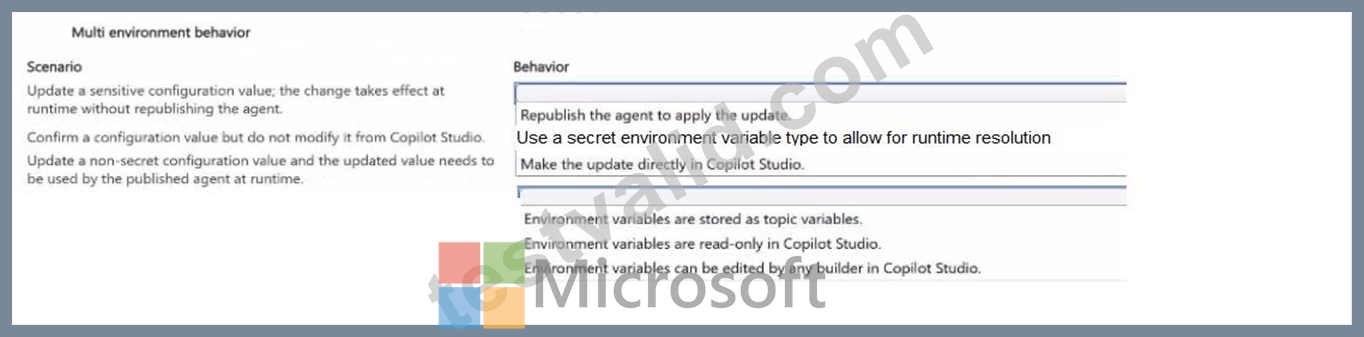
Answer:
Explanation: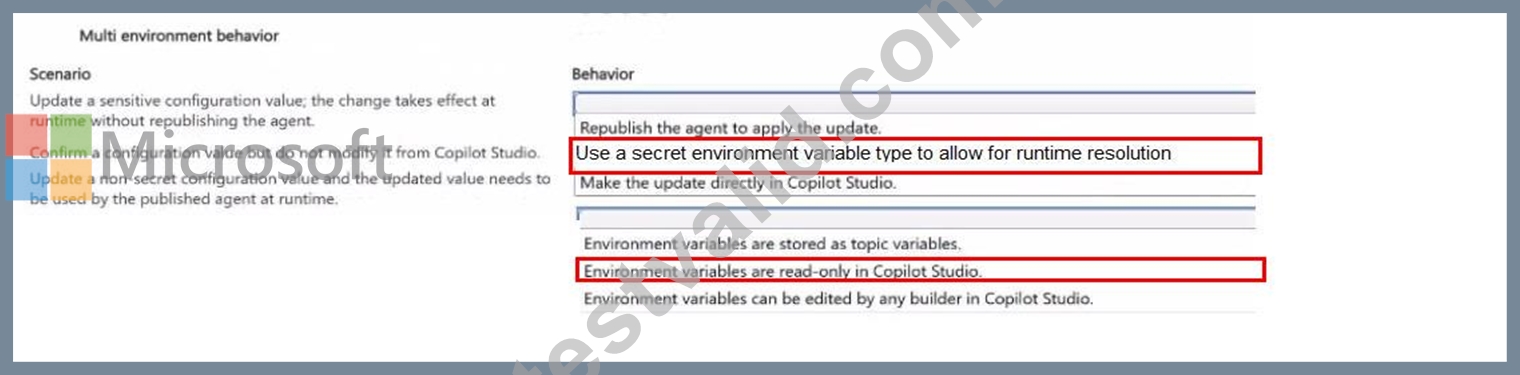
NEW QUESTION # 91
Drag and Drop Question
You run the same fixed test set three times in Copilot Studio.
During evaluation, you observe the following:
- The same interaction fails in all three runs.
- Score values range from 0.58 to 0.61.
- The reasoning states that the response partially matches the expected answer.
- The knowledge source that is used is internal documentation.
- No tools are invoked.
You need to determine which conclusions are supported based on the evaluation results.
Which conclusions should you make? To answer, move the appropriate conclusions to the correct evaluation results. You may use each conclusion once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.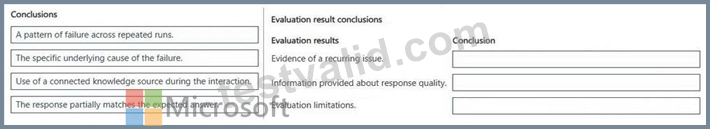
Answer:
Explanation: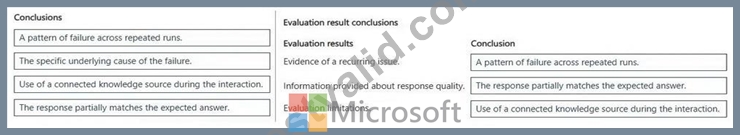
Explanation:
Box 1: A pattern failure across repeated runs.
The correct conclusion concerning evidence of a recurring issue is a) a pattern failure across repeated runs.
When the exact same interaction fails across three repeated runs, it establishes a systemic, predictable pattern rather than an isolated, one-time anomaly.
Box 2: The response partially matches the expected answer.
Based on the evaluation criteria in Microsoft Copilot Studio, the most definitive and direct conclusion that can be made concerning response quality is that the response partially matches the expected answer.
Direct Evidence: The evaluation results explicitly state in the reasoning that the "response partially matches the expected answer." This directly provides a qualitative conclusion regarding the quality of the generated response.
Score Alignment: The semantic similarity or quality score values ranging from 0.58 to 0.61 align with a partial match. In AI evaluation metrics, a perfect match is represented by 1.0, while values in the 0.6x range indicate that the core context was captured but lacked full completeness or exactness.
Box 3: Use of a connected knowledge source during the interaction
Because generative AI outputs are non-deterministic, running the same test set across a dynamic environment can yield varying scores. In Microsoft Copilot Studio, observing scores consistently between 0.58 and 0.61 points to a fundamental limitation with the underlying knowledge source.
The evaluation points to option use of a connected knowledge source during the interaction.
Because no tools are invoked, the agent heavily relies on generative search (retrieval-augmented generation) over internal documentation. The score range and reasoning indicate that the agent successfully retrieves a document but relies on a probabilistic model to paraphrase or assemble the response, which results in a "partial match" rather than an exact extraction.
Incorrect:
In contrast, specific underlying causes require explicit tool invocations or system error logs to diagnose, which are not present here.
Reference:
https://learn.microsoft.com/en-us/microsoft-copilot-studio/analytics-agent-evaluation-results
NEW QUESTION # 92
A company uses an agent flow that occasionally requires human input before continuing execution.
Some automated actions must pause until a human provides a decision or additional information. The flow must be configured to:
* Capture a human response for use in later steps.
* Continue processing within the same flow run after the response is submitted.
* Wait for a manual decision before proceeding.
You need to configure a human-in-the-loop agent flow.
Which setting should you configure for each requirement? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.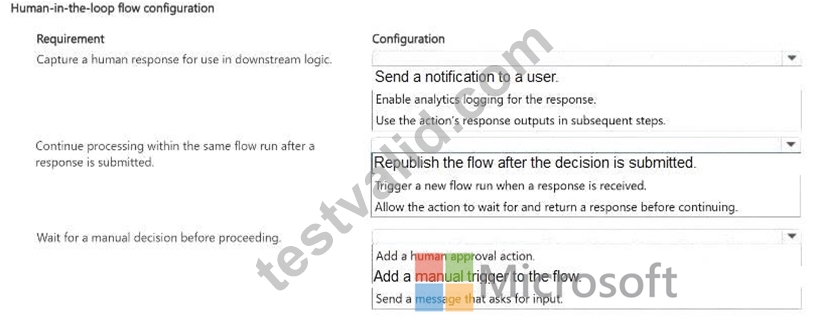
Answer:
Explanation: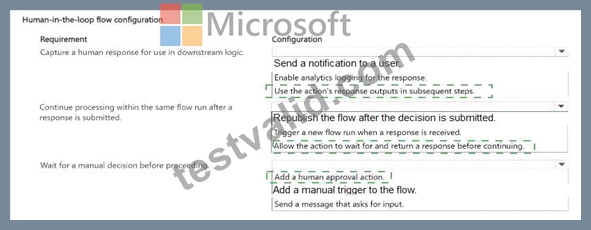
Explanation:
Capture response # Use the action ' s response outputs in later steps; Continue the same run # Allow the action to wait for and return a response before continuing; Require a manual decision # Add a human approval action.
Comprehensive and Detailed Explanation From Microsoft AB-620 Study Guide: A human-in-the-loop flow must preserve execution state while it waits. The approval or information action pauses the current run and returns a response when the designated person acts; triggering a new flow would lose that direct continuation contract. The response outputs-decision, comments, supplied fields, responder, and timestamps as applicable-are then referenced by downstream conditions and actions. A human approval action provides the explicit decision gate required before processing continues. Sending a notification or message alone does not wait and cannot guarantee that the decision controls the flow. The designer should configure expiration, escalation, reassignment, and rejection paths so the run cannot remain suspended without governance.
Responses should be validated before use, and sensitive values should be protected in variables and history.
Test approval, rejection, timeout, duplicate response, and unauthorized response scenarios. These controls ensure that human oversight changes execution deterministically instead of acting as an informational side channel. Study Guide alignment: Plan and configure agent solutions > Create and monitor agent flows in Copilot Studio > Create a human-in-the-loop agent flow.
NEW QUESTION # 93
A company requires an agent in Copilot Studio to answer questions using content stored in a third-party knowledge base system and reuse that content for knowledge grounding.
The agent must ground answers using indexed enterprise knowledge from a non-Microsoft system.
You need to choose the correct integration approach.
What should you use?
Answer: C
Explanation:
Adding a Copilot connector is the correct approach to index and ground an agent using authorized non-Microsoft enterprise knowledge.
Integration and Configuration
Indexing data: Copilot connectors (formerly Microsoft Graph connectors) sync and index external data sources into Microsoft Graph.
Adding knowledge: Open your agent in Microsoft Copilot Studio, go to the Overview, Knowledge, or Properties page, and select Add knowledge.
Selecting the source: Choose your configured Copilot connector from the dialog menu and select Add to agent.
Key Benefits
Security: Respects source-level permissions so users only see content they are authorized to access.
Grounding: Reduces AI hallucinations by anchoring replies directly in trusted business data.
Reference:
https://learn.microsoft.com/en-us/microsoft-copilot-studio/knowledge-copilot-connectors
NEW QUESTION # 94
......
Cease to struggle and you cease to live. Only by continuous learning can we not be surpassed by others. Many people do not like to study and think that learning is a very vexing thing. This kind of cognition makes their careers stagnate. AB-620 test question will change your perception. AB-620 learning dumps aim to help students learn easily and effectively that has been developed over many years by many industry experts. For the online version, unlike other materials that limit one person online, AB-620 learning dumps does not limit the number of concurrent users and the number of online users. You can practice anytime, anywhere, practice repeatedly, practice with others, and even purchase together with othersAB-620 learning dumps make every effort to help you save money and effort, so that you can pass the exam with the least cost.
AB-620 Vce Free: https://www.testvalid.com/AB-620-exam-collection.html