We will provide you with three different versions of our AI-300 exam questions on our test platform: PDF, software and APP versions. The three different versions will offer you same questions and answers, but they have different functions. You can choose any one version of our AI-300 guide torrent. For example, if you need to use our products in an offline state, you can choose the online version; if you want to try to simulate the real examination, you can choose the software. In a word, the three different versions of our AI-300 Test Torrent will help you pass the AI-300 exam.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Design and implement a GenAIOps infrastructure | 20–25% | - Implement infrastructure for generative AI workloads
|
| Topic 2: Design and implement an MLOps infrastructure | 15–20% | - Create and manage Machine Learning workspace resources and assets
|
| Topic 3: Optimize generative AI systems and model performance | 15–20% | - Improve efficiency and cost-effectiveness
|
| Topic 4: Implement generative AI quality assurance and observability | 10–15% | - Monitor generative AI systems
|
| Topic 5: Implement machine learning model lifecycle and operations | 25–30% | - Orchestrate model training and experimentation
|
>> AI-300 Latest Exam Materials <<
It is known to us that our AI-300 learning materials have been keeping a high pass rate all the time. There is no doubt that it must be due to the high quality of our study materials. It is a matter of common sense that pass rate is the most important standard to testify the AI-300 training files. The high pass rate of our study materials means that our products are very effective and useful for all people to pass their AI-300 Exam and get the related certification. So if you buy the AI-300 study questions from our company, you will get the certification in a shorter time.
NEW QUESTION # 41
Hotspot Question
You manage an Azure Machine Learning workspace by using the Python SDK v2.
You must create an automated machine learning job to generate a classification model by using data files stored in Parquet format. You must configure an autoscaling compute target and a data asset for the job.
You need to configure the resources for the job.
Which resource configuration should you use? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.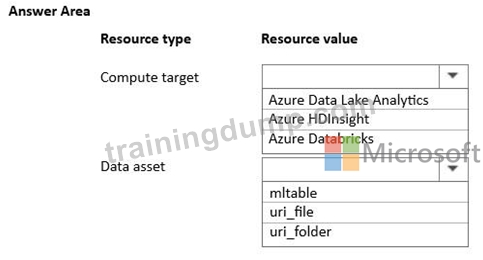
Answer:
Explanation: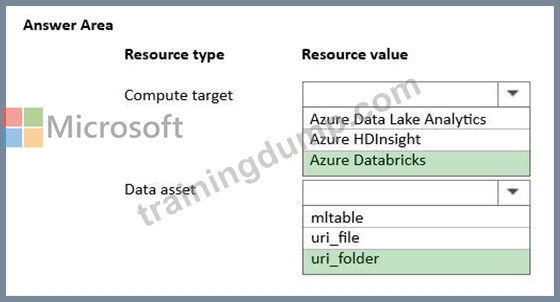
Explanation:
Box 1: Azure Databricks
Autoscaling: Out of the provided choices, Azure Databricks is the only compute target that natively supports the automated scaling up and down of worker nodes required to efficiently match the computation demands of your specific job.
Compatibility: Azure HDInsight and Azure Data Lake Analytics are legacy analytics platforms that do not offer the same direct, optimized, and auto-scaling compute integration within Azure ML SDK v2 pipelines for AutoML training.
Box 2: uri_folder
Directory access: Since your data consists of multiple data files stored in the Parquet format, pointing your asset type to a uri_folder allows the training job to automatically read and ingest all individual Parquet partition files stored inside that directory.
Reference:
https://github.com/Azure/MachineLearningNotebooks/blob/master/how-to-use-azureml/azure-databricks/automl/automl-databricks-local-01.ipynb
NEW QUESTION # 42
Drag and Drop Question
You develop a Prompt flow in Microsoft Foundry project.
You plan to use variants and invoke a custom API in the flow.
You need to add tools to the flow that will implement the planned functionality. Your solution must minimize development efforts.
Which tools should you use? To answer, move the appropriate tools to the correct functionalities.
You may use each tool once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.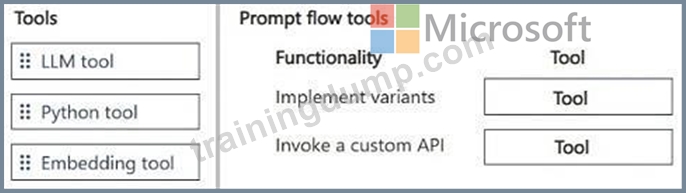
Answer:
Explanation: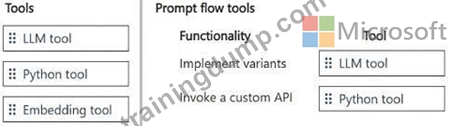
NEW QUESTION # 43
You manage an Azure Machine Learning workspace that includes a batch endpoint. You plan to deploy a model to the batch endpoint. You need to configure compute for the deployment. Which compute should you use?
Answer: B
NEW QUESTION # 44
You manage an Azure Machine Learning workspace named workspace!.
You plan to author custom pipeline components by using Azure Machine Learning Python SDK v2.
You must transform the Python code into a YAML specification that can be processed by the pipeline service.
You need to import the Python library that provides the transformation functionality.
Which Python library should you import?
Answer: A
NEW QUESTION # 45
A team schedules weekly retraining of a model using Azure ML pipelines. They also want retraining triggered automatically when production data significantly deviates from training data distribution, without duplicating pipeline logic. What should they implement?
Answer: B
Explanation:
Using a single pipeline triggered by both a schedule and data drift alerts ensures consistent retraining logic and avoids duplication. This approach minimizes operational overhead and maintenance complexity. Creating multiple pipelines can lead to inconsistencies, duplicated code, and increased effort when updating retraining logic or dependencies.
NEW QUESTION # 46
......
Free renewal of our AI-300 study prep in this respect is undoubtedly a large shining point. Apart from the advantage of free renewal in one year, our AI-300 exam engine offers you constant discounts so that you can save a large amount of money concerning buying our AI-300 Training Materials. And we give these discount from time to time, so you should come and buy AI-300 learning guide more and you will get more rewards accordingly.
AI-300 Intereactive Testing Engine: https://www.trainingdump.com/Microsoft/AI-300-practice-exam-dumps.html