Microsoft 인증 DP-750시험에 도전해보려고 결정하셨다면 Pass4Test덤프공부가이드를추천해드립니다. Pass4Test덤프는 고객님께서 필요한것이 무엇인지 너무나도 잘 알고 있답니다. Pass4Test의 Microsoft 인증 DP-750덤프는Microsoft 인증 DP-750시험을 쉽게 만듭니다.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Secure and govern data using Unity Catalog | 15-20% | - Access control and policies
|
| Topic 2: Deploy and manage data pipelines and workloads | 30-35% | - Lakehouse architecture operations
|
| Topic 3: Configure and manage Azure Databricks environments | 15-20% | - Workspace and compute configuration
|
| Topic 4: Prepare and process data | 30-35% | - Data quality and validation
|
IT전문가들이 자신만의 경험과 끊임없는 노력으로 작성한 Microsoft DP-750덤프에 관심이 있는데 선뜻 구매결정을 내릴수없는 분은Microsoft DP-750덤프 구매 사이트에서 메일주소를 입력한후 DEMO를 다운받아 문제를 풀어보고 구매할수 있습니다. 자격증을 많이 취득하면 좁은 취업문도 넓어집니다. Microsoft DP-750 덤프로Microsoft DP-750시험을 패스하여 자격즉을 쉽게 취득해보지 않으실래요?
질문 # 26
You use Databricks Asset Bundles to manage two jobs and an app.
You need to deploy the bundle to development and production environments. The solution must meet the following requirements
* Deploy the app to both environments.
* Deploy only one job to development.
* Minimize administrative effort.
What should you use?
정답:D
설명:
The correct answer is D - a targets node in databricks.yml.
Databricks Asset Bundles use a single databricks.yml to define all resources (jobs, apps, pipelines) once, and a targets node to define per-environment overrides. Within the development target, you can use the include
/exclude mechanism or resource-level overrides to deploy only one of the two jobs. The app and the second job are deployed to both environments through the shared resource definition.
Option B (separate databricks.yml files per environment) works technically but means duplicating the shared resource definitions across files - any change to a shared resource requires edits in multiple places, which is exactly the administrative overhead the question wants to avoid.
Option A (resources node) defines resources globally across all targets - it doesn't provide environment- specific filtering. Option C (variables node) parameterises values like cluster sizes or paths but doesn't control which resources are deployed to which environment.
Reference: https://learn.microsoft.com/en-us/azure/databricks/dev-tools/bundles/deployment-modes
질문 # 27
You have an Azure Databricks workspace that uses Unity Catalog.
You have a Lakeflow Spark Declarative Pipelines (SDP) pipeline that ingests data into a managed Delta table named Table1. Table1 is used for analytics.
New columns are added to the source data, causing pipeline failures during writes to Table1.
You need to prevent the pipeline failures. The solution must ensure that schema changes are detected and handled.
What should you do?
정답:C
설명:
You should enable schema evolution to resolve this problem. In Lakeflow Spark Declarative Pipelines (SDP)-formerly known as Delta Live Tables (DLT)-schema evolution automatically updates the schema of your managed Delta tables when new columns are detected in the source data.
Prevents Pipeline Failures: By default, Delta Lake applies strict schema enforcement to prevent bad or mismatched data from corrupting your tables. When the source data layout changes (e.g., column creep), the pipeline will throw a runtime error and fail the write operation.
Automates Ingestion Flexibility: Activating schema evolution allows Delta Lake to automatically adapt by adding the new columns to the target managed table layout dynamically, eliminating manual intervention or explicit ALTER TABLE operations.
Reference:
https://learn.microsoft.com/en-us/azure/databricks/ldp/unity-catalog
질문 # 28
Hotspot Question
You have an Azure Databricks workspace.
You have an Azure key vault named kv-secure that stores a secret named storageKey. The value of storageKey is managed and updated by the cloud security team at your company.
You need to enable a Databricks notebook named Notebook1 to retrieve the value of storageKey securely at runtime. The solution must follow the principle of least privilege and always retrieve the latest value.
What should you do? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.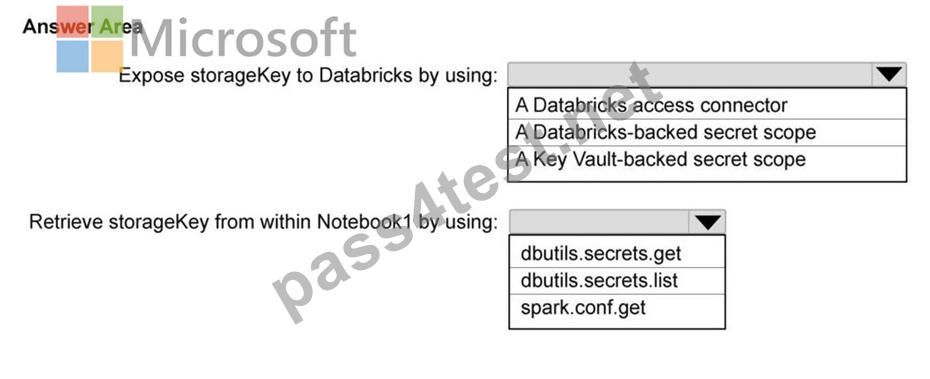
정답:
설명: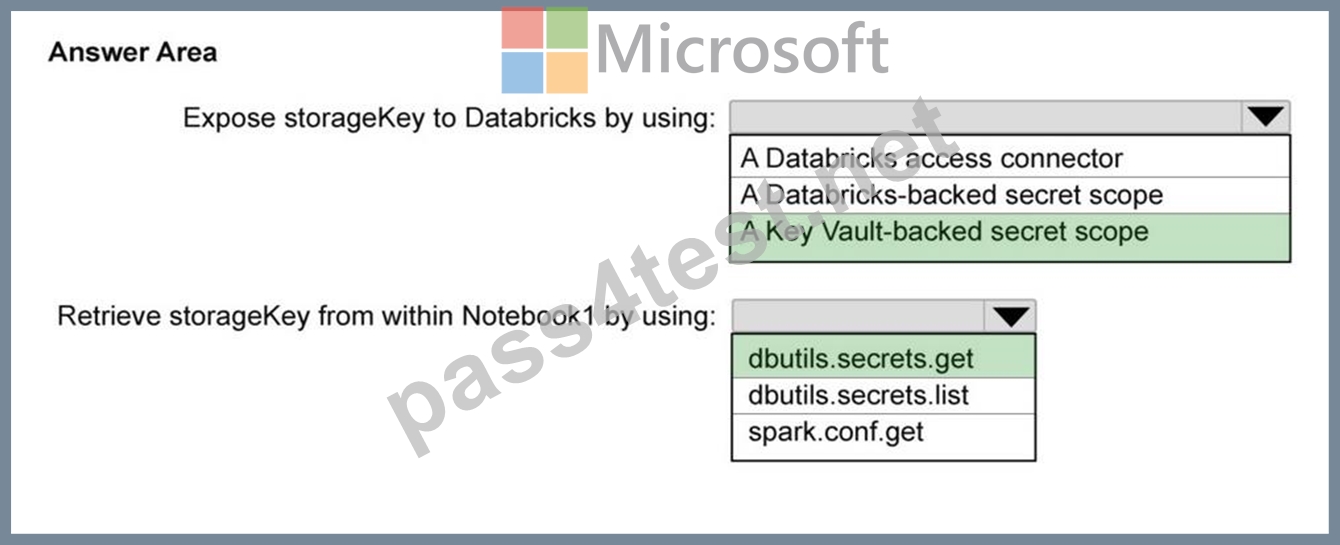
질문 # 29
You have an Azure Databricks job named Job1 that contains an ingestion task named Task1 and transformation task named Task2. You need to ensure that if Task1 fails, the task retries automatically, and Task2 is prevented from running How should you configure Job1? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.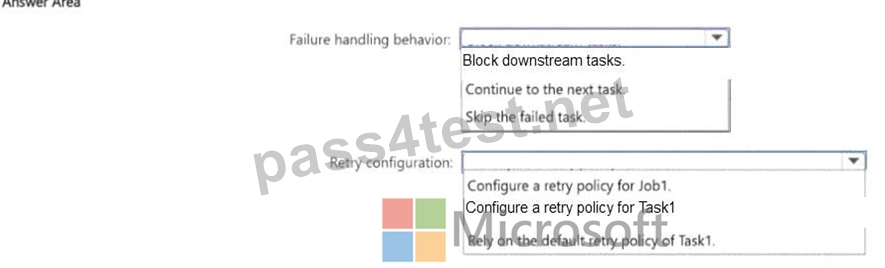
정답:
설명: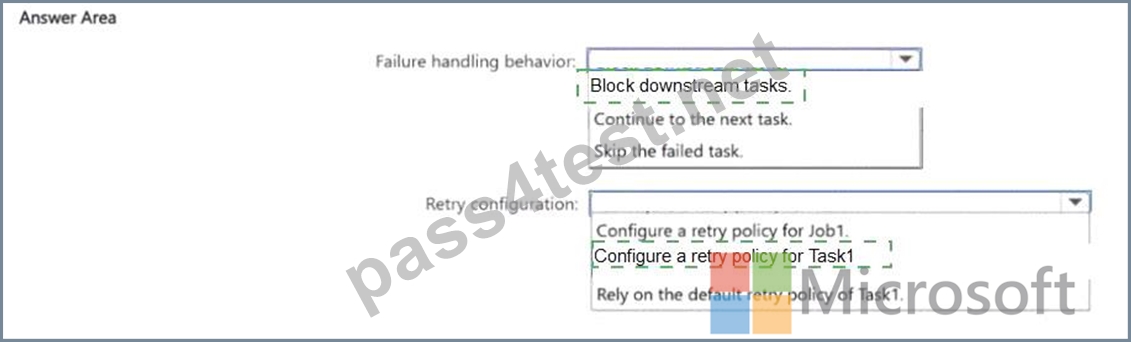
Explanation:
Two task-level settings solve this:
Task1 retry policy: configure Task1 with a maximum number of retries and a retry interval. When Task1 fails, Lakeflow Jobs automatically re-runs it up to the retry limit without any manual intervention. This handles transient infrastructure failures transparently.
Task2 run condition set to 'All succeeded' with Task1 as its dependency: this means Task2 only starts when Task1 has succeeded. If Task1 fails and exhausts all retries, Task2 remains blocked - it never runs on data from a failed upstream ingestion. The dependency is declared in Task2's 'Depends on' setting in the job configuration.
These two settings are independent and composable. Task1's retry policy gives it multiple chances to recover.
Task2's dependency and run condition ensure the downstream transformation only runs on clean, successfully ingested data.
Reference: https://learn.microsoft.com/en-us/azure/databricks/jobs/configure-jobs#task-retries
질문 # 30
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You plan to ingest data from CSV files stored in Azure Data Lake Storage Gen2. New rows are appended frequently.
You need to implement a data ingestion solution that meets the following requirements:
- New data must be available in near-real-time (NRT).
- The data must be stored in managed Delta tables.
- The solution must minimize custom code and maintenance effort.
What should you include in the solution?
정답:C
설명:
You should use Auto Loader with Delta Live Tables (DLT) or a streaming readStream using the cloudFiles format to load data into Unity Catalog managed tables.
To achieve the absolute lowest maintenance and custom code, Delta Live Tables with Auto Loader is the recommended choice.
Configure Cloud FilesFormat option: Set the source format to cloudFiles in your Spark stream.File detection: Auto Loader automatically tracks new files arriving in Azure Data Lake Storage (ADLS) Gen2.Schema evolution: It infers and adapts to schema changes without code updates.
Reference:
https://docs.databricks.com/aws/en/ingestion/cloud-object-storage/auto-loader/unity-catalog
질문 # 31
......
Pass4Test의 경험이 풍부한 IT전문가들이 연구제작해낸 Microsoft인증 DP-750덤프는 시험패스율이 100%에 가까워 시험의 첫번째 도전에서 한방에 시험패스하도록 도와드립니다. Microsoft인증 DP-750덤프는Microsoft인증 DP-750최신 실제시험문제의 모든 시험문제를 커버하고 있어 덤프에 있는 내용만 공부하시면 아무런 걱정없이 시험에 도전할수 있습니다.
DP-750최신 시험 최신 덤프자료: https://www.pass4test.net/DP-750.html