P.S. Kostenlose 2026 Databricks Databricks-Certified-Professional-Data-Engineer Prüfungsfragen sind auf Google Drive freigegeben von Zertpruefung verfügbar: https://drive.google.com/open?id=1eB0HQIqg_7xCYEGBMOFC0_en-dGrlk3R
Zertpruefung hat die spezielle Schulungsunterlagen zur Databricks Databricks-Certified-Professional-Data-Engineer Zertifizierungsprüfung. Sie können mit wenig Zeit und Geld Ihre IT-Fachkenntnisse in kurzer Zeit verbessern und somit Ihre Fachkenntnisse und Technik in der IT-Branche beweisen. Die Kurse von Zertpruefung werden von den Experten nach ihren Kenntnissen und Erfahrungen für die Databricks Databricks-Certified-Professional-Data-Engineer Zertifizierungsprüfung bearbeitet
| Section | Objectives |
|---|---|
| Security, Governance, Monitoring, and Optimization | - Monitor and optimize Spark workloads - Implement Unity Catalog governance and access control - Cost optimization and performance tuning |
| Production Pipelines and Orchestration | - Automate ETL pipelines and scheduling - Build and manage workflows using Databricks Jobs - Pipeline reliability and fault tolerance |
| Data Modeling and Storage | - Delta Lake table design and optimization - Design scalable data lakehouse architectures - Schema evolution and data partitioning strategies |
| Data Ingestion and Transformation | - Handle batch and streaming data pipelines - Ingest data using Apache Spark and Databricks - Transform and clean datasets using Spark SQL and DataFrame APIs |
>> Databricks-Certified-Professional-Data-Engineer PDF Demo <<
Es existiert viele Methoden, sich auf die Databricks Databricks-Certified-Professional-Data-Engineer Zertifizierungsprüfung vorzubereiten. Unsere Website bietet zuverlässige Trainingsinstrumente, mit denen Sie sich auf die nächste Databricks Databricks-Certified-Professional-Data-Engineer Zertifizierungsprüfung vorbereiten. Die Lernmaterialien zur Databricks Databricks-Certified-Professional-Data-Engineer Zertifizierungsprüfung von Zertpruefung enthalten sowohl Fragen als auch Antworten. Unsere Materialien sind von der Praxis überprüfte Software. Wir werden alle Ihren Bedürfnisse zur IT-Zertifizierung abdecken.
216. Frage
The data governance team is reviewing code used for deleting records for compliance with GDPR. They note the following logic is used to delete records from the Delta Lake table named users.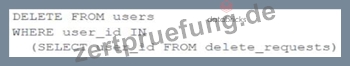
Assuming that user_id is a unique identifying key and that delete_requests contains all users that have requested deletion, which statement describes whether successfully executing the above logic guarantees that the records to be deleted are no longer accessible and why?
Antwort: E
Begründung:
The code uses the DELETE FROM command to delete records from the users table that match a condition based on a join with another table called delete_requests, which contains all users that have requested deletion. The DELETE FROM command deletes records from a Delta Lake table by creating a new version of the table that does not contain the deleted records. However, this does not guarantee that the records to be deleted are no longer accessible, because Delta Lake supports time travel, which allows querying previous versions of the table using a timestamp or version number. Therefore, files containing deleted records may still be accessible with time travel until a vacuum command is used to remove invalidated data files from physical storage. Verified Reference: [Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "Delete from a table" section; Databricks Documentation, under "Remove files no longer referenced by a Delta table" section.
217. Frage
A data engineering team is migrating off its legacy Hadoop platform. As part of the process, they are evaluating storage formats for performance comparison. The legacy platform uses ORC and RCFile formats.
After converting a subset of data to Delta Lake , they noticed significantly better query performance. Upon investigation, they discovered that queries reading from Delta tables leveraged a Shuffle Hash Join , whereas queries on legacy formats used Sort Merge Joins . The queries reading Delta Lake data also scanned less data.
Which reason could be attributed to the difference in query performance?
Antwort: B
Begründung:
Delta Lake outperforms legacy Hadoop formats because it leverages Parquet-based storage , data skipping
, and file pruning . According to Databricks documentation, Delta Lake automatically stores detailed statistics (min/max values and file-level metadata) in the transaction log. During query planning, the engine uses these statistics to skip entire files that do not match query filters , a process called data skipping and file pruning . Additionally, Delta uses a vectorized Parquet reader , which reduces I/O and CPU overhead.
Together, these optimizations allow Delta to scan significantly less data and produce more efficient physical query plans (e.g., Shuffle Hash Join instead of Sort Merge Join). The performance gain is due to efficient data skipping, not the inherent superiority of join type.
218. Frage
An organization processes customer data from web and mobile applications. Data includes names, emails, phone numbers, and location history. Data arrives both as batch files (from SFTP daily) and streaming JSON events (from Kafka in real-time).
To comply with data privacy policies, the following requirements must be met:
* Personally Identifiable Information (PII) such as email, phone number, and IP address must be masked or anonymized before storage.
* Both batch and streaming pipelines must apply consistent PII handling.
* Masking logic must be auditable and reproducible.
* The masked data must remain usable for downstream analytics.
How should the data engineer design a compliant data pipeline on Databricks that supports both batch and streaming modes, applies data masking to PII, and maintains traceability for audits?
Antwort: A
Begründung:
Databricks recommends applying data masking or anonymization before persisting PII to ensure compliance with privacy regulations such as GDPR and HIPAA. In a Lakeflow Declarative Pipeline , developers can define custom Python or SQL-based masking functions to standardize PII handling across both batch and streaming inputs.
This approach ensures that data entering the Delta Lake is already anonymized, guaranteeing consistent and auditable behavior. By applying masking during ingestion (in the Bronze layer), audit trails are preserved through pipeline event logs.
While Unity Catalog column masks (option C) can enforce dynamic masking at query time, they do not prevent PII storage. Thus, option D aligns with the best practice of securing PII before storage , while still supporting reproducibility and analytics usability.
219. Frage
The data engineering team is migrating an enterprise system with thousands of tables and views into the Lakehouse. They plan to implement the target architecture using a series of bronze, silver, and gold tables. Bronze tables will almost exclusively be used by production data engineering workloads, while silver tables will be used to support both data engineering and machine learning workloads. Gold tables will largely serve business intelligence and reporting purposes. While personal identifying information (PII) exists in all tiers of data, pseudonymization and anonymization rules are in place for all data at the silver and gold levels.
The organization is interested in reducing security concerns while maximizing the ability to collaborate across diverse teams.
Which statement exemplifies best practices for implementing this system?
Antwort: E
Begründung:
This is the correct answer because it exemplifies best practices for implementing this system. By isolating tables in separate databases based on data quality tiers, such as bronze, silver, and gold, the data engineering team can achieve several benefits. First, they can easily manage permissions for different users and groups through database ACLs, which allow granting or revoking access to databases, tables, or views. Second, they can physically separate the default storage locations for managed tables in each database, which can improve performance and reduce costs. Third, they can provide a clear and consistent naming convention for the tables in each database, which can improve discoverability and usability. Verified Reference: [Databricks Certified Data Engineer Professional], under "Lakehouse" section; Databricks Documentation, under "Database object privileges" section.
220. Frage
A platform team is creating a standardized template for Databricks Asset Bundles to support CI/CD. The template must specify defaults for artifacts, workspace root paths, and a run identity, while allowing a "dev" target to be the default and override specific paths.
How should the team use databricks.yml to satisfy these requirements?
Antwort: C
Begründung:
In Databricks Asset Bundles, the databricks.yml file defines all top-level configuration keys, including bundle, artifacts, workspace, run_as, and targets. The targets section defines specific deployment contexts (for example, dev, test, prod). Setting default: true for a target marks it as the default environment. Overrides for workspace paths and artifact configurations can be defined inside each target while keeping defaults at the top level.
Reference Source: Databricks Asset Bundle Configuration Guide - "Structure of databricks.yml and target overrides."
=========
221. Frage
......
Viele Leute, die in der IT-Branche arbeiten, wissen die mühsame Vorbereitung auf die Databricks Databricks-Certified-Professional-Data-Engineer Prüfung. Wir Zertpruefung können doch den Schwierigkeitsgrad der Databricks Databricks-Certified-Professional-Data-Engineer Prüfung nicht ändern, aber wir können die Schwierigkeitsgrad der Vorbereitung für Sie vermindern. Ihre Angst vor der Databricks Databricks-Certified-Professional-Data-Engineer Prüfung wird beseitigen, solange Sie die Prüfungsunterlagen von unserem Technik-Team probiert haben. Wir tun unser Bestes, um Ihnen zu helfen, Ihre Konfidenz für Databricks Databricks-Certified-Professional-Data-Engineer zu verstärken!
Databricks-Certified-Professional-Data-Engineer Zertifikatsfragen: https://www.zertpruefung.de/Databricks-Certified-Professional-Data-Engineer_exam.html
P.S. Kostenlose 2026 Databricks Databricks-Certified-Professional-Data-Engineer Prüfungsfragen sind auf Google Drive freigegeben von Zertpruefung verfügbar: https://drive.google.com/open?id=1eB0HQIqg_7xCYEGBMOFC0_en-dGrlk3R