P.S. Free & New DP-100 dumps are available on Google Drive shared by PDFTorrent: https://drive.google.com/open?id=1_2FqHwfIoh638Y3b1KP97qCK3tCCoTNd
As is known to us, the high pass rate is a reflection of the high quality of DP-100 study torrent. The more people passed their exam, the better the study materials are. There are more than 98 percent that passed their exam, and these people both used our DP-100 Test Torrent. We believe that our DP-100 test torrent can help you improve yourself and make progress beyond your imagination. If you buy our DP-100 study torrent, we can make sure that our study materials will not be let you down.
The DP-100 Exam is a valuable certification for data scientists who work with Azure, as it demonstrates their proficiency in designing and implementing data science solutions on this platform. Designing and Implementing a Data Science Solution on Azure certification can help data scientists advance their careers and increase their earning potential.
>> Microsoft DP-100 Torrent <<
We attach great importance on the quality of our DP-100 exam dumps. Every product will undergo a strict inspection process. The quality of our DP-100 study guide deserves your trust. The most important thing for preparing the exam is reviewing the essential point. Almost all questions and answers of the real exam occur on our DP-100 practice materials. That means if you study our DP-100 training prep, your passing rate is much higher than other candidates.
Languages: English, Japanese, Chinese (Simplified), Korean
Retirement date: none
This exam measures your ability to accomplish the following technical tasks: manage Azure resources for machine learning; run experiments and train models; deploy and operationalize machine learning solutions; and implement responsible machine learning.
NEW QUESTION # 72
You train a model by using Azure Machine Learning. You use Azure Blob Storage to store production data.
The model must be re-trained when new data is uploaded to Azure Blob Storage. You need to minimize development and coding.
You need to configure Azure services to develop a re-training solution.
Which Azure services should you use? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.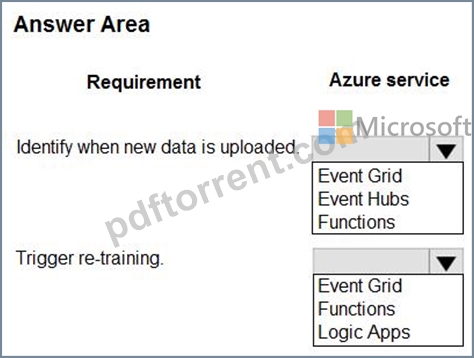
Answer:
Explanation: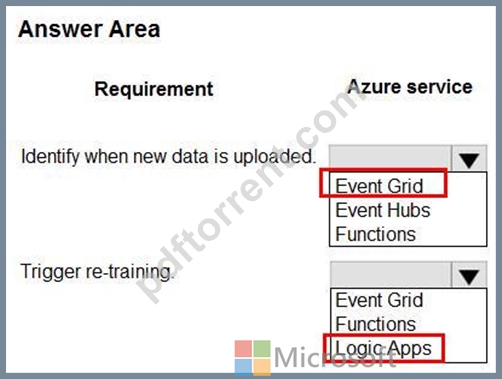
NEW QUESTION # 73
You create an Azure Machine Learning workspace.
You need to detect data drift between a baseline dataset and a subsequent target dataset by using the DataDriftDetector class.
How should you complete the code segment? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.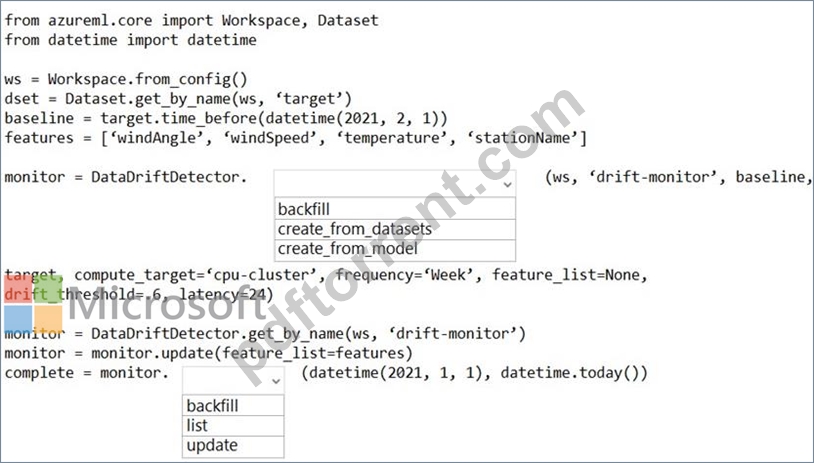
Answer:
Explanation: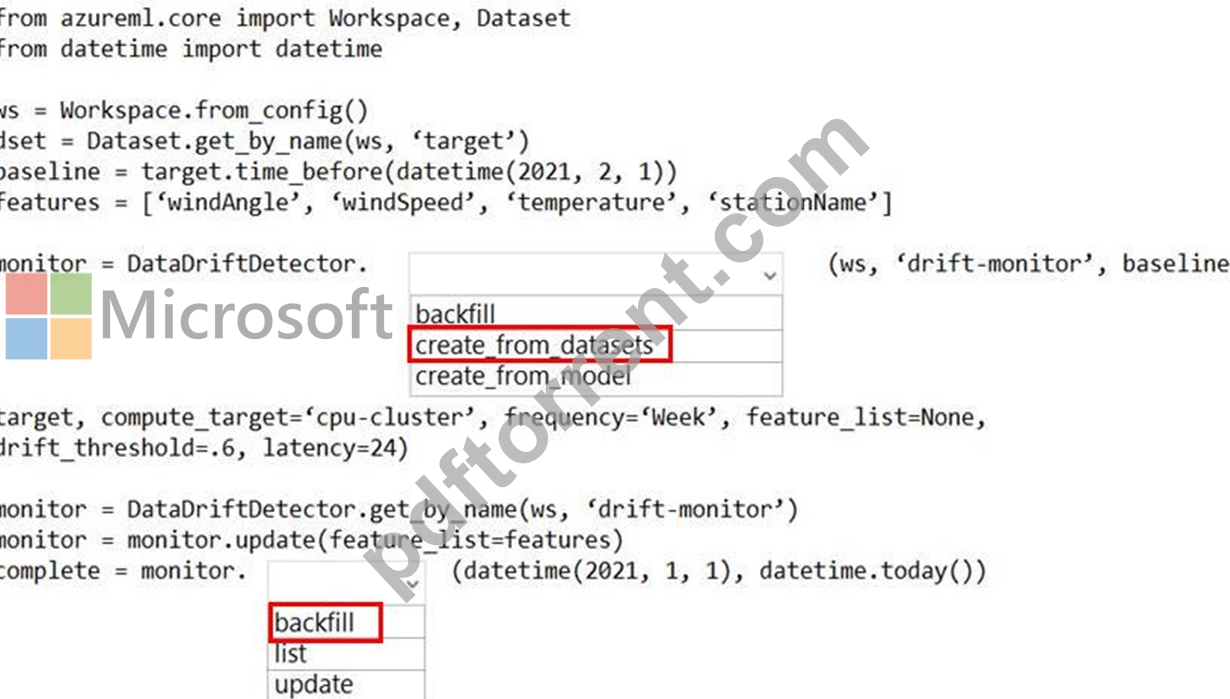
Reference:
https://docs.microsoft.com/en-us/python/api/azureml-datadrift/azureml.datadrift.datadriftdetector(class)
Topic 2, Overview
Current environment
Requirements
* Media used for penalty event detection will be provided by consumer devices. Media may include images and videos captured during the sporting event and snared using social media. The images and videos will have varying sizes and formats.
* The data available for model building comprises of seven years of sporting event media. The sporting event media includes: recorded videos, transcripts of radio commentary, and logs from related social media feeds feeds captured during the sporting events.
* Crowd sentiment will include audio recordings submitted by event attendees in both mono and stereo Formats.
Advertisements
* Ad response models must be trained at the beginning of each event and applied during the sporting event.
* Market segmentation nxxlels must optimize for similar ad resporr.r history.
* Sampling must guarantee mutual and collective exclusivity local and global segmentation models that share the same features.
* Local market segmentation models will be applied before determining a user's propensity to respond to an advertisement.
* Data scientists must be able to detect model degradation and decay.
* Ad response models must support non linear boundaries features.
* The ad propensity model uses a cut threshold is 0.45 and retrains occur if weighted Kappa deviates from 0.1 +/-5%.
* The ad propensity model uses cost factors shown in the following diagram: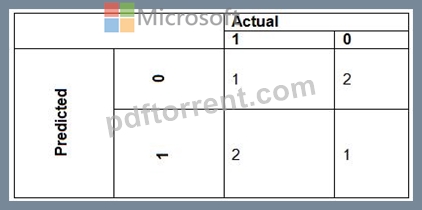
The ad propensity model uses proposed cost factors shown in the following diagram: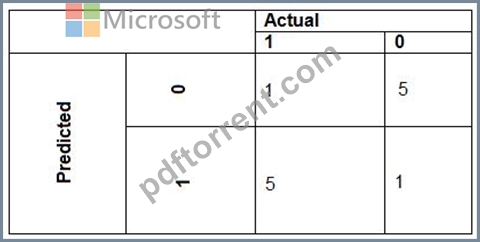
Performance curves of current and proposed cost factor scenarios are shown in the following diagram: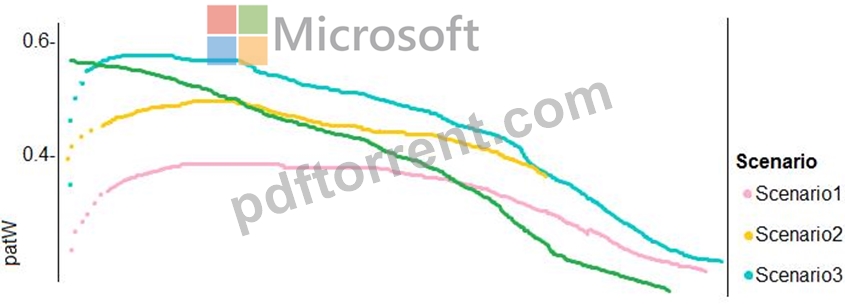
Penalty detection and sentiment
Findings
* Data scientists must build an intelligent solution by using multiple machine learning models for penalty event detection.
* Data scientists must build notebooks in a local environment using automatic feature engineering and model building in machine learning pipelines.
* Notebooks must be deployed to retrain by using Spark instances with dynamic worker allocation
* Notebooks must execute with the same code on new Spark instances to recode only the source of the data.
* Global penalty detection models must be trained by using dynamic runtime graph computation during training.
* Local penalty detection models must be written by using BrainScript.
* Experiments for local crowd sentiment models must combine local penalty detection data.
* Crowd sentiment models must identify known sounds such as cheers and known catch phrases. Individual crowd sentiment models will detect similar sounds.
* All shared features for local models are continuous variables.
* Shared features must use double precision. Subsequent layers must have aggregate running mean and standard deviation metrics Available.
segments
During the initial weeks in production, the following was observed:
* Ad response rates declined.
* Drops were not consistent across ad styles.
* The distribution of features across training and production data are not consistent.
Analysis shows that of the 100 numeric features on user location and behavior, the 47 features that come from location sources are being used as raw features. A suggested experiment to remedy the bias and variance issue is to engineer 10 linearly uncorrected features.
Penalty detection and sentiment
* Initial data discovery shows a wide range of densities of target states in training data used for crowd sentiment models.
* All penalty detection models show inference phases using a Stochastic Gradient Descent (SGD) are running too stow.
* Audio samples show that the length of a catch phrase varies between 25%-47%, depending on region.
* The performance of the global penalty detection models show lower variance but higher bias when comparing training and validation sets. Before implementing any feature changes, you must confirm the bias and variance using all training and validation cases.
NEW QUESTION # 74
You are developing a machine learning model.
You must inference the machine learning model for testing.
You need to use a minimal cost compute target.
Which two compute targets should you use? Each correct answer presents a complete solution.
NOTE: Each correct selection is worth one point.
Answer: A,E
Explanation:
https://learn.microsoft.com/en-us/azure/machine-learning/concept-compute-target?view=azureml- api-2#compute-targets-for-inference
NEW QUESTION # 75
You manage an Azure Al Foundry project.
You deploy a large language model from the model catalog.
You need to manually evaluate the model, collect the statistics, and be able to review the results later.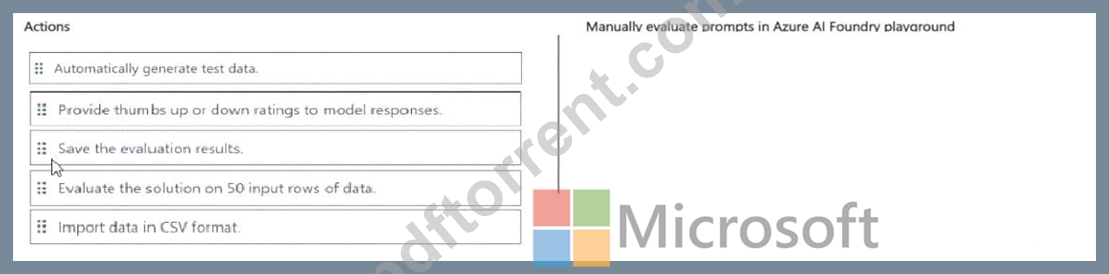
Answer:
Explanation: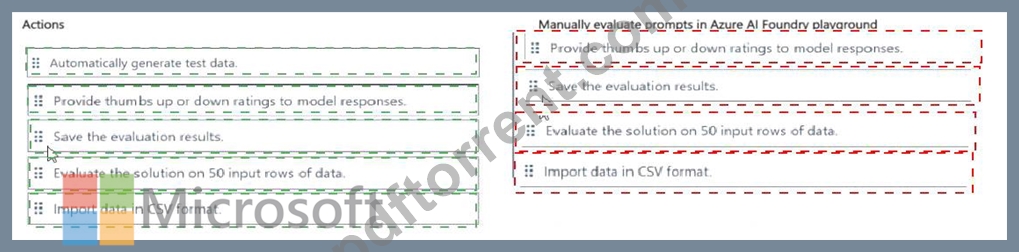
Explanation: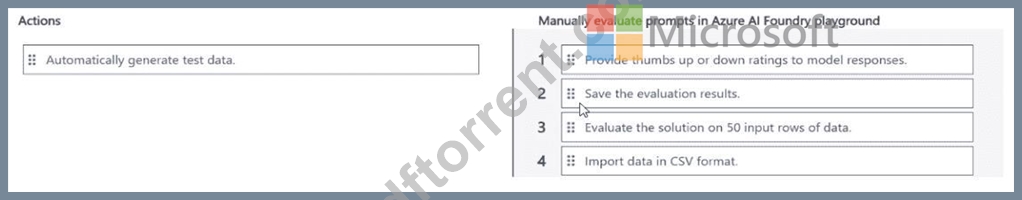
NEW QUESTION # 76
You need to select a pre built development environment for a series of data science experiments.
You must use the R language for the experiments.
Which three environments can you use? Each correct answer presents a complete solution.
NOTE:
Each correct selection is worth one point.
Answer: A,C,E
NEW QUESTION # 77
......
Upgrade DP-100 Dumps: https://www.pdftorrent.com/DP-100-exam-prep-dumps.html
What's more, part of that PDFTorrent DP-100 dumps now are free: https://drive.google.com/open?id=1_2FqHwfIoh638Y3b1KP97qCK3tCCoTNd