100% Pass Quiz NVIDIA - NCP-AIO - Valid Trustworthy NVIDIA AI Operations Exam Torrent

P.S. Free 2026 NVIDIA NCP-AIO dumps are available on Google Drive shared by PassLeaderVCE: https://drive.google.com/open?id=1hOuQ4RQvTjRLHR0e5Fkb1aH3zqbu-HFb
Do you always feel that your gains are not proportional to your efforts without valid NCP-AIO study torrent? Do you feel that you always suffer from procrastination and cannot make full use of your sporadic time? If your answer is absolutely yes, then we would like to suggest you to try our NCP-AIO Training Materials, which are high quality and efficiency NCP-AIO test tools. Your success is 100% ensured to pass the NCP-AIO exam and acquire the dreaming certification which will enable you to reach for more opportunities to higher incomes or better enterprises.
| Topic | Details |
|---|
| Topic 1 | - Installation and Deployment: This section of the exam measures the skills of system administrators and addresses core practices for installing and deploying infrastructure. Candidates are tested on installing and configuring Base Command Manager, initializing Kubernetes on NVIDIA hosts, and deploying containers from NVIDIA NGC as well as cloud VMI containers. The section also covers understanding storage requirements in AI data centers and deploying DOCA services on DPU Arm processors, ensuring robust setup of AI-driven environments.
|
| Topic 2 | - Administration: This section of the exam measures the skills of system administrators and covers essential tasks in managing AI workloads within data centers. Candidates are expected to understand fleet command, Slurm cluster management, and overall data center architecture specific to AI environments. It also includes knowledge of Base Command Manager (BCM), cluster provisioning, Run.ai administration, and configuration of Multi-Instance GPU (MIG) for both AI and high-performance computing applications.
|
| Topic 3 | - Workload Management: This section of the exam measures the skills of AI infrastructure engineers and focuses on managing workloads effectively in AI environments. It evaluates the ability to administer Kubernetes clusters, maintain workload efficiency, and apply system management tools to troubleshoot operational issues. Emphasis is placed on ensuring that workloads run smoothly across different environments in alignment with NVIDIA technologies.
|
| Topic 4 | - Troubleshooting and Optimization: NVIThis section of the exam measures the skills of AI infrastructure engineers and focuses on diagnosing and resolving technical issues that arise in advanced AI systems. Topics include troubleshooting Docker, the Fabric Manager service for NVIDIA NVlink and NVSwitch systems, Base Command Manager, and Magnum IO components. Candidates must also demonstrate the ability to identify and solve storage performance issues, ensuring optimized performance across AI workloads.
|
>> Trustworthy NCP-AIO Exam Torrent <<
100% Pass Quiz 2026 NVIDIA NCP-AIO: NVIDIA AI Operations – Trustable Trustworthy Exam Torrent
To keep pace with the times, we believe science and technology can enhance the way people study on our NCP-AIO exam materials. Especially in such a fast-pace living tempo, we attach great importance to high-efficient learning our NCP-AIO Study Guide. Therefore, our NCP-AIO study materials base on the past exam papers and the current exam tendency, and design such an effective simulation function to place you in the real exam environment.
NVIDIA AI Operations Sample Questions (Q11-Q16):
NEW QUESTION # 11
Your AI training pipeline involves processing large image datasets stored in a cloud object storage service (e.g., AWS S3, Google Cloud Storage). The download speed from the object storage is limiting your training performance. You are considering using caching mechanisms. Describe different caching strategies and their tradeoffs in this context.
- A. Using the cloud provider's caching service (e.g., AWS CloudFront, Google Cloud CDN): This can improve performance for frequently accessed data but might introduce additional costs and complexity.
- B. Local SSD caching on each compute node: This provides fast access but requires managing cache consistency and dealing with limited storage capacity.
- C. In-memory caching using tools like Redis or Memcached: This offers very low latency but is limited by the available memory and can be expensive.
- D. Completely removing caching: This is the simplest approach and always provides the best performance.
- E. Using only the object storage's built-in caching mechanisms: This is sufficient for all workloads and eliminates the need for additional caching layers.
Answer: A,B,C
Explanation:
Local SSD caching balances speed and capacity. In-memory caching offers the lowest latency but has memory limitations. Cloud provider's caching services improve performance for frequently accessed data but can have cost and complexity. Removing caching or relying solely on object storage caching is not ideal for performance-critical workloads.
NEW QUESTION # 12
A new researcher needs access to GPU resources but should not have permission to modify cluster settings or manage other users.
What role should you assign them in Run:ai?
- A. Application Administrator
- B. L1 Researcher
- C. Research Manager
- D. Department Administrator
Answer: B
Explanation:
In Run:ai, roles are assigned based on levels of permissions. The L1 Researcher role is designed for users who need access to GPU resources for running jobs and experiments but should not have administrative rights over cluster settings or other users. This role ensures researchers can use resources without affecting cluster configurations or user management. Other roles like Department Administrator, Application Administrator, or Research Manager have broader privileges, including managing users and settings, which are not appropriate for the new researcher's requirements.
NEW QUESTION # 13
Which configuration file dictates the initial settings and parameters for the Base Command Manager (BCM) installation?
- A. base_command.config
- B. cluster_config.json
- C. bcm_config.yaml
- D. bcm.conf
- E. nvidia bcm.ini
Answer: C
Explanation:
The 'bcm_config.yaml' file is the primary configuration file used during the initial installation and setup of Base Command Manager (BCM). It specifies various parameters such as the database connection details, authentication methods, and other system-level settings.
NEW QUESTION # 14
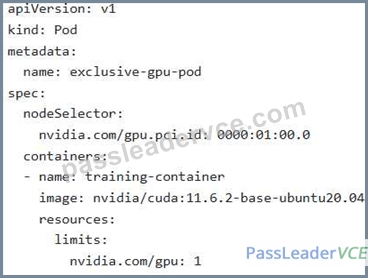
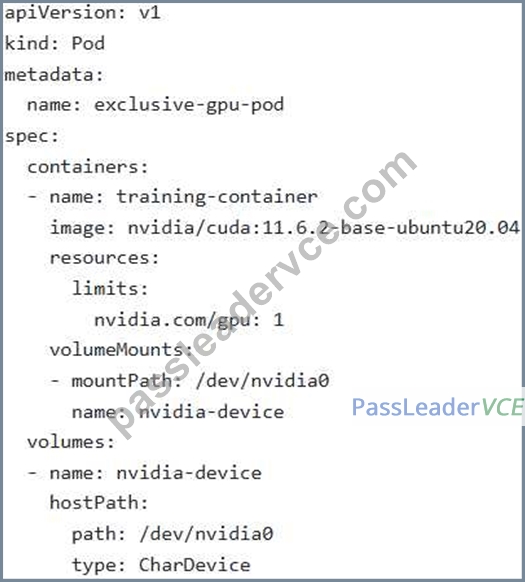
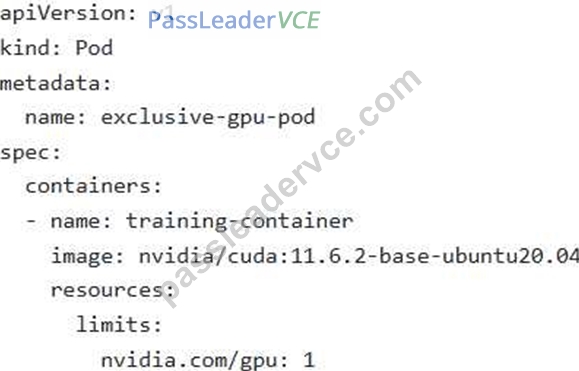
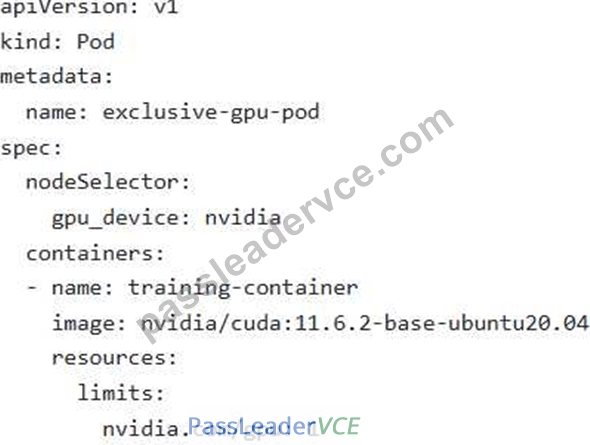
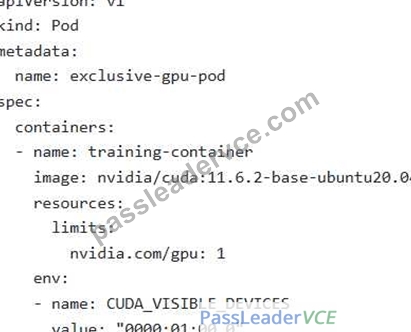
You are managing a Kubernetes cluster used for AI model training. One of the training jobs requires exclusive access to a specific GPU with PCI ID Which of the following Kubernetes manifests correctly configures this requirement for the pod?
Answer: E
Explanation:
The correct answer is A. Setting the 'CUDA VISIBLE DEVICES environment variable with the specific PCI ID ensures the container only sees that GPU. Option B attempts to use a nodeselector, which is not the correct way to request specific GPUs; it's more for scheduling to a node with GPUs. Options C and D do not enforce PCI ID exclusivity. Option E is too generic and doesn't target a specific GPU.
NEW QUESTION # 15
You are using NVSHMEM to manage shared memory across multiple GPUs in a multi-node cluster. Your application is crashing with out- of-memory errors, even though the reported GPU memory usage is well below the total available. You have already confirmed sufficient physical RAM on all nodes. What is the MOST likely cause, related to NVSHMEM configuration, of these out-of-memory errors?
- A. 'CUDA_VISIBLE DEVICES is set incorrectly
- B. The NCCL library is not properly initialized.
- C. The CUDA driver version is incompatible with NVSHMEM.
- D. The InfiniBand drivers are outdated.
- E. The 'NVSHMEM SYMMETRIC SIZE environment variable is set too low.
Answer: E
Explanation:
The 'NVSHMEM SYMMETRIC SIZE environment variable defines the total amount of shared memory available to NVSHMEM across all nodes. If this value is too small, even if individual GPUs have sufficient memory, the overall NVSHMEM shared memory pool may be exhausted, leading to out-of-memory errors. CUDA driver incompatibility, NCCL issues, and outdated InfiniBand drivers could cause other problems, but they are less likely to directly cause out-of-memory errors when individual GPU usage is low . CUDA_VISIBLE_DEVICES may effect device enumeration and memory allocation, but is the master environment variable.
NEW QUESTION # 16
......
With the high employment pressure, more and more people want to ease the employment tension and get a better job. The best way for them to solve the problem is to get the NCP-AIO certification. Because the certification is the main symbol of their working ability, if they can own the NCP-AIO certification, they will gain a competitive advantage when they are looking for a job. An increasing number of people have become aware of that it is very important for us to gain the NCP-AIO Exam Questions in a short time. And our NCP-AIO exam questions can help you get the dreamng certification.
NCP-AIO Exam Fee: https://www.passleadervce.com/NVIDIA-Certified-Professional/reliable-NCP-AIO-exam-learning-guide.html
- NCP-AIO New APP Simulations 👩 NCP-AIO Latest Study Plan 💸 NCP-AIO Latest Exam Duration 🕳 Open 「 www.validtorrent.com 」 enter “ NCP-AIO ” and obtain a free download 🐊New NCP-AIO Braindumps Questions
- New NCP-AIO Braindumps Questions 💇 New NCP-AIO Braindumps Questions 🐖 Best NCP-AIO Study Material 📰 Search for ➽ NCP-AIO 🢪 and easily obtain a free download on 「 www.pdfvce.com 」 💙NCP-AIO Relevant Questions
- NVIDIA's NCP-AIO Exam Questions Offer Realistic Practice and Accurate Answers for Your Success 🧗 Open ⮆ www.testkingpass.com ⮄ and search for ➽ NCP-AIO 🢪 to download exam materials for free 🤖NCP-AIO Free Study Material
- Learn Time Management Skill With NVIDIA NCP-AIO Practice Tests 🐋 Copy URL ➤ www.pdfvce.com ⮘ open and search for ▶ NCP-AIO ◀ to download for free ⏩NCP-AIO Exam Tutorials
- Trustworthy NCP-AIO Exam Torrent Exam Pass For Sure | NCP-AIO: NVIDIA AI Operations ♣ Search for ☀ NCP-AIO ️☀️ and easily obtain a free download on ⏩ www.vce4dumps.com ⏪ 🍉NCP-AIO Reliable Exam Blueprint
- NVIDIA's NCP-AIO Exam Questions Offer Realistic Practice and Accurate Answers for Your Success 🪓 Easily obtain “ NCP-AIO ” for free download through 「 www.pdfvce.com 」 🍏NCP-AIO Valid Test Dumps
- Free PDF NCP-AIO - Useful Trustworthy NVIDIA AI Operations Exam Torrent ⚡ Easily obtain free download of “ NCP-AIO ” by searching on ▷ www.troytecdumps.com ◁ 🏵NCP-AIO Vce Files
- Exam NCP-AIO Course 😊 NCP-AIO Exam Tutorials 🐽 Best NCP-AIO Study Material 📊 Open website ▛ www.pdfvce.com ▟ and search for { NCP-AIO } for free download 🔫NCP-AIO New Learning Materials
- NCP-AIO Latest Study Questions 🏣 NCP-AIO Test Tutorials 🛫 Exam NCP-AIO Course 🧿 Search for ▷ NCP-AIO ◁ on ▛ www.prep4away.com ▟ immediately to obtain a free download 🦐Exam NCP-AIO Tutorial
- Updated Trustworthy NCP-AIO Exam Torrent - Find Shortcut to Pass NCP-AIO Exam 🤨 Enter { www.pdfvce.com } and search for ➠ NCP-AIO 🠰 to download for free 🥍Exam NCP-AIO Tutorial
- New NCP-AIO Braindumps Questions ⚒ NCP-AIO Valid Test Dumps 🎅 NCP-AIO New APP Simulations 🚗 Search on ➽ www.dumpsquestion.com 🢪 for ➥ NCP-AIO 🡄 to obtain exam materials for free download 👼NCP-AIO Free Study Material
- www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.wonderlink.de, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, swipy.ru, Disposable vapes
What's more, part of that PassLeaderVCE NCP-AIO dumps now are free: https://drive.google.com/open?id=1hOuQ4RQvTjRLHR0e5Fkb1aH3zqbu-HFb