Passing Databricks Certified Data Engineer Professional actual test, valid Certified-Data-Engineer-Professional test braindump

The Certified-Data-Engineer-Professional test prep mainly help our clients pass the Certified-Data-Engineer-Professional exam and gain the certification. The certification can bring great benefits to the clients. The clients can enter in the big companies and earn the high salary. You may double the salary after you pass the Certified-Data-Engineer-Professional Exam. If you own the certification it proves you master the Certified-Data-Engineer-Professional quiz torrent well and you own excellent competences and you will be respected in your company or your factory. If you want to change your job it is also good for you.

Databricks Certified-Data-Engineer-Professional Exam Syllabus Topics:

SectionObjectives
Topic 1: Monitoring and Alerting- Alerting
  • 1. Use SQL Alerts to monitor data quality
    • 2. Use the Workflows UI and Jobs API to configure notifications for job status and performance issues
      - Monitoring
      • 1. Use Lakeflow Declarative Pipelines event logs to monitor pipelines
        • 2. Use system tables for observability of resource utilization, cost, auditing, and workloads
          • 3. Use Databricks REST APIs and Databricks CLI to monitor jobs and pipelines
            • 4. Use Query Profile and Spark UI to monitor workloads
              Topic 2: Data Modeling- Design and optimize data models
              • 1. Simplify data layout decisions and optimize query performance using liquid clustering
                • 2. Design dimensional models for analytical workloads with efficient querying and aggregation
                  • 3. Identify the benefits of liquid clustering over partitioning and Z-Ordering
                    • 4. Design and implement scalable data models using Delta Lake to manage large datasets
                      Topic 3: Data Governance- Govern enterprise data
                      • 1. Create and add descriptions and metadata to enterprise data to improve discoverability
                        • 2. Demonstrate understanding of the Unity Catalog permission inheritance model
                          Topic 4: Data Sharing and Federation- Share and federate data
                          • 1. Use Delta Sharing to share live data from the Lakehouse with any computing platform
                            • 2. Demonstrate secure Delta Sharing between Databricks deployments using Databricks-to-Databricks sharing or with external platforms using the open sharing protocol
                              • 3. Configure Lakehouse Federation with appropriate governance across supported source systems
                                Topic 5: Data Transformation, Cleansing, and Quality- Transform and validate data
                                • 1. Develop a quarantining process for bad data with Lakeflow Declarative Pipelines or Auto Loader in classic jobs
                                  • 2. Write efficient Spark SQL and PySpark code for advanced transformations including window functions, joins, and aggregations
                                    Topic 6: Data Ingestion & Acquisition- Design and implement data ingestion pipelines
                                    • 1. Create an append-only data pipeline capable of handling both batch and streaming data using Delta
                                      • 2. Ingest formats including Delta Lake, Parquet, ORC, AVRO, JSON, CSV, XML, text, and binary data from sources such as message buses and cloud storage
                                        Topic 7: Developing Code for Data Processing using Python and SQL- Using Python and Tools for Development
                                        • 1. Manage and troubleshoot external third-party library installations and dependencies, including PyPI packages, local wheels, and source archives
                                          • 2. Develop User-Defined Functions using Pandas/Python UDF
                                            • 3. Design and implement a scalable Python project structure optimized for Databricks Asset Bundles, enabling modular development, deployment automation, and CI/CD integration
                                              - Building and Testing an ETL Pipeline with Lakeflow Declarative Pipelines, SQL, and Apache Spark
                                              • 1. Create pipeline components using control flow operators such as if/else and foreach
                                                • 2. Build and manage reliable, production-ready batch and streaming data pipelines using Lakeflow Declarative Pipelines and Auto Loader
                                                  • 3. Choose appropriate configurations for environments, dependencies, high-memory notebook tasks, and retry behavior
                                                    • 4. Explain the advantages and disadvantages of streaming tables compared to materialized views
                                                      • 5. Create and automate ETL workloads using Jobs through the UI, APIs, or CLI
                                                        • 6. Use APPLY CHANGES APIs to simplify CDC in Lakeflow Declarative Pipelines
                                                          • 7. Compare Spark Structured Streaming and Lakeflow Declarative Pipelines to determine the optimal approach for scalable ETL pipelines
                                                            • 8. Develop unit and integration tests using assertDataFrameEqual, assertSchemaEqual, DataFrame.transform, testing frameworks, and debugging tools
                                                              Topic 8: Debugging and Deploying- Deploying CI/CD
                                                              • 1. Configure and integrate Git-based CI/CD workflows using Databricks Git folders for notebook and code deployment
                                                                • 2. Build and deploy Databricks resources using Databricks Asset Bundles
                                                                  - Debugging and Troubleshooting
                                                                  • 1. Identify diagnostic information using Spark UI, cluster logs, system tables, and query profiles to troubleshoot errors
                                                                    • 2. Use Lakeflow Declarative Pipelines event logs and Spark UI to debug Lakeflow Declarative Pipelines and Spark pipelines
                                                                      • 3. Analyze errors and remediate failed job runs using job repairs and parameter overrides
                                                                        Topic 9: Ensuring Data Security and Compliance- Applying Data Security Mechanisms
                                                                        • 1. Apply anonymization and pseudonymization methods including hashing, tokenization, suppression, and generalization
                                                                          • 2. Use row filters and column masks to protect sensitive table data
                                                                            • 3. Use ACLs to secure workspace objects and enforce the principle of least privilege
                                                                              - Ensuring Compliance
                                                                              • 1. Develop data purging solutions that comply with data retention policies
                                                                                • 2. Implement compliant batch and streaming pipelines that detect and mask PII
                                                                                  Topic 10: Cost & Performance Optimization- Optimize cost and performance
                                                                                  • 1. Understand Databricks query optimization techniques for large datasets, including data skipping and file pruning
                                                                                    • 2. Use query profiling to identify bottlenecks such as inefficient joins and data shuffling
                                                                                      • 3. Understand how and why Unity Catalog managed tables reduce operational overhead and maintenance burden
                                                                                        • 4. Apply Change Data Feed to address streaming table limitations and improve latency
                                                                                          • 5. Understand Delta optimization techniques such as deletion vectors and liquid clustering

                                                                                            >> Study Guide Certified-Data-Engineer-Professional Pdf <<

                                                                                            Authoritative Certified-Data-Engineer-Professional – 100% Free Study Guide Pdf | Certified-Data-Engineer-Professional Valid Exam Voucher

                                                                                            With all of these Certified-Data-Engineer-Professional study materials, your success is 100% guaranteed. Moreover, we have Demos as freebies. The free demos give you a prove-evident and educated guess about the content of our Certified-Data-Engineer-Professional practice materials. As long as you make up your mind on this exam, you can realize their profession is unquestionable. And their profession is expressed in our Certified-Data-Engineer-Professional training prep thoroughly. They are great help to pass the Certified-Data-Engineer-Professional exam and give you an unforgettable experience.

                                                                                            Databricks Certified Data Engineer Professional Sample Questions (Q97-Q102):

                                                                                            NEW QUESTION # 97
                                                                                            The data engineer team is configuring environment for development testing, and production before beginning migration on a new data pipeline. The team requires extensive testing on both the code and data resulting from code execution, and the team want to develop and test against similar production data as possible.
                                                                                            A junior data engineer suggests that production data can be mounted to the development testing environments, allowing pre production code to execute against production data. Because all users have Admin privileges in the development environment, the junior data engineer has offered to configure permissions and mount this data for the team.
                                                                                            Which statement captures best practices for this situation?

                                                                                            Answer: D

                                                                                            Explanation:
                                                                                            The best practice in such scenarios is to ensure that production data is handled securely and with proper access controls. By granting only read access to production data in development and testing environments, it mitigates the risk of unintended data modification. Additionally, maintaining isolated databases for different environments helps to avoid accidental impacts on production data and systems.


                                                                                            NEW QUESTION # 98
                                                                                            The view updates represents an incremental batch of all newly ingested data to be inserted or updated in the customers table.
                                                                                            The following logic is used to process these records.
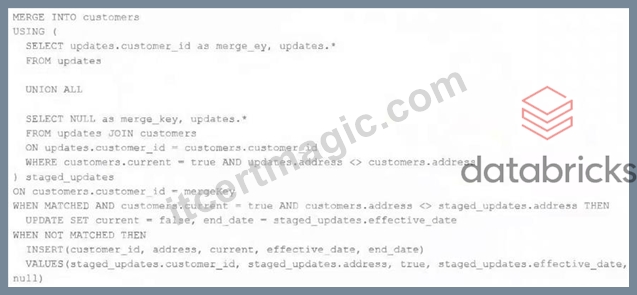
                                                                                            Which statement describes this implementation?

                                                                                            Answer: A


                                                                                            NEW QUESTION # 99
                                                                                            A member of the data engineering team has submitted a short notebook that they wish to schedule as part of a larger data pipeline. Assume that the commands provided below produce the logically correct results when run as presented.
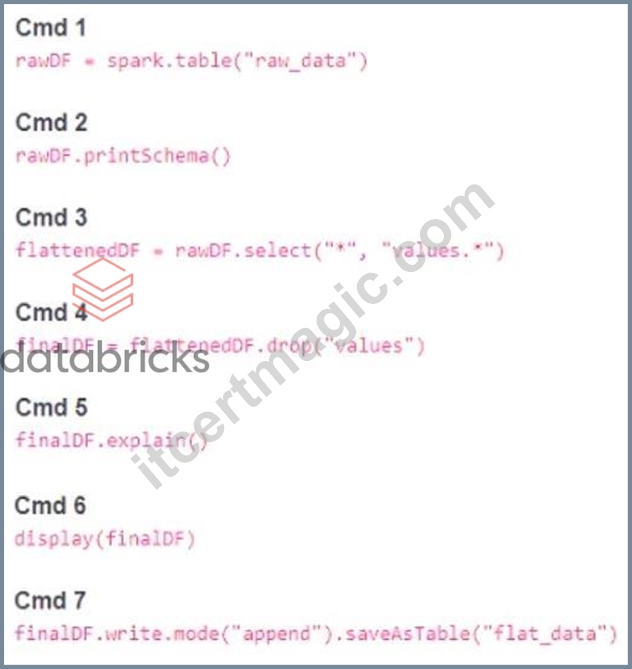
                                                                                            Which command should be removed from the notebook before scheduling it as a job?

                                                                                            Answer: A

                                                                                            Explanation:
                                                                                            When scheduling a Databricks notebook as a job, it's generally recommended to remove or modify commands that involve displaying output, such as using the display() function. Displaying data using display() is an interactive feature designed for exploration and visualization within the notebook interface and may not work well in a production job context.
                                                                                            The finalDF.explain() command, which provides the execution plan of the DataFrame transformations and actions, is often useful for debugging and optimizing queries. While it doesn't display interactive visualizations like display(), it can still be informative for understanding how Spark is executing the operations on your DataFrame.


                                                                                            NEW QUESTION # 100
                                                                                            Each configuration below is identical to the extent that each cluster has 400 GB total of RAM, 160 total cores and only one Executor per VM.
                                                                                            Given a job with at least one wide transformation, which of the following cluster configurations will result in maximum performance?

                                                                                            Answer: B

                                                                                            Explanation:
                                                                                            https://docs.databricks.com/en/clusters/cluster-config-best-practices.html


                                                                                            NEW QUESTION # 101
                                                                                            What statement is true regarding the retention of job run history?

                                                                                            Answer: A

                                                                                            Explanation:
                                                                                            https://docs.databricks.com/en/workflows/jobs/monitor-job-runs.html


                                                                                            NEW QUESTION # 102
                                                                                            ......

                                                                                            You can download ITCertMagic Databricks Certified-Data-Engineer-Professional PDF dumps file on your desktop computer, laptop, tab, or even on your smartphone. Just download the Certified-Data-Engineer-Professional PDF questions file after paying affordable Prepare for your Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) exam questions charges and start Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) exam preparation anytime and anywhere.

                                                                                            Certified-Data-Engineer-Professional Valid Exam Voucher: https://www.itcertmagic.com/Databricks/real-Certified-Data-Engineer-Professional-exam-prep-dumps.html