Databricks-Certified-Data-Engineer-Associate Valid Exam Notes - Databricks-Certified-Data-Engineer-Associate Valid Exam Papers

DOWNLOAD the newest VCEPrep Databricks-Certified-Data-Engineer-Associate PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1FiiTzTPKLW30Zcg4JyWL6wBk8PdZquvk
Our test-orientated high-quality Databricks-Certified-Data-Engineer-Associate exam questions would be the best choice for you, we sincerely hope all of our candidates can pass Databricks-Certified-Data-Engineer-Associate exam, and enjoy the tremendous benefits of our Databricks-Certified-Data-Engineer-Associate prep guide. Helping candidates to pass the Databricks-Certified-Data-Engineer-Associate Exam has always been a virtue in our company’s culture, and you can connect with us through email at the process of purchasing and using, we would reply you as fast as we can.
| Section | Weight | Objectives |
|---|
| Topic 1: Data Processing & Transformations | 31% | - Data transformation techniques
- 1. Aggregations, joins, and window functions
- 2. DataFrame operations and transformations
- 3. Complex data processing logic
- Query optimization and performance
- 1. Understanding query plans
- 2. Optimization strategies
|
| Topic 2: Development and Ingestion | 30% | - Data ingestion patterns and methods
- 1. Batch and streaming ingestion
- 2. Delta Lake basics and usage
- 3. Connecting to external data sources
- Notebook development fundamentals
- 1. Data exploration and validation
- 2. Using PySpark and Spark SQL
|
| Topic 3: Databricks Intelligence Platform | 10% | - Platform architecture and core concepts
- 1. Data layout and optimization: partitioning, file sizing, caching
- 2. Compute options: clusters, SQL warehouses, serverless
- 3. Workspace navigation and management
|
| Topic 4: Productionizing Data Pipelines | 18% | - Workflow orchestration
- 1. Lakeflow Jobs creation and management
- 2. Scheduling, triggers, and dependencies
- Deployment and CI/CD
- 1. Version control integration
- 2. Databricks Asset Bundles
- Monitoring and troubleshooting
- 1. Logging and error handling
- 2. Pipeline reliability and recovery
|
| Topic 5: Data Governance & Quality | 11% | - Data quality and reliability
- 1. Data validation and quality checks
- 2. Schema enforcement and evolution
- Unity Catalog implementation
- 1. Permissions and access control
- 2. Data governance model
|
>> Databricks-Certified-Data-Engineer-Associate Valid Exam Notes <<
Databricks Databricks-Certified-Data-Engineer-Associate Valid Exam Notes | Amazing Pass Rate For Your Databricks-Certified-Data-Engineer-Associate: Databricks Certified Data Engineer Associate Exam | Databricks-Certified-Data-Engineer-Associate Valid Exam Papers
All Databricks-Certified-Data-Engineer-Associate exam questions are available at an affordable cost and fulfill all your training needs. VCEPrep knows that applicants of the Databricks Databricks-Certified-Data-Engineer-Associate examination are different from each other. Each candidate has different study styles and that's why we offer our Databricks Databricks-Certified-Data-Engineer-Associate product in three formats. These formats are Databricks-Certified-Data-Engineer-Associate PDF, desktop practice test software, and web-based practice exam.
Databricks Certified Data Engineer Associate Exam Sample Questions (Q116-Q121):
NEW QUESTION # 116
A data engineer configures a Databricks Lakeflow Job for daily customer data processing:
- Entry task: Single notebook loads raw data
- Parallel tasks:
- SQL query task for cleansing
- Notebook task for feature engineering
- Pipeline task for model updates
- Exit task: Dashboard refresh (must run after all parallel tasks
complete)
- Requirement: Implement this dependency pattern using a DAG-based task graph Which task configuration ensures all parallel tasks complete before the dashboard refresh task runs?
- A. Set the dashboard task to depend only on the SQL query task; other tasks run independently.
- B. Configure the parallel tasks with sequential dependencies so each task waits for the previous one to finish.
- C. Create separate Lakeflow Jobs for each parallel task and trigger them sequentially using external orchestration.
- D. Add the dashboard task as dependent on all three parallel tasks using fan-in control flow.
Answer: D
Explanation:
A fan-in dependency makes the dashboard refresh task depend on all three parallel tasks.
Databricks runs the parallel tasks after the entry task, and the dashboard refresh starts only after every upstream dependency completes.
NEW QUESTION # 117
A data engineer wants to create a data entity from a couple of tables. The data entity must be used by other data engineers in other sessions. It also must be saved to a physical location.
Which of the following data entities should the data engineer create?
- A. Database
- B. Table
- C. View
- D. Temporary view
- E. Function
Answer: B
Explanation:
A table is a data entity that is stored in a physical location and can be accessed by other data engineers in other sessions. A table can be created from one or more tables using the CREATE TABLE or CREATE TABLE AS SELECT commands. A table can also be registered from an existing DataFrame using the spark.catalog.createTable method. A table can be queried using SQL or DataFrame APIs. A table can also be updated, deleted, or appended using the MERGE INTO command or the DeltaTable API. References:
* Create a table
* Create a table from a query result
* Register a table from a DataFrame
* [Query a table]
* [Update, delete, or merge into a table]
NEW QUESTION # 118
A data engineer is reading a very large dataset that contains skewed key values. Some partitions contain significantly more records than others, causing uneven workload distribution across executors. Which Spark issue does this scenario describe?
- A. Lazy evaluation
- B. Broadcast failure
- C. Schema evolution
- D. Data skew
Answer: D
NEW QUESTION # 119
A data engineer is using the following code block as part of a batch ingestion pipeline to read from a composable table:
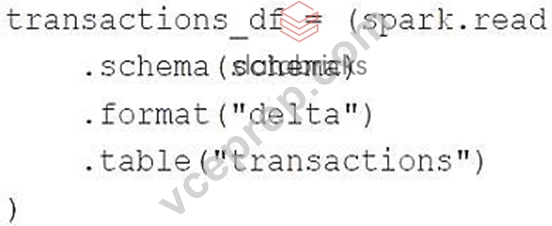
Which of the following changes needs to be made so this code block will work when the transactions table is a stream source?
- A. Replace " transactions " with the path to the location of the Delta table
- B. Replace predict with a stream-friendly prediction function
- C. Replace spark.read with spark.readStream
- D. Replace schema(schema) with option ( " maxFilesPerTrigger " , 1)
- E. Replace format( " delta " ) with format( " stream " )
Answer: C
Explanation:
To read from a stream source, the data engineer needs to use the spark.readStream method instead of the spark.
read method. The spark.readStream method returns a DataStreamReader object that can be used to specify the details of the input source, such as the format, the schema, the path, and the options. The spark.read method is only suitable for batch processing, not streaming processing. The other changes are not necessary or correct for reading from a stream source. References: Structured Streaming Programming Guide, Read a stream, Databricks Data Sources
NEW QUESTION # 120
A data analysis team has noticed that their Databricks SQL queries are running too slowly when connected to their always-on SQL endpoint. They claim that this issue is present when many members of the team are running small queries simultaneously. They ask the data engineering team for help. The data engineering team notices that each of the team's queries uses the same SQL endpoint.
Which of the following approaches can the data engineering team use to improve the latency of the team's queries?
- A. They can turn on the Auto Stop feature for the SQL endpoint.
- B. They can turn on the Serverless feature for the SQL endpoint and change the Spot Instance Policy to
"Reliability Optimized." - C. They can increase the cluster size of the SQL endpoint.
- D. They can turn on the Serverless feature for the SQL endpoint.
- E. They can increase the maximum bound of the SQL endpoint's scaling range.
Answer: A
Explanation:
https://community.databricks.com/t5/data-engineering/sequential-vs-concurrency-optimization-questions- from-query/td-p/36696
NEW QUESTION # 121
......
Do not ask me why you should purchase Databricks Certified Data Engineer Associate Exam Databricks-Certified-Data-Engineer-Associate valid exam prep, of course it is because of its passing rate. As every one knows certificaiton is difficult to pass, its passing rate is low, if you want to save exam cost and money, choosing a Databricks-Certified-Data-Engineer-Associate Valid Exam Prep will be a nice option.
Databricks-Certified-Data-Engineer-Associate Valid Exam Papers: https://www.vceprep.com/Databricks-Certified-Data-Engineer-Associate-latest-vce-prep.html
- Newest Databricks-Certified-Data-Engineer-Associate Valid Exam Notes offer you accurate Valid Exam Papers | Databricks Databricks Certified Data Engineer Associate Exam 🍌 Immediately open 《 www.pass4test.com 》 and search for ▶ Databricks-Certified-Data-Engineer-Associate ◀ to obtain a free download 🔪Databricks-Certified-Data-Engineer-Associate Exam Engine
- 100% Pass 2026 Marvelous Databricks Databricks-Certified-Data-Engineer-Associate Valid Exam Notes 🌈 Search for ➠ Databricks-Certified-Data-Engineer-Associate 🠰 on ➡ www.pdfvce.com ️⬅️ immediately to obtain a free download 🐆Dumps Databricks-Certified-Data-Engineer-Associate Discount
- Databricks-Certified-Data-Engineer-Associate Practice Materials: Databricks Certified Data Engineer Associate Exam - Databricks-Certified-Data-Engineer-Associate Real Exam Dumps - www.troytecdumps.com 🌆 Download ( Databricks-Certified-Data-Engineer-Associate ) for free by simply entering ✔ www.troytecdumps.com ️✔️ website 🧥Reliable Databricks-Certified-Data-Engineer-Associate Exam Simulator
- Free PDF 2026 Databricks-Certified-Data-Engineer-Associate: Professional Databricks Certified Data Engineer Associate Exam Valid Exam Notes 🔱 The page for free download of ( Databricks-Certified-Data-Engineer-Associate ) on 「 www.pdfvce.com 」 will open immediately 🦈Databricks-Certified-Data-Engineer-Associate Exam Engine
- Databricks-Certified-Data-Engineer-Associate Practice Materials: Databricks Certified Data Engineer Associate Exam - Databricks-Certified-Data-Engineer-Associate Real Exam Dumps - www.pdfdumps.com 🥃 Search for [ Databricks-Certified-Data-Engineer-Associate ] and download exam materials for free through ➽ www.pdfdumps.com 🢪 🔌Databricks-Certified-Data-Engineer-Associate Materials
- Test Databricks-Certified-Data-Engineer-Associate Result 🥀 Formal Databricks-Certified-Data-Engineer-Associate Test 🟡 Current Databricks-Certified-Data-Engineer-Associate Exam Content 🌺 Search for ⮆ Databricks-Certified-Data-Engineer-Associate ⮄ and download it for free on ➥ www.pdfvce.com 🡄 website ⚜Databricks-Certified-Data-Engineer-Associate Exam Labs
- Unparalleled Databricks-Certified-Data-Engineer-Associate Valid Exam Notes, Databricks-Certified-Data-Engineer-Associate Valid Exam Papers ⛑ Search on ➠ www.prepawaypdf.com 🠰 for { Databricks-Certified-Data-Engineer-Associate } to obtain exam materials for free download 🕵Databricks-Certified-Data-Engineer-Associate Reliable Test Tips
- Databricks-Certified-Data-Engineer-Associate Exam Engine 😨 Databricks-Certified-Data-Engineer-Associate Reliable Test Tips 🧞 Flexible Databricks-Certified-Data-Engineer-Associate Learning Mode ✊ Search on 《 www.pdfvce.com 》 for ➠ Databricks-Certified-Data-Engineer-Associate 🠰 to obtain exam materials for free download 💯Databricks-Certified-Data-Engineer-Associate Latest Exam Review
- Features of Databricks-Certified-Data-Engineer-Associate Practice Material 🐫 [ www.prepawaypdf.com ] is best website to obtain ⮆ Databricks-Certified-Data-Engineer-Associate ⮄ for free download 🧧Databricks-Certified-Data-Engineer-Associate Reliable Test Tips
- Databricks-Certified-Data-Engineer-Associate Practice Materials: Databricks Certified Data Engineer Associate Exam - Databricks-Certified-Data-Engineer-Associate Real Exam Dumps - Pdfvce 🎷 Download ▷ Databricks-Certified-Data-Engineer-Associate ◁ for free by simply entering ▛ www.pdfvce.com ▟ website 📁Exam Databricks-Certified-Data-Engineer-Associate Format
- Dumps Databricks-Certified-Data-Engineer-Associate Discount 🕡 New Databricks-Certified-Data-Engineer-Associate Dumps Files 🕶 Test Databricks-Certified-Data-Engineer-Associate Simulator 🐆 Open ✔ www.examcollectionpass.com ️✔️ enter ☀ Databricks-Certified-Data-Engineer-Associate ️☀️ and obtain a free download 🐝Databricks-Certified-Data-Engineer-Associate Exam Labs
- www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
2026 Latest VCEPrep Databricks-Certified-Data-Engineer-Associate PDF Dumps and Databricks-Certified-Data-Engineer-Associate Exam Engine Free Share: https://drive.google.com/open?id=1FiiTzTPKLW30Zcg4JyWL6wBk8PdZquvk