We provide our customers with the most reliable learning materials about CCAR-P certification exam and the guarantee of pass. We assist you to prepare the key knowledge points of CCAR-P actual test and obtain the up-to-dated exam answers. All CCAR-P Test Questions offered by us are tested and selected by our senior experts in IT filed, which only need little time to focus on the practice and the preparation.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Governance, Safety & Risk Management | 14% | - Ensure regulatory compliance (GDPR, HIPAA, etc.) - Address ethical AI considerations and bias mitigation - Manage data privacy and security compliance - Implement guardrails and safety controls |
| Topic 2: Integration | 19% | - Design authentication, authorization, and observability - Integrate with data pipelines and RAG systems - Implement Model Context Protocol (MCP) integrations - Integrate Claude with enterprise systems, APIs, and tools |
| Topic 3: Solution Design & Architecture | 17% | - Design multi-agent systems and orchestration strategies - Align solutions to business value pillars - Select architectural patterns: workflow, agentic, augmented LLM - Translate business problems into Claude-based AI solutions - Design end-to-end architectures and feedback loops |
| Topic 4: Claude Models, Prompting & Context Engineering | 13% | - Apply context engineering and context management techniques - Mitigate prompt injection, leaks, and jailbreak risks - Design system prompts, templates, and guardrails - Select appropriate Claude models based on trade-offs |
| Topic 5: Evaluation, Testing & Optimization | 16% | - Optimize performance, prompting, and model selection - Define evaluation metrics and success criteria - Implement iterative improvement pipelines - Test accuracy, reliability, latency, and cost |
| Topic 6: Stakeholder Communication & Lifecycle Management | 14% | - Conduct structured discovery and requirement gathering - Manage stakeholder feedback and expectation alignment - Document architectures and support full lifecycle phases - Communicate architectural decisions and trade-offs |
| Topic 7: Developer Productivity & Operational Enablement | 7% | - Support debugging, monitoring, and operational resolution - Configure Claude tools and environments for teams - Improve developer workflows with AI-assisted tooling |
>> CCAR-P Actual Braindumps <<
The customer is God. CCAR-P learning dumps provide all customers with high quality after-sales service. After your payment is successful, we will dispatch a dedicated IT staff to provide online remote assistance for you to solve problems in the process of download and installation. During your studies, CCAR-P study tool will provide you with efficient 24-hour online services. You can email us anytime, anywhere to ask any questions you have about our CCAR-P Study Tool. At the same time, CCAR-P test question will also generate a report based on your practice performance to make you aware of the deficiencies in your learning process and help you develop a follow-up study plan so that you can use the limited energy where you need it most. So with CCAR-P study tool you can easily pass the exam.
NEW QUESTION # 115
A managed agent deployment for claims triage has grown from 6 tools to 34 tools over 18 months as product teams added capabilities. Triage accuracy has declined from 91 percent to 78 percent, and average tool- selection latency has increased by 2.3 seconds. A junior engineer has proposed adding a tool-router agent in front of the current agent to filter the tool list per request.
Which two findings should you present to justify capability decomposition before adding the router? (Select two.) Each correct answer presents part of the solution.
Answer: A,E
Explanation:
Four distinct workflow domains indicate that the agent's responsibilities have expanded beyond a cohesive capability boundary. Decomposing the deployment into domain-focused agents reduces each agent's tool- selection space and produces clearer prompts, permissions, evaluations, and ownership. Option E strengthens this conclusion because placing a model-based router before the existing overloaded agent adds latency, cost, and another failure point without correcting the underlying capability sprawl. Overlapping descriptions should be clarified, while unused tools may simply be removed; neither finding alone proves that separate domain agents are required. Public documentation of a pattern is not evidence that it fits this workload. Anthropic emphasizes simple composable patterns, clearly differentiated tools, and empirical evaluation before adding orchestration complexity. Building Effective Agents
NEW QUESTION # 116
You are evaluating retrieval-strategy claims used by a peer team.
For each claim, select yes if the statement is generally accurate. Otherwise, select no.
Answer:
Explanation:
Explanation:
Yes, Yes, Yes, No, No
Dense vector retrieval represents semantic similarity, making it suitable for matching paraphrases and conceptually related language even when the query and source do not share identical words. Sparse lexical retrieval, including BM25-style matching, retains strong sensitivity to exact tokens and is therefore valuable for identifiers, product codes, technical names, and uncommon terminology.
Structured query retrieval is appropriate when the required operation depends on explicit fields, predicates, joins, counts, grouping, or aggregation over a relational schema. In that situation, generating or invoking a constrained database query is more precise than approximating the operation through semantic similarity.
Hybrid retrieval is not identical to dense retrieval. It combines semantic and lexical candidate sets, typically followed by rank fusion or reranking. Anthropic's contextual-retrieval guidance explains that semantic search captures meaning and paraphrases, while BM25 captures exact terminology; combining them improves coverage. Contextual Retrieval, Contextual Retrieval Cookbook Random sampling is not a relevance strategy. It provides no systematic relationship between the query and selected evidence, producing unstable coverage and preventable hallucination risk. Production Q & A requires deterministic or evaluated relevance mechanisms, access filters, suitable indexes, and measurable retrieval metrics such as recall at k.
Study Guide references/topics: Dense retrieval; sparse retrieval; structured queries; hybrid search; rank fusion; retrieval evaluation; production RAG design.
NEW QUESTION # 117
You are a solution architect evaluating candidate use cases for a Claude-based program.
For each scenario, select Yes if Claude is appropriate as the primary solution at the architectural level.
Otherwise, select No.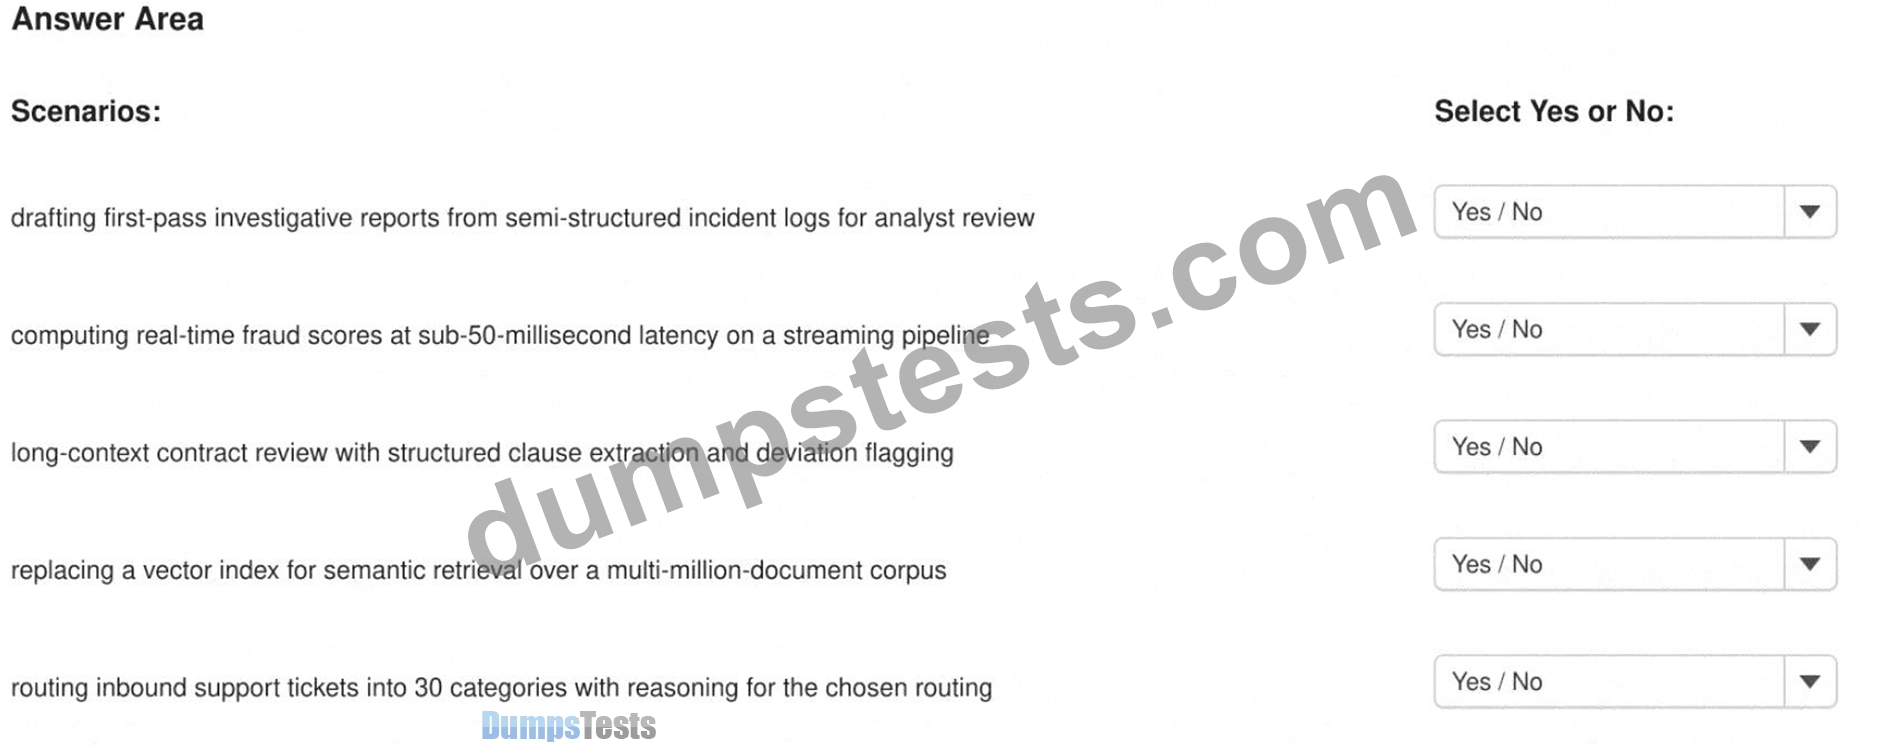
Answer:
Explanation:
Explanation:
Drafting first-pass investigative reports from semi-structured incident logs for analyst review - Yes Computing real-time fraud scores at sub-50-millisecond latency on a streaming pipeline - No Long-context contract review with structured clause extraction and deviation flagging - Yes Replacing a vector index for semantic retrieval over a multi-million-document corpus - No Routing inbound support tickets into 30 categories with reasoning for the selected route - Yes Claude is well suited to language-intensive analysis, summarization, extraction, classification, and drafting.
Investigative-report drafting, contract analysis, and support-ticket routing all require interpretation of unstructured or semi-structured language and can incorporate human review. A sub-50-millisecond fraud- scoring path requires deterministic, specialized real-time processing and should not place LLM inference on the critical path. Claude also does not replace the retrieval index used to search millions of documents; it consumes the results produced by that infrastructure. The correct architectural decision separates tasks requiring semantic language reasoning from deterministic computation and information-retrieval infrastructure. Model selection and evaluation must then confirm that the chosen Claude model satisfies quality, latency, and cost requirements.
NEW QUESTION # 118
A research summarization assistant has been deployed for six months. A user has flagged that a generated summary contained a fabricated citation. The product team has asked whether the incident requires architectural action or whether it is an isolated case.
Which two Diligence-competency actions should you take? (Select two.)
Each correct answer presents part of the solution.
Answer: A,D
Explanation:
A single confirmed fabrication requires investigation, but it does not establish the population-level failure rate. Sampling recent summaries determines prevalence, affected content types, and whether the incident correlates with particular prompts, documents, or model versions. The architecture must also be examined for grounding controls, including source-constrained generation, citation rendering, claim-to-source verification, and rejection of unsupported statements. Anthropic recommends making factual outputs auditable through citations and requiring supporting quotations for important claims. Immediate universal shutdown may become necessary if the risk is severe, but doing so before establishing scope is not the most disciplined first response. Options D and E dismiss evidence without validation and would prevent corrective action.
Reducing hallucinations
NEW QUESTION # 119
You are designing the prompt for a ticket-triage classifier with thirty well-defined categories and clear category descriptions in the prompt.
Which technique is most appropriate as the starting point?
Answer: D
Explanation:
A clearly defined closed-set classification task should begin with a concise zero-shot prompt containing the permitted categories, unambiguous category descriptions, and the required output structure. This provides a simple, inexpensive baseline that can be measured against a representative evaluation set. Chain-of-thought prompting adds unnecessary latency and token usage when the routing decision does not require substantive multi-step reasoning. Permitting Claude to invent categories would violate the closed-set contract and complicate downstream automation. Omitting descriptions would increase ambiguity among potentially overlapping labels. If evaluation later reveals persistent confusion between particular categories, the architect can introduce targeted examples or refine the definitions. Prompt complexity should be added in response to measured failure patterns, not assumed to be necessary before establishing baseline performance. Anthropic:
Prompt engineering overview
NEW QUESTION # 120
......
After taking a bird's eye view of applicants' issues, DumpsTests has decided to provide them with the real CCAR-P Questions. These CCAR-P dumps pdf is according to the new and updated syllabus so they can prepare for CCAR-P certification anywhere, anytime, with ease. A team of professionals has made the product of DumpsTests after much hard work with their complete potential so the candidates can prepare for Claude Certified Architect - Professional (CCAR-P) practice test in a short time.
Vce CCAR-P Files: https://www.dumpstests.com/CCAR-P-latest-test-dumps.html