No matter how old you are, no matter what kind of job you are in, as long as you want to pass the professional qualification exam, Databricks-Certified-Professional-Data-Engineer exam dump must be your best choice. All the materials in Databricks-Certified-Professional-Data-Engineer test guide is available in PDF, APP, and PC versions. If you are a student, you can take the time to simulate the real test environment on the computer online. If you are an office worker, Databricks-Certified-Professional-Data-Engineer practice materials provide you with an APP version that allows you to transfer data to your mobile phone and do exercises at anytime, anywhere. If you are a middle-aged person and you don't like the complex features of cell phones and computers, Databricks-Certified-Professional-Data-Engineer practice materials also provide you with a PDF mode so that you can print out the materials and learn. At the same time, Databricks-Certified-Professional-Data-Engineer test guide involve hundreds of professional qualification examinations. No matter which industry you are in, Databricks-Certified-Professional-Data-Engineer practice materials can meet you.
Databricks is a leading company in the field of data engineering and machine learning. The company offers a wide range of services and tools to help organizations manage and analyze their data more effectively. One of the key offerings from Databricks is the Databricks Certified Professional Data Engineer (Databricks-Certified-Professional-Data-Engineer) certification exam. Databricks-Certified-Professional-Data-Engineer Exam is designed to test the skills and knowledge of data engineers who work with Databricks.
Databricks Certified Professional Data Engineer (Databricks-Certified-Professional-Data-Engineer) certification exam is designed for data professionals who want to validate their skills and knowledge in building and deploying data engineering solutions using Databricks. Databricks is a unified data analytics platform that provides a collaborative environment for data engineers, data scientists, and business analysts to work together on big data projects. Databricks Certified Professional Data Engineer Exam certification exam covers a range of topics such as data ingestion, data processing, data transformation, and data storage using Databricks.
>> Simulation Databricks-Certified-Professional-Data-Engineer Questions <<
Our Databricks-Certified-Professional-Data-Engineer exam prep is elaborately compiled and highly efficiently, it will cost you less time and energy, because we shouldn’t waste our money on some unless things. The passing rate and the hit rate are also very high, there are thousands of candidates choose to trust our Databricks-Certified-Professional-Data-Engineer guide torrent and they have passed the exam. We provide with candidate so many guarantees that they can purchase our study materials no worries. So we hope you can have a good understanding of the Databricks-Certified-Professional-Data-Engineer Exam Torrent we provide, then you can pass you exam in your first attempt.
Databricks Certified Professional Data Engineer exam is an excellent choice for data engineers who want to demonstrate their expertise in using Databricks to process big data. Databricks Certified Professional Data Engineer Exam certification exam is recognized globally and highly valued by organizations that use Databricks for their big data processing needs. By passing the exam, data engineers can validate their knowledge and skills and increase their chances of career advancement.
NEW QUESTION # 174
All records from an Apache Kafka producer are being ingested into a single Delta Lake table with the following schema:
key BINARY, value BINARY, topic STRING, partition LONG, offset LONG, timestamp LONG There are 5 unique topics being ingested. Only the "registration" topic contains Personal Identifiable Information (PII). The company wishes to restrict access to PII. The company also wishes to only retain records containing PII in this table for 14 days after initial ingestion. However, for non-PII information, it would like to retain these records indefinitely.
Which of the following solutions meets the requirements?
Answer: D
Explanation:
Explanation
Partitioning the data by the topic field allows the company to apply different access control policies and retention policies for different topics. For example, the company can use the Table Access Control feature to grant or revoke permissions to the registration topic based on user roles or groups. The company can also use the DELETE command to remove records from the registration topic that are older than 14 days, while keeping the records from other topics indefinitely. Partitioning by the topic field also improves the performance of queries that filter by the topic field, as they can skip reading irrelevant partitions. References:
Table Access Control: https://docs.databricks.com/security/access-control/table-acls/index.html DELETE: https://docs.databricks.com/delta/delta-update.html#delete-from-a-table
NEW QUESTION # 175
A notebook accepts an input parameter that is assigned to a python variable called department and this is an optional parameter to the notebook, you are looking to control the flow of the code using this parameter. you have to check department variable is present then execute the code and if no department value is passed then skip the code execution. How do you achieve this using python?
Answer: E
Explanation:
Explanation
The answer is,
1.if department is not None:
2. #Execute code
3.else:
4. pass
NEW QUESTION # 176
An organization processes customer data from web and mobile applications. Data includes names, emails, phone numbers, and location history. Data arrives both as batch files (from SFTP daily) and streaming JSON events (from Kafka in real-time).
To comply with data privacy policies, the following requirements must be met:
* Personally Identifiable Information (PII) such as email, phone number, and IP address must be masked or anonymized before storage.
* Both batch and streaming pipelines must apply consistent PII handling.
* Masking logic must be auditable and reproducible.
* The masked data must remain usable for downstream analytics.
How should the data engineer design a compliant data pipeline on Databricks that supports both batch and streaming modes, applies data masking to PII, and maintains traceability for audits?
Answer: D
Explanation:
Databricks recommends applying data masking or anonymization before persisting PII to ensure compliance with privacy regulations such as GDPR and HIPAA. In a Lakeflow Declarative Pipeline , developers can define custom Python or SQL-based masking functions to standardize PII handling across both batch and streaming inputs.
This approach ensures that data entering the Delta Lake is already anonymized, guaranteeing consistent and auditable behavior. By applying masking during ingestion (in the Bronze layer), audit trails are preserved through pipeline event logs.
While Unity Catalog column masks (option C) can enforce dynamic masking at query time, they do not prevent PII storage. Thus, option D aligns with the best practice of securing PII before storage , while still supporting reproducibility and analytics usability.
NEW QUESTION # 177
A data engineer is creating a daily reporting job. There are two reporting notebooks-one for weekdays and one for weekends. An "if/else condition" task is configured as {{job.start_time.is_weekday}} == true to route the job to either the weekday or weekend notebook tasks. The same job would be used across multiple time zones.
Which action should a senior data engineer take upon reviewing the job to merge or reject the pull request?
Answer: C
Explanation:
Databricks parameter templates like {{job.start_time.is_weekday}} evaluate in UTC time by default, not in local workspace or regional time zones. Therefore, when jobs are configured to run across different time zones, relying on is_weekday using UTC may cause scheduling and task routing mismatches (for example, triggering the weekday notebook in one region while it's still the weekend locally).
Databricks recommends adjusting conditional logic or pipeline parameters explicitly to handle time zone conversions if business requirements depend on local times. Because the engineer's configuration does not account for this behavior, a senior data engineer should reject the pull request and suggest time-zone-aware logic before merging.
NEW QUESTION # 178
The data science team has created and logged a production model using MLflow. The following code correctly imports and applies the production model to output the predictions as a new DataFrame named preds with the schema "customer_id LONG, predictions DOUBLE, date DATE".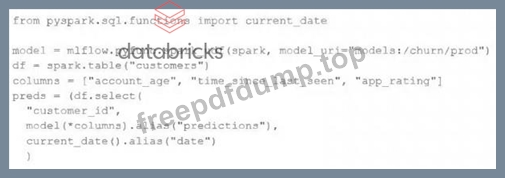
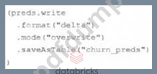
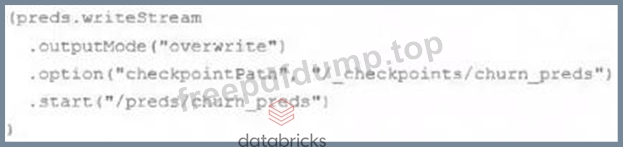
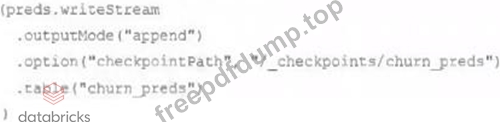
The data science team would like predictions saved to a Delta Lake table with the ability to compare all predictions across time. Churn predictions will be made at most once per day.
Which code block accomplishes this task while minimizing potential compute costs?
Answer: E
NEW QUESTION # 179
......
Databricks-Certified-Professional-Data-Engineer Valid Dumps Demo: https://www.freepdfdump.top/Databricks-Certified-Professional-Data-Engineer-valid-torrent.html