Our Databricks-Certified-Data-Analyst-Associate study materials can help you achieve your original goal and help your work career to be smoother and your family life quality to be better and better. There is no exaggeration to say that you will be confident to take part in you Databricks-Certified-Data-Analyst-Associate exam with only studying our Databricks-Certified-Data-Analyst-Associate practice torrent for 20 to 30 hours. And we can ensure your success for we have been professional in this career for over 10 years. And thousands of candidates have achieved their dreams and ambitions with the help of our outstanding Databricks-Certified-Data-Analyst-Associate training materials.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
| Topic 5 |
|
>> Latest Databricks-Certified-Data-Analyst-Associate Test Preparation <<
As you know, the low-quality latest Databricks-Certified-Data-Analyst-Associate exam torrent may do harmful influence on you which may causes results past redemption. Whether you have experienced that problem or not was history by now. The exam will be vanquished smoothly this time by the help of valid latest Databricks-Certified-Data-Analyst-Associate exam torrent. Written by meticulous and professional experts in this area, their quality has reached to the highest level compared with others’ similar Databricks-Certified-Data-Analyst-Associate Test Prep and concord with the syllabus of the exam perfectly. Their questions points provide you with simulation environment to practice. In that case, when you sit in the real Databricks-Certified-Data-Analyst-Associate exam room, you can deal with almost every question with ease.
NEW QUESTION # 27
A data scientist has asked a data analyst to create histograms for every continuous variable in a data set. The data analyst needs to identify which columns are continuous in the data set.
What describes a continuous variable?
Answer: C
Explanation:
A continuous variable is a type of quantitative variable that can assume an infinite number of values within a given range. This means that between any two possible values, there can be an infinite number of other values. For example, variables such as height, weight, and temperature are continuous because they can be measured to any level of precision, and there are no gaps between possible values. This is in contrast to discrete variables, which can only take on specific, distinct values (e.g., the number of children in a family). Understanding the nature of continuous variables is crucial for data analysts, especially when selecting appropriate statistical methods and visualizations, such as histograms, to accurately represent and analyze the data.
NEW QUESTION # 28
After running DESCRIBE EXTENDED accounts.customers;, the following was returned: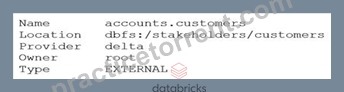
Now, a data analyst runs the following command:
DROP accounts.customers;
Which of the following describes the result of running this command?
Answer: E
Explanation:
the accounts.customers table is an EXTERNAL table, which means that it is stored outside the default warehouse directory and is not managed by Databricks. Therefore, when you run the DROP command on this table, it only removes the metadata information from the metastore, but does not delete the actual data files from the file system. This means that you can still access the data using the location path (dbfs:/stakeholders/customers) or create another table pointing to the same location. However, if you try to query the table using its name (accounts.customers), you will get an error because the table no longer exists in the metastore. Reference: DROP TABLE | Databricks on AWS, Best practices for dropping a managed Delta Lake table - Databricks
NEW QUESTION # 29
A data analysis team is working with the table_bronze SQL table as a source for one of its most complex projects. A stakeholder of the project notices that some of the downstream data is duplicative. The analysis team identifies table_bronze as the source of the duplication.
Which of the following queries can be used to deduplicate the data from table_bronze and write it to a new table table_silver?
A)
CREATE TABLE table_silver AS
SELECT DISTINCT *
FROM table_bronze;
B)
CREATE TABLE table_silver AS
INSERT *
FROM table_bronze;
C)
CREATE TABLE table_silver AS
MERGE DEDUPLICATE *
FROM table_bronze;
D)
INSERT INTO TABLE table_silver
SELECT * FROM table_bronze;
E)
INSERT OVERWRITE TABLE table_silver
SELECT * FROM table_bronze;
Answer: C
Explanation:
Option A uses the SELECT DISTINCT statement to remove duplicate rows from the table_bronze and create a new table table_silver with the deduplicated data. This is the correct way to deduplicate data using Spark SQL12. Option B simply inserts all the rows from table_bronze into table_silver, without removing any duplicates. Option C is not a valid syntax for Spark SQL, as there is no MERGE DEDUPLICATE statement.
Option D appends all the rows from table_bronze into table_silver, without removing any duplicates. Option E overwrites the existing data in table_silver with the data from table_bronze, without removing any duplicates. References: Delete Duplicate using SPARK SQL, Spark SQL - How to Remove Duplicate Rows
NEW QUESTION # 30
A data engineering team has created a Structured Streaming pipeline that processes data in micro-batches and populates gold-level tables. The microbatches are triggered every minute.
A data analyst has created a dashboard based on this gold-level dat
a. The project stakeholders want to see the results in the dashboard updated within one minute or less of new data becoming available within the gold-level tables.
Which of the following cautions should the data analyst share prior to setting up the dashboard to complete this task?
Answer: D
Explanation:
A Structured Streaming pipeline that processes data in micro-batches and populates gold-level tables every minute requires a high level of compute resources to handle the frequent data ingestion, processing, and writing. This could result in a significant cost for the organization, especially if the data volume and velocity are large. Therefore, the data analyst should share this caution with the project stakeholders before setting up the dashboard and evaluate the trade-offs between the desired refresh rate and the available budget. The other options are not valid cautions because:
B . The gold-level tables are assumed to be appropriately clean for business reporting, as they are the final output of the data engineering pipeline. If the data quality is not satisfactory, the issue should be addressed at the source or silver level, not at the gold level.
C . The streaming data is an appropriate data source for a dashboard, as it can provide near real-time insights and analytics for the business users. Structured Streaming supports various sources and sinks for streaming data, including Delta Lake, which can enable both batch and streaming queries on the same data.
D . The streaming cluster is fault tolerant, as Structured Streaming provides end-to-end exactly-once fault-tolerance guarantees through checkpointing and write-ahead logs. If a query fails, it can be restarted from the last checkpoint and resume processing.
E . The dashboard can be refreshed within one minute or less of new data becoming available in the gold-level tables, as Structured Streaming can trigger micro-batches as fast as possible (every few seconds) and update the results incrementally. However, this may not be necessary or optimal for the business use case, as it could cause frequent changes in the dashboard and consume more resources. Reference: Streaming on Databricks, Monitoring Structured Streaming queries on Databricks, A look at the new Structured Streaming UI in Apache Spark 3.0, Run your first Structured Streaming workload
NEW QUESTION # 31
A data analyst has been asked to produce a visualization that shows the flow of users through a website.
Which of the following is used for visualizing this type of flow?
Answer: B
Explanation:
A Sankey diagram is a type of visualization that shows the flow of data between different nodes or categories.
It is often used to represent the movement of users through a website, as it can show the paths they take, the sources they come from, the pages they visit, and the outcomes they achieve. A Sankey diagram consists of links and nodes, where the links represent the volume or weight of the flow, and the nodes represent the stages or steps of the flow. The width of the links is proportional to the amount of flow, and the color of the links can indicate different attributes or segments of the flow. A Sankey diagram can help identify the most common or popular user journeys, the bottlenecks or drop-offs in the flow, and the opportunities for improvement or optimization. References: The answer can be verified from Databricks documentation which provides examples and instructions on how to create Sankey diagrams using Databricks SQL Analytics and Databricks Visualizations. Reference links: Databricks SQL Analytics - Sankey Diagram, Databricks Visualizations - Sankey Diagram
NEW QUESTION # 32
......
With our numerous advantages of our Databricks-Certified-Data-Analyst-Associate latest questions and service, what are you hesitating for? Our company always serves our clients with professional and precise attitudes, and we know that your satisfaction is the most important thing for us. We always aim to help you pass the Databricks-Certified-Data-Analyst-Associate Exam smoothly and sincerely hope that all of our candidates can enjoy the tremendous benefit of our Databricks-Certified-Data-Analyst-Associate exam material, which might lead you to a better future!
Accurate Databricks-Certified-Data-Analyst-Associate Prep Material: https://www.practicetorrent.com/Databricks-Certified-Data-Analyst-Associate-practice-exam-torrent.html