NCP-AIO Exam Torrent - NVIDIA AI Operations Prep Torrent & NCP-AIO Test Guide

DOWNLOAD the newest Itcertmaster NCP-AIO PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=16joYvBujqJzJLCugxBbpBYorjMOuAF4v
NVIDIA AI Operations has introduced practice test (desktop and web-based) for the students so they can practice anytime in an easy way. The NVIDIA AI Operations (NCP-AIO) practice tests are customizable which means the students can set the time and questions according to their needs. The NCP-AIO Practice Tests have unlimited tries so that the users don't make extra mistakes when giving it the next time. Candidates can access the previously given tries from the history and avoid making mistakes in the final examination.
| Topic | Details |
|---|
| Topic 1 | - Troubleshooting and Optimization: NVIThis section of the exam measures the skills of AI infrastructure engineers and focuses on diagnosing and resolving technical issues that arise in advanced AI systems. Topics include troubleshooting Docker, the Fabric Manager service for NVIDIA NVlink and NVSwitch systems, Base Command Manager, and Magnum IO components. Candidates must also demonstrate the ability to identify and solve storage performance issues, ensuring optimized performance across AI workloads.
|
| Topic 2 | - Installation and Deployment: This section of the exam measures the skills of system administrators and addresses core practices for installing and deploying infrastructure. Candidates are tested on installing and configuring Base Command Manager, initializing Kubernetes on NVIDIA hosts, and deploying containers from NVIDIA NGC as well as cloud VMI containers. The section also covers understanding storage requirements in AI data centers and deploying DOCA services on DPU Arm processors, ensuring robust setup of AI-driven environments.
|
| Topic 3 | - Administration: This section of the exam measures the skills of system administrators and covers essential tasks in managing AI workloads within data centers. Candidates are expected to understand fleet command, Slurm cluster management, and overall data center architecture specific to AI environments. It also includes knowledge of Base Command Manager (BCM), cluster provisioning, Run.ai administration, and configuration of Multi-Instance GPU (MIG) for both AI and high-performance computing applications.
|
| Topic 4 | - Workload Management: This section of the exam measures the skills of AI infrastructure engineers and focuses on managing workloads effectively in AI environments. It evaluates the ability to administer Kubernetes clusters, maintain workload efficiency, and apply system management tools to troubleshoot operational issues. Emphasis is placed on ensuring that workloads run smoothly across different environments in alignment with NVIDIA technologies.
|
>> Reliable NCP-AIO Exam Prep <<
100% Pass Quiz 2026 Realistic NVIDIA Reliable NCP-AIO Exam Prep
Itcertmaster provide training tools included NVIDIA certification NCP-AIO exam study materials and simulation training questions and more importantly, we will provide you practice questions and answers which are very close with real certification exam. Selecting Itcertmaster can guarantee that you can in a short period of time to learn and to strengthen the professional knowledge of IT and pass NVIDIA Certification NCP-AIO Exam with high score.
NVIDIA AI Operations Sample Questions (Q35-Q40):
NEW QUESTION # 35
You are developing a DOCA application that needs to handle network packets at line rate. Which of the following DOCA services would be most suitable for achieving this goal and why?
- A. DOCA SPP: Provides support for scalable packet processing by managing packet buffers in user space but requires careful resource management.
- B. DOCA Flow: Allows defining complex flow rules and offloading packet processing to the DPU hardware, achieving high performance.
- C. DOCA DPI: Provides deep packet inspection capabilities for analyzing packet content but is not optimized for line-rate processing.
- D. DOCA RegEx: Offers regular expression matching for packet filtering but can introduce latency at high traffic rates.
- E. DOCA Telemetry: Designed for monitoring and collecting network statistics rather than packet processing.
Answer: A,B
Explanation:
DOCA Flow is designed for high-performance packet processing and allows offloading flow rules to the DPU hardware. DOCA SPP also plays a crucial role in line-rate processing with efficient packet buffer management.
NEW QUESTION # 36
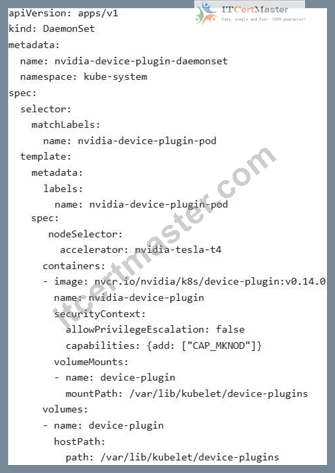
Consider this YAML snippet for deploying the NVIDIA device plugin. Which statement is true about the highlighted segment?
- A. It's a deprecated way of defining affinities. Consider using nodeAffinity instead.
- B. It will make sure that the node affinity is ignored during scheduling.
- C. It will make sure that the device plugin gets deployed on nodes with 'accelerator: nvidia-tesla-t4' label
- D. This will ensure that the pod is only deployed on the node with certain taints, but with no other scheduling requirements
- E. It will make sure that only tolerations are set, but there's no affinity.
Answer: C
Explanation:
The 'nodeselector' is used to target the deployment to nodes with label 'accelerator: nvidia-tesla-t4'. "nodeAffinity' is a more advanced way of doing this and is recommended, but in the absence of explicit nodeAffinity, nodeSelector is sufficient.
NEW QUESTION # 37
A data scientist reports that a Run.ai job is consistently crashing with a 'SIGKILL' signal. After verifying that the job is not exceeding its resource limits (CPU, memory, GPU), what is the MOST likely reason for this signal, and how can you diagnose it further within the Run.ai environment?
- A. The Run.ai agent is terminating the job due to exceeding a pre-defined time limit. Check the job's configuration for any time limits or deadlines.
- B. The job is being preempted due to higher priority tasks, resulting in SIGKILL. Check the job's priority, quota, and resource usage history with ACM.
- C. The job is experiencing a kernel panic on the node. Check the system logs on the node for kernel-related errors.
- D. The process is consuming a lot of disk I/O.
- E. The Kubernetes liveness probe is failing, causing the pod to be restarted. Inspect the pod's events and liveness probe configuration.
Answer: E
Explanation:
A 'SIGKILL' signal often indicates that the process was forcibly terminated by the operating system or a container runtime. A failing Kubernetes liveness probe is a common cause. If the probe fails, Kubernetes will restart the pod, sending a SIGKILL to the existing process. You can diagnose this by inspecting the pod's events using 'kubectl describe pod or 'runai describe job and examining the liveness probe configuration in the pod's YAML definition. Kernel panics, Run.ai agent time limits, and preemption are less likely to result directly in a SIGKILL signal.
NEW QUESTION # 38
A research team wants to use a specific version of TensorFlow (e.g., TensorFlow 2.9.0) for their experiments within the Run.ai environment. What is the RECOMMENDED approach for ensuring this specific TensorFlow version is available to their jobs?
- A. Install TensorFlow 2.9.0 directly on each node in the cluster.
- B. Use Run.ai's built-in environment module system to load TensorFlow 2.9.0.
- C. Mount a shared network drive containing TensorFlow 2.9.0 libraries into each container.
- D. Specify the TensorFlow version in the Run.ai job definition using a 'tf-version' parameter.
- E. Create a custom Docker image with TensorFlow 2.9.0 pre-installed and use that image for the Run.ai jobs.
Answer: E
Explanation:
Creating a custom Docker image with the desired TensorFlow version (2.9.0 in this case) is the recommended approach. This ensures that the job has a consistent and reproducible environment, regardless of the underlying infrastructure. Installing directly on nodes creates management overhead and potential conflicts. Run.ai does not have a built-in tf-version parameter or environment module system for this purpose. Mounting a network drive is less reliable and can introduce performance issues.
NEW QUESTION # 39
You are observing high GPU memory fragmentation, leading to 'CUDA out of memory' errors even when the total GPU memory utilization is relatively low. Which of the following strategies can help mitigate GPU memory fragmentation?
- A. Upgrade the GPU to one with more memory.
- B. Use a GPU memory allocator library that supports memory defragmentation.
- C. Reduce the number of concurrent CUDA contexts running on the GPU.
- D. Increase the swap space on the server.
- E. Allocate large, contiguous memory blocks upfront and reuse them whenever possible.
Answer: B,C,E
Explanation:
Allocating large blocks upfront (A) minimizes the creation of small, scattered memory allocations. Memory allocators with defragmentation capabilities (B) can reorganize memory to create larger contiguous blocks. Reducing concurrent CUDA contexts (C) decreases the number of independent memory allocation patterns that can lead to fragmentation. Increasing swap space (D) is a general memory management technique, but it doesn't directly address GPU memory fragmentation. Upgrading the GPU (E) provides more memory, but it doesn't solve the underlying fragmentation issue.
NEW QUESTION # 40
......
Itcertmaster releases 100% pass-rate NVIDIA NCP-AIO study guide files which guarantee candidates 100% pass exam in the first attempt. It is time for you to choose a valid NVIDIA NCP-AIO study guide, this will be your best method for clearing exam and obtain a certification. Good NCP-AIO Study Guide will be a shortcut for you to well-directed prepare and practice efficiently, you will avoid do much useless efforts and do something interesting.
Reliable NCP-AIO Test Braindumps: https://www.itcertmaster.com/NCP-AIO.html
- Quiz NVIDIA NCP-AIO - NVIDIA AI Operations Marvelous Reliable Exam Prep 🧈 The page for free download of ▷ NCP-AIO ◁ on ☀ www.pass4test.com ️☀️ will open immediately 🏞NCP-AIO Test Answers
- NCP-AIO Regualer Update 🙍 Reliable NCP-AIO Dumps Pdf 🗓 NCP-AIO Reliable Exam Testking 🌲 Search for ➠ NCP-AIO 🠰 and download it for free on 《 www.pdfvce.com 》 website 🌇Reliable NCP-AIO Dumps Pdf
- NCP-AIO Top Questions 🌳 Valid Test NCP-AIO Bootcamp 👙 NCP-AIO Vce Download ➡️ ➡ www.validtorrent.com ️⬅️ is best website to obtain “ NCP-AIO ” for free download 😂NCP-AIO Vce Download
- NCP-AIO New Practice Questions 🍅 NCP-AIO Reliable Exam Testking 🎈 Valid Test NCP-AIO Bootcamp 👓 《 www.pdfvce.com 》 is best website to obtain ⇛ NCP-AIO ⇚ for free download 〰NCP-AIO Vce Download
- 100% Pass Quiz NVIDIA - High Pass-Rate NCP-AIO - Reliable NVIDIA AI Operations Exam Prep 👳 Simply search for 【 NCP-AIO 】 for free download on 《 www.practicevce.com 》 😤Exam NCP-AIO Review
- Authorized NCP-AIO Test Dumps 🎸 Exam NCP-AIO Review 📕 NCP-AIO Regualer Update 🧾 Easily obtain free download of [ NCP-AIO ] by searching on ▛ www.pdfvce.com ▟ 🦨NCP-AIO Test Answers
- NCP-AIO Top Questions 🎂 Valid Test NCP-AIO Bootcamp 🚖 NCP-AIO Regualer Update 🔻 Open website ➤ www.torrentvce.com ⮘ and search for ⇛ NCP-AIO ⇚ for free download 😙NCP-AIO Valid Test Fee
- Trusted Reliable NCP-AIO Exam Prep | Easy To Study and Pass Exam at first attempt - Useful NVIDIA NVIDIA AI Operations 🐽 Search on 「 www.pdfvce.com 」 for 「 NCP-AIO 」 to obtain exam materials for free download 🧣Interactive NCP-AIO EBook
- Interactive NCP-AIO EBook 😐 Valid Test NCP-AIO Bootcamp 🕑 Interactive NCP-AIO EBook 🔎 Search for ✔ NCP-AIO ️✔️ and download it for free immediately on ➡ www.pass4test.com ️⬅️ 🎬Reliable NCP-AIO Dumps Ebook
- 2026 Valid Reliable NCP-AIO Exam Prep | NCP-AIO 100% Free Reliable Test Braindumps 😌 Search on ➡ www.pdfvce.com ️⬅️ for ▶ NCP-AIO ◀ to obtain exam materials for free download 🕎Reliable NCP-AIO Dumps Pdf
- Other NVIDIA NCP-AIO Exam Key Questions 🎀 Download ✔ NCP-AIO ️✔️ for free by simply entering { www.pdfdumps.com } website 🔟NCP-AIO Regualer Update
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, Disposable vapes
P.S. Free & New NCP-AIO dumps are available on Google Drive shared by Itcertmaster: https://drive.google.com/open?id=16joYvBujqJzJLCugxBbpBYorjMOuAF4v