This free Databricks Certified Professional Data Engineer Exam (Databricks-Certified-Professional-Data-Engineer) exam questions demo download facility is available in all three Databricks-Certified-Professional-Data-Engineer exam dumps formats. Just choose the best Prep4sureExam Databricks Certified Professional Data Engineer Exam (Databricks-Certified-Professional-Data-Engineer) exam demo questions format and download it quickly. If you think that Databricks-Certified-Professional-Data-Engineer exam dumps can work for you then take your buying decision.
Databricks is a leading cloud-based data platform that enables organizations to accelerate innovation and achieve their data-driven goals. To showcase their expertise in using the Databricks platform, data professionals can earn the Databricks-Certified-Professional-Data-Engineer (Databricks Certified Professional Data Engineer) certification. Databricks Certified Professional Data Engineer Exam certification is designed to validate the skills and knowledge required to design, build, and maintain data solutions on the Databricks platform.
>> Guaranteed Databricks-Certified-Professional-Data-Engineer Passing <<
Are you planning to pass the Databricks-Certified-Professional-Data-Engineer exam and don’t know where to start preparation? Many candidates don’t find a credible and lose money and time. If you want to save your resources, you are at right place because Databricks Databricks-Certified-Professional-Data-Engineer offers real exam questions for the students so that they can prepare and pass Databricks Databricks-Certified-Professional-Data-Engineer.
Databricks Certified Professional Data Engineer exam is a valuable certification for professionals who want to showcase their expertise in big data processing using Databricks. Databricks Certified Professional Data Engineer Exam certification demonstrates that the candidate has the necessary skills and knowledge to design and implement scalable data pipelines using Databricks. Databricks Certified Professional Data Engineer Exam certification also provides a competitive advantage to professionals in the job market and opens up new career opportunities in the field of big data engineering.
NEW QUESTION # 201
A table named user_ltv is being used to create a view that will be used by data analysts on various teams.
Users in the workspace are configured into groups, which are used for setting up data access using ACLs.
The user_ltv table has the following schema:
email STRING, age INT, ltv INT
The following view definition is executed: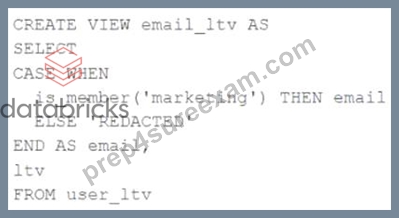
An analyst who is not a member of the marketing group executes the following query:
SELECT * FROM email_ltv
Which statement describes the results returned by this query?
Answer: B
Explanation:
The code creates a view called email_ltv that selects the email and ltv columns from a table called user_ltv, which has the following schema: email STRING, age INT, ltv INT. The code also uses the CASE WHEN expression to replace the email values with the string "REDACTED" if the user is not a member of the marketing group. The user who executes the query is not a member of the marketing group, so they will only see the email and ltv columns, and the email column will contain the string "REDACTED" in each row.
Verified References: [Databricks Certified Data Engineer Professional], under "Lakehouse" section; Databricks Documentation, under "CASE expression" section.
NEW QUESTION # 202
A data engineer wants to create a cluster using the Databricks CLI for a big ETL pipeline. The cluster should havefive workers,one driverof type i3.xlarge, and should use the '14.3.x-scala2.12' runtime.
Which command should the data engineer use?
Answer: A
Explanation:
Comprehensive and Detailed In-Depth Explanation:
TheDatabricks CLIallows users to manage clusters using command-line commands. The correct command for creating a cluster follows a specific format.
Key Components in the Command:
* Command Type:databricks compute create is the correct syntax for creating a new compute resource (cluster).
* Runtime Version:'14.3.x-scala2.12' specifies the Databricks runtime to use.
* Workers:--num-workers 5 sets the number of worker nodes to 5.
* Node Type:--node-type-id i3.xlarge defines the hardware configuration.
* Cluster Name:--cluster-name DataEngineer_cluster assigns a recognizable name to the cluster.
Evaluation of Options:
* Option A (databricks clusters create ...)
* Incorrect:databricks clusters createis not a valid commandin the Databricks CLI v0.205.
* The correct CLI command for cluster creation is databricks compute create.
* Option B (databricks clusters add ...)
* Incorrect:databricks clusters addis not a valid CLI command.
* Option C (databricks compute add ...)
* Incorrect:databricks compute addis not a valid CLI command.
* Option D (databricks compute create ...)
* Correct:databricks compute create is the correct command for creating a cluster.
Conclusion:
The correct command to create a cluster with five workers, an i3.xlarge node type, and Databricks runtime
14.3.x-scala2.12 is:
databricks compute create 14.3.x-scala2.12 --num-workers 5 --node-type-id i3.xlarge --cluster-name Data Engineer_cluster Thus, the correct answer isD.
References:
* Databricks CLI Documentation
NEW QUESTION # 203
A data engineer is designing a system to process batch patient encounter data stored in an S3 bucket, creating a Delta table (patient_encounters) with columns encounter_id, patient_id, encounter_date, diagnosis_code, and treatment_cost. The table is queried frequently by patient_id and encounter_date, requiring fast performance. Fine-grained access controls must be enforced. The engineer wants to minimize maintenance and boost performance.
How should the data engineer create the patient_encounters table?
Answer: A
Explanation:
Databricks documentation specifies that Unity Catalog managed tables are the preferred choice for secure, low-maintenance Delta Lake architectures. Managed tables provide full lifecycle management, including metadata, file storage, and access control integration with Unity Catalog. Fine-grained permissions can be enforced at the column and row level through built-in Unity Catalog governance.
Additionally, Predictive Optimization (Auto Optimize + Auto Compaction) automatically manages file sizes, metadata pruning, and layout optimization, eliminating the need for manual maintenance such as scheduling OPTIMIZE or VACUUM.
External tables (A) require manual path management, and Hive Metastore tables (D) do not support Unity Catalog access policies. Therefore, creating a managed Unity Catalog table with predictive optimization provides both the security and performance benefits needed, making B the correct solution.
NEW QUESTION # 204
A Spark job is taking longer than expected. Using the Spark UI, a data engineer notes that the Min, Median, and Max Durations for tasks in a particular stage show the minimum and median time to complete a task as roughly the same, but the max duration for a task to be roughly 100 times as long as the minimum.
Which situation is causing increased duration of the overall job?
Answer: D
Explanation:
This is the correct answer because skew is a common situation that causes increased duration of the overall job. Skew occurs when some partitions have more data than others, resulting in uneven distribution of work among tasks and executors. Skew can be caused by various factors, such as skewed data distribution, improper partitioning strategy, or join operations with skewed keys. Skew can lead to performance issues such as long-running tasks, wasted resources, or even task failures due to memory or disk spills. Verified References:
[Databricks Certified Data Engineer Professional], under "Performance Tuning" section; Databricks Documentation, under "Skew" section.
NEW QUESTION # 205
Which statement regarding spark configuration on the Databricks platform is true?
Answer: D
Explanation:
When Spark configuration properties are set for an interactive cluster using the Clusters UI in Databricks, those configurations are applied at the cluster level. This means that all notebooks attached to that cluster will inherit and be affected by these configurations. This approach ensures consistency across all executions within that cluster, as the Spark configuration properties dictate aspects such as memory allocation, number of executors, and other vital execution parameters. This centralized configuration management helps maintain standardized execution environments across different notebooks, aiding in debugging and performance optimization.
Reference:
Databricks documentation on configuring clusters: https://docs.databricks.com/clusters/configure.html
NEW QUESTION # 206
......
Certificate Databricks-Certified-Professional-Data-Engineer Exam: https://www.prep4sureexam.com/Databricks-Certified-Professional-Data-Engineer-dumps-torrent.html