Microsoft AI-200 시험 기출문제를 애타게 찾고 계시나요? DumpTOP의 Microsoft AI-200덤프는Microsoft AI-200최신 시험의 기출문제뿐만아니라 정답도 표기되어 있고 저희 전문가들의 예상문제도 포함되어있어 한방에 응시자분들의 고민을 해결해드립니다. 구매후 시험문제가 변경되면 덤프도 시험문제변경에 따라 업데이트하여 무료로 제공해드립니다.
| Section | Objectives |
|---|---|
| Develop AI solutions by using Azure data management services | - Work with Azure data platforms for AI workloads
|
| Develop containerized solutions on Azure | - Implement containerized applications
|
| Secure, monitor, troubleshoot Azure solutions | - Operate AI cloud solutions
|
| Connect to and consume Azure services | - Integrate Azure services
|
DumpTOP 에서는 IT인증시험에 대비한 퍼펙트한Microsoft 인증AI-200덤프를 제공해드립니다. 시험공부할 시간이 충족하지 않은 분들은DumpTOP 에서 제공해드리는Microsoft 인증AI-200덤프로 시험준비를 하시면 자격증 취득이 쉬워집니다. 덤프를 구매하시면 일년무료 업데이트서비스도 받을수 있습니다.
질문 # 38
You have two Azure Container Registry (ACR) instances: ACR01 and ACR02.
You plan to implement a containerized application named APP1 that will use a base image named BASE1.
The image for APP1 will be stored in ACR01. The image BASE1 will be stored in ACR02.
You need to automate the planned implementation by using a sequence of five Azure command-line interface (Azure CLI) commands. Your solution must ensure that the APP1 image stored in ACR01 will be automatically updated when the BASE1 image is updated.
In which order should you arrange the commands to develop the solution? To answer, move all commands from the list of commands to the answer area and arrange them in the correct order.
NOTE: More than one order of answer choices is correct. You will receive credit for any of the correct orders you select.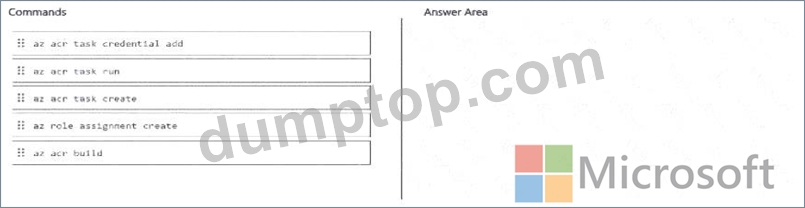
정답:
설명: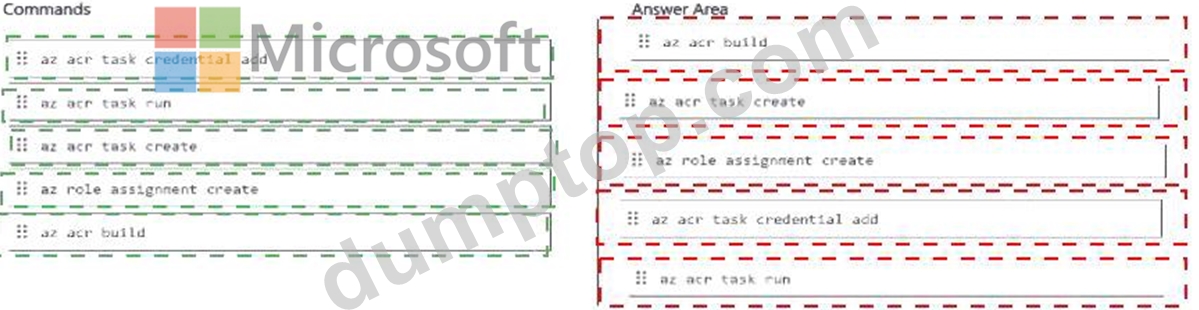
Explanation: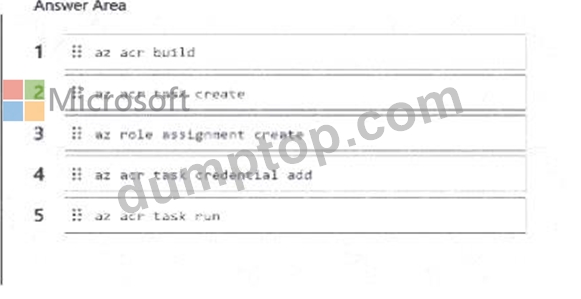
질문 # 39
Case Study 2 - Proseware Inc.
Background
Proseware Inc. develops AI-powered knowledge management solutions for enterprise customers.
The company is modernizing its platform to support semantic search, intelligent document retrieval, and real-time partner integrations.
The engineering team uses Python and Azure SDKs. The architecture is being redesigned to support containerized microservices, vector search workloads, and serverless backend processing.
Planned Application Architecture
Microservices are containerized by using Docker.
Code for containerized microservices and Azure Function apps is developed locally but stored in a GitHub repository.
Custom images for containerized microservices are stored in Azure Container Registry (ACR).
Base images are stored in Docker Hub. Custom images must be rebuilt automatically whenever their base images are updated.
Azure Cosmos DB for NoSQL stores documents, metadata, and vector embeddings.
Azure Functions generate vector embeddings of Azure Cosmos DB for NoSQL-hosted documents and send messages to Service Bus to trigger search index updates.
Azure Container Apps (ACA) apps host backend API services that provide semantic search across Azure Cosmos DB for NoSQL documents. API services process Service Bus messages and update search indexes.
Azure Kubernetes Service (AKS) processes batch vector embedding regeneration for existing Azure Cosmos DB for NoSQL documents (whenever the embedding model is changed).
An extranet-facing containerized webhook allows business partners to submit documents to be processed by internal AI workflows for semantic search and retrieval.
Monitoring
Telemetry generated by Azure resources is sent to Azure Monitor.
A Log Analytics workspace is used to collect ACA apps logs, AKS container logs, and Azure Functions apps logs.
Monitoring of Azure Functions is currently implemented by using Azure Application Insights SDK instrumentation.
Business Requirements
Embeddings for new or updated Azure Cosmos DB for NoSQL-hosted documents must be automatically generated.
Backend API services must scale automatically during business hours.
Cold start delay of backend APIs must be minimized.
Secrets must be stored outside of container images.
Developers must be able to correlate telemetry across Azure Functions hosts and apps.
All tracing must be implemented by using OpenTelemetry SDK instrumentation.
Development efforts must be minimized.
Technical Requirements
Container images must be built automatically and validated before code updates are merged into the main branch.
Image build automation must run inside the Azure Container Registry, eliminating dependency on local developer machines and external build services.
Dependency of image builds on local developer machines must be eliminated.
Event-driven scaling in ACA must occur based on the number of pending messages in the Azure Service Bus queue.
Azure Cosmos DB for NoSQL RU consumption must be minimized.
Vector similarity search must use embeddings stored in Azure Cosmos DB for NoSQL.
The partner-facing containerized webhook service must run on Azure App Service.
Secrets must NOT be stored in container images, source control, or application configuration directly. They must be accessed securely at runtime.
All secrets must be stored centrally in Azure Key Vault and accessed at runtime through a managed identity.
Azure App Service must supply secrets at runtime without relying on external services.
Resources and workloads must be deployed by using Bicep templates through an automated, version-controlled pipeline. Local and command-line deployments must be eliminated to ensure repeatable, auditable deployments.
Known Issues
RU consumption spikes during vector similarity queries.
You need to perform a one-time analysis of logs collected from AKS, ACA, and Azure Function apps according to the business requirements.
What should you use?
정답:A
설명:
Business Requirements
Developers must be able to correlate telemetry across Azure Functions hosts and apps.
A KQL query is the correct tool to use for a one-time, cross-resource analysis to correlate telemetry across AKS, Azure Container Apps (ACA), and Azure Functions.
Cross-Resource Querying: KQL (Kusto Query Language) allows you to use the union operator to combine tables from different workspaces or applications effortlessly.
Correlation Capabilities: You can join logs using standard cloud fields like operation_Id,
_ResourceId, or custom headers to track a single request across your entire architecture.
On-Demand Analysis: It requires no setup time, making it ideal for a one-time investigation directly inside the Azure Monitor Log Analytics interface.
Reference:
https://oneuptime.com/blog/post/2026-02-16-how-to-perform-cross-workspace-queries-in-azure-log-analytics/view
질문 # 40
You need to configure the database resources for the Azure Database for PostgreSQL instance.
How should you complete the configuration to meet the business and technical requirements? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.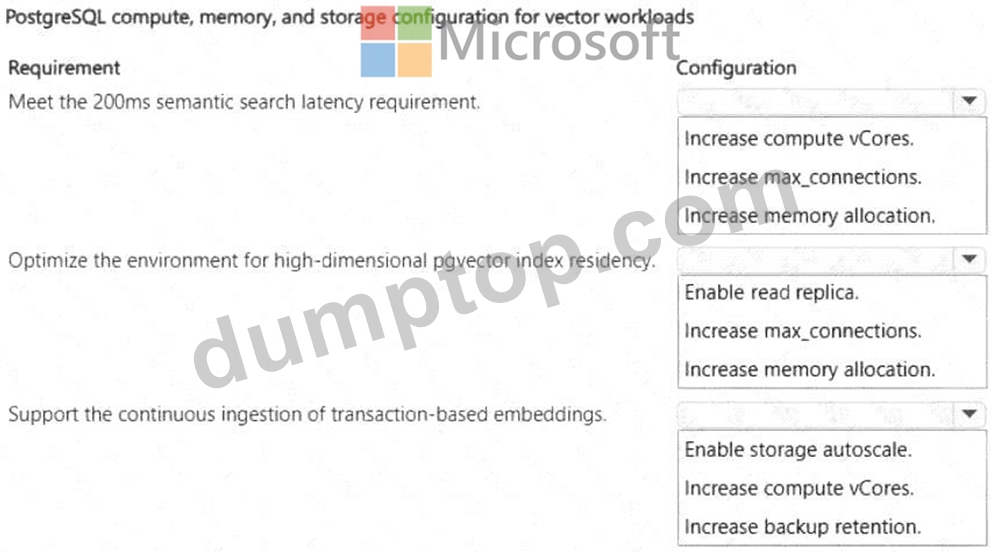
정답:
설명: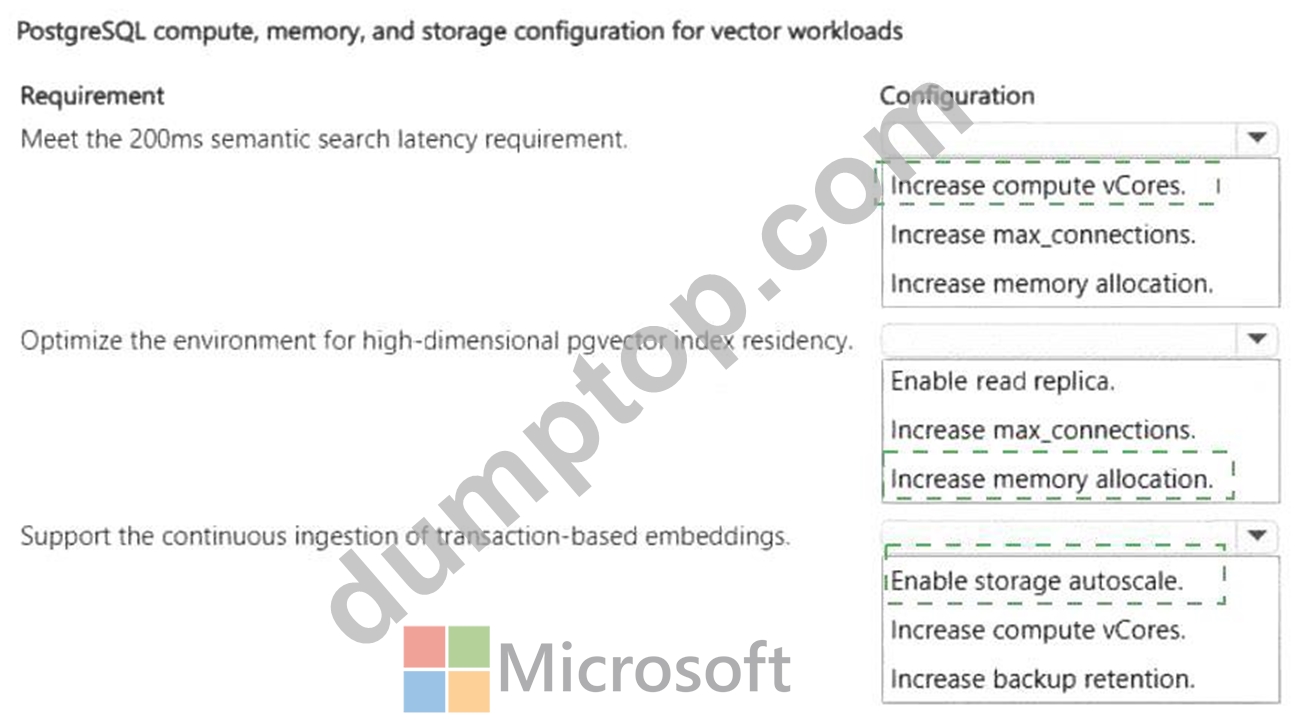
Explanation:
* Meet the 200-ms semantic search latency requirement: Increase compute vCores.
* Optimize the environment for high-dimensional pgvector index residency: Increase memory allocation.
* Support the continuous ingestion of transaction-based embeddings: Enable storage autoscale.
For the strict sub-200-ms vector-search latency target, increasing compute vCores is the appropriate choice.
Vector similarity operations are computationally intensive, and additional CPU capacity improves mathematical throughput and parallel query execution. Microsoft's pgvector guidance emphasizes query-plan optimization, ANN indexes such as HNSW, and sufficient compute resources when optimizing vector workloads.
For high-dimensional pgvector index residency , increase memory allocation . HNSW provides strong query-performance characteristics but consumes more memory than IVFFlat. Keeping frequently accessed vector index structures in memory minimizes disk access and materially improves latency. Microsoft explicitly notes that HNSW requires more memory while providing a better speed/recall tradeoff.
For the continuous ingestion of millions of embeddings, enable storage autoscale . Azure Database for PostgreSQL Flexible Server can automatically increase allocated storage as capacity approaches configured thresholds, avoiding an out-of-storage condition as data volumes grow. Microsoft recommends storage autogrow for workloads whose storage demand can increase dynamically.
Increasing max_connections does not directly improve vector computation or index residency, read replicas primarily scale reads, and backup retention does not address ingestion capacity.
Study Guide references: Azure Database for PostgreSQL Flexible Server # pgvector performance optimization; compute and memory sizing; HNSW indexing; storage autogrow.
질문 # 41
You deploy an API to Azure Container Apps.
The solution must provide the following functionality:
* Support the concurrent activation of multiple application versions.
* Allocate a specific percentage of incoming requests to a secondary version You need to configure revision behavior.
Which configurations should you use? To answer, move the appropriate configurations to the correct requirements. You may use each configuration once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.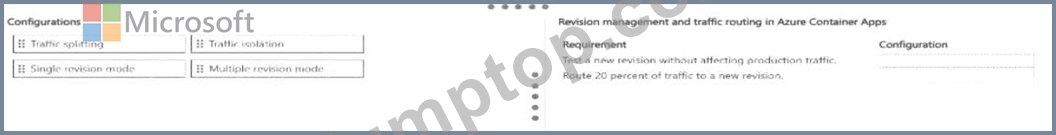
정답:
설명: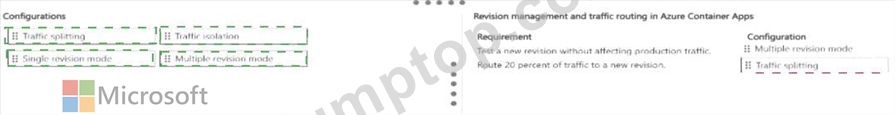
Explanation: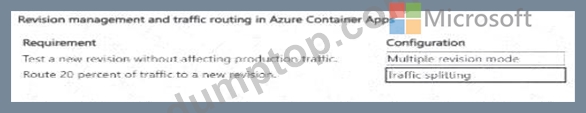
oncurrent active versions: Multiple revision mode. Route a percentage to the secondary version: Traffic splitting.
Detailed Explanation: Azure Container Apps supports side-by-side application versions through multiple revision mode. Once multiple revisions can be active, ingress traffic can be distributed by percentage across those revisions. This is the required combination for canary or controlled rollout scenarios. Single revision mode deactivates the previous revision as a new one becomes active, while traffic splitting is the specific feature that assigns a percentage of incoming requests to each active revision.
Study Guide Alignment: Containerized Azure workloads: registry builds, App Service containers, Container Apps revision/scaling behavior, and AKS deployment choices.
Official Microsoft Learn References: AI-200 Study Guide | Azure Container Apps revisions
질문 # 42
Drag and Drop Question
A semantic search application queries Azure Database for PostgreSQL and stores document embeddings and metadata in a table with the following columns:
- embedding (pgvector)
- department
- created_at
The application must return the top five most similar documents for a given query embedding only from the finance department.
You need to implement semantic retrieval with metadata filtering.
Which query components should you select? To answer, move the appropriate query components to the correct requirements. You may use each query component once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.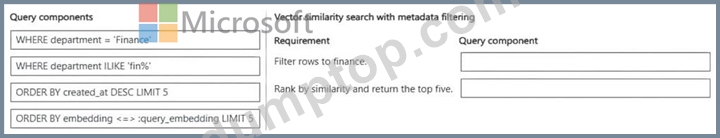
정답:
설명: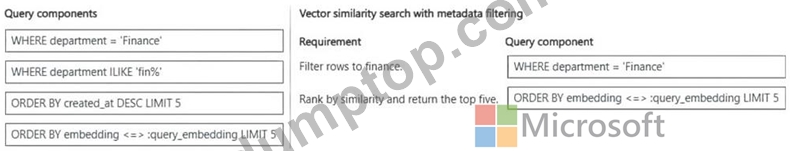
Explanation:
Box 1: WHERE department = 'Finance'
Box 2: ORDER BY embedding <=> :query_vector LIMIT 5
To rank and return the top five most similar documents by similarity in Microsoft Learn, use the ORDER BY embedding <=> [query_vector] expression combined with LIMIT 5, where <=> computes the cosine distance.
Reference:
https://learn.microsoft.com/en-us/azure/postgresql/extensions/how-to-use-pgvector
질문 # 43
......
IT국제공인자격증Microsoft AI-200시험대비덤프를 제공하는 전문적인 사이트로서 회원님의 개인정보를 철저하게 보호해드리고 페이팔을 통한 결제라 안전한 결제를 진행할수 있습니다. Microsoft AI-200 덤프외에 다른 인증시험덤프에 관심이 있으신 분은 온라인 서비스를 클릭하여 문의해주세요.
AI-200퍼펙트 최신 공부자료: https://www.dumptop.com/Microsoft/AI-200-dump.html