P.S. Free & New SPS-C01 dumps are available on Google Drive shared by FreePdfDump: https://drive.google.com/open?id=1l9q9AItwEj1aVyVgOMoiKqS23EiicLWK
The clients can download our products and use our SPS-C01 study materials immediately after they pay successfully with their credit cards. Our system will send our SPS-C01 learning prep in the form of mails to the client in 5-10 minutes after their successful payment. The mails provide the links and if only the clients click on the links they can log in our software immediately to learn our SPS-C01 Guide materials. If there are something they can't understand, they can contact with our service and we will solve them right away.
| Section | Weight | Objectives |
|---|---|---|
| Data Transformations and Operations | 35% | - Advanced operations
|
| Snowpark Concepts and Architecture | 25% | - Session management and connection
|
| Snowpark API and Development | 30% | - Multi-language support
|
| Performance and Best Practices | 10% | - Security and governance
|
>> Online SPS-C01 Bootcamps <<
With the development of science and technology, getting SPS-C01 certification as one of the most powerful means to show your ability has attracted more and more people to be engaged in the related exams. Thus there is no doubt that candidates for the exam are facing ever-increasing pressure of competition. Since SPS-C01 Certification has become a good way for all of the workers to prove how capable and efficient they are. But it is universally accepted that only the studious people can pass the complex SPS-C01 exam.
NEW QUESTION # 217
You're designing a Snowpark application to process large CSV files containing sensor data'. Each CSV file has millions of rows, and you need to calculate aggregate statistics (e.g., average, min, max) for specific sensor readings. The processing needs to be highly parallelized for performance. You have the following code snippet (incomplete):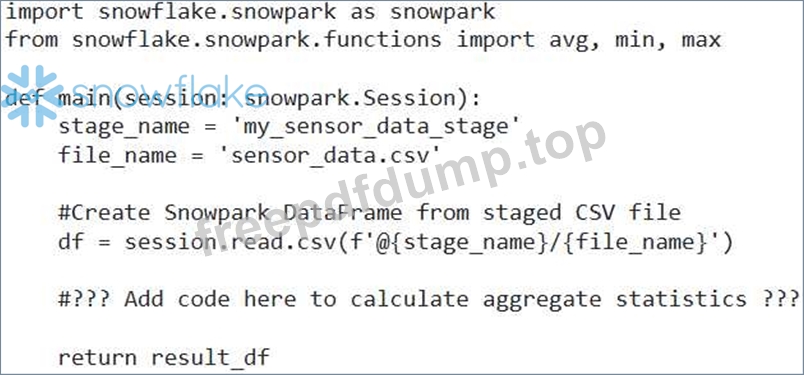
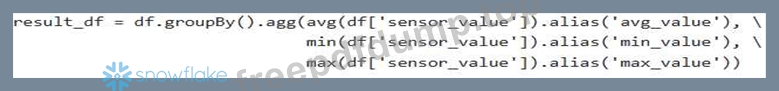
Which of the following code snippets, when inserted at the ' ??? Add code here to calculate aggregate statistics ??? ' marker, would correctly calculate the average, minimum, and maximum readings for a column named 'sensor value' and return the result in a new Snowpark DataFrame?

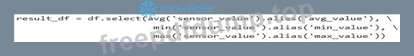
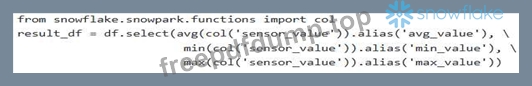
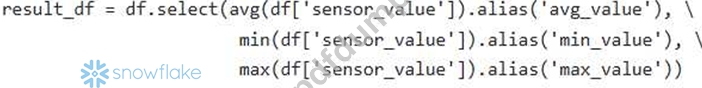
Answer: E
Explanation:
Option C is correct. When calculating aggregate statistics across the entire DataFrame (i.e., without any grouping), you need to use groupBy(Y with no arguments. This effectively creates a single group for the entire dataset, allowing the aggregation functions to operate correctly. Option A is syntactically valid but misses the crucial 'groupBy()' step, resulting in an error. Option B is incorrect because the 'agg function expects a dictionary where keys are column names and values are aggregation function strings , not Snowpark functions themselves. It also does not return alias values. Options D and E are syntactically valid because you can use and "sensor_value" instead of , but they fail to include so give incorrect aggregations.
NEW QUESTION # 218
You are working with a Snowpark DataFrame containing customer data'. One of the columns, 'phone number', contains phone numbers in various formats (e.g., '123-456-7890', '(123) 456-7890', '1234567890'). You need to standardize all phone numbers to the format '+1-123-456-7890' using Snowpark for Python. You also want to handle cases where the phone number is NULL gracefully, replacing them with '+1-000-000-0000'. Which of the following Snowpark code snippets is the most efficient and correct way to achieve this?

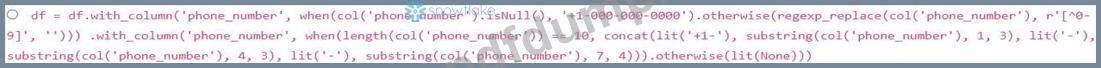



Answer: B
Explanation:
Option C is the most efficient because it uses built-in Snowpark functions (when, regexp_replace, substring, concat, length, and lit) to perform the transformation directly on the server-side. It first handles NULL values. It then removes non-numeric characters. Finally, it checks the length of the remaining digits before formatting, ensuring only valid 10-digit numbers are transformed, setting others to NULL. Options A, D, and E do not handle the case where after removing non-numeric characters, the length of phone number is not 10. Option B uses a UDF, which is generally less efficient than using built-in functions as it involves serialization/deserialization overhead .
NEW QUESTION # 219
You are developing a Snowpark Python application that reads data from an external stage (AWS S3) and performs several transformations before loading it into a Snowflake table. During testing, you encounter the following error: net.snowflake.client.jdbc.SnowflakeSQLException: SQL compilation error: User does not have OWNERSHIP privilege on integration object 'YOUR INTEGRATION NAME". You have confirmed that the user has the 'USAGE privilege on the integration. Besides granting ownership, which of the following actions could resolve this issue in the MOST secure and efficient way?
Answer: C
Explanation:
Option B is the MOST secure and efficient. The error indicates that the user lacks necessary privileges to utilize the integration for creating objects (in this case, likely an internal stage used during the transformation process). Granting a custom role with both 'USAGE on the integration and 'CREATE TABLE on the database adheres to the principle of least privilege. Option A grants broad privileges to the user, which is less secure. Option C involves complex integration setup and might not be necessary for a simple data loading scenario. Option D is related to reading data from the external stage, not using the integration for internal operations. Option E bypasses the error without addressing the underlying permission issue.
NEW QUESTION # 220
You've created a Snowpark Python stored procedure designed to perform sentiment analysis on customer reviews stored in a Snowflake table. This procedure utilizes a third-party Python library, 'transformers', for its sentiment analysis model. You need to operationalize this stored procedure for scheduled execution. Which of the following options represents the MOST efficient and reliable approach for deploying and managing the 'transformers' dependency within the Snowflake environment for your stored procedure, minimizing deployment complexity and potential runtime errors?
Answer: A
Explanation:
Using Snowflake Anaconda channels (option C) is the recommended and most efficient way to manage Python dependencies for Snowpark stored procedures. It provides version control, dependency management, and ensures consistency across executions. Option A is highly discouraged due to security risks and maintainability issues. Option B can work, but it lacks proper dependency management and versioning. Option D is not possible, as you cannot directly modify the Snowflake compute warehouse nodes. Option E is incorrect. Task definititions does not have any mechanism to include the library
NEW QUESTION # 221
You have a Snowpark DataFrame named with the following schema: 'product_id' (INTEGER), (STRING), 'category' (STRING), 'price' (FLOAT), and 'description' (STRING). You want to perform several data cleaning and transformation steps. Which of the following operations can be efficiently chained together using Snowpark DataFrames to clean null values in 'description', replace special characters in 'product_name' and standardize 'category' values? Select all that apply:
Answer: B,C,D
Explanation:
Options A, B, and D can be efficiently chained using Snowpark DataFrame operations. Option A Cna.fill()') is a built-in method for handling null values. Option B is a SQL function available in Snowpark for string manipulation. Option D ('coalesce()') effectively fills null values from another column if present. Option C, using a UDF for string standardization, is viable but potentially less efficient than using built-in functions if possible. Option E is extremely inefficient as it forces data transfer to the client and row-by-row processing instead of leveraging Snowflake's parallel processing capabilities. Chaining operations allows Snowpark to optimize the execution plan and potentially perform these transformations in a single pass over the data. UDF execution might introduce overhead.
NEW QUESTION # 222
......
Our SPS-C01 prep torrent boosts the highest standards of technical accuracy and only use certificated subject matter and experts. We provide the latest and accurate SPS-C01 exam torrent to the client and the questions and the answers we provide are based on the real exam. We can promise to you the passing rate is high and about 98%-100%. Our SPS-C01 Test Braindumps also boosts high hit rate and can stimulate the exam to let you have a good preparation for the SPS-C01 exam. Your success is bound with our SPS-C01 exam questions.
Latest SPS-C01 Braindumps Free: https://www.freepdfdump.top/SPS-C01-valid-torrent.html
What's more, part of that FreePdfDump SPS-C01 dumps now are free: https://drive.google.com/open?id=1l9q9AItwEj1aVyVgOMoiKqS23EiicLWK