2026年JPTestKingの最新Workday-Pro-Integrations PDFダンプおよびWorkday-Pro-Integrations試験エンジンの無料共有:https://drive.google.com/open?id=1DQ7zWYUYLkYX6lwjLM1mJ_-5mgcwLPf4
JPTestKingのWorkdayのWorkday-Pro-Integrations試験トレーニング資料は君の成功に導く鍵で、君のIT業種での発展にも助けられます。長年の努力を通じて、JPTestKingのWorkdayのWorkday-Pro-Integrations認定試験の合格率が100パーセントになっていました。もしうちの学習教材を購入した後、認定試験に不合格になる場合は、全額返金することを保証いたします。
| Certification Vendor: | Workday |
|---|---|
| Exam Name: | Workday Pro Integrations Certification Exam |
| Exam Number: | Workday-Pro-Integrations |
| Available Languages: | English |
| Exam Format: | Multiple Choice |
| Related Certifications: | Workday Pro Certifications Workday Integrations |
| Sample Questions: | Workday Workday-Pro-Integrations Sample Questions |
| Official Syllabus URL: | https://www.workday.com/en-us/services/certifications.html |
>> Workday-Pro-Integrations資格取得講座 <<
かつてないほどの才能の才能が大量に出てきたので、現代の才能はどのような能力を所有し、最終的に成功へと歩むべきでしょうか?まあ、もちろん、それはあなたに社会での地位の資本を与えるWorkday-Pro-Integrations試験資格認定です。 Workday-Pro-Integrations準備資料では、公式の試験銀行に最新の学習モデルと包括的な知識構造が表示されます。これは、技術スキルの向上と将来への価値の創造を目的としています。 Workday-Pro-Integrations試験の高度な質問とともにWorkday-Pro-Integrations試験に合格する必要があります。
| トピック | 出題範囲 |
|---|---|
| トピック 1 |
|
| トピック 2 |
|
| トピック 3 |
|
質問 # 56
Refer to the following XML to answer the question below.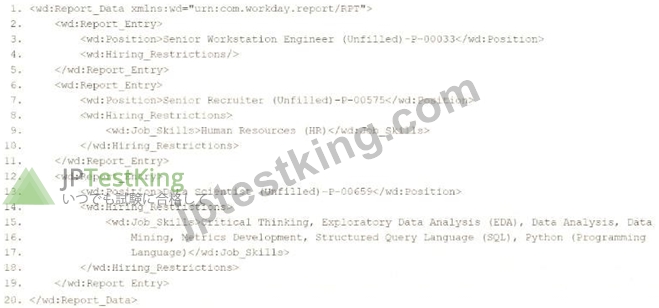
You are an integration developer and need to write X8LT to transform the output of an ElB which is using a web service enabled report to output position data along with hiring restrictions around skills. You currently have a template which matches on wd:Report Data/wd: Report .Entry for creating a record from each report entry.
Within the template which matches on wd:Report_Entry you would like to conditionally process the wd:
Job_Skills element by using a series of <xsl:if> elements so as to categorize the job skills data.
Assuming all jobs will have the wd:Job_Skills element, what XSLT syntax would be used to output the text HR Skills if the value of wd:Job_Skills contains the text HR and output NON-HR Skills if the value of wd:
Job_Skills does not contain the text HR?
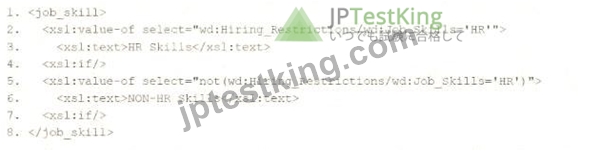
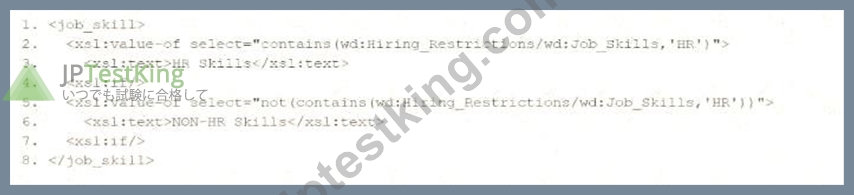
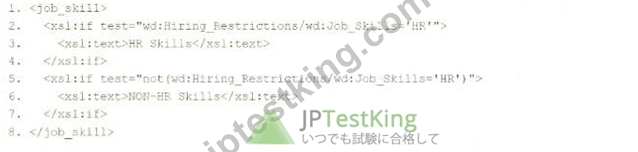
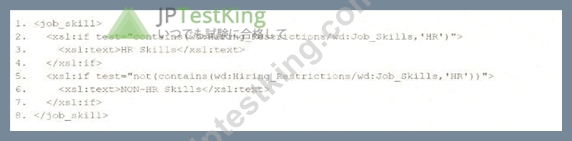
正解:D
解説:
The task is to write XSLT within a template matching wd:Report_Data/wd:Report_Entry to categorize wd:
Job_Skills data, outputting "HR Skills" if the value contains "HR" and "NON-HR Skills" if it does not, using a series of <xsl:if> elements. The correct syntax must use the contains() function to check for the substring
"HR" within wd:Job_Skills, as the question implies partial matching (e.g., "HR Specialist" or "Senior HR"), not exact equality.
Let's analyze each option:
* Option A:
xml
<job_skill>
<xsl:value-of select="wd:Hiring_Restrictions/wd:Job_Skills='HR'">
<xsl:text>HR Skills</xsl:text>
<xsl:if/>
<xsl:value-of select="not(wd:Hiring_Restrictions/wd:Job_Skills='HR')">
<xsl:text>NON-HR Skills</xsl:text>
<xsl:if/>
</job_skill>
* Issues:
* <xsl:value-of> is misused here. It outputs the result of the expression (e.g., "true" or "false" for a comparison), not the conditional text. The <xsl:text> inside won't execute as intended.
* The = operator checks for exact equality (e.g., wd:Job_Skills must be exactly "HR"), not substring presence, which contradicts the requirement to check if "HR" is contained within the value.
* <xsl:if/> is malformed (self-closing without a test attribute) and misplaced.
* Verdict: Incorrect syntax and logic.
* Option B:
xml
<job_skill>
<xsl:value-of select="contains(wd:Hiring_Restrictions/wd:Job_Skills, 'HR')">
<xsl:text>HR Skills</xsl:text>
<xsl:if/>
<xsl:value-of select="not(contains(wd:Hiring_Restrictions/wd:Job_Skills, 'HR'))">
<xsl:text>NON-HR Skills</xsl:text>
<xsl:if/>
</job_skill>
* Issues:
* Similar to A, <xsl:value-of> outputs the boolean result of contains() ("true" or "false"), not the conditional text "HR Skills" or "NON-HR Skills."
* The <xsl:text> elements are inside invalid <xsl:if/> tags (self-closing, no test), rendering them ineffective.
* While contains() is correct for substring checking, the structure fails to meet the <xsl:if> requirement.
* Verdict: Incorrect structure despite using contains().
* Option C:
xml
<job_skill>
<xsl:if test="wd:Hiring_Restrictions/wd:Job_Skills='HR'">
<xsl:text>HR Skills</xsl:text>
</xsl:if>
<xsl:if test="not(wd:Hiring_Restrictions/wd:Job_Skills='HR')">
<xsl:text>NON-HR Skills</xsl:text>
</xsl:if>
</job_skill>
* Analysis:
* Uses <xsl:if> correctly with test attributes, satisfying the "series of <xsl:if> elements" requirement.
* However, wd:Job_Skills='HR' tests for exact equality, not whether "HR" is contained within the value. For example, "HR Specialist" would fail this test, outputting "NON-HR Skills" incorrectly.
* Verdict: Semantically incorrect due to exact matching instead of substring checking.
* Option D:
xml
<job_skill>
<xsl:if test="contains(wd:Hiring_Restrictions/wd:Job_Skills, 'HR')">
<xsl:text>HR Skills</xsl:text>
</xsl:if>
<xsl:if test="not(contains(wd:Hiring_Restrictions/wd:Job_Skills, 'HR'))">
<xsl:text>NON-HR Skills</xsl:text>
</xsl:if>
</job_skill>
* Analysis:
* Correctly uses <xsl:if> with test attributes, aligning with the question's requirement.
* The contains() function properly checks if "HR" is a substring within wd:Job_Skills (e.g.,
"HR Manager" or "Senior HR" returns true).
* not(contains()) ensures the opposite condition, covering all cases (mutually exclusive).
* <xsl:text> outputs the exact strings "HR Skills" or "NON-HR Skills" as required.
* Note: The closing tag </xs1:if> is a typo in the option (should be </xsl:if>), but in context, it's an obvious formatting error, not a substantive issue.
* Verdict: Correct logic and syntax, making D the best answer.
Correct Implementation in Context:
xml
<xsl:template match="wd:Report_Data/wd:Report_Entry">
<job_skill>
<xsl:if test="contains(wd:Hiring_Restrictions/wd:Job_Skills, 'HR')">
<xsl:text>HR Skills</xsl:text>
</xsl:if>
<xsl:if test="not(contains(wd:Hiring_Restrictions/wd:Job_Skills, 'HR'))">
<xsl:text>NON-HR Skills</xsl:text>
</xsl:if>
</job_skill>
</xsl:template>
* Example Input: <wd:Job_Skills>Senior HR Analyst</wd:Job_Skills> # Output: <job_skill>HR Skills<
/job_skill>
* Example Input: <wd:Job_Skills>IT Specialist</wd:Job_Skills> # Output: <job_skill>NON-HR Skills<
/job_skill>
Workday Pro Integrations Study Guide: "Configure Integration System - TRANSFORMATION" section, detailing <xsl:if> and contains() for conditional XSLT logic in Workday.
Workday Documentation: "XSLT Transformations in Workday" under EIB, confirming wd: namespace usage and string functions.
W3C XSLT 1.0 Specification: Section 9.1, "Conditional Processing with <xsl:if>," and Section 11.2, "String Functions" (contains()).
Workday Community: Examples of substring-based conditionals in XSLT for report transformations.
質問 # 57
Refer to the following scenario to answer the question below.
An external system needs a file containing data for recent worker job changes. They would like to receive a file routinely at 5 PM eastern standard time, every 48 hours. The file should show job changes since the last integration run.
What is the run frequency of the integration schedule?
正解:D
解説:
The schedule requirement is every 48 hours, which is handled as a daily recurrence pattern with an interval of two days. Workday scheduling separates the general run frequency from the more specific recurrence interval.
The run frequency is therefore Daily Recurrence, while the recurrence detail would define the integration to recur every two days. Hourly Recurrence would be used when the integration runs at hourly intervals, not every two calendar days. Minute Recurrence is far too granular for this requirement. Custom Recurrence is unnecessary because the stated pattern can be handled by the standard daily recurrence configuration. Since the file must include changes since the last run, this schedule supports incremental processing while keeping the cadence predictable.
質問 # 58
Refer to the following XML to answer the question below.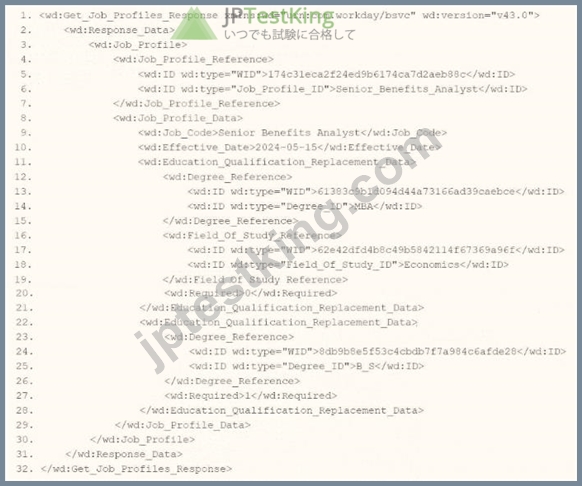
You are an integration developer and need to write XSLT to transform the output of an EIB which is making a request to the Get Job Profiles web service operation. The root template of your XSLT matches on the <wd:Get_Job_Profiles_Response> element. This root template then applies a template against <wd:Job_Profile>.
What XPath syntax would be used to select the value of the wd:Job_Code element when the <xsl:value-of> element is placed within the template which matches on <wd:Job_Profile>?
正解:B
解説:
As an integration developer working with Workday, you are tasked with transforming the output of an Enterprise Interface Builder (EIB) that calls the Get_Job_Profiles web service operation. The provided XML shows the response from this operation, and you need to write XSLT to select the value of the <wd:Job_Code> element. The root template of your XSLT matches on <wd:Get_Job_Profiles_Response> and applies a template to <wd:Job_Profile>. Within this template, you use the <xsl:value-of> element to extract the <wd:Job_Code> value. Let's analyze the XML structure, the requirement, and each option to determine the correct XPath syntax.
Understanding the XML and Requirement
The XML snippet provided is a SOAP response from the Get_Job_Profiles web service operation in Workday, using the namespace xmlns:wd="urn:com.workday/bsvc" and version wd:version="v43.0". Key elements relevant to the question include:
The root element is <wd:Get_Job_Profiles_Response>.
It contains <wd:Response_Data>, which includes <wd:Job_Profile> elements.
Within <wd:Job_Profile>, there are:
<wd:Job_Profile_Reference>, which contains <wd:ID> elements (e.g., a Job_Profile_ID).
<wd:Job_Profile_Data>, which contains <wd:Job_Code> with the value Senior_Benefits_Analyst.
The task is to select the value of <wd:Job_Code> (e.g., "Senior_Benefits_Analyst") using XPath within an XSLT template that matches <wd:Job_Profile>. The <xsl:value-of> element outputs the value of the selected node, so you need the correct XPath path from the <wd:Job_Profile> context to <wd:Job_Code>.
Analysis of Options
Let's evaluate each option based on the XML structure and XPath syntax rules:
Option A: wd:Job_Profile/wd:Job_Profile_Data/wd:Job_Code
This XPath starts from wd:Job_Profile and navigates to wd:Job_Profile_Data/wd:Job_Code. However, in the XML, <wd:Job_Profile> is the parent element, and <wd:Job_Profile_Data> is a direct child containing <wd:Job_Code>. The path wd:Job_Profile/wd:Job_Profile_Data/wd:Job_Code is technically correct in terms of structure, as it follows the hierarchy:
<wd:Job_Profile> → <wd:Job_Profile_Data> → <wd:Job_Code>.
However, since the template matches <wd:Job_Profile>, the context node is already <wd:Job_Profile>. You don't need to include wd:Job_Profile/ at the beginning of the XPath unless navigating from a higher level. Starting directly with wd:Job_Profile_Data/wd:Job_Code (Option C) is more concise and appropriate for the context. This option is technically valid but redundant and less efficient, making it less preferred compared to Option C.
Option B: wd:Job_Profile_Data[@wd:Job_Code]
This XPath uses an attribute selector ([@wd:Job_Code]) to filter <wd:Job_Profile_Data> based on an attribute named wd:Job_Code. However, examining the XML, <wd:Job_Profile_Data> does not have a wd:Job_Code attribute-it has a child element <wd:Job_Code> with the value "Senior_Benefits_Analyst." The [@attribute] syntax is used for attributes, not child elements, so this XPath is incorrect. It would not select the <wd:Job_Code> value and would likely return no results or an error. This option is invalid.
Option C: wd:Job_Profile_Data/wd:Job_Code
This XPath starts from wd:Job_Profile_Data (a direct child of <wd:Job_Profile>) and navigates to wd:Job_Code. Since the template matches <wd:Job_Profile>, the context node is <wd:Job_Profile>, and wd:Job_Profile_Data/wd:Job_Code correctly points to the <wd:Job_Code> element within <wd:Job_Profile_Data>. This path is:
Concise and appropriate for the context.
Directly selects the value "Senior_Benefits_Analyst" when used with <xsl:value-of>.
Matches the XML structure, as <wd:Job_Profile_Data> contains <wd:Job_Code> as a child.
This is the most straightforward and correct option for selecting the <wd:Job_Code> value within the <wd:Job_Profile> template.
Option D: wd:Job_Profile_Reference/wd:ID[@wd:type='Job_Profile_ID']
This XPath navigates to <wd:Job_Profile_Reference> (a child of <wd:Job_Profile>) and then to <wd:ID> with an attribute wd:type="Job_Profile_ID". In the XML, <wd:Job_Profile_Reference> contains:
<wd:ID wd:type="WID">1740d3eca2f2ed9b6174ca7d2ae88c8c</wd:ID>
<wd:ID wd:type="Job_Profile_ID">Senior_Benefits_Analyst</wd:ID>
The XPath wd:Job_Profile_Reference/wd:ID[@wd:type='Job_Profile_ID'] selects the <wd:ID> element with wd:type="Job_Profile_ID", which has the value "Senior_Benefits_Analyst." However, this is not the <wd:Job_Code> value-the <wd:Job_Code> is a separate element under <wd:Job_Profile_Data>, not <wd:Job_Profile_Reference>. The question specifically asks for the <wd:Job_Code> value, so this option is incorrect, as it selects a different piece of data (the job profile ID, not the job code).
Why Option C is Correct
Option C, wd:Job_Profile_Data/wd:Job_Code, is the correct XPath syntax because:
It starts from the context node <wd:Job_Profile> (as the template matches this element) and navigates to <wd:Job_Profile_Data/wd:Job_Code>, which directly selects the <wd:Job_Code> element's value ("Senior_Benefits_Analyst").
It is concise and aligns with standard XPath navigation in XSLT, avoiding unnecessary redundancy (unlike Option A) or incorrect attribute selectors (unlike Option B).
It matches the XML structure, where <wd:Job_Profile_Data> is a child of <wd:Job_Profile> and contains <wd:Job_Code> as a child.
When used with <xsl:value-of select="wd:Job_Profile_Data/wd:Job_Code"/> in the template, it outputs the job code value, fulfilling the requirement.
Practical Example in XSLT
Here's how this might look in your XSLT:
xml
WrapCopy
<xsl:template match="wd:Job_Profile">
<xsl:value-of select="wd:Job_Profile_Data/wd:Job_Code"/>
</xsl:template>
This would output "Senior_Benefits_Analyst" for the <wd:Job_Code> element in the XML.
Verification with Workday Documentation
The Workday Pro Integrations Study Guide and SOAP API Reference (available via Workday Community) detail the structure of the Get_Job_Profiles response and how to use XPath in XSLT for transformations. The XML structure shows <wd:Job_Profile_Data> as the container for job profile details, including <wd:Job_Code>. The guide emphasizes using relative XPath paths within templates to navigate from the matched element (e.g., <wd:Job_Profile>) to child elements like <wd:Job_Profile_Data/wd:Job_Code>.
Workday Pro Integrations Study Guide Reference
Section: XSLT Transformations in EIBs - Describes using XSLT to transform web service responses, including selecting elements with XPath.
Section: Workday Web Services - Details the Get_Job_Profiles operation and its XML output structure, including <wd:Job_Profile_Data> and <wd:Job_Code>.
Section: XPath Syntax - Explains how to navigate XML hierarchies in Workday XSLT, using relative paths like wd:Job_Profile_Data/wd:Job_Code from a <wd:Job_Profile> context.
Workday Community SOAP API Reference - Provides examples of XPath navigation for Workday web service responses.
Option C is the verified answer, as it correctly selects the <wd:Job_Code> value using the appropriate XPath syntax within the <wd:Job_Profile> template context.
質問 # 59
Refer to the following scenario to answer the question below.
You need to configure a Core Connector: Candidate Outbound integration for your vendor. The connector requires the data initialization service (DIS).
The vendor requests additional formatting of the candidate Country field. For example, if a candidate ' s country is the United States of America, the output should show USA.
What steps do you follow to meet this request?
正解:A
解説:
The scenario involves a Core Connector: Candidate Outbound integration with the Data Initialization Service (DIS), where the vendor requires the " Country " field to be formatted differently (e.g., " United States of America " to " USA " ). This is a data transformation requirement, and Core Connectors provide specific tools to handle such formatting. Let's evaluate the solution:
* Requirement:The vendor needs a shortened country code (e.g., " USA " instead of " United States of America " ) in the output file. This involves transforming the delivered " Country " field value from the Candidate business object into a vendor-specific format.
* Integration Maps:In Workday Core Connectors, integration maps are used to transform or map field values from Workday's format to a vendor's required format. For example, you can create a map that replaces " United States of America " with " USA, " " Canada " with " CAN, " etc. This is configured via the " Configure Integration Maps " related action on the integration system, allowing you to define a lookup table or rule-based transformation for the Country field.
* Option Analysis:
* A. Use an Evaluated Expression calculation and add it to the integration's report data source:
Incorrect. While an Evaluate Expression calculated field could transform the value (e.g., if-then logic), Core Connectors don't directly use report data sources for output formatting. Calculated fields are better suited for custom reports or EIBs, not Core Connector field mapping.
* B. Use the integration related action Configure Integration Population Eligibility: Incorrect. This action filters the population of candidates included (e.g., based on eligibility criteria), not the formatting of individual fields like Country.
* C. Use the integration services to only output shortened country codes: Incorrect. Integration services define the dataset or events triggering the integration, not field-level formatting or transformations.
* D. Use the integration related action Configure Integration Maps: Correct. Integration maps are the standard Core Connector tool for transforming field values (e.g., mapping " United States of America " to " USA " ) to meet vendor requirements.
* Implementation:
* Navigate to the Core Connector: Candidate Outbound integration system.
* Use the related action Configure Integration Maps.
* Create a new map for the " Country " field (e.g., Source Value: " United States of America, " Target Value: " USA " ).
* Apply the map to the Country field in the integration output.
* Test the output file to ensure the transformed value (e.g., " USA " ) appears correctly.
References from Workday Pro Integrations Study Guide:
* Core Connectors & Document Transformation: Section on " Configuring Integration Maps " details how to transform field values for vendor-specific formatting.
* Integration System Fundamentals: Explains how Core Connectors handle data transformation through maps rather than calculated fields or services for field-level changes.
質問 # 60
You need to create a report that includes data from multiple business objects. For a supervisory organization specified at run time, the report must output one row per worker, their active benefit plans, and the names and ages of all related dependents. The Worker business object contains the Employee, Benefit Plans, and Dependents fields. The Dependent business object contains the employee's dependent's Name and Age fields.
How would you select the primary business object (PBO) and related business objects (RBO) for the report?
正解:B
解説:
In Workday reporting, selecting the appropriatePrimary Business Object (PBO)andRelated Business Objects (RBOs)is critical to ensure that the report retrieves and organizes data correctly based on the requirements. The requirement here is to create a report that outputs one row per worker for a specified supervisory organization, including their active benefit plans and the names and ages of all related dependents. The Worker business object contains fields like Employee, Benefit Plans, and Dependents, while the Dependent business object provides the Name and Age fields for dependents.
* Why Worker as the PBO?The report needs to output "one row per worker," making the Worker business object the natural choice for the PBO. In Workday, the PBO defines the primary dataset and determines the granularity of the report (i.e., one row per instance of the PBO). Since the report revolves around workers and their associated data (benefit plans and dependents), Worker is the starting point. Additionally, the requirement specifies a supervisory organization at runtime, which is a filter applied to the Worker business object to limit the population.
* Why Dependent as an RBO?The Worker business object includes a "Dependents" field, which is a multi-instance field linking to the Dependent business object. To access detailed dependent data (Name and Age), the Dependent business object must be added as an RBO. This allows the report to pull in the related dependent information for each worker. Without the Dependent RBO, the report could only reference the existence of dependents, not their specific attributes like Name and Age.
* Analysis of Benefit Plans:The Worker business object already contains the "Benefit Plans" field, which provides access to active benefit plan data. Since this is a field directly available on the PBO (Worker), no additional RBO is needed to retrieve benefit plan information.
* Option Analysis:
* A. PBO: Dependent, RBO: Worker: Incorrect. If Dependent were the PBO, the report would output one row per dependent, not one row per worker, which contradicts the requirement.
Additionally, Worker as an RBO would unnecessarily complicate accessing worker-level data.
* B. PBO: Worker, RBO: Dependent: Correct. This aligns with the requirement: Worker as the PBO ensures one row per worker, and Dependent as the RBO provides access to dependent details (Name and Age). Benefit Plans are already accessible via the Worker PBO.
* C. PBO: Dependent, no RBOs: Incorrect.This would result in one row per dependent and would not allow easy access to worker or benefit plan data, failing to meet the "one row per worker" requirement.
* D. PBO: Worker, no RBOs: Incorrect. While Worker as the PBO is appropriate, omitting the Dependent RBO prevents the report from retrieving dependent Name and Age fields, which are stored in the Dependent business object, not directly on Worker.
* Implementation:
* Create a custom report withWorkeras the PBO.
* Add a filter for the supervisory organization (specified at runtime) on the Worker PBO.
* AddDependentas an RBO to access Name and Age fields.
* Include columns from Worker (e.g., Employee, Benefit Plans) and Dependent (e.g., Name, Age).
References from Workday Pro Integrations Study Guide:
* Workday Report Writer Fundamentals: Section on "Selecting Primary and Related Business Objects" explains how the PBO determines the report's row structure and RBOs extend data access to related objects.
* Integration System Fundamentals: Discusses how multi-instance fields (e.g., Dependents on Worker) require RBOs to retrieve detailed attributes.
質問 # 61
......
Workday-Pro-Integrations日本語pdf問題: https://www.jptestking.com/Workday-Pro-Integrations-exam.html
2026年JPTestKingの最新Workday-Pro-Integrations PDFダンプおよびWorkday-Pro-Integrations試験エンジンの無料共有:https://drive.google.com/open?id=1DQ7zWYUYLkYX6lwjLM1mJ_-5mgcwLPf4