By using our NCM-MCI-6.10 exam braindumps, it will be your habitual act to learn something with efficiency. With the cumulative effort over the past years, our NCM-MCI-6.10 study guide has made great progress with passing rate up to 98 to 100 percent among the market. A lot of professional experts concentrate to making our NCM-MCI-6.10 Preparation materials by compiling the content so they have gained reputation in the market for their proficiency and dedication.
| Section | Objectives |
|---|---|
| Topic 1: Analyze and Optimize Network Performance | - Advanced network configuration - Overlay networking optimization - Physical and virtual network evaluation - Flow policies analysis and optimization |
| Topic 2: Analyze and Optimize VM Performance | - Cluster and node metrics analysis - VM resource optimization |
| Topic 3: Advanced Configuration and Troubleshooting | - Security posture analysis - Troubleshooting Nutanix services - CLI and API execution - Risk mitigation configuration - Third-party integrations |
| Topic 4: Business Continuity | - BCDR compliance analysis - Workload resilience evaluation |
| Topic 5: Analyze and Optimize Storage Performance | - Storage internals and I/O analysis - Storage configuration optimization - Workload performance evaluation |
>> NCM-MCI-6.10 Valid Test Question <<
There is no another great way to pass the Nutanix NCM-MCI-6.10 exam in the first attempt only by doing a selective study with valid NCM-MCI-6.10 braindumps. If you already have a job and you are searching for the best way to improve your current NCM-MCI-6.10 test situation, then you should consider the NCM-MCI-6.10 Exam Dumps. By using our updated NCM-MCI-6.10 products, you will be able to get reliable and relative NCM-MCI-6.10 exam prep questions, so you can pass the exam easily. You can get one-year free NCM-MCI-6.10 exam updates from the date of purchase.
NEW QUESTION # 16
Task 15
Depending on the order you perform the exam items, the access information and credentials could change.
Please refer to the other item performed on Cluster B if you have problems accessing the cluster.
The infosec team has requested that audit logs for API Requests and replication capabilities be enabled for all clusters for the top 4 severity levels and pushed to their syslog system using highest reliability possible. They have requested no other logs to be included.
Syslog configuration:
Syslog Name: Corp_syslog
Syslop IP: 34.69.43.123
Port: 514
Ensure the cluster is configured to meet these requirements.
Answer:
Explanation:
See the Explanation for step by step solution.
Explanation:
To configure the cluster to meet the requirements of the infosec team, you need to do the following steps:
Log in to Prism Central and go to Network > Syslog Servers > Configure Syslog Server. Enter Corp_syslog as the Server Name, 34.69.43.123 as the IP Address, and 514 as the Port. Select TCP as the Transport Protocol and enable RELP (Reliable Logging Protocol). This will create a syslog server with the highest reliability possible.
Click Edit against Data Sources and select Cluster B as the cluster. Select API Requests and Replication as the data sources and set the log level to CRITICAL for both of them. This will enable audit logs for API requests and replication capabilities for the top 4 severity levels (EMERGENCY, ALERT, CRITICAL, and ERROR) and push them to the syslog server. Click Save.
Repeat step 2 for any other clusters that you want to configure with the same requirements.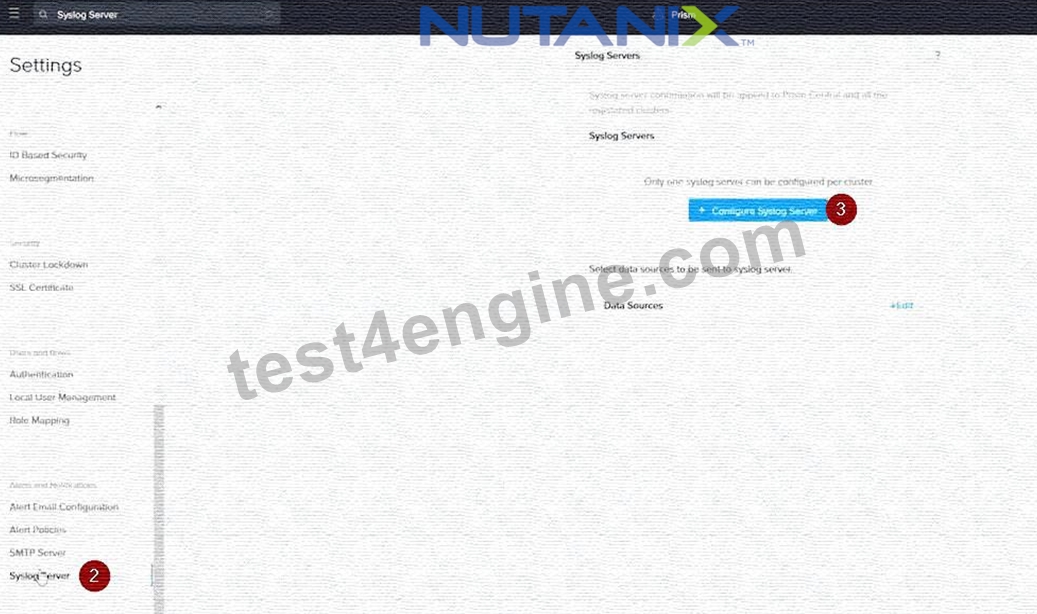
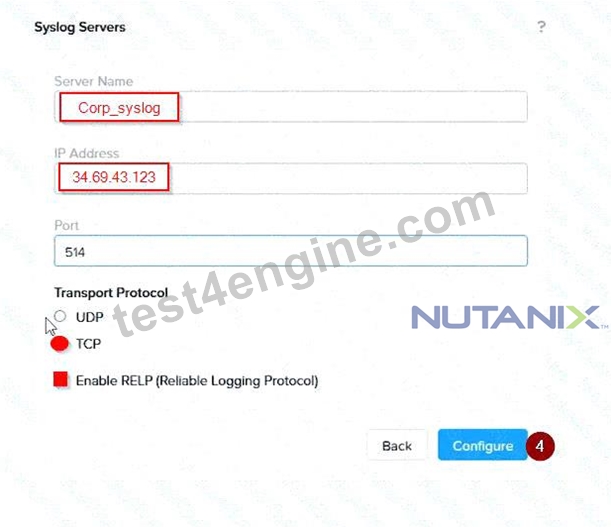
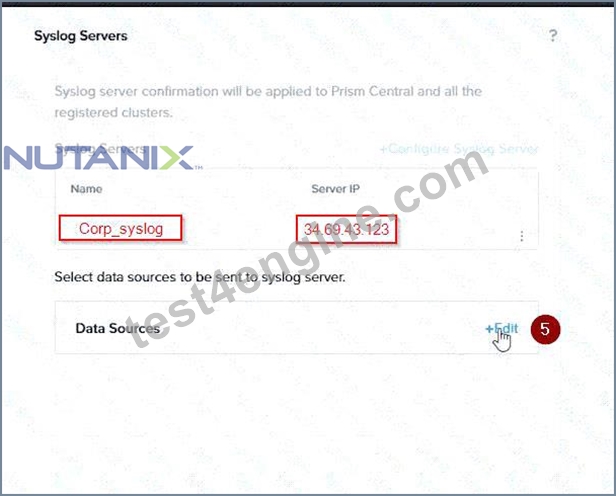
To configure the Nutanix clusters to enable audit logs for API Requests and replication capabilities, and push them to the syslog system with the highest reliability possible, you can follow these steps:
Log in to the Nutanix Prism web console using your administrator credentials.
Navigate to the "Settings" section or the configuration settings interface within Prism.
Locate the "Syslog Configuration" or "Logging" option and click on it.
Configure the syslog settings as follows:
Syslog Name: Enter "Corp_syslog" as the name for the syslog configuration.
Syslog IP: Set the IP address to "34.69.43.123", which is the IP address of the syslog system.
Port: Set the port to "514", which is the default port for syslog.
Enable the option for highest reliability or persistent logging, if available. This ensures that logs are sent reliably and not lost in case of network interruptions.
Save the syslog configuration.
Enable Audit Logs for API Requests:
In the Nutanix Prism web console, navigate to the "Cluster" section or the cluster management interface.
Select the desired cluster where you want to enable audit logs.
Locate the "Audit Configuration" or "Security Configuration" option and click on it.
Look for the settings related to audit logs and API requests. Enable the audit logging feature and select the top
4 severity levels to be logged.
Save the audit configuration.
Enable Audit Logs for Replication Capabilities:
In the Nutanix Prism web console, navigate to the "Cluster" section or the cluster management interface.
Select the desired cluster where you want to enable audit logs.
Locate the "Audit Configuration" or "Security Configuration" option and click on it.
Look for the settings related to audit logs and replication capabilities. Enable the audit logging feature and select the top 4 severity levels to be logged.
Save the audit configuration.
After completing these steps, the Nutanix clusters will be configured to enable audit logs for API Requests and replication capabilities. The logs will be sent to the specified syslog system with the highest reliability possible.
ncli
<ncli> rsyslog-config set-status enable=false
<ncli> rsyslog-config add-server name=Corp_Syslog ip-address=34.69.43.123 port=514 network- protocol=tdp relp-enabled=false
<ncli> rsyslog-config add-module server-name= Corp_Syslog module-name=APLOS level=INFO
<ncli> rsyslog-config add-module server-name= Corp_Syslog module-name=CEREBRO level=INFO
<ncli> rsyslog-config set-status enable=true
https://portal.nutanix.com/page/documents/kbs/details?targetId=kA00e0000009CEECA2
NEW QUESTION # 17
An administrator is experiencing an unidentified issue which is causing inode exhaustion on CVMs in Cluster
1. The time between receiving alerts and exhaustion is too short; the administrator needs to lower the alert thresholds to allow more time to clean up inodes until the issue has been identified and resolution implemented.
From Prism Element, modify the appropriate alert policy setting critical threshold for Cluster 1 to 60% and warning threshold to 45%. Ensure the check runs every minute and is not resolved without administrator action.
Answer:
Explanation:
See the Explanation below for detailed answer.
Explanation:
Here is the step-by-step solution to modify the alert policy from the Prism Element (PE) interface for Cluster 1.
1. Access Cluster 1 Prism Element
* From the main Prism Central dashboard, navigate to Hardware > Clusters.
* Find Cluster 1 in the list and click its name. This will open the specific Prism Element login page for that cluster.
* Log in to Cluster 1's Prism Element interface.
2. Modify the Alert Policy
* In the Cluster 1 PE interface, click the gear icon (Settings) in the top-right corner.
* From the left-hand menu, select Alert Policies.
* In the search bar, type inode to find the correct policy.
* Select the checkbox for the policy named cvm_inode_usage_high.
* Click the Update button.
* In the "Update Alert Policy" dialog, configure the following settings:
* Warning Threshold (%): Change the value to 45.
* Critical Threshold (%): Change the value to 60.
* Check Interval (Secs): Change the value to 60 (to run the check every minute).
* Auto Resolve: Uncheck this box (to ensure the alert is not resolved without administrator action).
* Click Save.
NEW QUESTION # 18
The Infosec team has requested that all operational tasks performed within Cluster 1 be properly logged to include the top 4 severity levels and pushed to their syslog system using highest reliability possible for analysis. This is to include any Virtual Machine changes only.
The Infosec team has also requested that monitor logs for the given RSyslog Server Module be included for now. No extra logs should be included.
No other clusters should connect to this syslog server.
Syslog configuration:
* Syslog Name: Corp_Syslog
* Syslog IP: 34.142.155.231
* Port: TCP/514
Ensure only Cluster 1 is configured to meet these requirements.
Answer:
Explanation:
See the Explanation below for detailed answer.
Explanation:
Here is the step-by-step solution to configure syslog for Cluster 1.
1. Access Cluster 1 Prism Element
Since the requirement is to only configure Cluster 1 and not other clusters, this task must be performed in the Prism Element (PE) interface for Cluster 1.
* From the main Prism Central dashboard, navigate to Hardware > Clusters.
* Find Cluster 1 in the list and click its name. This will open the specific Prism Element login page for that cluster.
* Log in to Cluster 1's Prism Element interface.
2. Add the Syslog Server
* In the Cluster 1 PE interface, click the gear icon (Settings) in the top-right corner.
* From the left-hand menu, select Syslog.
* In the "Remote Syslog Server" section, click the + Add Syslog Server button.
* Fill in the server details as required:
* Name: Corp_Syslog
* IP Address: 34.142.155.231
* Port: 514
* Protocol: TCP (This provides the highest reliability, as requested).
* Click Save.
3. Configure Log Modules and Severities
Now, we must specify which logs to send to the new server.
* On the same Syslog settings page, find the "Syslog Configuration" section and click the Configure button (or Modify if a default is present).
* A dialog box "Select Modules and Levels" will appear.
* Uncheck all modules to ensure no extra logs are sent.
* Check the box for the RSyslog Server Module (or rsyslog_forwarder).
* For this module, check the boxes for the severities: Critical, Warning, and Info.
* Check the box for the ApiServer module.
* This module logs all operational tasks and audit trails, which includes all Virtual Machine changes.
* For this module, check the boxes for the top severity levels: Critical, Warning, and Info.
* Ensure no other modules (like Stargate, Cerebro, Zookeeper, etc.) are checked.
* Click Save.
Cluster 1 is now configured to send its audit logs (including VM changes) and its own syslog monitoring logs to the Corp_Syslog server via TCP, fulfilling all security requirements.
Topic 2, Performance Based Questions Set 2
Environment
You have been provisioned a dedicated environment for your assessment which includes the following:
Workstation
* windows Server 2019
* All software/tools/etc to perform the required tasks
* Nutanix Documentation and whitepapers can be found in desktop\files\Documentation
* Note that the workstation is the system you are currently togged into Nutanix Cluster
* There are three clusters provided. The connection information for the relevant cluster will be displayed to the high of the question Please make sure you are working on the correct cluster for each item Please ignore any licensing violations
* Cluster A is a 3-node cluster with Prism Central 2022.6 where most questions will be performed
* Cluster B is a one-node cluster and has one syslog item and one security item to perform
* Cluster D is a one-node duster with Prism Central 5.17 and has a security policy item to perform Important Notes
* If the text is too small and hard to read, or you cannot see an of the GUI. you can increase/decrease the zoom of the browser with CTRL + ,and CTRL + (the plus and minus keys) You will be given 3 hours to complete the scenarios for Nutanix NCMMCI Once you click the start button below, you will be provided with:
- A Windows desktop A browser page with the scenarios and credentials (Desktop\instructions) Notes for this exam delivery:
The browser can be scaled lo Improve visibility and fit all the content on the screen.
- Copy and paste hot-keys will not work Use your mouse for copy and paste.
- The Notes and Feedback tabs for each scenario are to leave notes for yourself or feedback for
- Make sure you are performing tasks on the correct components.
- Changing security or network settings on the wrong component may result in a falling grade.
- Do not change credentials on an component unless you are instructed to.
- All necessary documentation is contained in the Desktop\Files\Documentation directory
NEW QUESTION # 19
Task 9
The application team has requested several mission-critical VMs to be configured for disaster recovery. The remote site (when added) will not be managed by Prism Central. As such, this solution should be built using the Web Console.
Disaster Recovery requirements per VM:
Mkt01
RPO: 2 hours
Retention: 5 snapshots
Fin01
RPO: 15 minutes
Retention: 7 days
Dev01
RPO: 1 day
Retention: 2 snapshots
Configure a DR solution that meets the stated requirements.
Any objects created in this item must start with the name of the VM being protected.
Note: the remote site will be added later
Answer:
Explanation:
See the Explanation for step by step solution.
Explanation:
To configure a DR solution that meets the stated requirements, you can follow these steps:
Log in to the Web Console of the source cluster where the VMs are running.
Click on Protection Domains on the left menu and click on Create Protection Domain.
Enter a name for the protection domain, such as PD_Mkt01, and a description if required. Click Next.
Select Mkt01 from the list of VMs and click Next.
Select Schedule Based from the drop-down menu and enter 2 hours as the interval. Click Next.
Select Remote Site from the drop-down menu and choose the remote site where you want to replicate the VM.
Click Next.
Enter 5 as the number of snapshots to retain on both local and remote sites. Click Next.
Review the protection domain details and click Finish.
Repeat the same steps for Fin01 and Dev01, using PD_Fin01 and PD_Dev01 as the protection domain names, and adjusting the interval and retention values according to the requirements.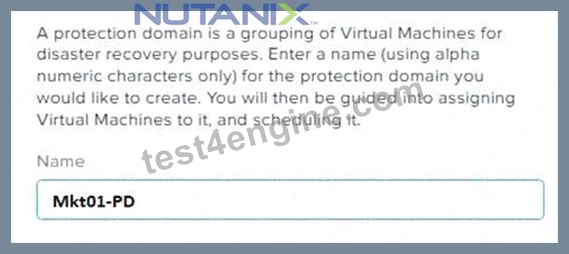
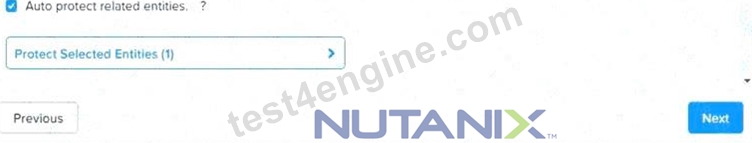
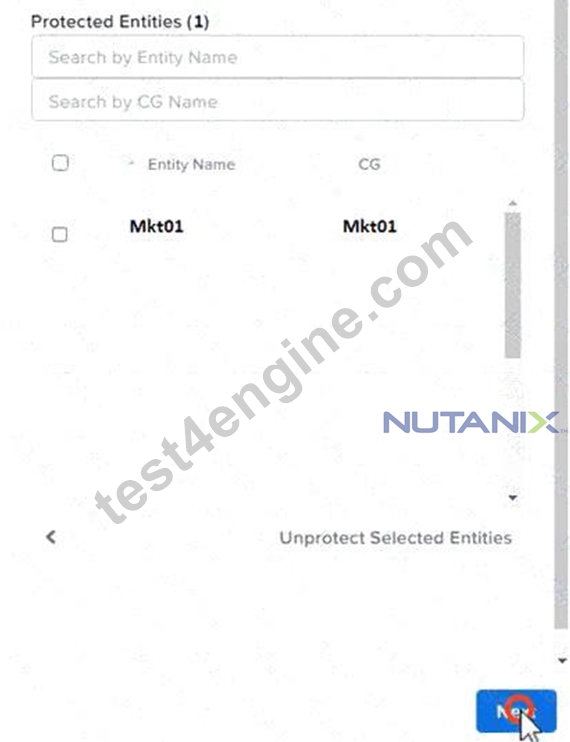
NEW QUESTION # 20
The Database team is reporting performance degradation for a business-critical application on Saturdays.
The team is requesting monitoring of processor, memory and storage utilization for the cluster for the application: SQL01, SQL02.
The report should contain views for the following:
* At the cluster level, only for the Cluster 1: The maximum percentage of CPU used
* At the VM level, including any future VM with the prefix SQL: The maximum time taken, maximum percentage of time a VM waits to use the physical CPU, out of the total CPU The report should run on Sundays at 12:00 AM for the previous 7 days. The report should show when completed.
Create a report named SQL_Batch_Saturday that meets these requirements.
Generate an instance of the report named SQL_Batch_Saturday as a CSV and save the file.
Note: You must name the report SQL_Batch_Saturday to receive any credit. Any other name will not be accepted. SMTP is not configured.
Answer:
Explanation:
See the Explanation below for detailed answer.
Explanation:
Here is the step-by-step solution to create and run the report, performed entirely within Prism Central.
1. Create the Analysis Session
First, we will build the charts and entities for the report using the Analysis tool.
* From the Prism Central main menu, navigate to Operations > Analysis.
* Click the + New Session button.
* Add the required entities:
* In the "Entities" search box, type Cluster 1 and select Cluster: Cluster 1.
* In the "Entities" search box, type SQL01 and select VM: SQL01.
* In the "Entities" search box, type SQL02 and select VM: SQL02.
* Click Add Charts > New Chart to add the Cluster CPU chart:
* Title: Cluster 1 Max CPU Usage
* Entity Type: Cluster
* Metric: Cluster CPU Usage %
* Aggregation: Select Maximum.
* Click Add.
* Click Add Charts > New Chart to add the VM CPU Ready Time chart:
* Title: VM Max CPU Ready Time
* Entity Type: VM
* Metric: CPU Ready Time %
* Aggregation: Select Maximum.
* Click Add.
2. Save and Configure the Report
Now, save the session as a report and configure it to dynamically include all VMs with the SQL prefix.
* Click the Save as Report icon (the bookmark icon in the upper right).
* Name the report SQL_Batch_Saturday and click Save.
* Navigate to Operations > Reports.
* Find the SQL_Batch_Saturday report you just created and click its name to open the report editor.
* In the Entities tile, click the Edit (pencil) icon.
* By default, it will list "Cluster 1", "SQL01", and "SQL02".
* Change the VM selection:
* Select the radio button for All VMs prefixed with.
* In the text box, enter SQL.
* Ensure "Cluster 1" is still listed under "Clusters".
* Click Save.
3. Schedule the Report
* While still in the report editor for SQL_Batch_Saturday, click the Schedule button.
* Configure the schedule:
* Recurrence: Weekly
* Repeat on: Sunday
* Start Time: 12:00 AM
* Time Range: Previous 7 Days
* Configure the notification (as SMTP is not available):
* Expand the Notification Settings section.
* Check the box for Notify when ready (this enables the bell icon notification).
* Ensure "Email Report" is not checked.
* Click Save.
4. Generate and Save the CSV Instance
Finally, run the report now and download the CSV as requested.
* Navigate back to the main Operations > Reports list.
* Select the checkbox next to SQL_Batch_Saturday.
* Click the Actions dropdown and select Run Now.
* In the dialog, confirm the time range (e.g., "Last 7 Days") and click Run.
* Click the Report Instances tab.
* Wait for the report instance "SQL_Batch_Saturday" to finish running (the status will change from
"Running" to Succeeded).
* Once it has succeeded, click the Download (arrow) icon for that instance.
* Select the CSV format.
* Save the file to the desktop.
NEW QUESTION # 21
......
With our outstanding NCM-MCI-6.10 exam questions, we can assure you a 99% percent pass rate. Due to continuous efforts of our experts, we have exactly targeted the content of the NCM-MCI-6.10 exam. You will pass the exam after 20 to 30 hours' learning with our NCM-MCI-6.10 Study Material. Many users have witnessed the effectiveness of our NCM-MCI-6.10 guide exam you surely will become one of them. Try it right now!
Valid Dumps NCM-MCI-6.10 Sheet: https://www.test4engine.com/NCM-MCI-6.10_exam-latest-braindumps.html