JapancertにたくさんのIT専門人士がいって、弊社の問題集に社会のITエリートが認定されて、弊社の問題集は試験の大幅カーバして、合格率が100%にまで達します。弊社のみたいなウエブサイトが多くても、彼たちは君の学習についてガイドやオンラインサービスを提供するかもしれないが、弊社はそちらにより勝ちます。Japancertは同業の中でそんなに良い地位を取るの原因は弊社のかなり正確な試験の練習問題と解答そえに迅速の更新で、このようにとても良い成績がとられています。そして、弊社が提供した問題集を安心で使用して、試験を安心で受けて、君のMicrosoft DP-800認証試験の100%の合格率を保証しますす。
| トピック | 出題範囲 |
|---|---|
| トピック 1 |
|
| トピック 2 |
|
| トピック 3 |
|
今の社会はますます激しく変化しているから、私たちはいつまでも危機意識を強化します。キャンパース内のIT知識を学ぶ学生なり、IT職人なり、DP-800試験資格認証証明書を取得して、社会需要に応じて自分の能力を高めます。我々社は最高のMicrosoft DP-800試験問題集を開発し提供して、一番なさービスを与えて努力しています。業界で有名なMicrosoft DP-800問題集販売会社として、購入意向があると、我々の商品を選んでくださいませんか。
質問 # 70
You have a database named DB1. The schema is stored in a GitHub repository as an SDK style SQL database project.
You use a feature branch workflow to deploy changes to DB1
You need to update the local feature branch with the latest changes to main, and then create a pull request to merge the feature branch into main for review.
How should you complete the GitHub CLI script? To answer, drag the appropriate values to the correct targets. Each value may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.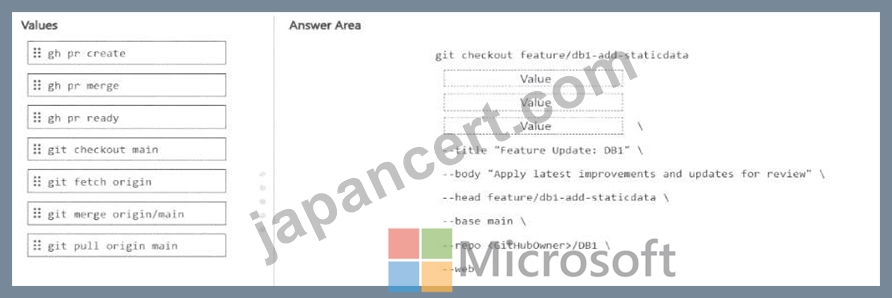
正解:
解説: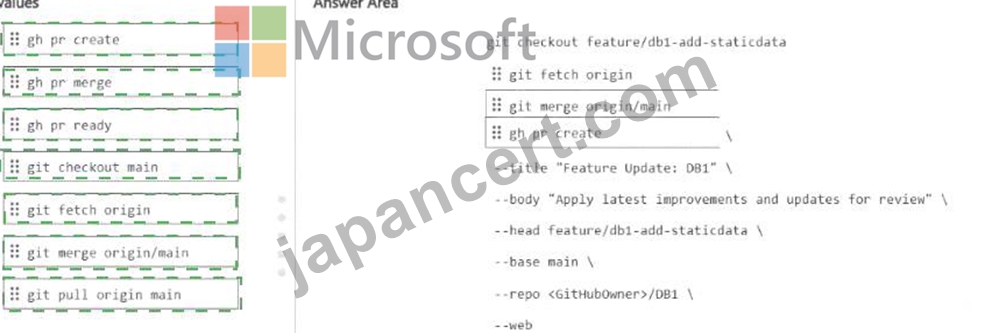
Explanation: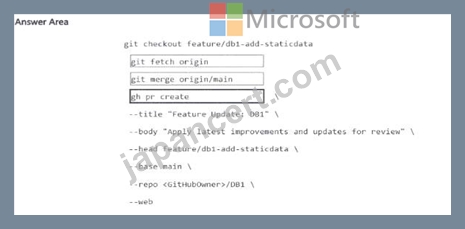
The correct sequence is:
* git fetch origin
* git merge origin/main
* gh pr create
This is the right workflow because the script starts on the local feature branch:
git checkout feature/db1-add-staticdata
To update that local feature branch with the latest changes from main, you first fetch the latest remote refs with git fetch origin , then merge the updated remote main branch into the current feature branch with git merge origin/main . After the feature branch is up to date, the correct GitHub CLI command to open the pull request is gh pr create . GitHub's CLI documentation shows that gh pr create is the command used to create a pull request, and supports flags such as --title, --body, --head, --base, --repo, and --web, which match the script shown in the question.
The other commands are not the best fit here:
* git checkout main would move you off the feature branch, which is not what you want before merging main into the feature branch.
* git pull origin main could update from remote main, but the script pattern here clearly separates fetching and then merging.
* gh pr merge merges an existing pull request, not create one.
* gh pr ready marks a draft PR as ready for review, but does not create the PR.
質問 # 71
You have a database named db1. The schema is stored in a Git repository as an SDK-style SQL database project The repository Contains the following GitHub Action workflow.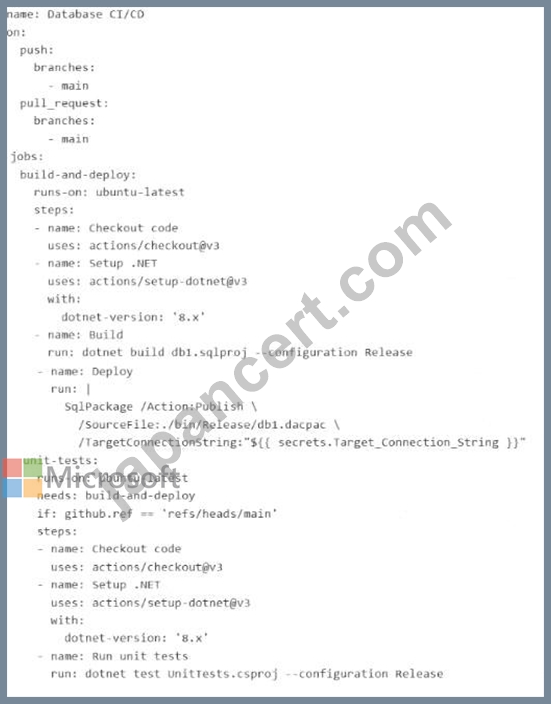
For each of the following statements, select Yes if the statement is true. Otherwise, select No. NOTE: Each correct selection is worth one point.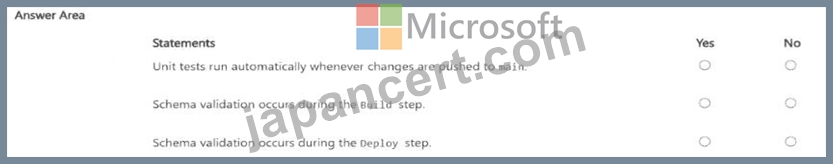
正解:
解説: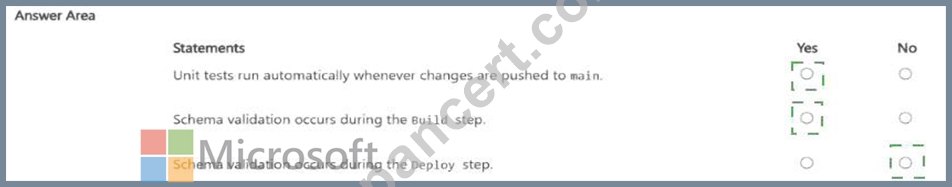
Explanation:
* Unit tests run automatically whenever changes are pushed to main. # Yes
* Schema validation occurs during the Build step. # Yes
* Schema validation occurs during the Deploy step. # No
The first statement is Yes . The workflow is configured to trigger on both push to main and pull_request targeting main. The unit-tests job has this condition:
if: github.ref == ' refs/heads/main '
On a push to main , GitHub sets github.ref to refs/heads/main, so the condition is true and the unit-tests job runs. GitHub's workflow syntax documentation confirms that push.branches: [main] triggers on pushes to main, and the github.ref value for branch pushes is the fully qualified ref such as refs/heads/main.
The second statement is Yes . The Build step runs:
dotnet build db1.sqlproj --configuration Release
For an SDK-style SQL database project, the build process produces a .dacpac and validates the database project model as part of compilation/build. Microsoft's SQL database project documentation describes SDK- style SQL projects as the project format used for SQL Database Projects, and Microsoft's command-line build documentation is specifically about building a .dacpac from that SQL project. That means schema-level project validation happens during build.
The third statement is No . The Deploy step uses:
SqlPackage /Action:Publish ...
Microsoft documents that SqlPackage Publish incrementally updates the target database schema to match the source .dacpac. That is a deployment operation, not the primary schema-validation stage of the SQL project source itself. In this workflow, the schema is validated when the SQL project is built into the .dacpac; the deploy step applies that built artifact to the target database.
質問 # 72
You have a Microsoft SQL Server 2025 database that contains a table named products. products contains two columns named description and embedding. embedding is generated from description.
You have an application named App1. App1 has a feature that uses the following query.
VECTOR_DISTANCE('cosine', @query_vector, embedding)
Users report that the feature is slow during peak usage times.
You discover that during peak usage times, the semantic search latency increases and CPU utilization spikes.
You need to reduce latency and CPU utilization related to the App1 feature.
What should you do?
正解:D
解説:
To optimize your Microsoft SQL Server 2025 environment, you should transition from a brute- force distance calculation to an Approximate Nearest Neighbor (ANN) search using a DiskANN- based vector index.
The Solution: Vector Indexing
The VECTOR_DISTANCE function performs a full table scan, calculating the distance for every single row. During peak times, this consumes massive CPU cycles. A vector index allows SQL Server to navigate a pre-built graph to find matches, reducing complexity from O(n) to O(log n).
Implementation Steps
1. Create the Vector Index
You must specify the distance metric during index creation. For cosine similarity, use COSINE.
CREATE VECTOR INDEX idx_product_embedding
ON products (embedding)
WITH (METRIC = 'COSINE');
2. Update the Search Query
Replace the WHERE or ORDER BY clause that uses VECTOR_DISTANCE with the VECTOR_SEARCH function.
SELECT TOP (10) description, embedding
FROM products
WHERE VECTOR_SEARCH(
embedding,
@query_vector,
'COSINE',
10 -- Number of neighbors to return
);
Why This Solves Your Problem
CPU Relief: Avoids calculating distances for millions of rows.
Lower Latency: DiskANN is designed for sub-second retrieval even on large datasets.
Peak Performance: By offloading the math to a specialized index structure, the engine remains responsive for other transactional queries.
Reference:
https://learn.microsoft.com/en-us/azure/postgresql/extensions/how-to-use-pgdiskann
質問 # 73
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You have a SQL database in Microsoft Fabric that contains a table named dbo.Orders.
dbo.Orders has a clustered index, contains three years of data, and is partitioned by a column named OrderDate by month.
You need to remove all the rows for the oldest month. The solution must minimize the impact on other queries that access the data in dbo.Orders.
Solution: Identify the partition scheme for the oldest month, and then run the following Transact- SQL statement.
ALTER TABLE dbo.Orders
DROP PARTITION SCHEME (partition_scheme_name);
Does this meet the goal?
正解:B
解説:
Correct:
* Identify the partition number for the oldest month, and then run the following Transact-SQL statement.
TRUNCATE TABLE dbo.Orders
WITH (PARTITIONS (partition number));
The best Transact-SQL statement to remove all rows for the oldest month while minimizing the impact on other queries is TRUNCATE TABLE with a WITH (PARTITIONS (...)) clause.
Why TRUNCATE TABLE ... WITH (PARTITIONS (...)) is Best
Efficiency: TRUNCATE TABLE is a Data Definition Language (DDL) operation that removes data by deallocating the data pages, which is a metadata operation and is very fast, regardless of the amount of data in the partition.
Minimal Logging: It uses less transaction log space compared to a DELETE statement, which logs each row deletion individually.
Low Impact on Concurrency: It performs a quick, partition-specific operation. A row-by-row DELETE would be a long-running transaction and could cause locking and blocking issues for other queries accessing the table.
Data Integrity: Because the table has a clustered index and is partitioned by the same column (aligned indexes), the TRUNCATE PARTITION operation is a fast, partition-level maintenance operation that targets only that specific data subset.
Incorrect:
* : Identify the partition scheme for the oldest month, and then run the following Transact-SQL statement.
ALTER TABLE dbo.Orders
DROP PARTITION SCHEME (partition_scheme_name);
The DROP PARTITION SCHEME statement removes the partition scheme object from the database but does not remove the data itself or free up the space, and it requires all tables to be moved off the scheme first, which is a complex operation. This does not meet the goal of removing the data efficiently.
* Run the following Transact-SQL statement.
DELETE FROM dbo.Orders
WHERE OrderDate < DATEADD(month, -36, SYSUTCDATETIME());
A standard DELETE statement, even with a WHERE clause that uses the partition column, can be a time-consuming, logged operation that causes locking and blocking on the main table, negatively impacting performance.
Reference:
https://stackoverflow.com/questions/63632963/truncate-partition-vs-drop-partition-performace- wise-which-one-is-efficient-an
質問 # 74
Hotspot Question
You have a database named db1. The schema is stored in a Git repository as an SDK-style SQL database project. The repository contains the following GitHub Action workflow.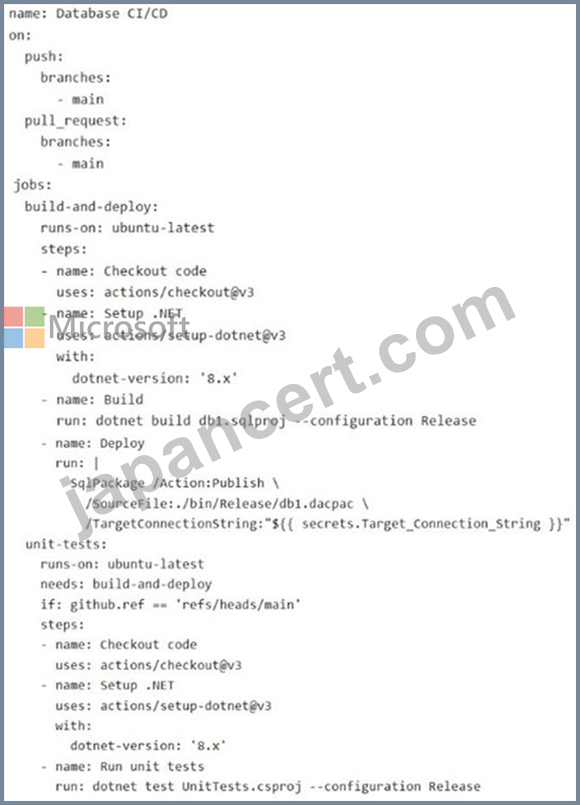
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.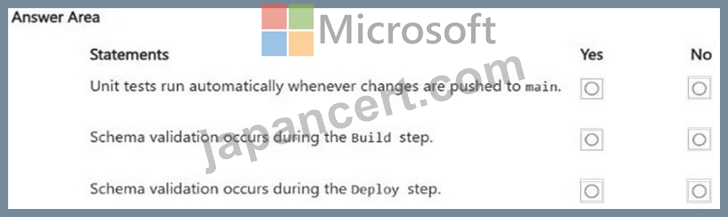
正解:
解説: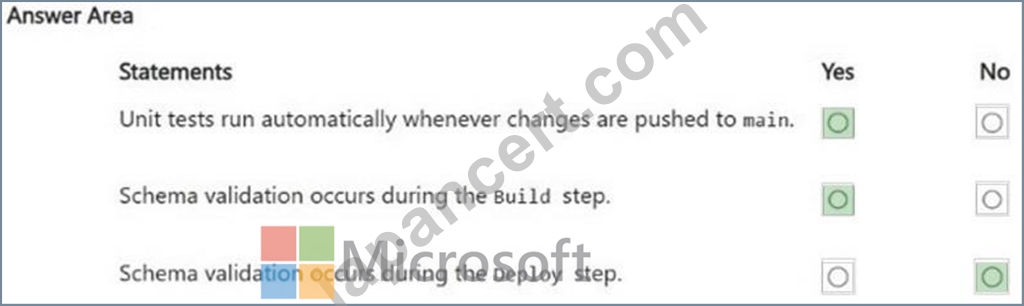
質問 # 75
......
テストに関する最も有用で効率的なDP-800トレーニング資料を提供するために最善を尽くし、クライアントが効率的に学習できるように複数の機能と直感的な方法を提供します。 DP-800の有用なテストガイドを学習すれば、時間と労力はほとんどかかりません。合格率とヒット率はともに高いため、テストに合格するための障害はほとんどありません。 Webで紹介を読んだ後、DP-800学習実践ガイドをさらに理解できます。
DP-800オンライン試験: https://www.japancert.com/DP-800.html