그 외, Itcertkr DY0-001 시험 문제집 일부가 지금은 무료입니다: https://drive.google.com/open?id=1ihVAzpaPsESfbD95XmeHAVdBSY0fqa47
최근 IT 업종에 종사하는 분들이 점점 늘어가는 추세하에 경쟁이 점점 치열해지고 있습니다. IT인증시험은 국제에서 인정받는 효력있는 자격증을 취득하는 과정으로서 널리 알려져 있습니다. Itcertkr의 CompTIA인증 DY0-001덤프는IT인증시험의 한 과목인 CompTIA인증 DY0-001시험에 대비하여 만들어진 시험전 공부자료인데 높은 시험적중율과 친근한 가격으로 많은 사랑을 받고 있습니다.
| Certification Vendor: | CompTIA |
|---|---|
| Exam Name: | CompTIA DataAI Certification Exam |
| Exam Number: | DY0-001 |
| Exam Price: | $544 USD |
| Real Exam Qty: | Up to 90 |
| Certificate Validity Period: | 3 years |
| Related Certifications: | CompTIA Data+ CompTIA AI Essentials |
| Exam Format: | Multiple Choice, Performance-Based Questions (PBQs) |
| Passing Score: | Pass/Fail (no numerical score) |
| Exam Duration: | 165 minutes |
| Available Languages: | English, Japanese |
| Recommended Training: | CompTIA CertMaster Learn for DataAI CompTIA Official Study Guide |
| Exam Registration: | Pearson VUE Scheduling CompTIA Official Registration |
| Sample Questions: | CompTIA DY0-001 Sample Questions |
| Exam Way: | Online proctored or in-person at Pearson VUE test centers |
| Pre Condition: | No mandatory prerequisites; recommended 5+ years of experience in data science, analytics, or related fields |
| Official Syllabus URL: | https://www.comptia.org/certifications/dataai |
Itcertkr는Itcertkr의CompTIA인증 DY0-001덤프자료를 공부하면 한방에 시험패스하는것을 굳게 약속드립니다. Itcertkr의CompTIA인증 DY0-001덤프로 공부하여 시험불합격받으면 바로 덤프비용전액 환불처리해드리는 서비스를 제공해드리기에 아무런 무담없는 시험준비공부를 할수 있습니다.
| 주제 | 소개 |
|---|---|
| 주제 1 |
|
| 주제 2 |
|
| 주제 3 |
|
| 주제 4 |
|
| 주제 5 |
|
질문 # 83
A data scientist needs to:
Build a predictive model that gives the likelihood that a car will get a flat tire.
Provide a data set of cars that had flat tires and cars that did not.
All the cars in the data set had sensors taking weekly measurements of tire pressure similar to the sensors that will be installed in the cars consumers drive. Which of the following is the most immediate data concern?
정답:A
설명:
Because tire-pressure sensors report only weekly measurements, you risk missing the critical pressure drop immediately preceding a flat. Those stale ("lagged") readings may not reflect the condition just before failure, undermining your model's ability to learn the true precursors to a flat tire.
질문 # 84
A computer vision model is trained to identify cats on a training set that is composed of both cat and dog images. The model predicts a picture of a cat is a dog. Which of the following describes this error?
정답:B
설명:
Classifying an actual cat (positive instance) as a dog (negative prediction) is a false negative, which corresponds to a Type II error.
질문 # 85
During EDA, a data scientist wants to look for patterns, such as linearity, in the data. Which of the following plots should the data scientist use?
정답:C
설명:
# Scatter plots are used to examine relationships and trends between two numeric variables. They are especially effective at revealing linear (or nonlinear) patterns, clusters, and outliers.
Why the other options are incorrect:
* A: Violin plots show distribution and density, not relationships.
* B: Box plots compare distributions across groups but don't reveal linearity.
* D: Q-Q plots test normality, not variable relationships.
Official References:
* CompTIA DataX (DY0-001) Official Study Guide - Section 1.2:"Scatter plots are commonly used during EDA to identify correlations, linearity, and outliers between two continuous variables."
* Data Science Fundamentals, Chapter 2 - EDA Techniques:"To assess linear trends and relationships, scatter plots provide a direct visual assessment between variables."
질문 # 86
Which of the following modeling tools is appropriate for solving a scheduling problem?
정답:D
설명:
Scheduling problems typically involve the assignment of limited resources (e.g., time, personnel, machines) over time to tasks, often under constraints. These problems are inherently mathematical and are typically solved using:
# Constrained Optimization - which is a mathematical technique for optimizing an objective function subject to one or more constraints. This tool is widely used for operations research problems such as scheduling, resource allocation, logistics, and supply chain optimization.
Why the other options are incorrect:
* A. One-armed bandit: Refers to a class of algorithms used for balancing exploration and exploitation, not scheduling.
* C. Decision tree: Used for classification and regression, not for constraint-based scheduling.
* D. Gradient descent: An optimization method for training models (typically ML), but not specifically suitable for complex constraint-based scheduling.
Official References:
* CompTIA DataX (DY0-001) Official Study Guide - Section 3.4 (Modeling Tools):"Scheduling and allocation problems are best addressed using constrained optimization techniques which allow incorporation of resource limits and goal functions."
* Data Science and Operations Research Foundations, Chapter 7:"Constraint-based optimization is the primary mathematical strategy used in scheduling problems to meet deadlines, minimize cost, or maximize throughput."
-
질문 # 87
A data scientist needs to determine whether product sales are impacted by other contributing factors. The client has provided the data scientist with sales and other variables in the data set.
The data scientist decides to test potential models that include other information.
INSTRUCTIONS
Part 1
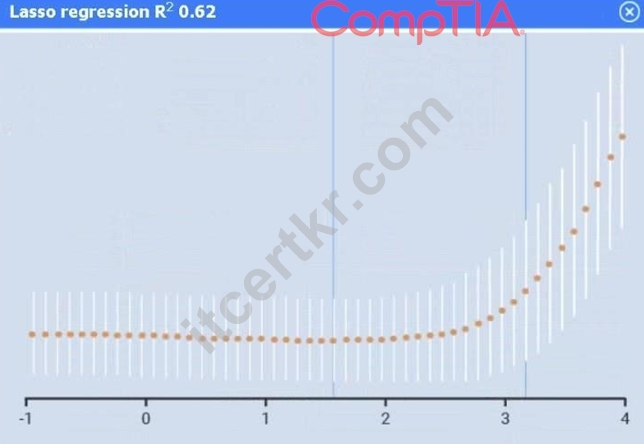
Use the information provided in the table to select the appropriate regression model.
Part 2
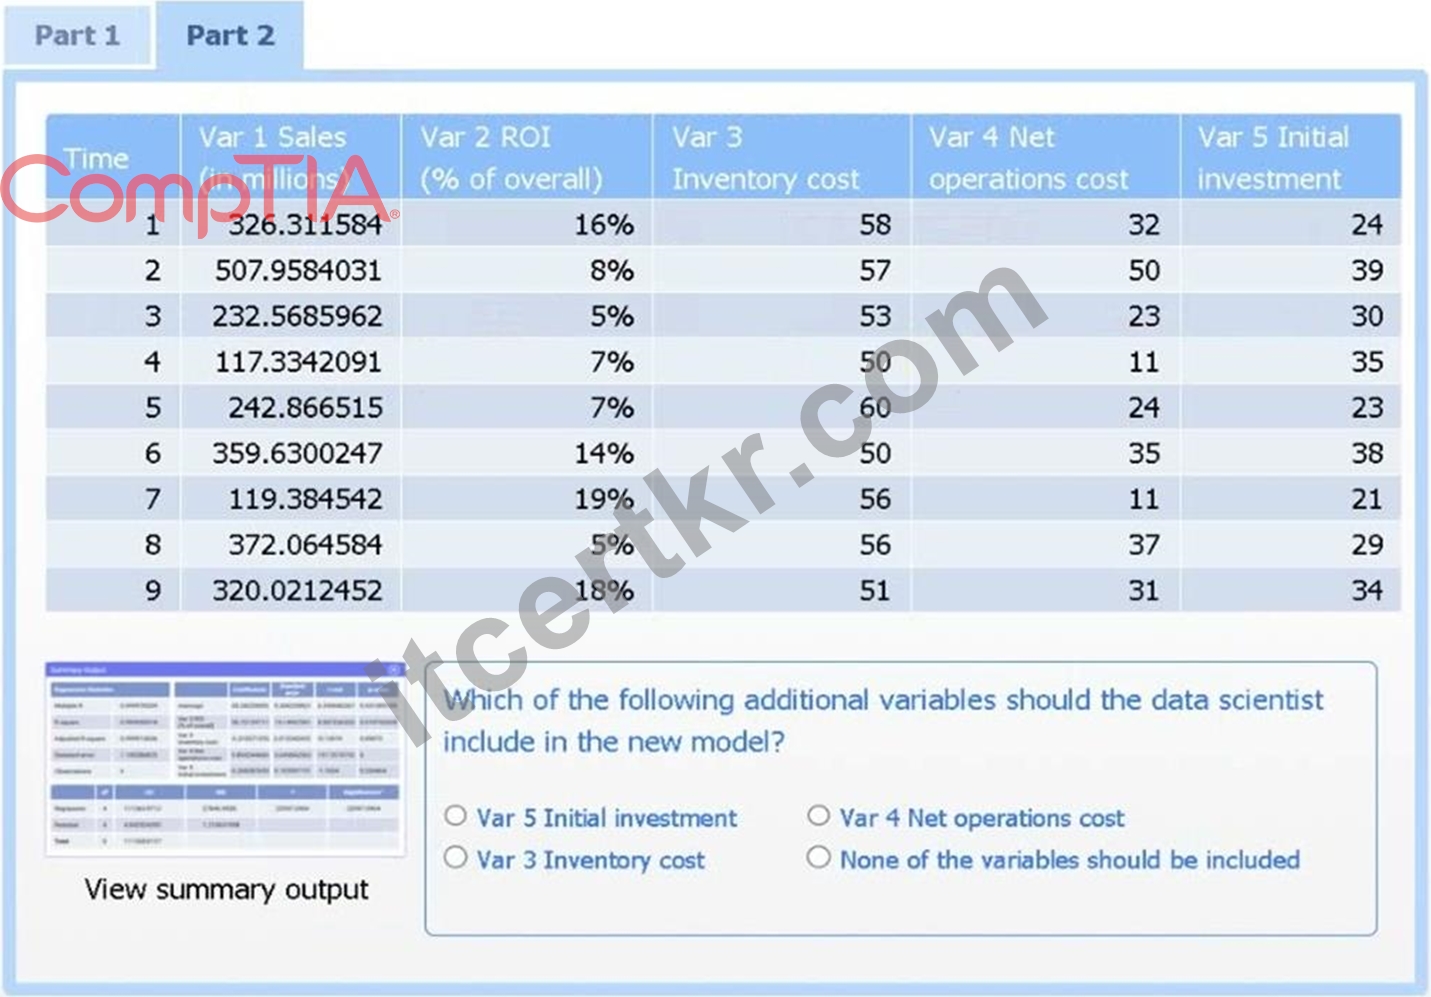
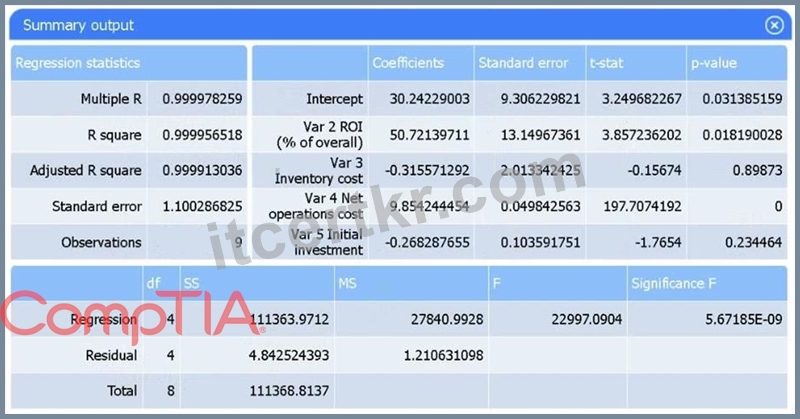
Review the summary output and variable table to determine which variable is statistically significant.
If at any time you would like to bring back the initial state of the simulation, please click the Reset All button.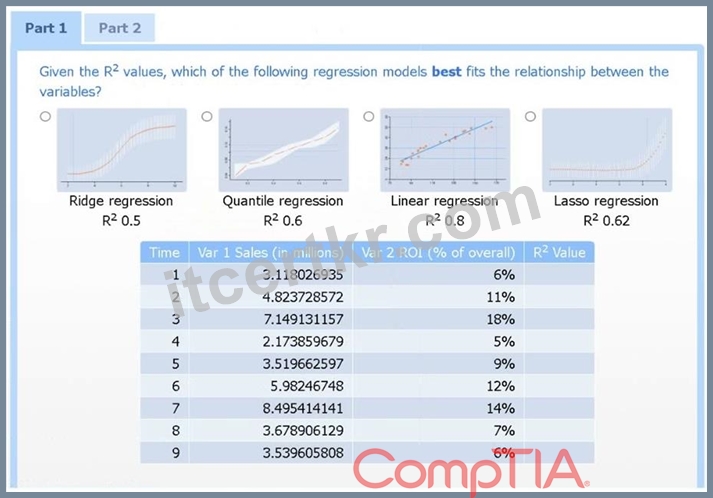
정답:
설명:
See explanation below.
Explanation:
Part 1
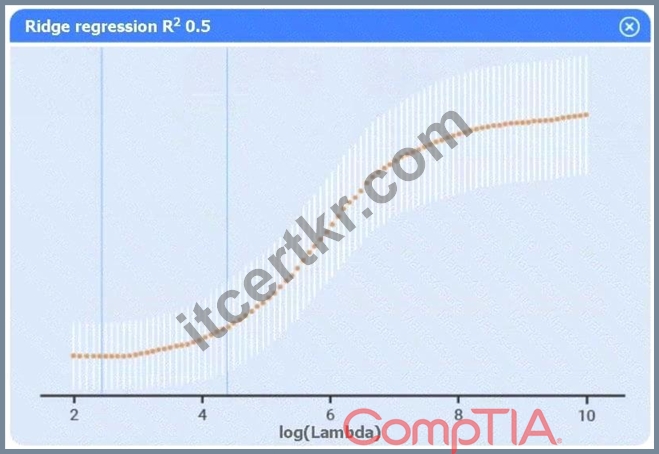
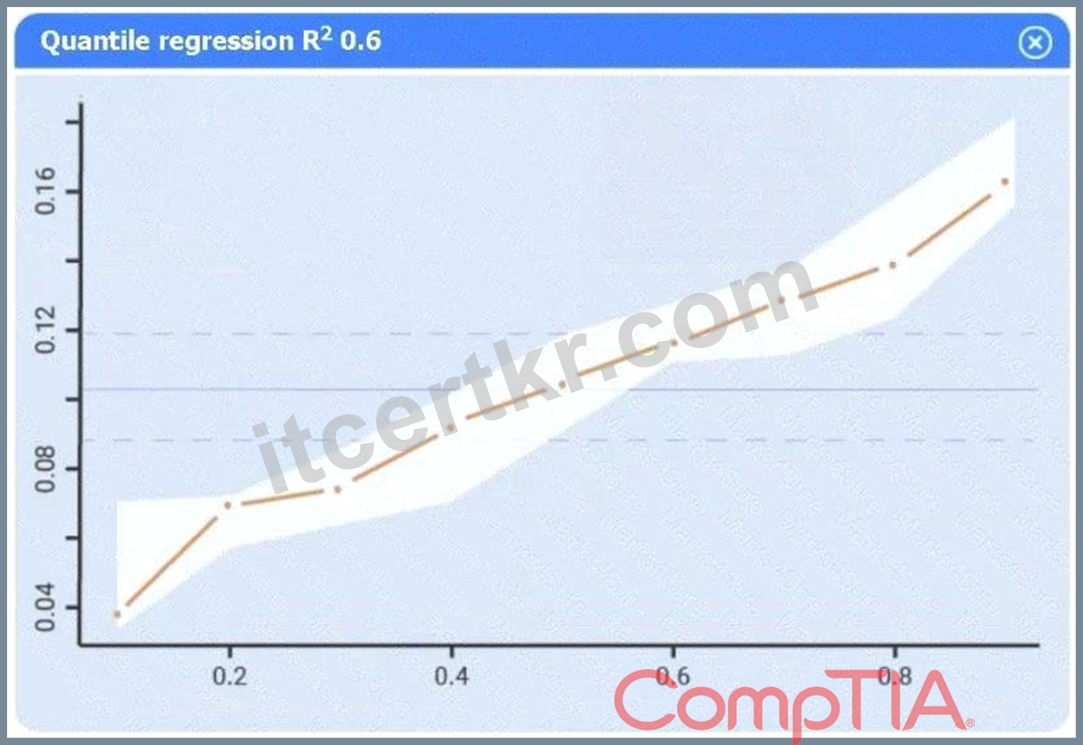
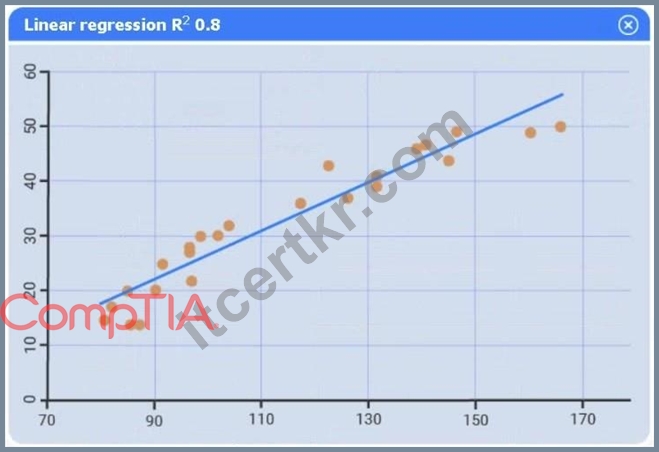
Linear regression.
Of the four models, linear regression has the highest R² (0.8), indicating it explains the greatest proportion of variance in sales.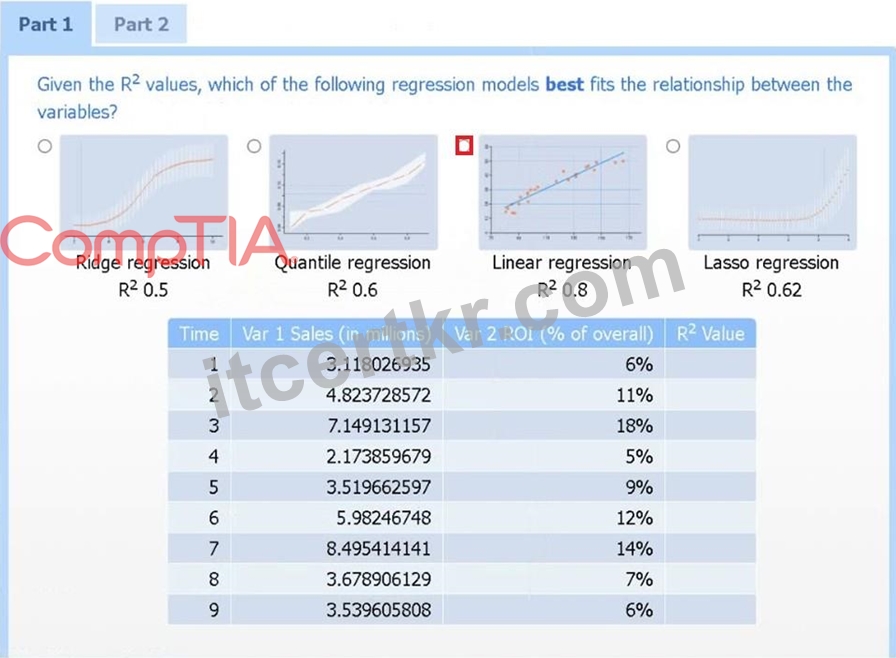
Part 2
Var 4 - Net operations cost.
Net operations cost has a p-value of essentially 0 (far below 0.05), indicating it is the only additional predictor statistically significant in explaining sales. Neither inventory cost (p#0.90) nor initial investment (p#0.23) reach significance.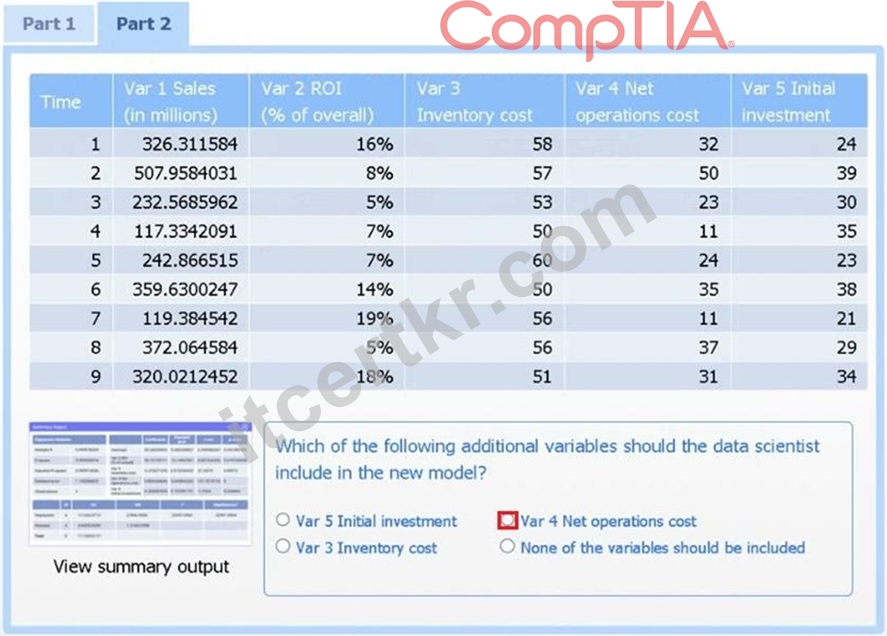
질문 # 88
......
DY0-001합격보장 가능 덤프공부: https://www.itcertkr.com/DY0-001_exam.html
Itcertkr DY0-001 최신 PDF 버전 시험 문제집을 무료로 Google Drive에서 다운로드하세요: https://drive.google.com/open?id=1ihVAzpaPsESfbD95XmeHAVdBSY0fqa47