ちなみに、Fast2test Databricks-Generative-AI-Engineer-Associateの一部をクラウドストレージからダウンロードできます:https://drive.google.com/open?id=1aZKNRlevyh2AAurg-OW0xl45mYQzZ8gh
このインターネット時代において、社会の発展とともに、コストがより低くて内容が完全な情報が不可欠です。弊社のDatabricks-Generative-AI-Engineer-Associate問題集は他のサイトに比べて、試験の範囲をカバーすることはより広くて、合理的な価格があります。しかしも、品質はもっと高くて一度Databricks-Generative-AI-Engineer-Associate試験に合格したい客様に対して、我が社のDatabricks-Generative-AI-Engineer-Associateはあなたの最高選択かつ成功のショートカットであると思われます。
| トピック | 出題範囲 |
|---|---|
| トピック 1 |
|
| トピック 2 |
|
| トピック 3 |
|
| トピック 4 |
|
| トピック 5 |
|
>> Databricks-Generative-AI-Engineer-Associateテスト難易度 <<
Fast2testはDatabricks-Generative-AI-Engineer-Associate認定試験に対する短期で有効な訓練を提供するウェブサイト、Databricks-Generative-AI-Engineer-Associate認定試験が生活の変化をもたらすテストでございます。合格書を持ち方が持たない人により高い給料をもうけられます。
質問 # 27
A Generative Al Engineer is building an LLM-based application that has an important transcription (speech-to-text) task. Speed is essential for the success of the application Which open Generative Al models should be used?
正解:B
解説:
The task requires an open generative AI model for a transcription (speech-to-text) task where speed is essential. Let's assess the options based on their suitability for transcription and performance characteristics, referencing Databricks' approach to model selection.
* Option A: Llama-2-70b-chat-hf
* Llama-2 is a text-based LLM optimized for chat and text generation, not speech-to-text. It lacks transcription capabilities.
* Databricks Reference:"Llama models are designed for natural language generation, not audio processing"("Databricks Model Catalog").
* Option B: MPT-30B-Instruct
* MPT-30B is another text-based LLM focused on instruction-following and text generation, not transcription. It's irrelevant for speech-to-text tasks.
* Databricks Reference: No specific mention, but MPT is categorized under text LLMs in Databricks' ecosystem, not audio models.
* Option C: DBRX
* DBRX, developed by Databricks, is a powerful text-based LLM for general-purpose generation.
It doesn't natively support speech-to-text and isn't optimized for transcription.
* Databricks Reference:"DBRX excels at text generation and reasoning tasks"("Introducing DBRX," 2023)-no mention of audio capabilities.
* Option D: whisper-large-v3 (1.6B)
* Whisper, developed by OpenAI, is an open-source model specifically designed for speech-to-text transcription. The "large-v3" variant (1.6 billion parameters) balances accuracy and efficiency, with optimizations for speed via quantization or deployment on GPUs-key for the application's requirements.
* Databricks Reference:"For audio transcription, models like Whisper are recommended for their speed and accuracy"("Generative AI Cookbook," 2023). Databricks supports Whisper integration in its MLflow or Lakehouse workflows.
Conclusion: OnlyD. whisper-large-v3is a speech-to-text model, making it the sole suitable choice. Its design prioritizes transcription, and its efficiency (e.g., via optimized inference) meets the speed requirement, aligning with Databricks' model deployment best practices.
質問 # 28
A Generative Al Engineer has created a RAG application to look up answers to questions about a series of fantasy novels that are being asked on the author's web forum. The fantasy novel texts are chunked and embedded into a vector store with metadata (page number, chapter number, book title), retrieved with the user' s query, and provided to an LLM for response generation. The Generative AI Engineer used their intuition to pick the chunking strategy and associated configurations but now wants to more methodically choose the best values.
Which TWO strategies should the Generative AI Engineer take to optimize their chunking strategy and parameters? (Choose two.)
正解:C、E
解説:
To optimize a chunking strategy for a Retrieval-Augmented Generation (RAG) application, the Generative AI Engineer needs a structured approach to evaluating the chunking strategy, ensuring that the chosen configuration retrieves the most relevant information and leads to accurate and coherent LLM responses. Here
' s why C and E are the correct strategies:
Strategy C: Evaluation Metrics (Recall, NDCG)
* Define an evaluation metric : Common evaluation metrics such as recall, precision, or NDCG (Normalized Discounted Cumulative Gain) measure how well the retrieved chunks match the user ' s query and the expected response.
* Recall measures the proportion of relevant information retrieved.
* NDCG is often used when you want to account for both the relevance of retrieved chunks and the ranking or order in which they are retrieved.
* Experiment with chunking strategies : Adjusting chunking strategies based on text structure (e.g., splitting by paragraph, chapter, or a fixed number of tokens) allows the engineer to experiment with various ways of slicing the text. Some chunks may better align with the user ' s query than others.
* Evaluate performance : By using recall or NDCG, the engineer can methodically test various chunking strategies to identify which one yields the highest performance. This ensures that the chunking method provides the most relevant information when embedding and retrieving data from the vector store.
Strategy E: LLM-as-a-Judge Metric
* Use the LLM as an evaluator : After retrieving chunks, the LLM can be used to evaluate the quality of answers based on the chunks provided. This could be framed as a " judge " function, where the LLM compares how well a given chunk answers previous user queries.
* Optimize based on the LLM ' s judgment : By having the LLM assess previous answers and rate their relevance and accuracy, the engineer can collect feedback on how well different chunking configurations perform in real-world scenarios.
* This metric could be a qualitative judgment on how closely the retrieved information matches the user ' s intent.
* Tune chunking parameters : Based on the LLM ' s judgment, the engineer can adjust the chunk size or structure to better align with the LLM ' s responses, optimizing retrieval for future queries.
By combining these two approaches, the engineer ensures that the chunking strategy is systematically evaluated using both quantitative (recall/NDCG) and qualitative (LLM judgment) methods. This balanced optimization process results in improved retrieval relevance and, consequently, better response generation by the LLM.
質問 # 29
A Generative AI Engineer I using the code below to test setting up a vector store: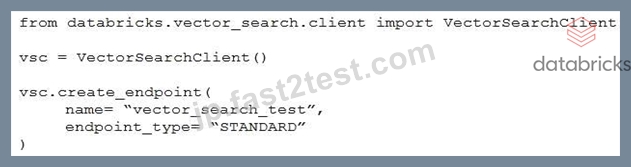
Assuming they intend to use Databricks managed embeddings with the default embedding model, what should be the next logical function call?
正解:C
解説:
Context: The Generative AI Engineer is setting up a vector store using Databricks' VectorSearchClient. This is typically done to enable fast and efficient retrieval of vectorized data for tasks like similarity searches.
Explanation of Options:
* Option A: vsc.get_index(): This function would be used to retrieve an existing index, not create one, so it would not be the logical next step immediately after creating an endpoint.
* Option B: vsc.create_delta_sync_index(): After setting up a vector store endpoint, creating an index is necessary to start populating and organizing the data. The create_delta_sync_index() function specifically creates an index that synchronizes with a Delta table, allowing automatic updates as the data changes. This is likely the most appropriate choice if the engineer plans to use dynamic data that is updated over time.
* Option C: vsc.create_direct_access_index(): This function would create an index that directly accesses the data without synchronization. While also a valid approach, it's less likely to be the next logical step if the default setup (typically accommodating changes) is intended.
* Option D: vsc.similarity_search(): This function would be used to perform searches on an existing index; however, an index needs to be created and populated with data before any search can be conducted.
Given the typical workflow in setting up a vector store, the next step after creating an endpoint is to establish an index, particularly one that synchronizes with ongoing data updates, henceOption B.
質問 # 30
A team uses Mosaic AI Vector Search to retrieve documents for their Retrieval-Augmented Generation (RAG) pipeline. The search query returns five relevant documents, and the first three are added to the prompt as context. Performance evaluation with Agent Evaluation shows that some lower-ranked retrieved documents have higher context relevancy scores than higher-ranked documents. Which option should the team consider to optimize this workflow?
正解:C
解説:
The scenario describes a common " retrieval gap " where the initial bi-encoder (embedding model) used for vector search identifies relevant documents but does not rank them perfectly. This happens because embedding models represent entire documents as a single vector, which can lose nuance. The standard engineering solution is to implement a Reranker (Cross-Encoder). Unlike embedding models, a reranker processes the query and a candidate document simultaneously, allowing it to capture deep semantic interactions between the two. In a Mosaic AI workflow, after the vector search retrieves the top $k$ documents, the reranker evaluates those specific $k$ documents to produce a more accurate relevance score.
This ensures that the most contextually relevant documents are placed at the top of the list (and thus the top of the LLM prompt), which is crucial because LLMs are sensitive to document order and often prioritize information found at the beginning of the context.
質問 # 31
A Generative Al Engineer would like an LLM to generate formatted JSON from emails. This will require parsing and extracting the following information: order ID, date, and sender email. Here's a sample email: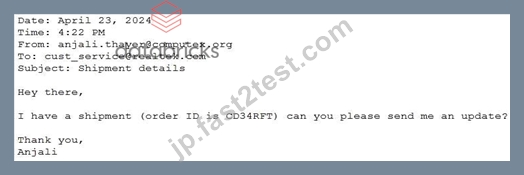
They will need to write a prompt that will extract the relevant information in JSON format with the highest level of output accuracy.
Which prompt will do that?
正解:B
解説:
Problem Context: The goal is to parse emails to extract certain pieces of information and output this in a structured JSON format. Clarity and specificity in the prompt design will ensure higher accuracy in the LLM' s responses.
Explanation of Options:
* Option A: Provides a general guideline but lacks an example, which helps an LLM understand the exact format expected.
* Option B: Includes a clear instruction and a specific example of the output format. Providing an example is crucial as it helps set the pattern and format in which the information should be structured, leading to more accurate results.
* Option C: Does not specify that the output should be in JSON format, thus not meeting the requirement.
* Option D: While it correctly asks for JSON format, it lacks an example that would guide the LLM on how to structure the JSON correctly.
Therefore,Option Bis optimal as it not only specifies the required format but also illustrates it with an example, enhancing the likelihood of accurate extraction and formatting by the LLM.
質問 # 32
......
Databricks-Generative-AI-Engineer-Associate学習ガイドを今すぐ購入してください。お手伝いします。すぐにそれが信じられます、あなたは成功した人です!業界の他の製品と比較して、Databricks-Generative-AI-Engineer-Associate実際の試験の合格率は高くなっています。本当に試験に合格したい場合、これはあなたが最も感じさせるものでなければなりません。当社は、コンテンツやサービスなどのさまざまな側面からこの合格率を保証します。もちろん、ユーザーのニーズも考慮します。Databricks-Generative-AI-Engineer-Associate試験問題は、すべてのユーザーが夢を実現するのに役立つことを願っています。 Databricks-Generative-AI-Engineer-Associateスタディガイドの99%合格率は、私たちにとって非常に誇らしい結果です。
Databricks-Generative-AI-Engineer-Associate技術内容: https://jp.fast2test.com/Databricks-Generative-AI-Engineer-Associate-premium-file.html
BONUS!!! Fast2test Databricks-Generative-AI-Engineer-Associateダンプの一部を無料でダウンロード:https://drive.google.com/open?id=1aZKNRlevyh2AAurg-OW0xl45mYQzZ8gh