P.S. Free & New DP-750 dumps are available on Google Drive shared by PassLeader: https://drive.google.com/open?id=1xUuWJp2sZ5Sh6nrXLqhWkrU4xtFb03b0
The key trait of our product is that we keep pace with the changes of syllabus and the latest circumstance to revise and update our DP-750 study materials, and we are available for one-year free updating to assure you of the reliability of our service. Our company has established a long-term partnership with those who have purchased our DP-750 exam guides. We have made all efforts to update our product in order to help you deal with any change, making you confidently take part in the exam. We will inform you that the DP-750 Study Materials should be updated and send you the latest version in a year after your payment. We will also provide some discount for your updating after a year if you are satisfied with our DP-750 exam prepare.
| Section | Weight | Objectives |
|---|---|---|
| Secure and govern Unity Catalog objects | 15–20% | - Implement data governance and security
|
| Prepare and process data | 30–35% | - Ingest and transform data
|
| Set up and configure an Azure Databricks environment | 15–20% | - Select and configure compute resources
|
| Deploy and maintain data pipelines and workloads | 30–35% | - Monitor, troubleshoot, and maintain workloads
|
>> DP-750 Reliable Exam Blueprint <<
Once you have practiced and experienced the quality of our DP-750 exam preparation, you will remember the serviceability and usefulness of them. It explains why our DP-750 practice materials helped over 98 percent of exam candidates get the certificate you dream of successfully. Believe me you can get it too and you will be benefited by our DP-750 Study Guide as well. Just have a try on our DP-750 learning prep, and you will fall in love with it.
NEW QUESTION # 23
Which component enforces table-level permissions in Databricks?
Answer: D
Explanation:
Unity Catalog provides fine-grained access control at table, schema, and column levels. It centralizes governance across workspaces. Cluster policies control compute settings. Spark configuration does not manage security. DBFS permissions are not sufficient for enterprise governance.
NEW QUESTION # 24
You have an Azure Databricks workspace named Workspace1.
You create a compute cluster named Cluster1 that will be used to ingest data.
You need to install the required libraries on Cluster1. The solution must use Unity Catalog for access control.
What should you do?
Answer: B
Explanation:
The best action is uploading the libraries to the workspace and installing the libraries on the cluster (or ideally uploading them to Unity Catalog volumes).
Unity Catalog Compatibility: When using Unity Catalog for access control, compute clusters are typically configured with Standard (Shared) access mode. In this mode, traditional cluster init scripts [Not B.] face strict execution restrictions or are completely blocked to maintain secure user isolation.
Governance: Uploading your packages as Workspace Files or to Unity Catalog volumes allows administrators to manage access permissions directly and add them to an allowlist if needed.
Cluster-Wide Availability: Installing the libraries via the cluster's Libraries tab ensures that the required ingestion packages are automatically pre-installed and available across all nodes and notebooks running on that cluster.
Incorrect:
[Not A]
Running pip3 install manually on a cluster terminal or inside a notebook only applies to the specific notebook session (notebook-scoped). It does not natively persist across cluster restarts or handle cross-node execution effectively for data ingestion pipelines.
[Not B]
Running a custom script or a legacy init script to modify system-level paths introduces security risks and is generally incompatible with Unity Catalog's strict execution isolation policies for shared compute.
Reference:
https://docs.databricks.com/aws/en/libraries/
NEW QUESTION # 25
You have an Azure Databricks workspace that uses Databricks SQL.
You have a table named sales_goals_source that contains the following columns:
* Salesperson
* Item
* 2019
* 2020
* 2021
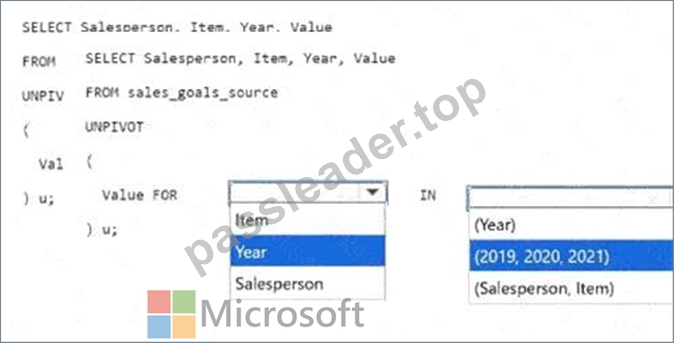
You need to transform the year columns into rows and return the columns Salesperson, Item, Year, and Value.
How should you complete the SQL statement? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
SELECT Salesperson, Item, Year, Value
FROM sales_goals_source
UNPIVOT
(
Value FOR [first dropdown] IN [second dropdown]
);
Answer:
Explanation: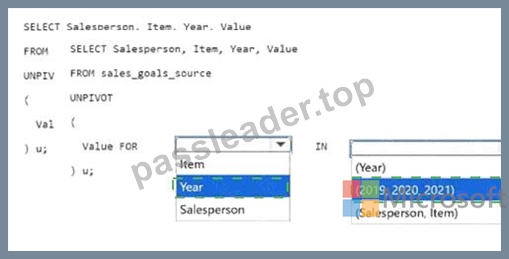
Explanation:
First dropdown: Year
Second dropdown: (2019, 2020, 2021)
The UNPIVOT operator converts the separate 2019, 2020, and 2021 columns into rows. Value becomes the output column containing the values previously stored in those year columns. Year becomes the output name column that identifies the original column from which each value came. Therefore, the expression must use Value FOR Year IN (2019, 2020, 2021). The Salesperson and Item columns are not included in the IN list because they remain identifier columns and are repeated for every resulting year row. A single source row consequently produces three output rows-one for each listed year. Selecting (Year) would reference an output name rather than the source columns that must be rotated.
NEW QUESTION # 26
Hotspot Question
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a Delta table named db1.sales_orders.
db1.sales_orders is updated nightly and has change data feed (CDF) enabled.
You need to ingest all the changes from the db1.sales_orders table, including inserts, updates, and deletes, into a downstream pipeline.
How should you complete the PsySpark code segment? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.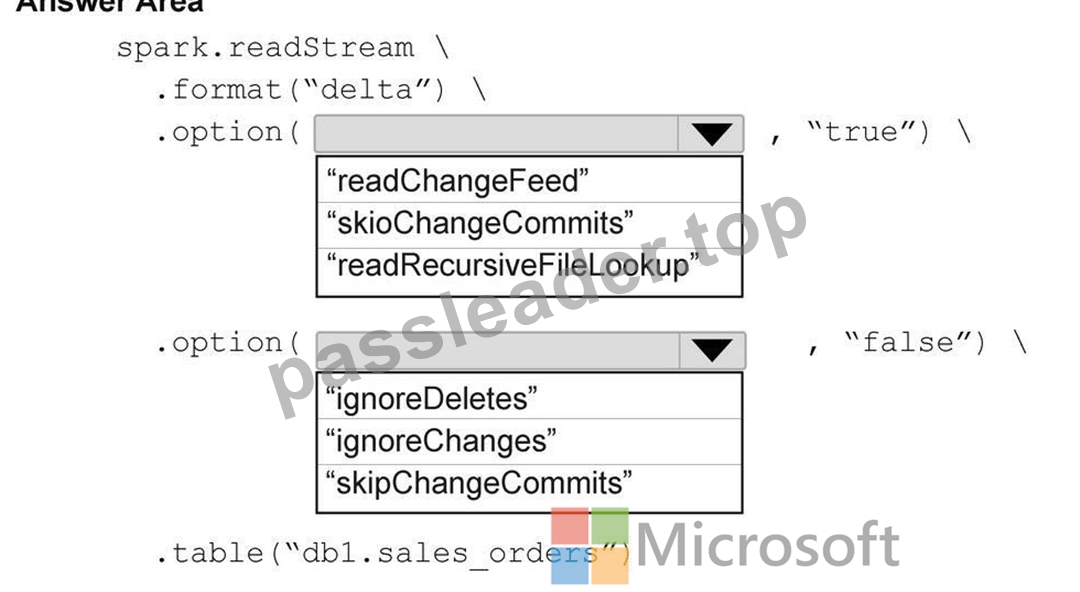
Answer:
Explanation: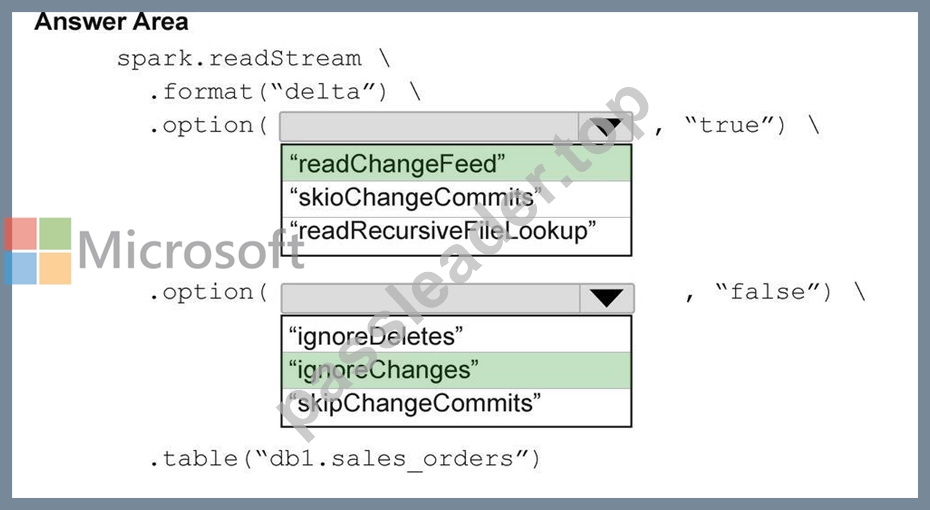
NEW QUESTION # 27
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You plan to create a job in Lakeflow Jobs named Job1 that:
* Ingests data from cloud storage
* Runs two independent transformation tasks
The transformation tasks must run only after the ingestion completes and must run in parallel.
You need to design the task logic for Job1.
What should you configure?
Answer: C
Explanation:
Job1 should contain one ingestion task that acts as the common upstream dependency for two separate transformation tasks. Once ingestion succeeds, Lakeflow Jobs can start both downstream tasks concurrently because neither transformation depends on the other. This design represents the actual workflow, avoids duplicated ingestion, and reduces total execution time through parallelism. Creating two ingestion tasks would repeat the same source processing and could introduce inconsistent results or unnecessary costs. A single sequential task would prevent parallel transformation and make failures harder to isolate and retry. Defining three independent tasks without dependencies could allow transformations to start before ingestion has completed. An explicit directed task graph therefore provides the required execution order while preserving parallelism for independent downstream processing.
NEW QUESTION # 28
......
No matter in China or other company, Microsoft has great influence for both enterprise and personal. If you can go through examination with DP-750 latest exam study guide and obtain a certification, there may be many jobs with better salary and benefits waiting for you. Most large companies think a lot of IT professional certification. DP-750 Latest Exam study guide makes your test get twice the result with half the effort and little cost.
Exam DP-750 Questions: https://www.passleader.top/Microsoft/DP-750-exam-braindumps.html
DOWNLOAD the newest PassLeader DP-750 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1xUuWJp2sZ5Sh6nrXLqhWkrU4xtFb03b0