Users do not need to spend too much time on DP-800 questions torrent, only need to use their time pieces for efficient learning, the cost is about 20 to 30 hours, users can easily master the test key and difficulties of questions and answers of DP-800 Prep Guide, and in such a short time acquisition of accurate examination skills, better answer out of step, so as to realize high pass the qualification test, has obtained the corresponding qualification certificate.
| Certification Vendor: | Microsoft |
|---|---|
| Exam Name: | Developing AI-Enabled Database Solutions |
| Exam Number: | DP-800 |
| Available Languages: | Portuguese (Brazil), Chinese (Traditional), Japanese, Korean, French, English, Arabic (Saudi Arabia), Italian, Spanish, German, Chinese (Simplified), Indonesian (Indonesia) |
| Exam Duration: | 100 minutes |
| Passing Score: | 700 |
| Exam Format: | Drag and drop, Multiple choice, Multiple select, Build list, Case studies |
| Certificate Validity Period: | 1 year |
| Real Exam Qty: | 40-60 |
| Related Certifications: | Microsoft Certified: SQL AI Developer Associate |
| Exam Price: | $165 USD |
| Sample Questions: | Microsoft DP-800 Sample Questions |
| Exam Way: | Online proctored or in-person at a testing center |
| Pre Condition: | No specific prerequisites, but candidates should have experience with SQL and a basic understanding of Azure services. Familiarity with AI or machine learning concepts is recommended. |
| Official Syllabus URL: | https://learn.microsoft.com/en-us/credentials/certifications/exams/dp-800/ |
>> DP-800 Accurate Prep Material <<
We would like to provide our customers with different kinds of DP-800 practice guide to learn, and help them accumulate knowledge and enhance their ability. Besides, we guarantee that the DP-800 exam questions of all our users can be answered by professional personal in the shortest time with our DP-800 Study Dumps. One more to mention, we can help you make full use of your sporadic time to absorb knowledge and information.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
NEW QUESTION # 85
Case Study 2 - Fabrikam
Existing Environment
Azure Environment
Fabrikam has a single Azure subscription in the East US 2 Azure region. The subscription contains an Azure SQL database named DB1. DB1 contains the following tables:
* Patients
* Employees
* Procedures
* Transactions
* UsefulPrompts
* ProcedureDocuments
You store a column master key as a secret in Azure Key Vault.
You have an on-premises application named TransactionProcessing that uses a hard-coded username and password in a connection string to access DB1.
Problem Statements
Users report that after executing a long-running stored procedure named sp_UpdateProcedureForPatient, updates to the underlying data are sometimes inconsistent.
Requirements
Planned Changes
Fabrikam plans to manage all changes to Azure SQL Database objects by using source control in GitHub. Every pull request submitted to production will be validated before it can be merged.
Deployments must use the Release configuration.
Security Requirements
Fabrikam identifies the following security requirements:
* The TransactionProcessing application must use a passwordless connection to DB1.
* The Employees table contains two columns named TaxID and Salary that must be encrypted at rest.
* Auditors must have a tamper-evident history of transactions with cryptographic proof of changes to the employee data.
Database Performance Requirements
Records accessed by using sp_UpdateProcedureForPatient must NOT be changed by other transactions while the stored procedure runs.
AI Search, Embeddings, and Vector Indexing
Fabrikam identifies the following AI-related requirements:
* Queries to the ProcedureDocuments table must use Reciprocal Rank Fusion (RRF).
* Users must be able to query the data in DB1 by using prompts in Copilot in Microsoft Fabric.
* The UsefulPrompts table will store prompts that doctors can use to help diagnose patient illness by connecting to an Azure OpenAI endpoint.
Development Requirements
Fabrikam identifies the following development requirements:
* Provide the functionality to retrieve all the transactions of a given patient between two dates, showing a running total.
* Expose a Data API builder (DAB) configuration file to enable Azure services to perform the following operations over a REST API:
- Read data from the procedures table without authentication.
- Read and insert data into the Transactions table once authenticated.
- Execute the sp_UpdateProcedurePatient stored procedure.
* Provide the functionality to retrieve a list of the names of patients who underwent medical procedures during the last 30 days.
* Information for each medical procedure will be stored in a table. The table will be used with a large language model (LLM) for user querying and will have the following structure.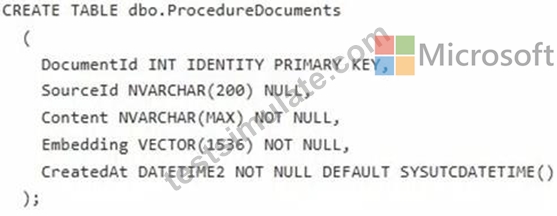
DAB
You create a DAB configuration file that meets the development requirements for DB1 and includes the following entities.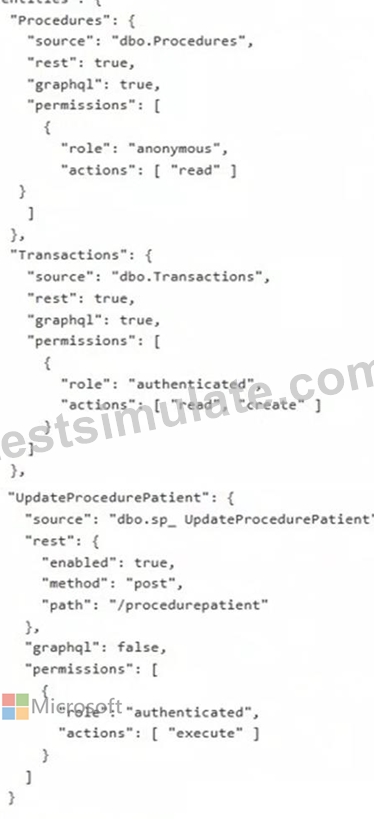
Hotspot Question
You need to create a solution that meets the development requirements for retrieving the patient transaction data. The solution must ensure that database developers use the resulting data to join to other tables.
How should you complete the Transact-SQL code? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.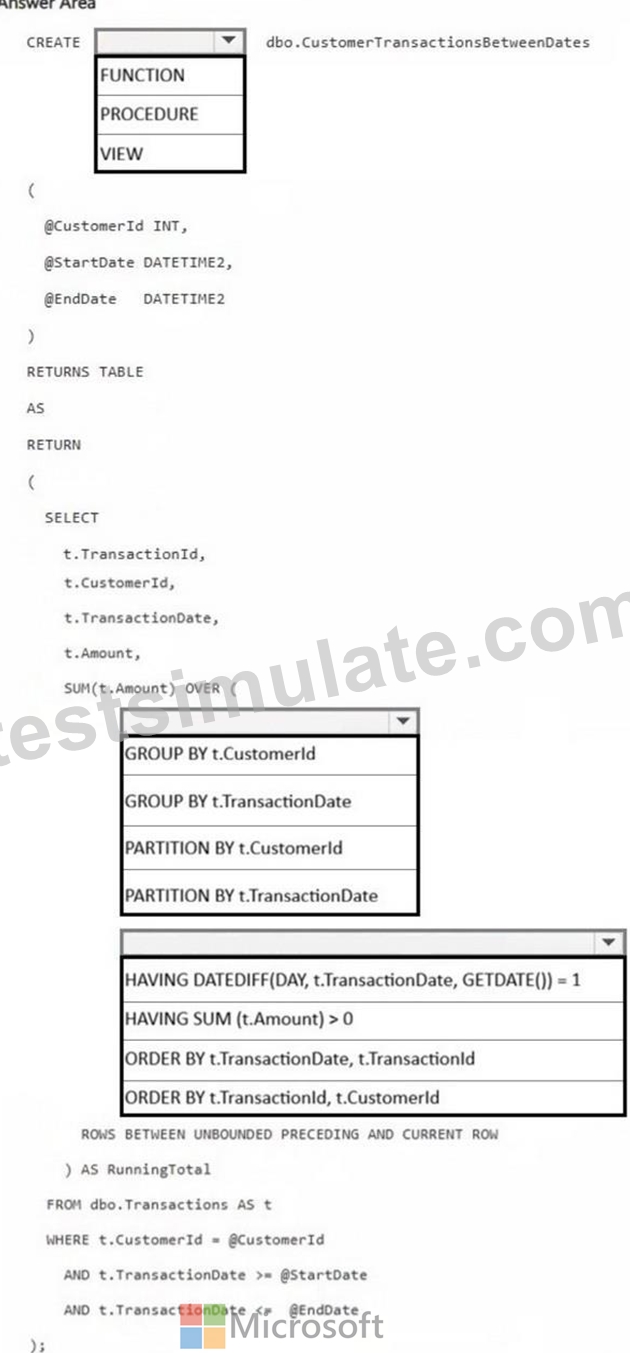
Answer:
Explanation: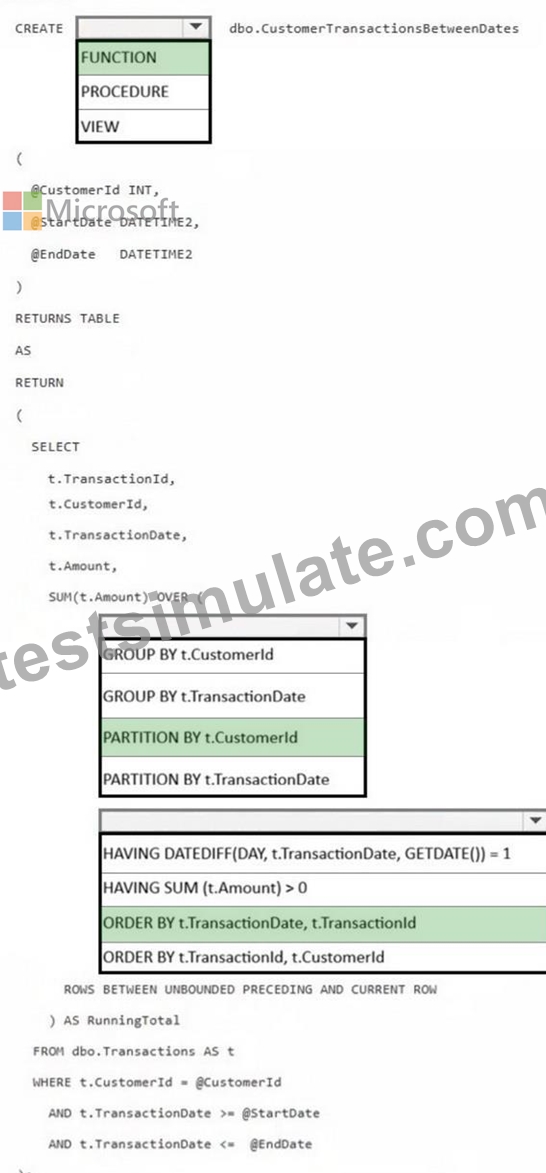
NEW QUESTION # 86
Drag and Drop Question
You have an Azure SQL database that supports an OLTP application.
You need to write Transact-SQL code that returns blocking chain details. The output must return only sessions that are blocked or are blocking other sessions.
How should you complete the code? To answer, drag the appropriate values to the correct targets. Each value may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.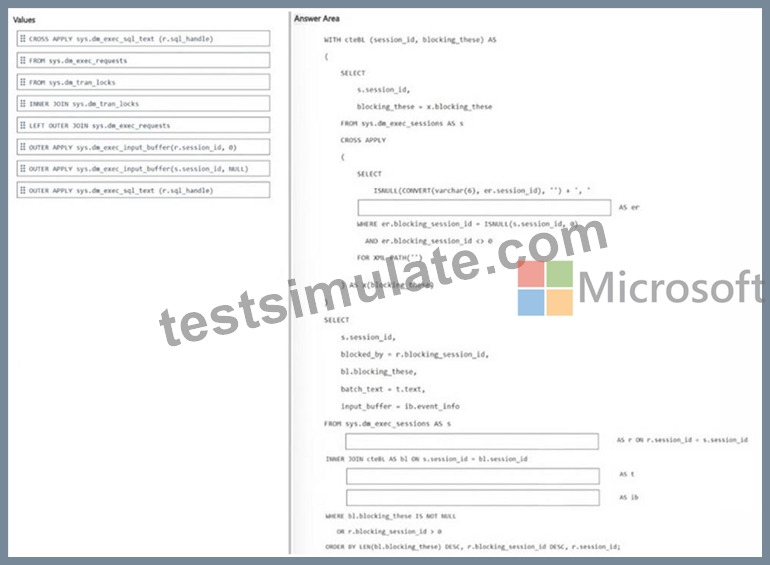
Answer:
Explanation: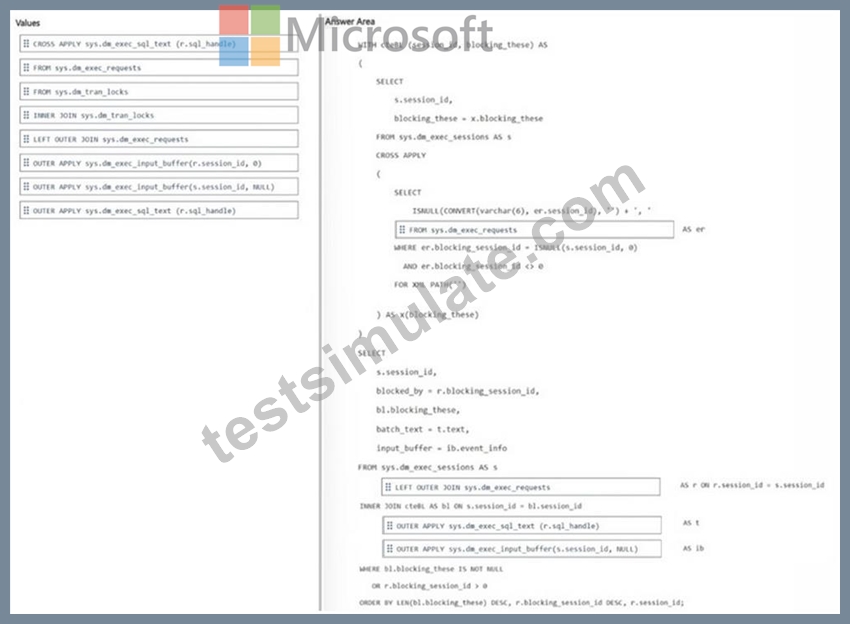
NEW QUESTION # 87
Hotspot Question
Your company has an ecommerce catalog in a Microsoft SQL Server 2025 database named SalesDB. SalesDB contains a table named products. products contains the following columns:
- product_id (int)
- product_name (nvarchar(200))
- description (nvarchar(max))
- category (nvarchar(50))
- brand (nvarchar(50))
- price (decimal)
- sku (nvarchar(40))
The description fields are updated daily by a content pipeline, and price can change multiple times per day.
You want customers to be able to submit natural language queries and apply structured filters for brand and price.
You plan to store embeddings in a new VECTOR(1536) column and use VECTOR_SEARCH(...
METRIC='cosine' ...).
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.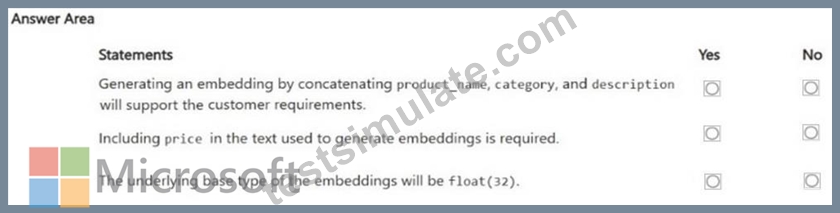
Answer:
Explanation: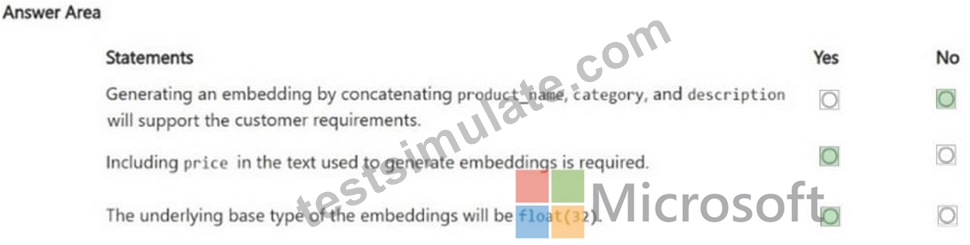
NEW QUESTION # 88
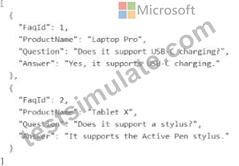
You have an Azure SQL table that contains the following data.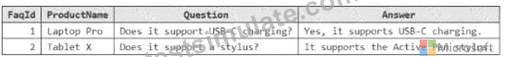
You need to retrieve data to be used as context for a large language model (LLM). The solution must minimize token usage.
Which formal should you use to send the data to the LLM?
Answer: A
Explanation:
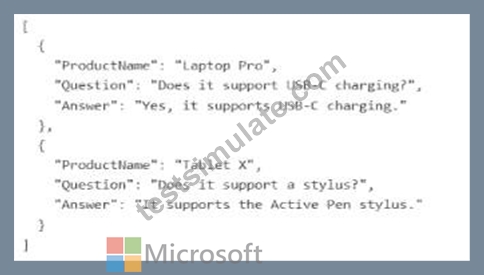
The correct choice is Option A because it provides the relevant semantic context the LLM needs while avoiding an unnecessary field that would add tokens without improving answer quality.
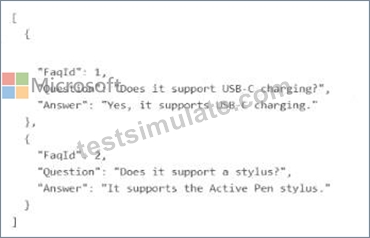
For LLM grounding and RAG-style context, Microsoft guidance emphasizes mapping and sending the fields that contain text pertinent to the use case . In this FAQ scenario, the useful context is the ProductName , the Question , and the Answer . Those three fields help the model understand both the subject domain and the actual Q & A pair. By contrast, FaqId is just a technical identifier and generally adds no semantic value for response generation, so including it wastes tokens.
That is why Option A is better than the others:
* Option A keeps the meaningful text fields and removes the low-value identifier.
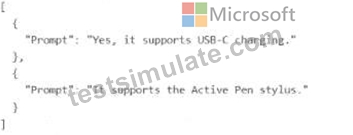
* Option B is too minimal because it includes only the answer text as Prompt, which strips away the product and question context the LLM may need for accurate grounding.
* Option C keeps FaqId but omits ProductName, which can be important disambiguating context.
* Option D includes everything, but that does not minimize token usage because it keeps the unnecessary FaqId.
NEW QUESTION # 89
You have an Azure SQL database that contains a table named knowledgebase, knowledgebase stores human resources (HR) policy documents and contains columns named title, content, category, and embedding.
You have an application named App1. App1 queries two relational tables named employee_pnofiles and benefits_enrollnent that contain HR data. App1 hosts a chatbot that calls a large language model (LLM) directly.
Users report that the chatbot answers general HR questions correctly but provides outdated or incorrect answers when policies change. The chatbot also fails to answer questions that reference internal policy documents by title or category.
You need to recommend a Retrieval Augmented Generation (RAG) solution to resolve the chatbot issues.
What should you recommend? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.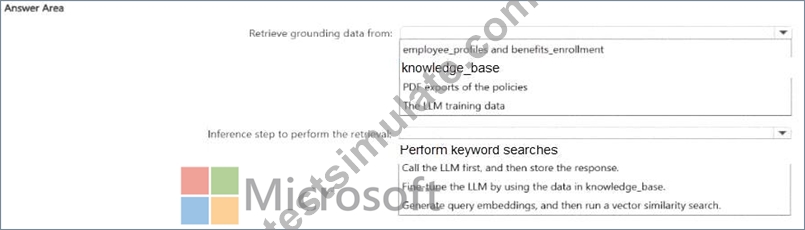
Answer:
Explanation: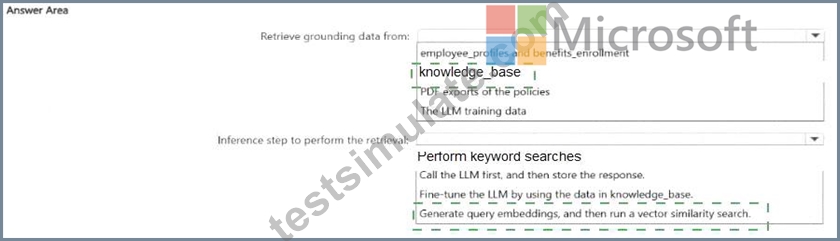
Explanation: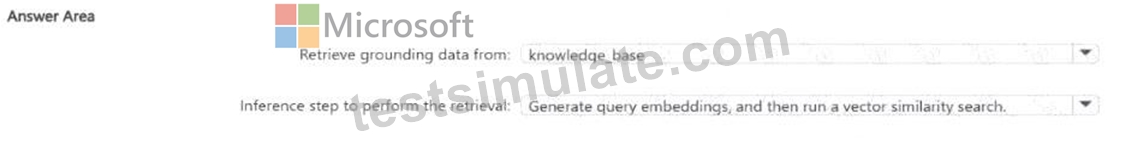
The correct recommendation is to retrieve grounding data from knowledge_base and, at inference time, generate query embeddings and run a vector similarity search .
The chatbot currently answers some general HR questions but fails when policies change and when users ask about internal policy documents by title or category . That is exactly the kind of problem RAG is meant to solve: ground the LLM in the organization's proprietary content instead of relying on the model's training data or unrelated transactional tables. Microsoft's RAG guidance states that RAG extends LLMs by grounding responses in your own content and that, for agentic retrieval, knowledge bases unify knowledge sources for retrieval.
So the grounding data should come from knowledge_base , because that table stores the HR policy documents and already includes fields like title, content, category, and embedding. Those are the fields directly tied to the missing and outdated policy answers. By contrast:
* employee_profiles and benefits_enrollment are operational HR tables, not the authoritative store for policy-document grounding.
* PDF exports of the policies would be inferior to querying the indexed/structured knowledge base already prepared for retrieval.
* The LLM training data is specifically the wrong source when the issue is outdated internal content.
For the retrieval step, Microsoft's guidance says to use embeddings for vector queries and notes that vector similarity search matches concepts, not exact terms . This is especially important because users ask about policy documents by title or category and also phrase questions in ways that might not exactly match document wording. Generating a query embedding and then running a vector similarity search is the appropriate retrieval step in a RAG pipeline.
NEW QUESTION # 90
......
New DP-800 Braindumps Questions: https://www.testsimulate.com/DP-800-study-materials.html