Get Free Updates For 1 year For Databricks Databricks-Machine-Learning-Professional Exam Questions
DOWNLOAD the newest PassLeader Databricks-Machine-Learning-Professional PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1cAHCv804xhlPK70UKCncXE9f8fPDW5q9
Passing an Databricks Certified Machine Learning Professional exam on the first attempt can be stressful, but Databricks Databricks-Machine-Learning-Professional exam questions can help manage stress and allow you to perform at your best. We at PassLeader give you the techniques and resources to make sure you get the most out of your exam study. We provide preparation material for the Databricks Certified Machine Learning Professional exam that will guide you when you sit to study for it. Databricks-Machine-Learning-Professional updated questions give you enough confidence to sit for the Databricks exam.
Databricks Databricks-Machine-Learning-Professional Exam Overview:
| Certification Vendor: | Databricks |
|---|
| Exam Name: | Databricks Certified Machine Learning Professional |
|---|
| Exam Number: | Databricks-Machine-Learning-Professional |
|---|
| Real Exam Qty: | 60 |
|---|
| Certificate Validity Period: | 2 years |
|---|
| Available Languages: | English |
|---|
| Exam Price: | USD 200 |
|---|
| Passing Score: | 70% |
|---|
| Exam Duration: | 120 minutes |
|---|
| Exam Format: | Multiple choice |
|---|
| Related Certifications: | Databricks Certified Machine Learning Associate |
|---|
| Sample Questions: | Databricks Databricks-Machine-Learning-Professional Sample Questions |
|---|
| Exam Way: | Online (proctored) or Test Center |
|---|
| Pre Condition: | No formal prerequisites, but 1+ years of hands-on experience performing the machine learning tasks outlined in the exam guide is highly recommended. Recommended courses: Machine Learning at Scale and Advanced Machine Learning Operations (instructor-led or self-paced via Databricks Academy). |
|---|
| Official Syllabus URL: | https://www.databricks.com/learn/certification/machine-learning-professional |
|---|
>> Databricks-Machine-Learning-Professional Questions Answers <<
Databricks-Machine-Learning-Professional Authorized Certification & Databricks-Machine-Learning-Professional Study Guides
We provide 24-hours online customer service which replies the client’s questions and doubts about our Databricks-Machine-Learning-Professional training quiz and solve their problems. Our professional personnel provide long-distance assistance online. Our expert team will check the update Databricks-Machine-Learning-Professional learning prep and will send the update version automatically to the clients. So the clients can enjoy the convenience of our wonderful service and the benefits brought by our superior Databricks-Machine-Learning-Professional guide materials.
| Topic | Details |
|---|
| Topic 1 | - Identify a use case for HTTP webhooks and where the Webhook URL needs to come
- Identify advantages of using Job clusters over all-purpose clusters
|
| Topic 2 | - Describe the advantages of using the pyfunc MLflow flavor
- Manually log parameters, models, and evaluation metrics using MLflow
|
| Topic 3 | - Identify JIT feature values as a need for real-time deployment
- Describe how to list all webhooks and how to delete a webhook
|
| Topic 4 | - Test whether the updated model performs better on the more recent data
- Identify when retraining and deploying an updated model is a probable solution to drift
|
| Topic 5 | - Describe model serving deploys and endpoint for every stage
- Identify scenarios in which feature drift and
- or label drift are likely to occur
|
| Topic 6 | - Create, overwrite, merge, and read Feature Store tables in machine learning workflows
- View Delta table history and load a previous version of a Delta table
|
| Topic 7 | - Identify which code block will trigger a shown webhook
- Describe the basic purpose and user interactions with Model Registry
|
| Topic 8 | - Identify that data can arrive out-of-order with structured streaming
- Identify how model serving uses one all-purpose cluster for a model deployment
|
Databricks Certified Machine Learning Professional Sample Questions (Q133-Q138):
NEW QUESTION # 133
A machine learning engineering team wants to build a continuous pipeline for data preparation of a machine learning application. The team would like the data to be fully processed and made ready for inference in a series of equal-sized batches.
Which of the following tools can be used to provide this type of continuous processing?
- A. AutoML
- B. MLflow
D Delta Lake - C. Spark UDFs
- D. [Structured Streaming
Answer: C
NEW QUESTION # 134
A Machine Learning Engineer has deployed a customer churn prediction model to production three months ago. The model serves real-time predictions via a Databricks endpoint with inference logging enabled. They notice declining model accuracy in recent weeks and suspect data drift in customer demographics. They need to implement monitoring to track model performance degradation and input feature drift over time. Which monitoring profile type should they use?
- A. Custom profile - Create a hybrid monitoring approach combining snapshot and time series profiles to capture both baseline comparisons and temporal trends.
- B. Time series profile - Monitor the inference table using timestamp-based windows to track model performance and input drift over time.
- C. Snapshot profile - Monitor the complete inference table to compare current model performance against the baseline established at deployment.
- D. Inference profile - Monitor the inference table to track model performance metrics, prediction drift, and input feature drift across time windows.
Answer: D
Explanation:
The inference profile is designed specifically to monitor production model behavior using inference logs. It tracks model performance metrics, prediction distributions, and input feature drift across time windows, enabling detection of performance degradation and demographic data drift after deployment.
NEW QUESTION # 135
In a Spark ML Pipeline, what is the role of a Transformer?
- A. Trains models
- B. Evaluates models
- C. Fits data
- D. Converts datasets into new datasets
Answer: D
Explanation:
A Transformer takes a dataset and transforms it into another dataset.
NEW QUESTION # 136
In order to connect an MLflow Model Registry Webhook to a Databricks Job, the Job ID must be provided to the code block used to create the webhook. Which approach can be used to obtain a Databricks Job ID?
- A. The Job ID field returned in a query using the Jobs API
- B. The Job ID field in the Job details section of the specific Job page in the UI
- C. The Job ID field in the Jobs page in the UI
- D. All of these approaches
Answer: D
Explanation:
A Databricks Job ID can be obtained in multiple ways - it is displayed directly in the Jobs page, in the Job details section of a specific Job, and can also be retrieved programmatically through the Databricks Jobs API. Any of these methods can be used to supply the Job ID when configuring an MLflow Model Registry Webhook.
NEW QUESTION # 137
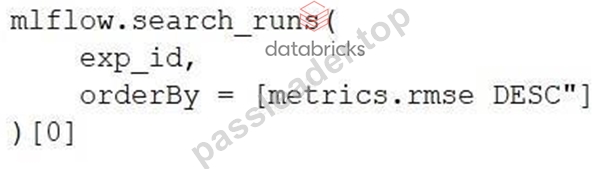
A data scientist is utilizing MLflow to track their machine learning experiments. After completing a run with run ID run_id for the experiment with experiment ID exp_id, the data scientist wants to programmatically return the logged metrics for run_id. They have an active MLflow Client client and an active Spark session spark. Which lines of code can be used to return the logged metrics for run_id?
- A. client.qet_run(exp_id.run_id).data.metrics
- B. spark.read.format("mlflow-run").load(run_id)
- C. client.get_run(run_id).data.metrics
- D.
Answer: C
Explanation:
The correct way to retrieve logged metrics for a specific run using the MLflow Client is client.get_run(run_id).data.metrics. This returns a dictionary of all metrics logged for that run. The method in the image (mlflow.search_runs(...)) is for querying across multiple runs, not for accessing a specific run's metrics.
NEW QUESTION # 138
......
Databricks-Machine-Learning-Professional Authorized Certification: https://www.passleader.top/Databricks/Databricks-Machine-Learning-Professional-exam-braindumps.html
- Databricks Databricks-Machine-Learning-Professional Guaranteed Success with Satisfied Customers and 24/7 Support System ✨ Search for ▛ Databricks-Machine-Learning-Professional ▟ and easily obtain a free download on ➽ www.vce4dumps.com 🢪 🐜Questions Databricks-Machine-Learning-Professional Exam
- Databricks-Machine-Learning-Professional Valid Exam Answers ↘ Databricks-Machine-Learning-Professional Test Valid 🔁 Databricks-Machine-Learning-Professional Exam Topic 🍼 Search for ☀ Databricks-Machine-Learning-Professional ️☀️ and obtain a free download on ✔ www.pdfvce.com ️✔️ 🤜Trustworthy Databricks-Machine-Learning-Professional Exam Torrent
- Quiz 2026 Reliable Databricks Databricks-Machine-Learning-Professional: Databricks Certified Machine Learning Professional Questions Answers 🧴 Search for ▛ Databricks-Machine-Learning-Professional ▟ and obtain a free download on 《 www.pdfdumps.com 》 🌠Databricks-Machine-Learning-Professional Practice Exam Questions
- 100% Pass Databricks Marvelous Databricks-Machine-Learning-Professional - Databricks Certified Machine Learning Professional Questions Answers 📌 Open website ➤ www.pdfvce.com ⮘ and search for 【 Databricks-Machine-Learning-Professional 】 for free download 🔼Questions Databricks-Machine-Learning-Professional Exam
- Reliable Databricks-Machine-Learning-Professional Test Guide 🛢 Databricks-Machine-Learning-Professional Latest Examprep 🍍 Databricks-Machine-Learning-Professional Practice Exam Questions 🆚 Open ➠ www.dumpsquestion.com 🠰 and search for ➤ Databricks-Machine-Learning-Professional ⮘ to download exam materials for free 👼Databricks-Machine-Learning-Professional Latest Examprep
- Free Databricks-Machine-Learning-Professional Dumps 🏍 Databricks-Machine-Learning-Professional Latest Test Materials 🦞 Trustworthy Databricks-Machine-Learning-Professional Exam Torrent 🤾 Immediately open ▶ www.pdfvce.com ◀ and search for ☀ Databricks-Machine-Learning-Professional ️☀️ to obtain a free download 🍶Latest Databricks-Machine-Learning-Professional Mock Test
- Databricks-Machine-Learning-Professional Exam Learning 📀 Questions Databricks-Machine-Learning-Professional Exam 🦒 Trustworthy Databricks-Machine-Learning-Professional Exam Torrent 💽 Simply search for ▷ Databricks-Machine-Learning-Professional ◁ for free download on 「 www.examdiscuss.com 」 🔸Latest Databricks-Machine-Learning-Professional Mock Test
- 100% Pass 2026 Databricks Databricks-Machine-Learning-Professional: Databricks Certified Machine Learning Professional Authoritative Questions Answers 🙂 Easily obtain ⮆ Databricks-Machine-Learning-Professional ⮄ for free download through 【 www.pdfvce.com 】 🦲Latest Databricks-Machine-Learning-Professional Mock Test
- Choosing Databricks-Machine-Learning-Professional Questions Answers Makes It As Easy As Eating to Pass Databricks Certified Machine Learning Professional ⏭ Search for ➤ Databricks-Machine-Learning-Professional ⮘ and easily obtain a free download on ▷ www.dumpsmaterials.com ◁ 🚆Test Databricks-Machine-Learning-Professional Dumps
- 100% Pass Databricks Marvelous Databricks-Machine-Learning-Professional - Databricks Certified Machine Learning Professional Questions Answers 😋 Search on 「 www.pdfvce.com 」 for 【 Databricks-Machine-Learning-Professional 】 to obtain exam materials for free download 🤒Databricks-Machine-Learning-Professional Practice Exam Questions
- Databricks-Machine-Learning-Professional Valid Exam Answers 🧱 Valid Test Databricks-Machine-Learning-Professional Vce Free 🛳 Databricks-Machine-Learning-Professional Exam Learning 🤏 Simply search for ☀ Databricks-Machine-Learning-Professional ️☀️ for free download on ➥ www.testkingpass.com 🡄 🦜Databricks-Machine-Learning-Professional Exam Topic
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, jobs.electronicsweekly.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
2026 Latest PassLeader Databricks-Machine-Learning-Professional PDF Dumps and Databricks-Machine-Learning-Professional Exam Engine Free Share: https://drive.google.com/open?id=1cAHCv804xhlPK70UKCncXE9f8fPDW5q9