順便提一下,可以從雲存儲中下載Fast2test ARA-C01考試題庫的完整版:https://drive.google.com/open?id=1Ee24lubrGuJ-VbDaUYeAWIFWqDN_jZ3K
如果你想通過困難的ARA-C01認證考試,那麼在準備考試時不使用相關考試資料是絕對不行的。如果你想找到適合你自己的優秀的資料,那麼你最應該來的地方就是Fast2test。Fast2test的知名度很高,擁有很多與IT認證相關的優秀的考試考古題。而且所有的考古題都免費提供demo。如果你想知道Fast2test的考古題是不是適合你,那麼先下載考古題的demo體驗一下吧。
Snowflake ARA-C01 考試分為四個不同的部分,每個部分都集中在 Snowflake 架構的特定領域。這些部分包括 Snowflake 架構和設計、數據倉儲、數據處理和數據集成。該考試是一個基於計算機的測試,通過第三方考試提供商進行管理。
面對職場的競爭和不景氣時期,提升您的專業能力是未來最好的投資,而獲得Snowflake ARA-C01認證對于考生而言有諸多好處。相對于考生尋找工作而言,一張ARA-C01認證可以倍受企業青睞,為您帶來更好的工作機會。但是如何輕松拿到ARA-C01認證哪? Fast2test的ARA-C01考古題是通過考試最有效的方式之一,我們提供在線測試引擎的題庫,可以讓您模擬真實的考試情景,快速讓考生掌握知識點并應用。ARA-C01題庫資料包含真實的考題體型,100%幫助考生通過考試。
Snowflake ARA-C01考試是一項全球認可的供應商中立認證,旨在驗證專業人士在Snowflake架構和設計方面的技能和知識,使他們在就業市場上更具競爭力。通過考試可以證明候選人對Snowflake有深刻的理解,能夠高效、可擴展和安全地設計和實施複雜的Snowflake解決方案。總的來說,Snowflake ARA-C01考試是想在Snowflake架構和設計方面推進職業生涯的專業人士的絕佳機會。
問題 #158
When using the Snowflake Connector for Kafka, what data formats are supported for the messages? (Choose two.)
答案:A,B
解題說明:
Explanation
The data formats that are supported for the messages when using the Snowflake Connector for Kafka are Avro and JSON. These are the two formats that the connector can parse and convert into Snowflake table rows. The connector supports both schemaless and schematized JSON, as well as Avro with or without a schema registry1. The other options are incorrect because they are not supported data formats for the messages. CSV, XML, and Parquet are not formats that the connector can parse and convert into Snowflake table rows. If the messages are in these formats, the connector will load them as VARIANT data type and store them as raw strings in the table2. References: Snowflake Connector for Kafka | Snowflake Documentation, Loading Protobuf Data using the Snowflake Connector for Kafka | Snowflake Documentation
問題 #159
A media company needs a data pipeline that will ingest customer review data into a Snowflake table, and apply some transformations. The company also needs to use Amazon Comprehend to do sentiment analysis and make the de-identified final data set available publicly for advertising companies who use different cloud providers in different regions.
The data pipeline needs to run continuously and efficiently as new records arrive in the object storage leveraging event notifications. Also, the operational complexity, maintenance of the infrastructure, including platform upgrades and security, and the development effort should be minimal.
Which design will meet these requirements?
答案:C
解題說明:
Option B is the best design to meet the requirements because it uses Snowpipe to ingest the data continuously and efficiently as new records arrive in the object storage, leveraging event notifications. Snowpipe is a service that automates the loading of data from external sources into Snowflake tables1. It also uses streams and tasks to orchestrate transformations on the ingested data. Streams are objects that store the change history of a table, and tasks are objects that execute SQL statements on a schedule or when triggered by another task2. Option B also uses an external function to do model inference with Amazon Comprehend and write the final records to a Snowflake table. An external function is a user-defined function that calls an external API, such as Amazon Comprehend, to perform computations that are not natively supported by Snowflake3. Finally, option B uses the Snowflake Marketplace to make the de-identified final data set available publicly for advertising companies who use different cloud providers in different regions. The Snowflake Marketplace is a platform that enables data providers to list and share their data sets with data consumers, regardless of the cloud platform or region they use4.
Option A is not the best design because it uses copy into to ingest the data, which is not as efficient and continuous as Snowpipe. Copy into is a SQL command that loads data from files into a table in a single transaction. It also exports the data into Amazon S3 to do model inference with Amazon Comprehend, which adds an extra step and increases the operational complexity and maintenance of the infrastructure.
Option C is not the best design because it uses Amazon EMR and PySpark to ingest and transform the data, which also increases the operational complexity and maintenance of the infrastructure. Amazon EMR is a cloud service that provides a managed Hadoop framework to process and analyze large-scale data sets. PySpark is a Python API for Spark, a distributed computing framework that can run on Hadoop. Option C also develops a python program to do model inference by leveraging the Amazon Comprehend text analysis API, which increases the development effort.
Option D is not the best design because it is identical to option A, except for the ingestion method. It still exports the data into Amazon S3 to do model inference with Amazon Comprehend, which adds an extra step and increases the operational complexity and maintenance of the infrastructure.
問題 #160
Company A would like to share data in Snowflake with Company B. Company B is not on the same cloud platform as Company A.
What is required to allow data sharing between these two companies?
答案:B
解題說明:
According to the SnowPro Advanced: Architect documents and learning resources, the requirement to allow data sharing between two companies that are not on the same cloud platform is to set up data replication to the region and cloud platform where the consumer resides. Data replication is a feature of Snowflake that enables copying databases across accounts in different regions and cloud platforms. Data replication allows data providers to securely share data with data consumers across different regions and cloud platforms by creating a replica database in the consumer's account. The replica database is read-only and automatically synchronized with the primary database in the provider's account. Data replication is useful for scenarios where data sharing is not possible or desirable due to latency, compliance, or security reasons1. The other options are incorrect because they are not required or feasible to allow data sharing between two companies that are not on the same cloud platform. Option A is incorrect because creating a pipeline to write shared data to a cloud storage location in the target cloud provider is not a secure or efficient way of sharing data. It would require additional steps to load the data from the cloud storage to the consumer's account, and it would not leverage the benefits of Snowflake's data sharing features. Option B is incorrect because ensuring that all views are persisted is not relevant for data sharing across cloud platforms. Views can be shared across cloud platforms as long as they reference objects in the same database. Persisting views is an option to improve the performance of querying views, but it is not required for data sharing2. Option D is incorrect because Company A and Company B do not need to agree to use a single cloud platform. Data sharing is possible across different cloud platforms using data replication or other methods, such as listings or auto-fulfillment3. References: Replicating Databases Across Multiple Accounts | Snowflake Documentation, Persisting Views | Snowflake Documentation, Sharing Data Across Regions and Cloud Platforms | Snowflake Documentation
問題 #161
Which of the following ingestion methods can be used to load near real-time data by using the messaging services provided by a cloud provider?
答案:A
解題說明:
Snowflake Connector for Kafka and Snowpipe are two ingestion methods that can be used to load near real-time data by using the messaging services provided by a cloud provider. Snowflake Connector for Kafka enables you to stream structured and semi-structured data from Apache Kafka topics into Snowflake tables.
Snowpipe enables you to load data from files that are continuously added to a cloud storage location, such as Amazon S3 or Azure Blob Storage. Both methods leverage Snowflake's micro-partitioning and columnar storage to optimize data ingestion and query performance. Snowflake streams and Spark are not ingestion methods, but rather components of the Snowflake architecture. Snowflake streams provide change data capture (CDC) functionality by tracking data changes in a table. Spark is a distributed computing framework that can be used to process large-scale data and write it to Snowflake using the Snowflake Spark Connector. References:
* Snowflake Connector for Kafka
* Snowpipe
* Snowflake Streams
* Snowflake Spark Connector
問題 #162
The Business Intelligence team reports that when some team members run queries for their dashboards in parallel with others, the query response time is getting significantly slower What can a Snowflake Architect do to identify what is occurring and troubleshoot this issue?
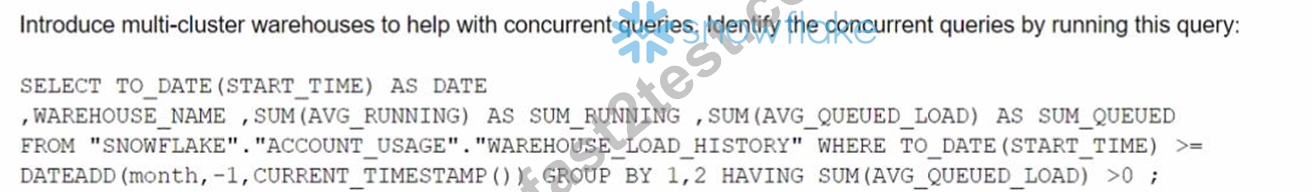
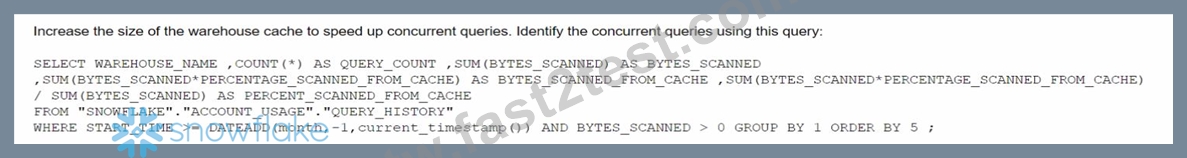
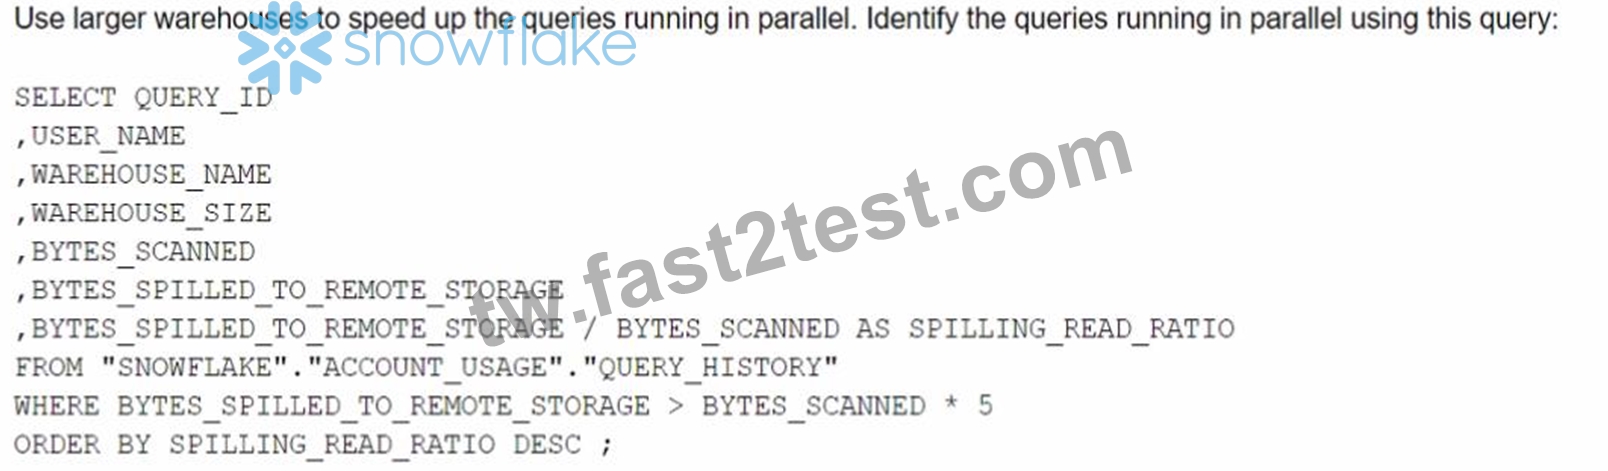
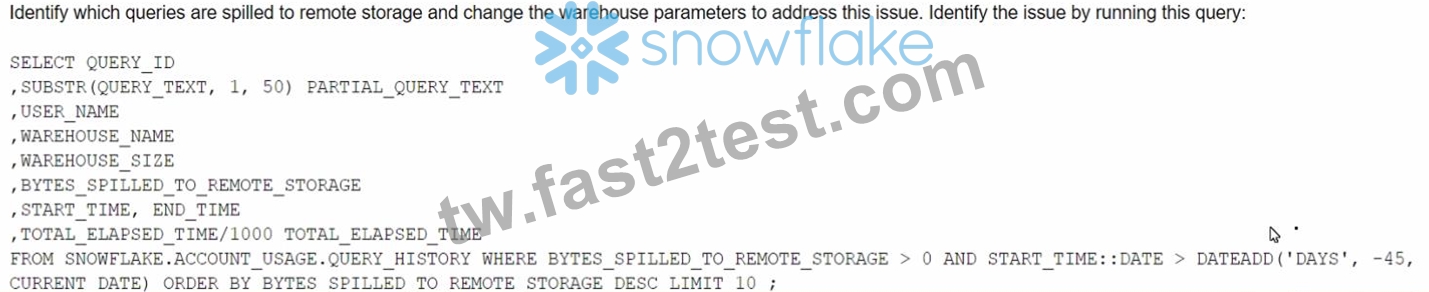
答案:D
問題 #163
......
ARA-C01認證: https://tw.fast2test.com/ARA-C01-premium-file.html
從Google Drive中免費下載最新的Fast2test ARA-C01 PDF版考試題庫:https://drive.google.com/open?id=1Ee24lubrGuJ-VbDaUYeAWIFWqDN_jZ3K