
P.S. Free & New MLA-C01 dumps are available on Google Drive shared by ValidExam: https://drive.google.com/open?id=1C_a1yIrzWTvTZA0eYkQ066Mlfn9j3q28
AWS Certified Machine Learning Engineer - Associate MLA-C01 certification exam offers a quick way to validate skills in the market. By doing this they can upgrade their skill set and knowledge and become a certified member of the AWS Certified Machine Learning Engineer - Associate MLA-C01 exam. There are several benefits of MLA-C01 Certification that can enjoy a successful candidate for the rest of their life. MLA-C01 also offers valid dumps book and valid dumps free download, with 365 days free updates.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
The ValidExam is one of the leading platforms that have been offering valid, updated, and real Amazon MLA-C01 exam dumps for many years. The AWS Certified Machine Learning Engineer - Associate MLA-C01 practice test questions offered by the ValidExam are designed and verified by experienced Amazon MLA-C01 Certification Exam trainers. They work together and put all their expertise to ensure the top standard of AWS Certified Machine Learning Engineer - Associate MLA-C01 valid dumps.
NEW QUESTION # 175
An ML engineer needs to train a supervised deep learning model. The available dataset is a large number of unlabeled images that only employees should access. The ML engineer needs to implement a solution that labels the dataset with the highest possible accuracy. Which combination of steps should the ML engineer take to meet these requirements? (Choose two.)
Answer: B,E
Explanation:
To achieve the highest labeling accuracy with controlled employee-only access, the ML engineer should use Amazon SageMaker Ground Truth to define the annotation job and then assign it to a private workforce of employees for labeling and review. This ensures high-quality, secure labeling restricted to authorized personnel.
NEW QUESTION # 176
An ML engineer is evaluating several ML models and must choose one model to use in production. The cost of false negative predictions by the models is much higher than the cost of false positive predictions.
Which metric finding should the ML engineer prioritize the MOST when choosing the model?
Answer: C
Explanation:
Recall measures the ability of a model to correctly identify all positive cases (true positives) out of all actual positives, minimizing false negatives. Since the cost of false negatives is much higher than falsepositives in this scenario, the ML engineer should prioritize models with high recall to reduce the likelihood of missing positive cases.
NEW QUESTION # 177
An ML engineer is working on an ML model to predict the prices of similarly sized homes. The model will base predictions on several features The ML engineer will use the following feature engineering techniques to estimate the prices of the homes:
* Feature splitting
* Logarithmic transformation
* One-hot encoding
* Standardized distribution
Select the correct feature engineering techniques for the following list of features. Each feature engineering technique should be selected one time or not at all (Select three.)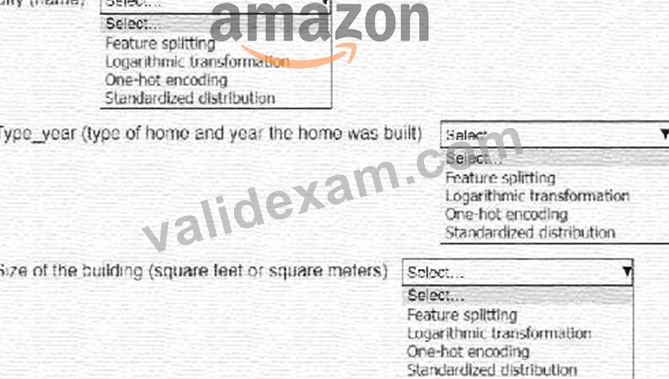
Answer:
Explanation: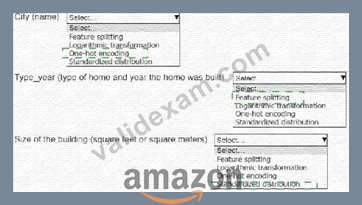
Explanation:
* City (name): One-hot encoding
* Type_year (type of home and year the home was built): Feature splitting
* Size of the building (square feet or square meters): Standardized distribution
* City (name): One-hot encoding
* Why? The "City" is a categorical feature (non-numeric), so one-hot encoding is used to transform it into a numeric format. This encoding creates binary columns for each unique category (e.g., cities like "New York" or "Los Angeles"), which the model can interpret.
* Type_year (type of home and year the home was built): Feature splitting
* Why? "Type_year" combines two pieces of information into one column, which could confuse the model. Feature splitting separates this column into two distinct features: "Type of home" and
"Year built," enabling the model to process each feature independently.
* Size of the building (square feet or square meters): Standardized distribution
* Why? Size is a continuous numerical variable, and standardization (scaling the feature to have a mean of 0 and a standard deviation of 1) ensures that the model treats it fairly compared to other features, avoiding bias from differences in feature scale.
By applying these feature engineering techniques, the ML engineer can ensure that the input data is correctly formatted and optimized for the model to make accurate predictions.
NEW QUESTION # 178
Case study
An ML engineer is developing a fraud detection model on AWS. The training dataset includes transaction logs, customer profiles, and tables from an on-premises MySQL database. The transaction logs and customer profiles are stored in Amazon S3.
The dataset has a class imbalance that affects the learning of the model's algorithm. Additionally, many of the features have interdependencies. The algorithm is not capturing all the desired underlying patterns in the data.
The training dataset includes categorical data and numerical data. The ML engineer must prepare the training dataset to maximize the accuracy of the model.
Which action will meet this requirement with the LEAST operational overhead?
Answer: B
Explanation:
Preparing a training dataset that includes both categorical and numerical data is essential for maximizing the accuracy of a machine learning model. Transforming categorical data into numerical format is a critical step, as most ML algorithms require numerical input.
Why Transform Categorical Data into Numerical Data?
* Model Compatibility: Many ML algorithms cannot process categorical data directly and require numerical representations.
* Improved Performance: Proper encoding of categorical variables can enhance model accuracy and convergence speed.
Why Use Amazon SageMaker Data Wrangler?
Amazon SageMaker Data Wrangler offers a visual interface with over 300 built-in data transformations, including tools for encoding categorical variables.
Implementation Steps:
* Import Data:
* Load the dataset into SageMaker Data Wrangler from sources like Amazon S3 or on-premises databases.
* Identify Categorical Features:
* Use Data Wrangler's data type inference to detect categorical columns.
* Apply Categorical Encoding:
* Choose appropriate encoding techniques (e.g., one-hot encoding or ordinal encoding) from Data Wrangler's transformation options.
* Apply the selected transformation to convert categorical features into numerical format.
* Validate Transformations:
* Review the transformed dataset to ensure accuracy and completeness.
Advantages of Using SageMaker Data Wrangler:
* Ease of Use: Provides a user-friendly interface for data transformation without extensive coding.
* Operational Efficiency: Integrates data preparation steps, reducing the need for multiple tools and minimizing operational overhead.
* Flexibility: Supports various data sources and transformation techniques, accommodating diverse datasets.
By utilizing SageMaker Data Wrangler to transform categorical data into numerical format, the ML engineer can efficiently prepare the dataset, thereby enhancing the model's accuracy with minimal operational overhead.
References:
* Transform Data - Amazon SageMaker
* Prepare ML Data with Amazon SageMaker Data Wrangler
NEW QUESTION # 179
Case study
An ML engineer is developing a fraud detection model on AWS. The training dataset includes transaction logs, customer profiles, and tables from an on-premises MySQL database. The transaction logs and customer profiles are stored in Amazon S3.
The dataset has a class imbalance that affects the learning of the model's algorithm. Additionally, many of the features have interdependencies. The algorithm is not capturing all the desired underlying patterns in the data.
After the data is aggregated, the ML engineer must implement a solution to automatically detect anomalies in the data and to visualize the result.
Which solution will meet these requirements?
Answer: B
Explanation:
Amazon SageMaker Data Wrangler is a comprehensive tool that streamlines the process of data preparation and offers built-in capabilities for anomaly detection and visualization.
Key Features of SageMaker Data Wrangler:
* Data Importation: Connects seamlessly to various data sources, including Amazon S3 and on-premises databases, facilitating the aggregation of transaction logs, customer profiles, and MySQL tables.
* Anomaly Detection: Provides built-in analyses to detect anomalies in time series data, enabling the identification of outliers that may indicate fraudulent activities.
* Visualization: Offers a suite of visualization tools, such as histograms and scatter plots, to help understand data distributions and relationships, which are crucial for feature engineering and model development.
Implementation Steps:
* Data Aggregation:
* Import data from Amazon S3 and on-premises MySQL databases into SageMaker Data Wrangler.
* Utilize Data Wrangler's data flow interface to combine and preprocess datasets, ensuring a unified dataset for analysis.
* Anomaly Detection:
* Apply the anomaly detection analysis feature to identify outliers in the dataset.
* Configure parameters such as the anomaly threshold to fine-tune the detection sensitivity.
* Visualization:
* Use built-in visualization tools to create charts and graphs that depict data distributions and highlight anomalies.
* Interpret these visualizations to gain insights into potential fraud patterns and feature interdependencies.
Advantages of Using SageMaker Data Wrangler:
* Integrated Workflow: Combines data preparation, anomaly detection, and visualization within a single interface, streamlining the ML development process.
* Operational Efficiency: Reduces the need for multiple tools and complex integrations, thereby minimizing operational overhead.
* Scalability: Handles large datasets efficiently, making it suitable for extensive transaction logs and customer profiles.
By leveraging SageMaker Data Wrangler, the ML engineer can effectively detect anomalies and visualize results, facilitating the development of a robust fraud detection model.
Analyze and Visualize - Amazon SageMaker
Transform Data - Amazon SageMaker
NEW QUESTION # 180
......
In order to help you save more time, we will transfer MLA-C01 test guide to you within 10 minutes online after your payment and guarantee that you can study these MLA-C01 training materials as soon as possible to avoid time waste. We believe that time is the most valuable things in the world. This is why we are dedicated to improve your study efficiency and production. Here are some advantages of our MLA-C01 study question and we would appreciate that you can have a look to our MLA-C01 questions.
New MLA-C01 Test Review: https://www.validexam.com/MLA-C01-latest-dumps.html
DOWNLOAD the newest ValidExam MLA-C01 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1C_a1yIrzWTvTZA0eYkQ066Mlfn9j3q28